lingbot-map's KV cache was wrong twice, and once silently
A feed-forward 3D foundation model for reconstructing scenes from streaming data.
At a glance
- What is it?
- LingBot-Map is a feed-forward 3D foundation model from the Robbyant team for reconstructing scenes from streaming input, claiming about 20 frames per second at 518 by 378 over sequences past ten thousand frames, with a paged KV cache carrying the long-range memory. The install is five manual steps and the manifest does not list PyTorch.
- Who is it for?
- lingbot-map fits a team that wants a single forward pass over a long video to produce a 3D scene, and that has a CUDA machine and a tolerance for a research package at version 0.1.0 with no tagged releases. It does not fit a pipeline that needs a reproducible version, because the repository publishes no releases and the only change record is the dated news list, where two KV cache fixes appear within ten weeks of each other.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 31 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
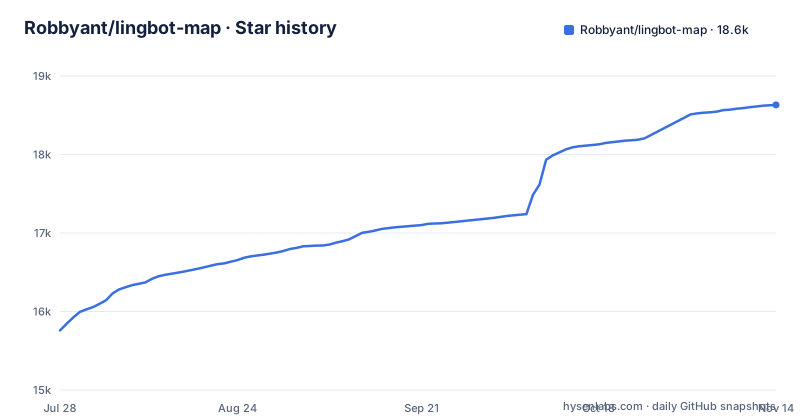
- Robbyant/lingbot-map18,632 ★ · +2,873
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| Robbyant/lingbot-map | 15.8k | 18.6k |
2,873 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two keyframe cache bugs in one quarter, and one of them was silent
The news list is the most informative section in the README, and two of its five entries are about the same subsystem. On 2026-04-24 the project fixed a FlashInfer key-value cache bug where a keyframe interval greater than one silently cached non-keyframes, with the note that you should now see better pose and reconstruction quality when running with more than 320 frames. On 2026-06-28 it fixed a bug in the other backend, saying the SDPA backend now performs better on long sequences while still recommending FlashInfer for the best performance. Read together, they tell you two things about this architecture. The paged KV cache is the mechanism that makes a stream of thousands of frames fit in memory, and it was wrong twice inside ten weeks. And the first failure mode was not an error, it was quietly degraded output, which is the kind that survives into a result set. Pin a version after June 2026 and re-check a short and a long sequence when you move.
The performance claim is one resolution and one frame rate
The high-efficiency claim is stated as a feed-forward architecture with paged KV cache attention enabling stable inference at about 20 frames per second on 518 by 378 resolution over long sequences exceeding 10,000 frames. Those numbers are precise enough to be useful and narrow enough to be misleading outside their conditions. A frame rate at a stated resolution is not a throughput figure for your data, because what you feed it is frames and how much of each frame the model consumes is your choice, and the cost of a long trajectory grows with the memory it keeps. The word feed-forward is the real differentiator, because the README's comparison is against both existing streaming approaches and iterative optimisation-based ones. You get no per-scene refinement loop, which is where the latency advantage comes from, and the trade is that there is no second pass you can run longer on a scene that came out badly.
PyTorch is not in the dependency list, and the version is pinned by hand
The package manifest lists seven dependencies: Pillow, huggingface_hub, einops, safetensors, opencv-python, tqdm and scipy. PyTorch is not among them, and neither is the attention backend the project recommends, so pip install -e . gives you a package that imports a framework you have to install yourself. The readme makes that a numbered step, and pins the version:
pip install torch==2.8.0 torchvision==0.23.0 --index-url https://download.pytorch.org/whl/cu128The reason is documented and specific. NVIDIA Kaolin, which the batch rendering pipeline requires, has prebuilt wheels for that exact PyTorch and CUDA combination. If you only need the interactive demo you may use a newer PyTorch, and then the batch renderer requires building Kaolin from source. So the pin is not superstition, it is a dependency resolution the manifest cannot express, and the practical consequence is that an environment set up by the five steps in the readme is not the same as one assembled by a resolver.
Two attention backends, and a flag that picks which one you silently got
The recommended backend is FlashInfer, installed as a pure-Python package that just-in-time compiles CUDA kernels on first use, so a single wheel works across CUDA and PyTorch versions:
pip install --index-url https://pypi.org/simple flashinfer-pythonThe readme also says what happens without it. If FlashInfer is not installed, the model falls back to PyTorch native attention through a flag, and the news entry about the SDPA fix says that backend now performs better on long sequences while FlashInfer is still recommended. So the fallback is a fallback rather than an equivalent. On an internal package mirror you may also need the explicit index, which the readme flags as a requirement rather than a preference. Treat the backend as part of your configuration and record it alongside your checkpoint, because two results from the same weights and different backends are two results.
Around 3000 frames the interactive path hands over to the batch renderer
The table of contents is organised by what you are trying to do, and the split is the interesting part. There is a section on streaming with a keyframe interval, one on windowed inference explicitly for long sequences above 3000 frames, one on sky masking, and separate ones for visualisation options and for performance and memory. Then there is a second entry point entirely, an offline rendering pipeline, for long-sequence batch rendering. The worked example in the news list is a very long video of about 25,000 frames, a 13-minute indoor walkthrough, and it was rendered with the offline pipeline rather than in the interactive viewer. The first use after installation is deliberately small, a single image folder, so the handover point is something you discover by hitting it. The scene folders at example/ give you courthouse, loop and university to start from.
Every todo item is ticked, and the change log is a news list
The todo list is entirely checked, and it is a reasonable summary of what the project set out to do. The evaluation benchmark is marked done for nine datasets, including Oxford Spires, KITTI, TUM, ETH3D, 7-scenes, Tanks and Temples and NRGBD, and the demo scripts are marked done for indoor, outdoor, aerial and LingBot-World long-video examples. The news entries add the detail: the benchmark scripts for KITTI and Oxford Spires were released in May 2026, with a preprocess script named for preparing the Oxford data, and the long-video demo came in April 2026. Against that, the packaging is thin. The package version is 0.1.0, the repository publishes no releases, and the last push recorded is 2026-10-14. So there is no changelog to diff and no tag to pin, and the dated news list is the change record. Read it when you upgrade rather than trusting the version number.
Two checkpoints, and the balanced one is the one behind the numbers
Two models are published, on Hugging Face and on ModelScope, and they are not variants of the same thing. The first, named for the project, is described as a balanced checkpoint used in the paper, the benchmark and the offline demo, trading off all-round performance across short and long sequences. The second, a stage-one variant, is the stage-1 training checkpoint and can be loaded into the VGGT model for bidirectional inference, described as c2w. A third is promised: a note says a stronger model supporting longer sequences is still being trained. So if you want to reproduce a published number, the balanced checkpoint is the one, and the stage-one checkpoint is for a particular inference mode. Running both and comparing tells you nothing unless you already know which mode you are testing, and the coming-soon note means the published checkpoint list is not the end state.
Editorial conclusion
lingbot-map fits a team that wants a single forward pass over a long video to produce a 3D scene, and that has a CUDA machine and a tolerance for a research package at version 0.1.0 with no tagged releases. It does not fit a pipeline that needs a reproducible version, because the repository publishes no releases and the only change record is the dated news list, where two KV cache fixes appear within ten weeks of each other. Before you build on it, install the pinned PyTorch rather than the newest, because the batch renderer depends on a library with prebuilt wheels for that exact combination, and choose your attention backend deliberately, since the model falls back to PyTorch native attention when the recommended one is absent. Then pick the balanced checkpoint, since that is the one the paper and the benchmark used, and re-run a long sequence after every upgrade, because the earlier cache bug was silent and showed up only as worse poses.
Frequently asked questions
What is the LingBot map?
LingBot-Map is a feed-forward 3D foundation model for streaming 3D reconstruction, from the Robbyant team, described as a Geometric Context Transformer. It unifies coordinate grounding, dense geometric cues and long-range drift correction in one streaming framework through anchor context, a pose-reference window and trajectory memory.
how to use lingbot map
Install it in a Python 3.10 conda environment with a pinned PyTorch, install the package with pip install -e ., optionally install the attention backend, then run the interactive demo on an example scene with python demo.py, which opens a viser viewer in the browser at localhost:8080.
Which model checkpoints does lingbot-map publish?
Two. The project-named checkpoint is a balanced one used in the paper, the benchmark and the offline demo, trading off performance across short and long sequences. A stage-1 checkpoint can be loaded into the VGGT model for bidirectional inference. Both are on Hugging Face and ModelScope, and a stronger model for longer sequences is described as still being trained.
Why does lingbot-map pin a specific PyTorch version?
Because NVIDIA Kaolin, which the batch rendering pipeline requires, has prebuilt wheels for that PyTorch and CUDA combination. The readme says you may use a newer PyTorch if you only need the interactive demo, but the batch renderer then has to build Kaolin from source. PyTorch is not listed among the package's declared dependencies.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/robbyant-lingbot-map)Star history chart for your README
[](https://hysenlabs.com/projects/robbyant-lingbot-map)Was this useful?