AI LocalBase is a Go RAG service whose first-run window is the thing to plan around
A local-first AI knowledge-base system (RAG) that connects local documents into a tutoring search and LLM chat workflow. Currently supports md, txt, pdf (text), xlsx, and csv files, with MCP server support.
At a glance
- What is it?
- AI LocalBase wires local documents into retrieval-augmented chat on Qdrant, with Ollama or any OpenAI-compatible endpoint for chat and embedding models, plus an embedded MCP server so an agent can query the same knowledge base. It is single instance by design, it will not start Qdrant on a non-loopback address without a key, and swapping your embedding model means picking a new collection prefix.
- Who is it for?
- AI LocalBase suits someone running a personal or small-team knowledge base who wants a retrieval stack they can read and an MCP endpoint for an agent, all on their own machine. It does not suit anyone planning to run more than one backend replica, since the chat database, state files and in-memory jobs are all single-writer.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 60 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
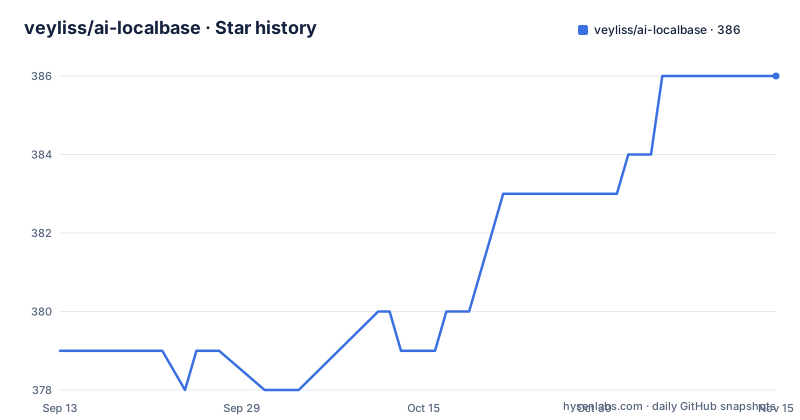
- veyliss/ai-localbase386 ★ · +7
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| veyliss/ai-localbase | 379 | 386 |
7 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Five compose files, and a container that refuses to start unconfigured
The deployment surface is wide. There is a base compose file, plus app-only, development and production variants, plus a Qdrant-only one, and the README walks through each separately.
The shortest path is two commands:
cp .env.example .env
docker compose up --build
Then the front end on port 4173, where you configure the chat and embedding models before anything else.
The Qdrant service is the most carefully written part of the deployment. Its entrypoint is a shell script rather than the image's own, and its job is to refuse to run in one specific bad configuration:
if [ -z "$$AI_LOCALBASE_QDRANT_API_KEY" ]; then
  echo "QDRANT_API_KEY must be set when QDRANT_BIND_ADDRESS is not loopback" >&2
  exit 1
fi
So the documented rule that the vector database must not be exposed without a key is enforced by the container, not left to the reader. Its health check is also hand-built: a raw TCP connection with a hand-written HTTP request for the collections endpoint, checking for a 200 in the response line, rather than depending on a binary being present in the image.
One detail in the backend service explains how local model access works at all. It declares a host gateway mapping, which is what lets the container reach an Ollama server running on the host rather than requiring a second copy inside the compose network.
Authentication is on by default and the first visitor wins
The default posture is the safe one, with a small window that needs closing deliberately.
Authentication is enabled by default in both the normal and the production compose setups. If you supply a password, the first start creates the root user and stores a bcrypt hash of it, and the backend rejects the initialisation outright if the password is shorter than eight characters.
If you leave the password empty while authentication is on, the first person to load the web page lands in an initialisation wizard instead of a login form. Anyone who reaches that page first sets the credentials. The documentation tells you twice to close this by setting a password or a setup token before deploying, and the setup token is the alternative for people who would rather not ship a password in an environment file.
Development is the exception, and it is explicit rather than implied: to skip the login while developing you have to set the authentication flag to false yourself.
There is a matching set of production choices around it. The backend binds to loopback by default and only exposes itself if you override the bind address. Proxy headers are not trusted by default, and the documentation says to enable that only when a controlled reverse proxy of your own sits in front and to preserve the forwarded protocol and host headers. Health, liveness and readiness endpoints return minimal probe responses; the detailed diagnostics are in the settings page after you log in.
The rate limits are similarly split. Requests per minute and a global concurrency cap both apply to the expensive endpoints, and each resource category is counted and capped separately.
Change your embedding model and you change your collection prefix
This is the setting that will cost you an afternoon if you miss it, and the documentation calls it out in the same breath as the environment template.
The vector size configured for Qdrant must match the dimensionality of your embedding model. Those two numbers are set in different places: one in the environment file, one in whichever embedding model you pick in the settings page. Nothing reconciles them at startup.
If you swap in an embedding model with a different dimension, you cannot simply restart. You need either a new collection prefix or a rebuild of the existing collection, because the stored vectors have the wrong shape for the new model and the old ones are not comparable to the new ones.
The same advice comes back for the hybrid search option. Before enabling it you are told to change the collection prefix and rebuild the index, because hybrid collections need named dense and sparse vectors rather than a single anonymous one. That is a specific enough implementation detail to be useful: it tells you the project uses Qdrant's named-vector feature rather than a payload-side workaround.
The Ollama path makes the trap easy to fall into, because the settings page offers a couple of embedding models with different sizes and a general option to use any OpenAI-compatible endpoint. Pick a chat model and an embedding model independently, and check the dimension before you upload anything.
Single instance, and do not scale the backend
The deployment section states the scaling limit plainly, and it is an application-layer limit rather than a database one.
Chat history lives in a local SQLite database, application state lives in local JSON files, and MCP jobs live in memory. None of those three supports multiple backend replicas writing at once. There is no shared store and no coordination.
The production compose file reflects that. It pins a specific published image version rather than tracking the latest tag, and upgrades and rollbacks happen by switching the image tag variable explicitly. The README asks you not to depend on the latest tag for anything, and not to scale the backend service horizontally.
There is also local guidance for anyone working on the code: source changes should be verified through the development or a local build compose file rather than by rebuilding the production one.
What that means in practice is that this is a single-tenant or small-team system by design. If you need more than one instance you are looking at externalising the chat store, the state files and the job queue, which is a real piece of work rather than a configuration change. The data directory list is short enough to check before an upgrade: uploads, application state, the chat database and the Qdrant storage, all backed up before you touch anything.
The MCP endpoint returns JSON, issues no session, and skips SSE
The MCP support is the feature that distinguishes this from a plain RAG script, and it has a defined protocol surface worth knowing before you point a client at it.
It runs as a tool service embedded in the backend, reached over HTTP with JSON-RPC. The supported methods are initialise, ping, tools listing, tool calls, and the initialisation notification. There is a capability self-check tool for confirming what the server exposes, and the tool set covers document detail, retrieval debugging, structured queries, evaluation-set generation and index rebuild, plus an asynchronous job workflow for import with progress, status, cancellation and a recent-task list. There are also composite tools aimed at agents: answering with sources, checking knowledge-base quality, comparing retrieval modes, and creating evaluation samples.
The limitation is in the transport. The implementation returns JSON, does not issue MCP session identifiers, and does not provide a server-sent-events stream. Clients must therefore accept a JSON content type rather than declaring only the event-stream type, or they will fail to negotiate. Nested mount paths ending in the same suffix work through the front-end proxy, and the front end handles the default path as well.
Permission tiers are three: read-only, write, and dangerous, with dangerous tools behind a one-shot confirmation. API keys carry scopes, with three recommended for normal use and a fourth for the delete-class tools. The old standalone token is treated as full MCP permission, is deprecated, and is refused by default; a migration flag exists and the documentation frames it as temporary.
MCP ships disabled, behind auth, with copy-paste client templates
The activation sequence is deliberate and worth following in order.
MCP is off by default. The advice for a server deployment is explicit: enable authentication first, then turn MCP on. The request timeout defaults to fifteen seconds and the per-minute rate limit to the same hundred and twenty as the rest of the API.
The last piece is a small quality-of-life decision that saves real time. The settings page includes ready-made configuration blocks for Cherry Studio, Claude Desktop, Cursor and a generic HTTP client, and the documentation works through one of them in full, including the content type, the bearer authorization header carrying an API key with MCP scope, and the accept header that has to list both the JSON and event-stream types for the negotiation issue above.
That example also explains a detail that would otherwise look like a typo: the client's type selector may label the transport as a streamable HTTP variant even though the server is returning JSON.
Behind all of it, the MCP tools reuse the existing knowledge base, session, configuration and retrieval services rather than reimplementing them. That is why there is no second index and no separate credential store, and why the version reported by the server is injected from the application release, showing as a development marker on a local build.
Audit logging is listed alongside the rate limiting and timeout, which is the part to turn on first if the endpoint is reachable beyond your machine.
Seven retrieval toggles and an evaluation set you generate yourself
The retrieval layer is where the engineering went, and the feature list reads like a list of known failure modes.
Documents are chunked and embedded in batches. Candidates are recalled dynamically rather than by a fixed top count, then reranked on keyword coverage so that a hit matching the query's terms outranks one that is merely similar. Redundancy is removed with maximal marginal relevance, which is what stops three near-identical chunks from filling the context window.
Two of the behaviours exist for the case where nothing good comes back. Low-confidence situations trigger a second, wider recall pass, and there is an embedding cache with an optional semantic layer on top so that similar queries do not re-embed.
Then four features are switches rather than defaults: hybrid search, a semantic reranker, query rewriting, and context compression. Each of those changes what reaches the model, and each of them is something you have to evaluate rather than assume.
Which is why the evaluation dataset generator matters. You can build a RAG evaluation set from the documents already in a knowledge base and check the result on a small sample before committing a configuration. For a system whose quality depends on seven interacting parameters, having a way to measure is the difference between tuning and guessing.
Bulk upload is handled the same way: an asynchronous indexing job with queryable progress and a cancel action, rather than a request that times out halfway through a large directory.
Windows contributors got a batch file, and the deployment docs are four files long
Small repository details that say how the project is worked on.
There is a Windows batch script at the repository root and no Makefile anywhere in the top-level entries. Combined with the five compose variants and the per-environment variable file, that says the deployment path is documented exhaustively for Docker and the local development path leans Windows.
The documentation set is broader than the README. There is a deployment guide for the images and versions, a troubleshooting file at the root, a security policy, and a docs directory holding the getting-started walkthrough, the architecture notes, the MCP reference, a backup and restore guide and a Docker operations guide covering restarts, health checks and third-party failure diagnosis for the model service and Qdrant.
One entry is deliberately outside version control. The retrieval improvement plan lives in a local workspace and is marked as not committed to git, which is a reasonable choice for a working plan and one more thing you will not find by browsing the repository.
The alternative to all of this is Qdrant with a thin API of your own. That gets you the same vector store and the same durability, and you write the retrieval pipeline yourself rather than inheriting seven parameters and no obligation to evaluate them. What you give up is the settings page, the seven-level rate limiting, the permission tiers on the MCP surface, and the evaluation dataset generator that makes the parameters arguable rather than decorative.
Editorial conclusion
AI LocalBase suits someone running a personal or small-team knowledge base who wants a retrieval stack they can read and an MCP endpoint for an agent, all on their own machine. It does not suit anyone planning to run more than one backend replica, since the chat database, state files and in-memory jobs are all single-writer. Verify two things before you start: that your embedding model's dimension matches the configured vector size, because changing it means a new collection prefix or a rebuild, and that you set a password or setup token before the first page load, because authentication is on by default and the first visitor otherwise gets the initialisation wizard. It is MIT licensed, the current release is v1.4.11 and the last push was on 2026-09-17.
Frequently asked questions
How do I start AI LocalBase?
Copy the environment template to .env, run docker compose up --build, and open the front end on port 4173. Then go to the settings page and configure the chat and embedding models separately, either against a local Ollama endpoint or any OpenAI-compatible base URL.
What does AI LocalBase need for embeddings, and what happens if I change model?
The configured vector size must match the dimensionality of your embedding model. If you switch to a model with a different dimension you need a new collection prefix or a rebuild of the existing collection, and the same applies before enabling hybrid search so that collections use named dense and sparse vectors.
Can I run more than one backend replica of AI LocalBase?
No. Chat history in a local SQLite database, application state in local files and MCP jobs in memory are all single-writer, and the documentation explicitly says not to scale the backend service horizontally. Production deployments pin a specific image tag and switch versions explicitly rather than tracking the latest tag.
Does AI LocalBase expose Qdrant to the network?
Not by default. The Qdrant ports bind to loopback, and the container's entrypoint refuses to start if the bind address is not loopback and no Qdrant API key is set. To allow other machines to reach it you have to override the bind address yourself and configure a key and firewall rules.
How do I connect an agent to the AI LocalBase MCP server?
Enable authentication first, then enable MCP, and register the HTTP JSON-RPC endpoint, by default on the /mcp path, with an API key carrying an MCP scope. The transport returns JSON, issues no session identifiers and does not provide an event stream, so the client must accept a JSON content type rather than declaring only the event-stream type.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/veyliss-ai-localbase)Star history chart for your README
[](https://hysenlabs.com/projects/veyliss-ai-localbase)Was this useful?