VeADK reads config.yaml from your project root and ships Studio switched off
An open-source kit for agent development, integrated the powerful capabilities of Volcengine.
At a glance
- What is it?
- Volcengine's agent development kit wraps Google ADK with Volcengine cloud integrations, an AgentKit application factory, a Feishu channel and 17 numbered examples. The minimal path is an Agent() call and a four-line model config, and most of the platform machinery stays disabled until you turn it on.
- Who is it for?
- Use VeADK when your agents have to run on Volcengine ARK models or inside AgentKit, and when you want Google ADK's architecture with the platform wiring already done. Skip it if you need Python 3.14, or if you are on Apple silicon and cannot tolerate a dependency set that CI never exercised on that architecture, since the pinned sqlalchemy and litellm ranges and the documented greenlet failure both come from a test matrix running on x86_64.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
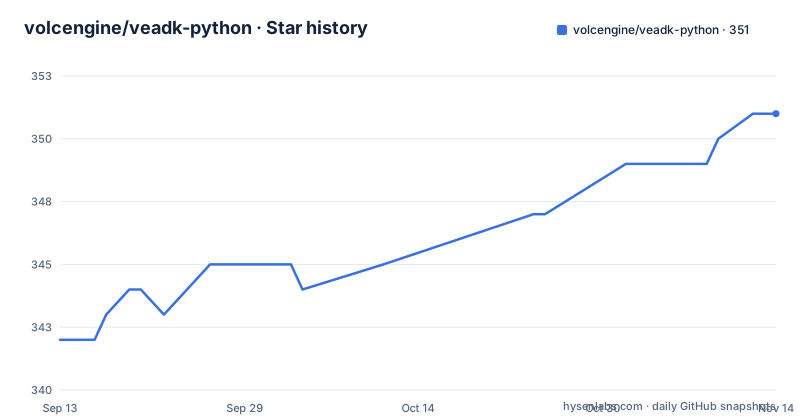
- volcengine/veadk-python351 ★ · +9
| Repository | 2026-09-13 | 2026-11-14 |
|---|---|---|
| volcengine/veadk-python | 342 | 351 |
9 Stars in the last 62 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
config.yaml in your own project root is what the kit actually reads
Configuration is a file, not constructor arguments. The guidance is to create a config.yaml in the root directory of your own project, and VeADK reads it automatically. The repository ships two ready references at the top level, config.yaml.simple and config.yaml.full, so the shortest path to understanding the surface is to diff those two rather than to read the configuration pages.
A minimal agent needs one model block.
model:
  agent:
    provider: openai
    name: doubao-seed-1-6-250615
    api_base: https://ark.cn-beijing.volces.com/api/v3/
    api_key: # <-- set your Volcengine ARK api key here
Read the pairing in that block carefully. The provider is set to openai while api_base points at a Volcengine ARK endpoint in Beijing, so the shipped example is a model on ARK reached through a provider key that is not OpenAI. Copy that combination when your model lives on ARK, and expect to change both halves together if it does not.
Everything else in the file is optional in the sense that the kit will start without it, which is also why a fresh config tends to fail later rather than at load time.
Agent() with no arguments is the whole minimal agent, and the tutorial is a notebook
The first runnable example is five statements long.
from veadk import Agent
import asyncio

agent = Agent()

res = asyncio.run(agent.run("hello!"))
print(res)
No model is passed to the constructor and no tools are registered, so everything the agent can do comes from that config.yaml. The corollary is worth stating: a typo in the model block surfaces as a failure inside run(), not as a validation error at construction.
For learning the rest, the project ships a tutorial as a Jupyter Notebook, veadk_tutorial.ipynb, and points at Google Colab as the alternative way to open it, so the first hour does not require a local environment at all.
Installation itself is one line from PyPI, with extensions as a separate extra.
pip install veadk-python
pip install veadk-python[extensions]
Building from source uses uv instead, and the README is specific about the interpreter it expects for that route: Python 3.12, created with uv venv, then uv sync for the base requirements, or uv sync --extra database, --extra eval and --extra cli for the extras you actually want, and uv pip install -e . for an editable install.
Studio tools and routes ship disabled, and the app factory exists to keep platform code out of your agent
Platform serving is a separate concern from agent logic, and the kit draws that line with a factory.
from veadk import Agent
from veadk.integrations.agentkit import create_agentkit_app

root_agent = Agent(name="customer_support")
app = create_agentkit_app(
    root_agent,
    enable_studio_tools=True,
)
The stated reason for the factory is that it keeps platform routes and lifecycle code out of the agent module, so the thing you iterate on is not tangled with the thing you deploy. A complete generated project sits in examples/generated_agentkit_project.
Two capabilities are opt-in and both default to disabled: Studio-owned dynamic tools and Studio HTTP routes, enabled with enable_studio_tools=True and enable_studio_routes=True. That default is the right one to keep in mind when reading the Studio feature list, since most of what follows describes what you can have rather than what you get.
The metadata endpoint is the other half of that surface. It reports the root agent's name, description, model, sub-agents, tools, skills and mounted component summaries, and it advertises mounted smart-search sources so Studio can disable the ones that are not available before anything is queried.
Browser clients never receive Volcengine credentials, and secrets stay out of generated YAML
Three separate mechanisms keep keys out of places they should not be, and they are worth separating because they solve different problems.
First, requests to account-scoped resources are signed on the server. That covers browsing AgentKit Skill Spaces and their paginated skill lists by region and project, and it means the browser client authenticates to Studio rather than holding a Volcengine credential. The same metadata path queries an agent's web-search tool, KnowledgeBase or long-term memory without exposing component credentials either.
Second, deployment values are not source. Settings entered in the Studio deployment flow, which cover Feishu, knowledge base, short- and long-term memory and observability, are mirrored into a deployment environment-variable summary and converted into VeADK runtime environment variables only at deploy time. Secrets are never written into generated source or exported YAML.
Third, build failures are readable without being dangerous. When a cloud image build fails from the bundled Web UI, the deployment error carries a credential-safe excerpt of the build log, so a Dockerfile or dependency failure can be diagnosed from the error itself.
Feedback follows the same discipline: like and dislike controls on completed answers write server-side into per-agent evaluation sets named {agent_name}_good_case and {agent_name}_bad_case, with stable item keys so repeated clicks stay idempotent.
More than one instance means a database behind short-term memory
Short-term memory is where a deployment quietly stops being correct. The Studio deployment documentation says that multi-instance runtimes should use a database-backed short-term memory store so sessions remain available across instances, and the extras list carries a matching uv sync --extra database.
The failure mode is easy to miss locally. A single process keeps its session state in memory, everything appears to work, and the problem only appears once a second instance is serving requests or a restart moves the conversation elsewhere. Nothing in the minimal example warns about it, because the minimal example is one process by construction.
The repo layout suggests the same split at a larger scale: docker/, frontend/, plugins/ and veadk/ at the top level, and seventeen numbered example directories running from 01_quickstart through 17_remote_sandbox_agent, with 03_short_term_memory and 09_long_term_memory as the two that matter for this decision. Later numbers cover routing, tracing, an MCP tunnel, OpenViking, and sandbox variants, which tells you the sandbox and hosting options are where this kit is still spreading out.
Choose the store before you scale out, not after the first session disappears.
The macOS arm64 greenlet trap is in pyproject.toml because CI runs on x86_64
The dependency block carries unusually candid comments, and they explain real upgrade cost rather than aspiration.
google-adk is required at >=1.34.0. On 2.x it moved litellm and sqlalchemy behind extras, so VeADK declares both directly to stay compatible across 1.x and 2.x. That means litellm is pinned into a narrow window, >=1.83.7 and <=1.83.14, and pydantic-settings is held at exactly 2.10.1, with deprecated at 1.2.18. A project that needs a newer LiteLLM will be fighting this package rather than the upstream library.
The sharper note concerns platform coverage. sqlalchemy is declared with the asyncio extra because that extra pulls greenlet, which the async engine requires and which the database session service therefore needs. The comment records what happens without it: a bare install on macOS arm64 raised the greenlet library is required error on the first session write to sqlite, mysql or postgres, and CI never saw it because ubuntu-latest is x86_64, where a different platform marker matches.
So the supported interpreter range is >=3.10,<3.14 while the from-source instructions create a 3.12 environment. Both facts are in the repository; they simply do not say the same thing.
Project hygiene is otherwise strict: pre-commit is expected before a first contribution, and the unit tests must pass or CI rejects the pull request.
pytest -n 16Feishu maps thread_id onto session_id so memory survives the chat
Chat channels are where an agent's identity usually breaks, because a messaging app has no notion of the session key an agent runtime expects. The Feishu extension solves that with explicit mapping.
from veadk import Agent, Runner
from veadk.extensions import FeishuChannelExtension

agent = Agent()
runner = Runner(agent=agent, app_name="feishu_demo")
channel = FeishuChannelExtension(runner=runner)
It maps union_id to user_id, and thread_id or chat_id to session_id, which is what lets VeADK memory and tracing work directly inside Feishu conversations rather than in a parallel web session. Credentials come from TOOL_FEISHU_CHANNEL_APP_ID and TOOL_FEISHU_CHANNEL_APP_SECRET, or from tool.feishu_channel in config.yaml, and the extension is imported from veadk.extensions.
Feishu also appears in the Studio deployment flow as one of the configurable feature sections, so a Feishu deployment can be driven from either the config file or the Studio screen.
The wider picture of integrations is visible in the example directories: a2ui_agent, basic-app, and several codex variants including codex_runtime_on_agentkit and codex_with_skill_and_mcp. Studio manages user-owned Codex, OpenClaw and Hermes sessions, where leaving a Codex conversation disconnects it and OpenClaw and Hermes expose their main interface and Terminal through Studio. That is a wide surface for a kit whose minimum example is one constructor call.
Editorial conclusion
Use VeADK when your agents have to run on Volcengine ARK models or inside AgentKit, and when you want Google ADK's architecture with the platform wiring already done. Skip it if you need Python 3.14, or if you are on Apple silicon and cannot tolerate a dependency set that CI never exercised on that architecture, since the pinned sqlalchemy and litellm ranges and the documented greenlet failure both come from a test matrix running on x86_64. Check three things first: that your ARK key reaches the api_base you configured, that you know which Studio capabilities you are switching on, and that short-term memory has a database behind it if you run more than one instance. The licence is Apache 2.0, releases landed on 2026-09-14, 2026-09-15 and 2026-09-28, and the last push was on 2026-10-01.
Frequently asked questions
How do I install VeADK Python and run a first agent?
Install it with pip install veadk-python, put a model block in a config.yaml at the root of your own project with your Volcengine ARK api key, then call Agent() and await agent.run(). A tutorial notebook, veadk_tutorial.ipynb, is included.
Which Python versions does VeADK support?
The packaging metadata requires Python >=3.10,<3.14, and the build-from-source instructions create a Python 3.12 environment with uv before running uv sync.
Are VeADK Studio tools and HTTP routes enabled by default?
No. Both are separate Runtime capabilities that default to disabled and are enabled explicitly with enable_studio_tools=True and enable_studio_routes=True.
What does VeADK do when a deployment builds more than one runtime instance?
The documentation directs multi-instance runtimes to a database-backed short-term memory store so sessions stay available across instances, which corresponds to the database extra available with uv sync.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/volcengine-veadk-python)Star history chart for your README
[](https://hysenlabs.com/projects/volcengine-veadk-python)Was this useful?