deja says seventeen agents in its description and thirty-five in its highlights
Your agents already solved this. deja finds it, it indexes the sessions your coding agents already wrote to disk, months of history from before you installed it, and recalls them automatically at session start in all seventeen. 84.9% hit@1 on LongMemEval-S, no LLM, no embeddings. One zero-dep binary, fully local.
At a glance
- What is it?
- A Go binary with no dependencies that indexes the session history your coding agents already wrote to disk, then recalls it at session start. It works without a model or embeddings, its benchmark corpus is synthetic, and its install path is a shell script piped from a URL.
- Who is it for?
- deja is worth trying if you use more than one coding agent, because the problem it solves is that your fixes do not travel between them, and a local index is the least invasive way to make them travel. Three things to check first.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
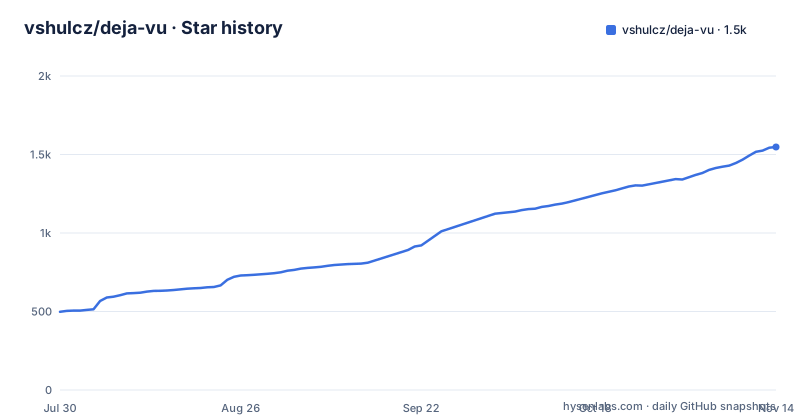
- vshulcz/deja-vu1,548 ★ · +1,050
| Repository | 2026-07-30 | 2026-11-14 |
|---|---|---|
| vshulcz/deja-vu | 498 | 1.5k |
1,050 Stars in the last 107 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository description says seventeen agents and the highlights say thirty-five
Start with a discrepancy, because it is the first thing a reader hits.
The repository description says recall arrives automatically at session start in all seventeen agents. The highlights section of the project file says all thirty-five agents read the same index, and names Claude Code, Codex and Cursor plus thirty-two more. The anchor link in that same sentence points at the supported harnesses section, which is where the real list lives.
Seventeen against thirty-five is not a rounding difference. Either the description was written when the count was half of what it is now and nobody updated it, or one of the two numbers counts something narrower, such as harnesses with a package of their own against harnesses with a plugin bundle. The file does not say which.
Neither number is the interesting part of this project. The interesting part is that the index is shared. The example is a fix found in Codex coming back in Claude Code, in Cursor, or in opencode, which is a problem no single-agent memory feature can solve because each agent only sees its own history.
So the design bet is that the disk is the common denominator: every harness already writes transcripts to disk, so index that directory and any of them can read the result.
Install is a shell script piped from a URL, and Windows is sent elsewhere
The two commands at the top are the whole install on macOS and Linux:
curl -fsSL https://raw.githubusercontent.com/vshulcz/deja-vu/main/install.sh | sh
deja install --auto
The second command is where the work happens. It wires MCP recall into every agent it finds, turns on session-start recall where the agent supports it, and builds the first index so the next session does not pay for it.
Windows is excluded from that path, and the file says so plainly: the install script exits with an unsupported OS because it is a shell script. The alternatives are named instead:
scoop install deja-vu
winget install vshulcz.deja-vu
or taking a windows_amd64 zip from the latest release and putting deja.exe on the PATH.
The pip-install-anything-from-the-internet pattern is on the primary path here, and there is no checksum, no version pin and nothing to read before it runs. Elsewhere the project is careful: Homebrew, go install, npx for trying it without installing, and a bundle file for desktop apps that take MCP servers as bundles, which carries the binary inside it. Claude Code, Cursor, Qwen and OpenClaw take the same plugin bundle from their own marketplaces, and Codex has a bundle of its own.
Copilot CLI is the odd one out. It installs the plugin but takes only the skill, so it needs a different install command.
The index has no model in it, and the benchmark corpus is synthetic
There is no model, no embeddings and no server. Keys and tokens are stripped as the index is built, and the binary has no external dependencies at all: the module file declares a module path and a Go version and then stops, with no require block.
That is why the retrieval numbers are the interesting claim. The project file reports 97.2 percent recall at five on LongMemEval-S, alongside 96.6 percent published by MemPalace and 95.2 percent by agentmemory. It also reports 17.6 seconds to index 19,195 sessions, and says the next of seven tools takes 72 seconds.
Two things about those numbers. The comparison figures are the other projects' own published numbers, not a head-to-head the author re-ran. And the project is explicit that the corpus is synthetic, in a line that reads two real runs against a synthetic corpus, nobody's history is published.
The Makefile shows what that means concretely. The demo target builds an OpenCode database from a shell script under fixtures/synthetic, then points the binary at fixture directories through environment variables named after the driver, including a Claude root, a Codex root and an OpenCode database path, with the index written to a temporary directory, and finally runs a rebuild over a fixture name.
So the evidence is reproducible and the history is invented. That is a fair trade for a privacy tool, and it is not the same thing as being right about your own transcripts.
Rejected decisions are recorded and replayed on every later hit
One command is the feature that makes this more than a search box.
`deja promote <id> --state rejected` marks a decision you reverted. After that, every later hit on the same subject says it was tried, and says why it was dropped. `--state accepted` takes the mark back.
Think about what that does to an agent. Recall from a transcript is not neutral: an agent reading its own March conversation finds the thing you tried, and without a marker it is as likely to redo it as to avoid it. The mark converts a search result into a decision record.
The cost is ownership, and the project does not pretend otherwise. Every mark is something you maintain, and a stale accepted mark on something you have since abandoned is worse than no mark at all, because the agent will treat it as settled. The CLI has one command for the whole lifecycle and no way to bulk-review marks.
The surrounding feature list is built on the same principle of telling the truth rather than sounding confident. A hit reports how many files this session touched have changed since, in a sample phrased as four, and stays quiet when it cannot tell rather than guessing.
It indexes the commands and the edits, not just the conversation
Most session search indexes prose. This one is described as indexing the work rather than the talk, and the list of what it stores is specific.
The files each turn opened. The commands, with their exit status, which means a failed command is findable as a failure rather than as text that happened to contain an error message. And the exact spans an edit replaced, which is what lets a search result point at code rather than at a paragraph about code.
That is a meaningfully different index from the one your editor already has. An editor's history search finds the file. This finds the turn that decided to change it, across thirty-five harnesses that may not share an editor at all.
Recall timing is the other half. The highlights say recall arrives at session start, before a file is edited or a command runs, and again after a command fails. The second one is the interesting case: a failure is exactly when an agent should reach for what you already learned about that failure, and a tool that only fires at session start is absent from the moment it is most useful.
For moving between machines there are two more commands, one that syncs to a named host over ssh with no cloud in between, and one that hands a thread off to a named agent.
Compaction kept the decisions and lost the commands
Every agent summarises a long conversation, and the summary is lossy in ways that matter.
The measured figure is over 43 compactions, where the summary kept 77 percent of the decisions and 0.2 percent of the commands. Read together those two numbers say the compression preserves intent and destroys evidence: after a compaction you still know what was decided, and you no longer know what was tried, what ran, what failed, or what the exit status was.
That is exactly the shape of the problem this project indexes. A command is the thing that turns a decision into a fact about the machine, and a summary that keeps zero point two percent of them cannot tell a later session which of yesterday's approaches had already been ruled out.
So the argument for keeping the raw transcripts on disk is not sentiment. It is that the parts agents summarise away are the parts that cannot be regenerated: a command that exited non-zero, an edit that was reverted, a file that was opened and closed again.
The compaction behaviour is documented separately, which is the right place for it, since it is the boundary between what the agent knows and what the tool knows.
The module declares no dependencies and the image installs sqlite anyway
The build files are small enough to read in full, and they say two contradictory things about what the binary needs.
The module file contains a module path and a Go version, 1.25, and no require block. That is the zero-dependency claim made concrete.
The container build compiles with CGO disabled, trims the path and strips the binary with size flags, then copies it into an Alpine image whose entry point is the binary and whose default command is the MCP server. The comment above the builder says the server speaks stdio, so the container needs nothing beyond the binary.
And then the runtime stage runs an apk add for sqlite. If the binary is statically linked with CGO off, it does not need the SQLite library from the system, so that line is either cargo cult or a leftover from a version that did link it. Either way it makes the image larger and gives a reader the impression that the MCP server has a native dependency it does not have.
There is also a version mismatch worth noting: the module asks for Go 1.25 and the builder image is golang:1.27-alpine. That direction is safe, since a newer toolchain builds an older language version, but it does mean the tested compiler is not the declared one.
The rest of the build tooling is conventional: goreleaser with a snapshot target, golangci-lint, and go test across the module.
The repository root package.json belongs to a different agent harness
The root manifest is the strangest file in the repository.
Its name is dsh-deja, it is marked private, and its own description says what it is: a repository-root manifest for the DeepSeek Harness plugin that lives in a subdirectory, the same package published to npm under a shorter name. It exists so the plugin can install from a bare git URL or from a path-qualified reference, and the npm package is described as the shorter route. Its entry point re-exports that subdirectory, its file list contains only that subdirectory plus the readme and licence, and its single dependency is the project's own published npm package at the same version, 0.21.5.
So a Go project has a Node manifest at its root whose job is to make a third-party harness able to install a JavaScript shim for it. Twenty-six keywords ship with it, and the list mixes the harness name, the memory idea, session search and local-first positioning.
The rest of the root explains the same pattern at scale. There are plugin and extension manifests for several agent hosts side by side, a Claude plugin directory, a Codex plugin directory, a Gemini extension file, a Kimi plugin file, a generic plugin file, an MCP config, a registry server file, a marketplace entry, a plugin scanner configuration, and an agents directory. One repository, at least nine packaging shapes.
The release stream matches that sprawl: a v0.21.5 tag, a rolling nightly tag published the same day, and v0.21.4 two days earlier.
Editorial conclusion
deja is worth trying if you use more than one coding agent, because the problem it solves is that your fixes do not travel between them, and a local index is the least invasive way to make them travel. Three things to check first. Count the harnesses yourself, because the two numbers published disagree, and remember that support is uneven: Copilot CLI takes only the skill, not the bundle. Decide whether the marks are worth maintaining, since rejected decisions are recorded and replayed on every later hit, which is the feature that makes recall trustworthy and also the thing you now own. And read the benchmark framing: the corpus is synthetic and the comparison figures come from other projects' own published numbers, so treat 97.2 percent as a claim about a fixture set rather than about your history.
Frequently asked questions
What does deja-vu do with my coding agent sessions?
It indexes the session history your agents already wrote to disk and recalls it at session start. The index covers prompts and responses plus the work itself: the files each turn opened, commands with their exit status, and the exact spans an edit replaced. There is no model and no embeddings, so nothing leaves the machine.
How do I install deja-vu?
On macOS and Linux, curl the install.sh piped into sh and then run deja install --auto, which wires MCP recall into every agent it finds and builds the first index. Homebrew, go install, npx and a bundle file are alternatives. On Windows the shell script exits with unsupported OS, so use Scoop or winget instead.
How many coding agents does deja-vu support?
The repository description says seventeen agents while the highlights say thirty-five, naming Claude Code, Codex, Cursor and 32 more that read the same index. Support is uneven in practice: Copilot CLI installs only the skill rather than the bundle, and Codex has a bundle of its own.
Does deja-vu send my code or my keys anywhere?
No model, no embeddings and no server, and keys and tokens are stripped as the index is built. The module declares no dependencies at all. Moving between machines uses deja sync over ssh with no cloud in between.
How does deja-vu handle a decision I later reverted?
You mark it with deja promote and the rejected state, and every later hit on the same subject then reports that it was tried and why it was dropped. The accepted state takes the mark back. A hit also reports how many files this session touched have changed since, and stays quiet when it cannot tell.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vshulcz-deja-vu)Star history chart for your README
[](https://hysenlabs.com/projects/vshulcz-deja-vu)Was this useful?