Pydantic Deep Agents points two of its own links at a repository with a different name
Open-source, self-hosted Claude Code - a terminal AI assistant and the Python framework behind it. Tool-calling, sandboxed execution, multi-agent teams, skills, checkpoints, unlimited context - on Pydantic AI, any model.
At a glance
- What is it?
- A terminal assistant and a Python framework on the same harness, whose distinguishing feature forks a live run into isolated branches and merges the winner with an AI judge. The default merge mode needs no human, the sandbox behind the one-call framework is an optional extra, and the install script is fetched from a repository path this repository does not use.
- Who is it for?
- The forking mechanism is the part worth understanding, because the isolation is real: a copy-on-write overlay, a per-branch budget cap and a per-branch steering message, which is more thought through than most agent scaffolds. Two things to decide before using it unattended.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 15 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
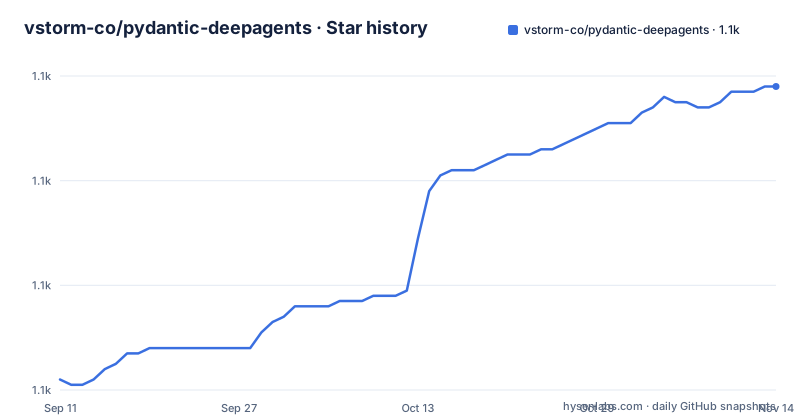
- vstorm-co/pydantic-deepagents1,118 ★ · +56
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| vstorm-co/pydantic-deepagents | 1.1k | 1.1k |
56 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The install command fetches from a different repository name
The primary install path is a piped script:
curl -fsSL https://raw.githubusercontent.com/vstorm-co/pydantic-deep/main/install.sh | bash
pydantic-deep
The path segment in that URL is one name, while this repository is called something else, and the security badge near the top links to a file under that same other name. The distribution itself is consistent: the package is called without the agents suffix, the manual alternative installs that name with a command-line extra, and the index link points at the matching project page. So the naming is settled everywhere except the two URLs, and both of those are the ones a reader types first. Worth checking whether the script URL resolves at all before running anything, and worth noting that a piped installer is a poor place to have a stale path.
The default merge mode resolves a fork without asking you
When a run branches, the coordinator resolves it with one of four acceptance modes: a manual picker, an automatic decision, a vote, or an automatic decision with a fallback. The third of the four, the one with a fallback, is the default. That means an unattended run can fork, pick a winner and adopt its history as the parent run's continuation with nobody reviewing it. The opt-in surface is a single flag, and turning it on hands the model six tools, including forking, inspecting branches, merging or selecting, diffing them, reading the fork cost and terminating a branch. So the model holds both the budget and the kill switch on its own work. The counterweight is a per-branch cost cap in dollars, which is the right place to put the limit, and it only bounds spend, not the decision to merge.
The confidence formula is published and uncalibrated
The page gives the scoring expression outright: a weighted sum of quality spread, test pass ratio and internal consistency, at four tenths, four tenths and two tenths. That is unusually good practice, and the diagram then shows what the numbers do. Three branches refactor the same authentication code; one passes all eight tests, one passes six, and one passes all eight. The judge adopts the first, and the confidence figures printed next to the branches are 0.71, 0.42 and 0.55. So the branch that tied on tests won on the two terms nobody can compute from the page, and the branch that also passed everything scored lowest. Nothing explains what quality spread is measured against, how internal consistency is derived, or why those weights rather than others. The formula is checkable and the inputs are not.
Isolation is copy-on-write, which is the part done properly
The branch model has three properties and each is a real answer to a real problem. A copy-on-write filesystem overlay means a branch reads through to the parent and writes only locally, so three agents refactoring the same module do not overwrite each other. Each branch gets its own steering message, so you can tell one to use a decorator and another to use a context manager without either seeing the other's instruction. And each branch carries its own dollar cap, so one branch cannot spend the run's whole budget. The surviving branch's history becomes the parent's continuation, which means the run continues as a single history rather than as a tree of merged transcripts. There is a second mode for anyone who would rather not have a model judge anything: give it a real test command and a timeout and let exit codes pick the winner.
The one-call framework needs an extra for the sandbox it advertises
The framework is sold on a single function that hands a model a filesystem, a shell, planning, memory, sub-agents, sandboxed execution, the protocol connector and unlimited context. The base dependency list does not include a sandbox. It does include a package for summarisation, which is almost certainly how the unlimited context claim is delivered, though the page never says so. The sandbox lives in an optional extra that pulls a container backend, skills support lives in another extra for the frontmatter parser, and the terminal assistant lives in a third. So the one call works, and the three capabilities most likely to be the reason you wanted it need an extra each. The page does not mark any of the eight capabilities in that sentence as optional, which is the part that misleads.
The comparison table has a staleness date and no links
A nine-row table sets this project against four named alternatives, with three states per cell: first class, partial or via extensions, and not available, plus a fourth state meaning you wire it yourself. Two rows are claims of absence rather than comparison. One says live run forking is unavailable in all four competitors, and the text above it says in four separate sentences that the three named tools cannot do it. Another marks their sandboxed execution as yours to build. Nothing in the table links to any of the four projects, versions any of them, or cites a feature request or a source for the absence claims, and the footnote dates the whole thing to a specific month, four months before the page in front of you. A table that says everything wins is a table to discount unless each cell can be checked.
Type checking runs with warnings switched off
Type safety is one of the four claims in the opening paragraph, and the build tooling takes it seriously: a linter with a format check, two separate type checkers, pre-commit hooks, a frozen dependency sync across four dependency groups, and a target that installs a separate environment for each supported interpreter from 3.10 to 3.13. The detail worth naming is in the fast type check target, which sets an environment variable telling the checker to ignore warnings before it runs. A strict mode flag is set in the project configuration and warnings are suppressed in the make target that a contributor is most likely to run. Nobody is hiding anything, since both files are in the repository, but the default check is a weaker check than the headline implies.
Editorial conclusion
The forking mechanism is the part worth understanding, because the isolation is real: a copy-on-write overlay, a per-branch budget cap and a per-branch steering message, which is more thought through than most agent scaffolds. Two things to decide before using it unattended. The default acceptance mode merges without asking, so a fork can be resolved and adopted into the parent run with nobody present, and the confidence score that picks the winner is a published weighted sum with no stated calibration. And the one-call framework is thinner than its capability list implies, because sandboxed execution is an optional extra rather than part of the base install. Separately, check the install path before you run it, since the script URL and the security link both name a repository other than this one.
Frequently asked questions
What is Pydantic Deep Agents?
Two things in one repository: a self-hosted terminal assistant that is an open-source alternative to a commercial coding tool, and the Python framework behind it. Both run on Pydantic AI, work with any model, and can fork a live run into isolated parallel branches that an AI judge merges back.
What does live run forking do in Pydantic Deep?
It splits an in-flight run into parallel branches, each fully isolated with a copy-on-write filesystem overlay, its own steering message and its own dollar cap. The coordinator resolves the fork with one of four modes, of which an automatic decision with a fallback is the default, and the winning branch's history becomes the parent run's continuation.
How does the AI judge pick the winning branch?
A published weighted sum of quality spread, test pass ratio and internal consistency, at four tenths, four tenths and two tenths. The page gives the formula but not the inputs: nothing explains what quality spread is measured against or how internal consistency is derived, and the worked diagram has two branches passing all tests with different confidence scores.
What models does Pydantic Deep support?
Any model, because both the assistant and the framework run on Pydantic AI rather than on a single vendor's client. The one-call example names a specific model string, and the comparison table marks the commercial alternative as Anthropic-only while the two other open-source tools are marked as supporting any provider.
How do I install Pydantic Deep?
A piped install script followed by running the command, or a pip install of the package with a command-line extra on Windows and for manual setups. The script is fetched from a raw file URL whose repository path does not match this repository's name, and the manual alternative installs a package whose name is shorter than the repository's.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vstorm-co-pydantic-deepagents)Star history chart for your README
[](https://hysenlabs.com/projects/vstorm-co-pydantic-deepagents)Was this useful?