The SAGE router decides ownership, and says what it does not do
Sprix AI at Yuzhitongxing - state-aware SELF/COLLABORATE/HANDOFF routing for A2A agent networks.
At a glance
- What is it?
- Sprix SAGE Router is a Python research implementation of a decision layer for agent networks: given a task already in flight, it chooses between finishing it, recruiting collaborators, or handing the whole thing to a peer. The routing is built on a small set of named mechanisms the project explicitly refuses to claim as its own, and the A2A integration layer stops short of sending anything.
- Who is it for?
- This project fits someone building multi-agent task execution who has an A2A endpoint or marketplace producing skill cards, bids and task state, and wants the choice of execution mode made in one auditable objective rather than in per-agent prompt logic. It does not fit anyone looking for a working A2A client, because the integration layer deliberately does not transmit tasks, authenticate endpoints or verify signatures, and that work stays with the client.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 79 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
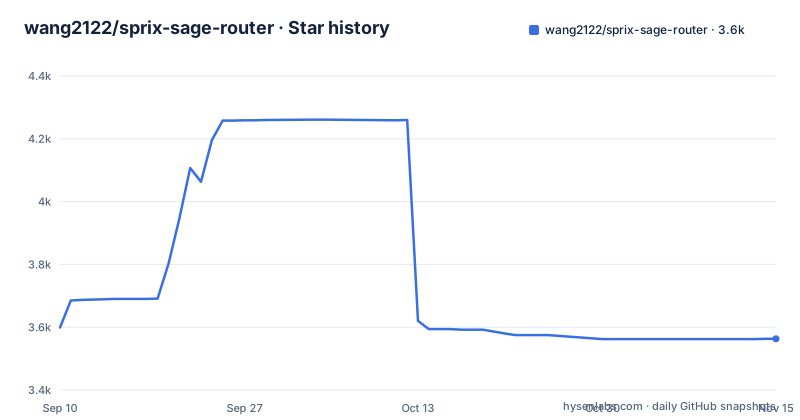
Star history
- wang2122/sprix-sage-router3,563 ★ · -36
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| wang2122/sprix-sage-router | 3.6k | 3.6k |
-36 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three routes that differ only in who owns the work
The routing table has three rows and one varying column.
SELF keeps the incumbent agent as owner, and is for when its existing capability and accumulated context are already sufficient. COLLABORATE keeps the incumbent as owner too, and brings in a small complementary team to cover missing requirements. HANDOFF is the only row where ownership moves: a peer takes the whole thing.
So the first two routes differ in team size and the third differs in accountability, and the table's last column gives the condition for each: existing capability, missing requirements, and specialist advantage exceeding context-transfer loss.
That last condition is the interesting one, because it is the only place in the design where a qualitative judgement is made explicit rather than priced. Handoff is not simply the strongest specialist winning; it is weighed against the cost of moving accumulated work to someone else.
The three share one action space constrained by permissions, budget and deadline, which is what makes them comparable at all.
The project lists the mechanisms it will not claim
One paragraph of the page is about what is not an invention, and it is unusual to find.
Named as replaceable implementation mechanisms: a noisy-OR aggregation, beam search, a linear utility, Beta beliefs, online logistic regression, and communication edges induced by the dependency graph.
Those are ordinary components. Writing them down as substitutions rather than contributions tells you two things about the design. The first is that the contribution is claimed to be the objective and the decision procedure, not the machinery. The second is that each of these can be swapped without breaking the comparison, which is what lets the baselines use the same registry and limits.
The same paragraph then lists what is claimed, as engineering features rather than research: permission-first filtering, bounded candidate search, workload-sensitive quotes, auditable alternatives, degraded-route flags, state persistence, and transport-neutral execution plans.
Reliability is tracked per agent and per requirement rather than as one reputation number, on the stated ground that a single score does not transfer across skills.
Artifact portability is the hinge between retaining and switching
The reuse fraction is the one piece of arithmetic worth reading closely, because it is what separates the three routes numerically.
If the current owner has completed a fraction of a requirement, a candidate owner reuses that fraction when it is kept, and the fraction multiplied by artifact portability when the owner changes.
Portability is therefore a per-requirement number in zero to one that says how much of the completed work survives the move. Perfect portability means a switch costs nothing in lost work. Zero means the new owner starts from nothing on that requirement.
Two consequences are stated. Only the assigned owner contributes coverage for a requirement, so adding a teammate who is not assigned to it no longer produces an aggregation gain, which removes the usual incentive to staff a task with everyone available. And the same reused fraction reduces projected remaining cost and duration, so the work already done is not charged twice inside the learned success probability.
That second point is the difference between a planner that re-estimates from scratch and one that knows what is already on disk.
The prototype does not transmit, authenticate or verify
The A2A section states its own limits in the clearest sentence on the page.
The current prototype intentionally does not transmit tasks, does not authenticate endpoints and does not verify signatures.
What remains with an A2A client is named explicitly: sending a message, streaming, polling, cancellation, and secure handling of artifacts.
So the boundary is that the library produces a plan and stops there. The conversion step turns the selected route into a transport-neutral execution plan containing ownership, assignments, dependency edges, communication edges, estimated resources, and a rationale, and the page says the integration module also validates declared skill identifiers against locally calibrated evidence before any of that happens.
That is a coherent line to draw for a research output. It is also the line to check first if you are evaluating whether the project is usable, because nothing here talks to a network.
What it does provide is the decision, plus the paperwork to justify it.
Protocol signals become filters before anything is scored
A mapping table converts what an agent network says into what the router consumes, and the order of the rows matters more than it looks.
Declared skills on an agent card become a normalised capability vector. Security requirements become a hard permissions eligibility filter. Supported input and output modes become a compatibility filter that runs before scoring.
Only after those three filters does anything get evaluated. Task status, artifacts and failures become the execution state, which carries active ownership, completed nodes, in-flight quality and progress, and per-artifact portability. A provider quote becomes a bid of cost, latency and confidence. A completed task evaluation feeds contextual trust, explicit pairwise evidence, the success model and bid-fidelity updates.
So credentials and mode compatibility are gates rather than terms in the objective. That ordering is what stops the router from proposing an assignment it is not permitted to run, and it is also why the permission filter is listed as an engineering feature rather than part of the scoring.
The figure caption above the table describes the same pipeline in prose: filter candidates, compare the three modes, search assignments and schedules jointly, rank feasible plans, then learn from execution evidence.
Five benchmark scripts exist and three are named in the quick start
The verification instructions are a short list of commands.
python -m unittest -v
python benchmark.py
python benchmark_dynamic.py
python benchmark_trust.py
The repository contains more benchmark machinery than that. Alongside those three there is a scaling benchmark, a static evaluator, a dynamic evaluator, and a separate evaluator module for the dynamic case, plus matching test files for the benchmark, the dynamic benchmark and the trust benchmark.
The one the quick start leaves out most conspicuously is the scaling benchmark, whose name matches the question a reader arrives with.
The design intent is stated elsewhere and explains the extra modules: the evaluator is deliberately separate, it replays checkpoints, and it scores artifact reuse, added cost, recovery latency, wasted work and final quality without calling the router's switching equation. Keeping the scorer outside the decision path is what stops the router grading its own homework.
So the unlisted scripts are infrastructure for that separation rather than extra demos.
No runtime dependencies, and a four-tool development extra
The install story is short because there is nothing to install at run time.
git clone https://github.com/wang2122/sprix-sage-router.git
cd sprix-sage-router
python demo.py
The page states that the reference implementation requires Python 3.10 or newer and has no runtime dependencies. The packaging configuration backs both halves: the interpreter floor is 3.10 and the only declared build requirement is a minimum version of the build backend.
Development tooling is declared as an optional extra with four entries: a build frontend, a type checker, a linter and a package upload tool, each with a minimum version.
The linter is configured with a line length of 110, a target version matching the interpreter floor, and a short rule selection limited to a few error classes, unused names and import ordering. The type checker is configured to run against a named file list that includes every shipped module, every benchmark and the examples directory, with implicit optionals disallowed.
That is a small, deliberate surface. Nothing here pulls in a machine learning framework.
Alpha status, three tested Python versions, four shipped modules
The packaging metadata is where the project's self-description is most precise.
name = "sprix-sage-router"
version = "0.3.0"
requires-python = ">=3.10"
license = "MIT"
Development status is declared as alpha, with the audience listed as both developers and research. The tested Python classifiers run 3.10, 3.11 and 3.12, so a 3.13 interpreter is outside the tested range even though the floor permits it.
Four modules are shipped, declared as flat modules rather than as a package.
py-modules = ["sprix_sage", "sprix_learning", "sprix_types", "sprix_a2a"]The split matches the page: the router, the learning component, the type definitions, and the protocol adapter. Benchmarks, tests and examples are in the tree but are not part of what gets installed.
Releases are v0.1.0 on 2026-08-18 and v0.3.0 on 2026-08-28, so the project went from first to third minor version in ten days, and the last push on the default branch is dated 2026-08-28.
Editorial conclusion
This project fits someone building multi-agent task execution who has an A2A endpoint or marketplace producing skill cards, bids and task state, and wants the choice of execution mode made in one auditable objective rather than in per-agent prompt logic. It does not fit anyone looking for a working A2A client, because the integration layer deliberately does not transmit tasks, authenticate endpoints or verify signatures, and that work stays with the client. Before you build on it, check four things. Whether you can accept an alpha-status package, since that is the declared development status. Which Python you have, since the floor is 3.10 and the tested classifiers stop at 3.12. That your benchmark story includes the baselines rather than the router alone, since the point of the evaluation is a separate scorer that does not call the router's own switching decision. And where your artifacts can actually be carried, because artifact portability is the term that decides whether a switch is worth its context loss.
Frequently asked questions
What does the Sprix SAGE Router decide?
It chooses one of three execution modes for a task that is already under way: self, where the incumbent agent keeps ownership, collaborate, where the incumbent keeps ownership and a small team covers missing requirements, and handoff, where a peer takes full ownership. The choice weighs permissions, budget, deadline, completed work, observed quality and artifact portability.
What can the Sprix SAGE Router not do yet?
The prototype intentionally does not transmit tasks, authenticate endpoints or verify signatures, and an A2A client remains responsible for message sending, streaming, polling, cancellation and secure artifact handling. It converts the selected route into a transport-neutral execution plan and stops there.
How do I run the Sprix SAGE Router demo and its checks?
Clone the repository, enter the directory and run the demo script. It requires Python 3.10 or newer and has no runtime dependencies. The verification suite is the standard library test runner plus three benchmark scripts named in the quick start, although the repository also holds a scaling benchmark and separate evaluator modules.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wang2122-sprix-sage-router)Star history chart for your README
[](https://hysenlabs.com/projects/wang2122-sprix-sage-router)Was this useful?