wechat-bot: allowlist-gated replies on a protocol the author calls risky
🤖 Multi-platform IM AI Agent for Telegram, WhatsApp, Lark, and WeChat. Connects ChatGPT / Claude / Kimi / DeepSeek / Ollama / Pi for auto-replies, community analysis, contact management, and inactive-friend detection.
At a glance
- What is it?
- wechat-bot routes WeChat, Lark, Telegram and WhatsApp messages into an AI agent, but its real design is in the small print: two allowlists decide who gets an answer, every captured message lands in a local JSONL file, and the default WeChat protocol is described as a standing risk of warnings or bans. The command surface is broad; the guardrails are narrow and explicit.
- Who is it for?
- Use wechat-bot if you genuinely want an always-on assistant on a messaging account and can accept the account risk the project states plainly, and if you are willing to read the protocol section before the first login rather than after. Do not use it on an account you cannot afford to lose, and do not expect it to read images or reply in groups without being mentioned.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 72 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
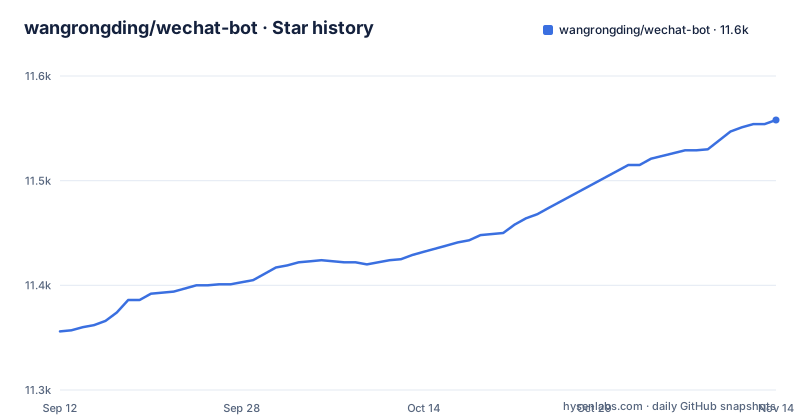
- wangrongding/wechat-bot11,558 ★ · +202
| Repository | 2026-09-12 | 2026-11-14 |
|---|---|---|
| wangrongding/wechat-bot | 11.4k | 11.6k |
202 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two allowlists and one mention decide who the bot answers
The reply logic is not a model choice, it is a membership test, and it is configured before any provider key matters.
BOT_NAME='@Your WeChat nickname'
ALIAS_WHITELIST='Friend alias allowed for private chat'
ROOM_WHITELIST='Group name allowed for access'

PI_BIN='pi'
PI_AGENT_ARGS='--print --no-session'
WECHAT_STORE_MESSAGES='true'
A private chat is answered only when the sender alias or nickname appears in ALIAS_WHITELIST. A group needs the group name in ROOM_WHITELIST and the message must mention the bot by its nickname. Non-text messages are not automatically sent to the reply pipeline. The consequence is concrete: a group member typing to the room gets silence unless they type the mention, and an image or voice note is not automatically passed to a model.
The pipeline writes every captured message to a local JSONL file
Once started, the process runs a five stage path, and the third stage is the one that persists.
WeChat QR-code login -> Wechaty receives message -> local JSONL capture -> Pi agent reply -> WeChat IM sends replyThe capture is switched on by WECHAT_STORE_MESSAGES set to true in the same env block as the allowlists, so it is on by default in the documented setup. The consequence is that this is a transcript store as much as a bot: every accepted message accumulates on the machine that runs the agent. If you point the agent at a busy group, you have created an archive.
The default WeChat protocol is described as a ban risk three times over
The repository is unusually blunt about this. A note beside the quick start says WeChat web protocols carry account risk including warnings or bans, tells you to use the project only with accounts and scenarios where you explicitly accept the risk, and advises keeping allowlists and usage scope narrow. A separate warning section says WeChat has recently become very strict about this type of usage and that the default protocol can trigger warnings or bans. It also names the root cause: the author of the padlocal protocol is no longer maintaining it.
The consequence is that the out-of-box path is the one carrying the risk, and the fix is left to you, expressed as switching to a more stable protocol yourself if needed.
Local chat history comes from a separate CLI, not from Wechaty
Two capabilities sit outside the message pipeline entirely. Reading local WeChat chats, contacts, group members and the Moments cache goes through a separate tool, OpenCLI with its wx-cli command, exposed as `wb wx sessions`, `wb wx history`, `wb wx members`, `wb wx sns-feed` and `wb wx sns-search`. Analysis then runs on top of that, with `wb analyze --room "Group name"` and `wb analyze --friend "Friend alias"` covering local statistics and AI deep analysis.
The consequence is a second dependency in the chain, and one the project is candid about: if you only use the wx commands to reach local data, or only use the Lark commands, you do not need to configure an LLM at all. But the moment you ask for deep analysis, you are back to needing a provider, so the no-key path covers retrieval and statistics only.
The npm scripts are the real interface, and they have drifted from the release list
Everything runs through one file, cli.js, and the package manifest exposes a script per transport.
  "scripts": {
    "dev": "node ./cli.js",
    "format": "prettier --write ./src",
    "start": "node ./cli.js",
    "test": "node ./src/wechaty/testMessage.js",
    "test:analysis": "node ./src/analysis/__test__.js",
    "lark:login": "node ./cli.js lark login",
    "lark:agent": "node ./cli.js lark agent --agent pi",
    "telegram:agent": "node ./cli.js telegram agent --agent pi",
    "whatsapp:agent": "node ./cli.js whatsapp agent --agent pi",
    "wechat:analyze": "node ./cli.js analyze --stats-only",
    "agent": "node ./cli.js agent --im wechat --agent pi",
    "opencli": "node ./cli.js opencli",
    "wx": "node ./cli.js wx",
    "pi": "node ./cli.js pi",
    "test-openai": "node ./src/openai/__test__.js",
    "test-xunfei": "node ./src/xunfei/__test__.js",
    "test-kimi": "node ./src/kimi/__test__.js",
    "test-dify": "node ./src/dify/__test__.js",
    "prepare": "npx husky"
  },
The binary is registered twice, as wb and as wechat-bot, both pointing at cli.js. Note the version drift: the manifest reads 1.0.2 while the newest published release is 0.0.2 from 2024-03-26, so the version you see in package.json is not a release you can install.
The Docker image installs Chromium, ffmpeg and sudo to start one Node process
The image picks its package mirror at build time with a build argument, and the default is the public npm registry.
ARG APT_SOURCE="default"

FROM node:19 as builder-default
ENV NPM_REGISTRY="https://registry.npmjs.org"

FROM node:19 as builder-aliyun

ENV NPM_REGISTRY="https://registry.npmmirror.com"
RUN sed -i s/deb.debian.org/mirrors.aliyun.com/g /etc/apt/sources.list \
    && ln -sf /usr/share/zoneinfo/Asia/Shanghai /etc/localtime && echo 'Asia/Shanghai' >/etc/timezone
The resulting stage installs a long apt list including chromium, ffmpeg, jq, shellcheck, sudo, vim and wget, then sets CHROME_BIN to the system chromium and skips the Puppeteer download. The consequence is a heavy image for a process whose only command is npm run dev, built on node:19, with no non-root user created anywhere in the file.
Twelve reply backends, twelve different key names, and one test script each
The service list covers ChatGPT, doubao, deepseek, Kimi, Xunfei, deepseek-free, 302AI, dify, ollama, tongyi, claude and pi, and each expects its own variables; package.json has test scripts for only some of them (openai, xunfei, kimi and dify). The Tongyi block is representative, with a URL that includes the URI path and a model set to qwen-plus:
# Copy .env.example to .env
cp .env.example .env
# Fill in .env
# Tongyi URL, including the URI path
TONGYI_URL = "https://dashscope.aliyuncs.com/compatible-mode/v1"
# Tongyi API key
TONGYI_API_KEY = ''
# Tongyi model
TONGYI_MODEL='qwen-plus'
The two lists do not fully agree. The DeepSeek section names DEEPSEEK_FREE_TOKEN while the example environment file names DEEPSEEK_API_KEY, DEEPSEEK_URL and DEEPSEEK_MODEL, with a comment that the official DeepSeek API has stopped and SiliconFlow can be used instead. Xunfei needs three separate values, which the README warns are easy to mix up, with two issue numbers attached for service errors, and Kimi is described as integrated at a basic level.
Editorial conclusion
Use wechat-bot if you genuinely want an always-on assistant on a messaging account and can accept the account risk the project states plainly, and if you are willing to read the protocol section before the first login rather than after. Do not use it on an account you cannot afford to lose, and do not expect it to read images or reply in groups without being mentioned. Before you start, check which WeChat protocol your build is on, since the default one is called out as unmaintained upstream, and confirm that the keys named in the README match the ones in your .env file, because the two do not fully agree.
Frequently asked questions
How can I create my bot?
Install and link the CLI with npm i, cp .env.example .env and npm link, set at least BOT_NAME, ALIAS_WHITELIST, ROOM_WHITELIST, PI_BIN, PI_AGENT_ARGS and WECHAT_STORE_MESSAGES, then run wb agent --im wechat --agent pi and scan the QR code it prints.
Is WeChat blocked in the USA?
The project's stated platform risk is that WeChat web protocols can trigger warnings or bans, and it advises keeping allowlists and usage scope narrow.
Can US citizens use WeChat?
The project describes the transport layer: WeChat QR-code login through Wechaty, Lark IM events, Telegram Bot API long polling, and WhatsApp Cloud API webhooks.
Do non-Chinese people use WeChat?
The project's account mechanics are: QR-code login, allowlists keyed on nickname or group name, and a JSONL capture of accepted messages.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wangrongding-wechat-bot)Star history chart for your README
[](https://hysenlabs.com/projects/wangrongding-wechat-bot)Was this useful?