Exportify exports playlists as CSV and admits search is a local filter
Export/Backup Spotify playlists using the Web API
At a glance
- What is it?
- Exportify is a browser application that turns Spotify playlists into CSV files through the Web API, with no server and no stored data. The engineering it actually needed was not CSV generation but pacing: a rate limiting library sits in the dependency list, the search box cannot search until every playlist in the account has been fetched, and the README notes that the more data is exported, the longer the export takes.
- Who is it for?
- Exportify fits someone who wants their Spotify library in a spreadsheet they own, and who is willing to grant a third party read-only access to their playlists and library to get it. It does not fit anyone who needs audio files, since the export carries preview URLs rather than tracks, and it does not fit an account large enough that fetching every playlist first becomes a problem.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 26 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
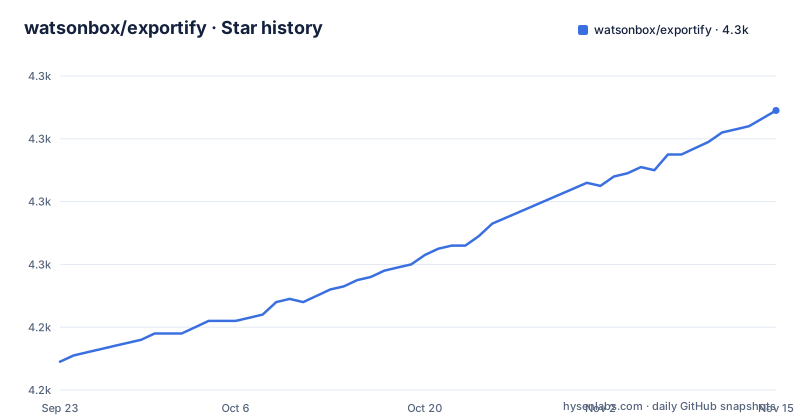
- watsonbox/exportify4,309 ★ · +80
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| watsonbox/exportify | 4.2k | 4.3k |
80 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Read-only access, in the browser, with nothing saved
The pitch is in two sentences. There is no way to export, archive or back up playlists from the Spotify client for safekeeping, which many users have pointed out, and this application does that job using the Spotify Web API.
Underneath that, the page makes one claim about privacy that shapes everything else: no data will be saved, and the entire application runs in the browser.
That is why the permission requested is narrow. The usage steps are four: open the app, click get started, grant read-only access to your playlists and library, then click export. There is no step where you create an account with this service, because there is no service side to hold an account.
The output is a file you keep. One playlist gives you one CSV, and export all gives you a zip with a CSV for each playlist in the account, with the page warning that this may take a while when many playlists exist or they are large. That file is the backup, and it lives on your disk rather than anywhere the project controls.
Rate limiting is a dependency, not a retry loop
The feature list has one engineering entry among the user-facing ones: advanced rate limiting handling for speedy exports, linked to a pull request.
The dependency list confirms the shape of the solution. There is a rate limiting library in the manifest, alongside the HTTP client and the zip library, and rate limiting is not something a CSV exporter needs for its own sake. It needs it because every field it exports comes from an API that meters requests.
So the app's real constraint is politeness towards someone else's API. A feature that looks like a one-click download is really a scheduling problem, and the speed of an export is capped by how fast the app is willing to ask.
Search cannot search, so it fetches everything first
The playlist search facility carries a warning that explains the whole design of that feature. If you have a very large number of playlists there may be a small delay before the first results appear, because the Spotify API itself does not allow searching directly, so all playlists have to be retrieved first.
That single sentence turns the search box into a client-side filter over a complete account fetch. It is honest about the consequence, which is unusual: rather than hiding the delay, the page names the cause.
Searching is case-insensitive, and results can be exported as their own zip file, which means a filtered subset can be exported without touching the rest of the account.
On top of the free text search there is a small query language, given as a table: public true or false to filter by visibility, collaborative true or false to do the same for collaborative playlists, and an owner token with two forms, one meaning playlists you own and one taking an owner name. These are the only queries with special meaning, and they operate on data already in the browser.
Optional columns are a cost dial, and the default set has nineteen fields
The default export is a UTF-8 encoded CSV built from the Spotify track object, and it carries nineteen fields: track URI and name, artist URIs and names, album URI and name, album artist URIs and names, album release date, album image URL at what is typically a 640 by 640 jpeg, disc number, track number, duration in milliseconds, a preview URL for an mp3, whether the track is explicit, its popularity, its ISRC, who added it and when.
Three switches behind a cog add more.
Artist data adds genres. Album data adds album genres, label and copyright lines. Audio features data adds twelve values: danceability, energy, key, loudness, mode, speechiness, acousticness, instrumentalness, liveness, valence, tempo and time signature.
The page states the trade-off directly: the more data being exported, the longer the export will take. That is the whole reason those columns are optional rather than default, and it means the export format is a dial between a fast nineteen-field file and a slow one carrying per-track audio analysis.
Folders are not in the API, so the model stays flat
Re-importing is a manual operation: open the CSV in a spreadsheet, select and copy the track URI column, then create a playlist in Spotify and paste them in. The page notes this has only been tested with the desktop app.
So the round trip is file, spreadsheet, clipboard, client. Nothing is uploaded back, nothing is created through the API, and the track URI is the only piece of the original data that survives the journey.
Ten languages, a zip library, and two shims for older browsers
The stack section names the usual pieces for a browser application: React, Bootstrap 5, Font Awesome, an internationalisation framework, a testing library for DOM nodes, and a network mocking tool for tests. The stack now uses Vite with Vitest, and the manifest's scripts are start, build, preview, test and lint.
The dependency list is more revealing than the stack section. Alongside React and Bootstrap there is an error reporting client with its React plugin, the zip library that builds the multi-playlist archive, the language detector that pairs with the internationalisation framework, and a file saver for the download.
The README lists the interface as available in 15 languages, including Arabic.
The container serves the development server, and the release is named after a month
The Dockerfile is a two-stage build. The first stage starts from node:22-alpine, enables corepack, installs dependencies with pnpm from the lockfile, copies the source and runs pnpm build; the second stage starts from nginx:alpine, copies in nginx.conf and the built dist folder, and exposes port 80.
So the container serves the production build through nginx rather than running the development server.
The versioning tells a similar story. There is exactly one GitHub release, named after a month of 2024 rather than a version number, and the manifest says version 0.1.0 with the package marked private, which means that number is a placeholder rather than something anybody can install.
The history section is the better record: born in 2015, a major release in 2020 that added search, artist and audio features, liked songs export and the new rate limiting system, and another in 2024 that added dark mode, internationalisation and search enhancements. The last push on the default branch is dated 2026-10-20.
Editorial conclusion
Exportify fits someone who wants their Spotify library in a spreadsheet they own, and who is willing to grant a third party read-only access to their playlists and library to get it. It does not fit anyone who needs audio files, since the export carries preview URLs rather than tracks, and it does not fit an account large enough that fetching every playlist first becomes a problem. Before using it, check four things. Whether read-only access to your playlists and library is acceptable to you, since that is the only permission the app asks for and the app runs in the browser rather than on a server. How many playlists you have, because the search facility cannot query the API and must retrieve everything before the first result appears. Which optional columns you actually need, because the page is explicit that more exported data means a longer export. And whether the CSV will still be useful in a year, since there is one release, named after a month rather than a version, and a manifest version of 0.1.0 in a package marked private, so there is nothing to pin and no compatibility promise to track.
Frequently asked questions
What is Exportify?
A web application that exports your Spotify playlists to CSV files using the Spotify Web API. It runs entirely in the browser, asks only for read-only access to your playlists and library, and the page states that no data is saved.
How do I use Exportify?
Four steps: open the app, click get started, grant read-only access to your playlists and library, then click export for a single playlist or export all for a zip containing one CSV per playlist. Re-importing is manual: copy the track URI column from the CSV and paste it into a new playlist in Spotify, which has only been tested with the desktop app.
Is Exportify safe?
The page states that the whole application runs in the browser and that no data is saved, and the only access requested is read-only access to your playlists and library. The source is public and MIT licensed.
Can I turn Spotify songs into MP3?
No. The CSV carries a track preview URL field, which is the mp3 preview the Spotify API returns, and the tool copies that address into the file. It does not download or convert track audio.
How do I get a Spotify CSV file?
Export a playlist from the app and you get a UTF-8 CSV with nineteen fields taken from the Spotify track object, or export all playlists for a zip of one CSV each. Switches add artist genres, twelve audio feature values, and album genres, label and copyright lines, and the page notes that more exported data makes the export slower.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/watsonbox-exportify)Star history chart for your README
[](https://hysenlabs.com/projects/watsonbox-exportify)Was this useful?