SAITS ships the paper, a PDF at the root, and its own successor toolbox
The official PyTorch implementation of the paper "SAITS: Self-Attention-based Imputation for Time Series". A fast and state-of-the-art (SOTA) deep-learning neural network model for efficient time-series imputation (impute multivariate incomplete time series containing NaN missing data/values with machine learning). https://arxiv.org/abs/2202.08516
At a glance
- What is it?
- WenjieDu/SAITS is the official PyTorch implementation of a self-attention model for filling gaps in multivariate time series, kept alongside a survey, a benchmark and a separate toolbox that now contains the model itself. The performance claims are precise ranges against named baselines, and the repository root holds a paper PDF, an example script and a tuning directory.
- Who is it for?
- Read this as the reference implementation of a specific published model rather than as a maintained library. It has no releases, the last commit is from late August, and the same author now points new users at a separate toolbox where SAITS is one model among many.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 83 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
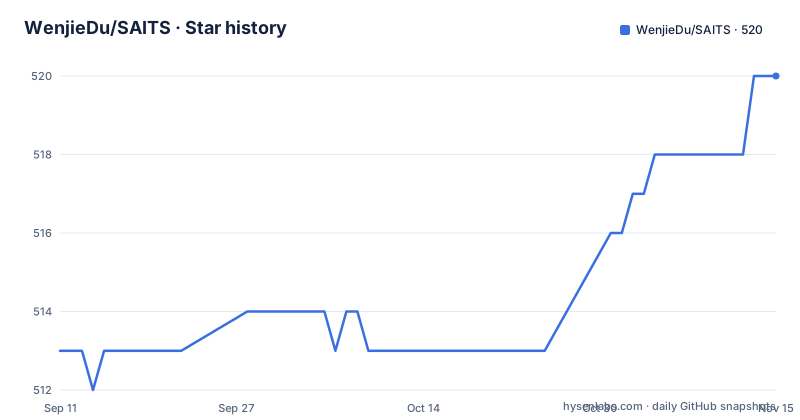
- WenjieDu/SAITS520 ★ · +7
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| WenjieDu/SAITS | 513 | 520 |
7 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two accuracy claims and four named baselines
The performance section is more specific than most readmes of this kind, which makes it more useful and also more checkable.
Against a recurrent baseline, the model reports a 12 to 38 percent improvement in mean absolute error and two to two and a half times faster training. Against a Transformer trained with the same joint-optimisation approach, it reports 2 to 19 percent lower error while needing only 15 to 30 percent of the parameters. Against another self-attention imputation model, it reports 7 to 39 percent lower mean squared error, with the note that the gap exceeds twenty percent in nine of sixteen cases. Every comparison names its baseline and links to it, which is better practice than the anonymous improvement claims most readmes make.
The motivation sits alongside the numbers: the model targets the slowness, memory cost and compounding error of recurrent imputation models, which is the same claim the survey and benchmark in the surrounding notes were built to test.
What the ranges share is a shape rather than a point. Every figure is an interval, none is a single number, and the comparisons use two different error metrics. So the correct reading is that the model is reliably in the same class as the alternatives and better on some cases, not that it is uniformly ahead.
No dataset, no seed, no evaluation script
The gap in the performance section is reproducibility, and it is a real one.
No dataset is named, no train and validation split is described, no seed count appears, and no evaluation script is referenced anywhere in the visible documentation. The section closes by pointing at the full paper for details, which is the right place for them, but it means a reader cannot reproduce a single number from the repository alone.
This matters more than it would for a smaller project, because the author is also the author of the benchmark that covers this model. A benchmark spanning close to thirty-five thousand experiments across twenty-eight methods exists, and it uses eight real-world datasets and three missing patterns of points, sequences and blocks. So the machinery for producing better numbers is public, just not wired into this repository's documentation.
The practical advice is therefore narrow: if you need to cite a figure, cite the paper's, and if you need to trust a figure, run the benchmark. The readme's own framing points the same way, since it describes the code as a framework you are expected to adjust rather than a configuration you can trust out of the box.
The author now points new users at a toolbox that already contains it
The most consequential line in the readme is an attention notice, and it changes what this repository is for.
The model is stated to be available inside a separate Python toolbox for partially-observed time series, with a worked example of training it on a hospital dataset where the ecosystem libraries download and extract the data automatically. The closing line of that section describes the toolbox as the place to go, in language that leaves little doubt.
Above that sit three dated updates explaining the trajectory. A survey on deep learning for multivariate time-series imputation was accepted at a 2025 conference, reviewing the field with a taxonomy organised by uncertainty and model architecture, comparing several toolkits and discussing open problems. A benchmark paper from mid-2024 is presented as the first comprehensive one, with its code in a separate repository. And a mid-2024 note records that the SAITS embedding and training strategies were applied to more than twenty other architectures inside that toolbox.
So a single research codebase grew into a survey, a benchmark and a toolbox, and this repository is the historical reference implementation underneath all three. That is a healthy outcome for the field and a real complication for anyone arriving here expecting maintained code with a version number.
No releases, and a paper PDF committed at the repository root
The release history is empty and there are no tags to install from, so the only way to use this code is to clone it.
The top-level listing shows what a research code release looks like in practice. There is a paper PDF sitting at the root next to the readme, which means the published version of the method is versioned alongside the code that implements it. That is unusual and mostly a good thing, since it guarantees the paper and the implementation travel in the same commit, and it also means the repository permanently carries a binary artefact that will never change while the code around it does.
Then there is a global configuration module with a capitalised file name, sitting at the root rather than inside a package, an example script whose name says it runs a recurrent model on data that has already been imputed, a directory for hyperparameter tuning with a specific framework, a configs directory, a directory of scripts for generating datasets, a directory of figures, a modelling directory, a run script, a citation metadata file and an environment dependency file.
The layout is a research artifact rather than a library. There is no package directory, and configuration is split between a root module and a configs directory. Anyone expecting an installable package will not find one here, which is consistent with the readme steering new users elsewhere.
The claims date from 2022 and the field has moved past them
The model is described as the first work applying pure self-attention with no recursive design to general time-series imputation. The preprint dates from early 2022 and the journal version came later.
The alternatives list is where the ageing shows. The 2022 benchmark covered twenty-eight methods, and the material attached to this repository now also names a diffusion model for probabilistic imputation, a low-rankness Transformer for spatiotemporal imputation, and the recurrent baseline the original paper beat. So the field the model competed in has widened considerably, and a 2022 comparison set is no longer the state of the art for anyone choosing a method today.
The readme's own framing is the honest part. The author calls it a validated framework for imputation rather than the winning approach, notes that specific scenarios will probably need the model structure or the loss functions adjusted, and frames the contribution as a reusable design that has been integrated into more than twenty other architectures. That is what a good foundational implementation looks like after four years: not the answer, but the thing other answers were built from.
The readme also spends three sentences establishing the prestige of the receiving journal, quoting an impact figure and two rankings. For a reader weighing accuracy, venue ranking is not evidence, and the survey and benchmark links are the more useful things on that page.
A license that asks for a citation and a star
The licensing terms are the most permissive part of the page, and they are stated with unusual clarity about what you may do.
The code is MIT licensed, and the readme says explicitly that you are welcome to modify it for your own research purpose and domain applications. It also says plainly that it will probably need modification to the model structure or the loss functions for a specific scenario or data input. That is a candid statement of what a research implementation is: a starting point, not a finished component.
Alongside the permission come two requests. One is to cite the work in publications where it helped, with a citation section linked from the readme and a citation metadata file at the repository root, so the requested format is machine-readable rather than a paragraph to retype. The other is to star the repository, justified by saying what it means to open-source research.
Neither request constrains what you build. Both are worth honouring, and the second is the kind of ask that is easier to satisfy than to design around.
One example, and it is written for the other library
There is exactly one worked example in the readme, and it does not use this repository's code.
It imports a preprocessing helper from an ecosystem library, loads a hospital dataset through another, prints the shapes of the training, validation and test tensors, and comments on the difference between them: the sample counts differ between the training and validation sets, but the sequence length and feature dimension are shared. The set is preprocessed at a chosen missing rate, and the comment notes that the download and extraction happen automatically.
So the example teaches you three things and none of them are about SAITS's own API. It teaches you where the data comes from, how a missing rate is applied at preprocessing time rather than at training time, and what a correctly shaped dataset looks like. It does not show how to build the model, train it or impute with it, which is the thing a reader arriving from a search for an implementation would most want.
That is a coherent choice if the toolbox is the supported path, and the surrounding notes make it clear that it is. It is also the difference between a repository that is a research artifact and one that is a library, and this one is the former.
Editorial conclusion
Read this as the reference implementation of a specific published model rather than as a maintained library. It has no releases, the last commit is from late August, and the same author now points new users at a separate toolbox where SAITS is one model among many. If you want to reproduce the paper, this repository is the right place. If you want to impute data in production, weigh the toolbox instead, since it carries the SAITS training strategy across more than twenty other architectures and shares a maintained ecosystem of loaders and utilities. Before you rely on any of the accuracy numbers, read them as the paper's reported ranges rather than as a benchmark you can reproduce from the readme, because no dataset list, seed count or evaluation script is described there.
Frequently asked questions
What is SAITS?
A self-attention model for imputing missing values in multivariate time series, described as the first work to apply pure self-attention with no recursive design to general time-series imputation. It uses a joint-optimisation training approach and is published in Expert Systems with Applications, with a preprint on arXiv from early 2022.
How does SAITS compare with recurrent and Transformer baselines?
Against the recurrent baseline it reports 12 to 38 percent lower mean absolute error and two to two and a half times faster training. Against a Transformer trained with the same joint-optimisation approach it reports 2 to 19 percent lower error while needing 15 to 30 percent of the parameters, and against another self-attention imputation model 7 to 39 percent lower mean squared error.
How do I install SAITS from this repository?
You cannot install it, because the repository has no releases and no tags. It is a research code release: the top level holds a global configuration module, a run script, configs, a modelling directory, dataset-generating scripts and a hyperparameter tuning directory, with no package directory or installable manifest.
What license is SAITS released under?
MIT, with a license file at the repository root and the readme explicitly inviting modification for your own research and domain applications, while noting that specific scenarios will probably need the model structure or loss functions adjusted. It also asks that the work be cited where it helped and that the repository be starred.
Where can I find a survey or benchmark for time-series imputation?
Both are from the same author and linked from the readme. A 2025 survey proposes a taxonomy organised by uncertainty and model architecture and compares several toolkits, and a 2024 benchmark covers close to thirty-five thousand experiments across twenty-eight methods, three missing patterns and eight real-world datasets, with its code in a separate repository.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wenjiedu-saits)Star history chart for your README
[](https://hysenlabs.com/projects/wenjiedu-saits)Was this useful?