Noise Suppression for Voice: a speech-gated RNNoise filter in six plugin formats
Noise suppression plugin based on Xiph's RNNoise
At a glance
- What is it?
- werman's plugin wraps Xiph's RNNoise as VST2, VST3, LV2, LADSPA, AU and AUv3. It gates on a voice activity detector, so the tuning you care about is one threshold and two grace periods, and one of them costs latency.
- Who is it for?
- Adopt it when you want one speech-gated filter whose threshold and grace periods you can see, and you are willing to hold your audio source at 48000 Hz. Walk away when the capture chain is weak or when a fixed configuration would do.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 21 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
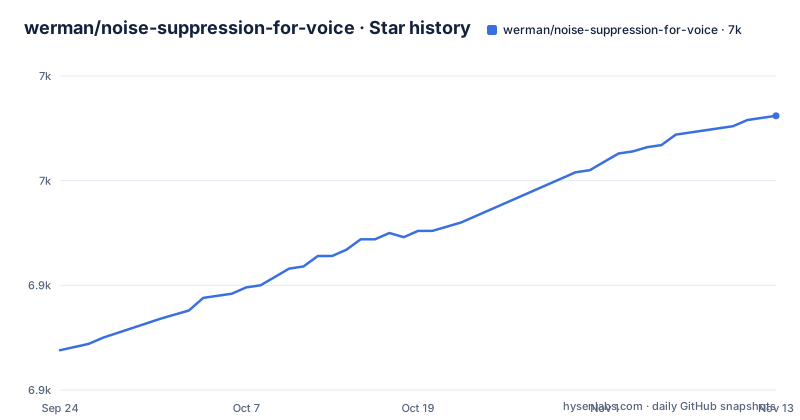
- werman/noise-suppression-for-voice6,981 ★ · +112
| Repository | 2026-09-24 | 2026-11-13 |
|---|---|---|
| werman/noise-suppression-for-voice | 6.9k | 7k |
112 Stars in the last 50 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One RNNoise model behind six plugin formats
The same filter ships in six plugin formats: VST2, VST3, LV2, LADSPA, AU and AUv3. Every release name repeats that list, so the host application picks the packaging rather than the user picking it. The repository is C++ under GPL-3.0 on the master branch, and the tree is small: CMakeLists.txt, src/, external/, toolchains/ and a .gitmodules file, with no package manifest for any system package manager. The noise classes it aims at are the ones named in the RNNoise paper the project points at: computer fans, office, crowd, airplane, car, train and construction. The last push was on 2026-10-25, the same day release v1.22 was published, following v1.21 on 2026-05-29 and v1.10 in 2024.
48000 Hz is a requirement, not a suggestion
Input is one or more channels, 16 bit, 48000 Hz, and the instruction about the rate is unusually blunt: use only 48000 Hz, make sure the audio source already is 48000 Hz, and force it if it is not. On Windows the path runs through the recording dialog, from Recording devices to Recording, then Properties of the target mic, then Advanced, which is where the rate gets checked or changed. On Linux the documentation does not close the loop. Under the PipeWire heading the troubleshooting list holds a single open entry, a TODO asking how to change the sample rate for the mic, and the how-to stops there. Anyone on PipeWire with a 44100 Hz source has to solve that outside this page.
VAD Threshold (%) decides what counts as voice
Three parameters do the real work. VAD Threshold (%) is the gate: when the probability that a sound is a voice falls below the threshold, the output is silenced. The guidance is that a value between 85% and 95% suits most cases, and that without the VAD some loud noises stay audible during silence. That explains what the filter is actually good at. The maintainer reports that mild background noise is always suppressed, and that loud sounds such as the clicking of a mechanical keyboard are suppressed while there is no voice but only reduced in volume when voice is present. It is a suppressor keyed to speech presence, not a general noise remover. The PipeWire example in the same document ships VAD Threshold (%) at 50.0, well below the range the prose recommends.
The retroactive grace period trades latency for word starts
VAD Grace Period (ms) covers the other half of the problem. It holds the output open for a while after the last voice detection, which stops the ends of words and sentences from being clipped. Retroactive VAD Grace Period (ms) does the mirror image for the starts of words and sentences, and it carries a warning: it introduces latency. That is the trade the two settings make. One keeps word endings, the other keeps word beginnings, and only one of them is free. Since v1.0 there is a GUI, described as minimalistic, holding all parameters and diagnostic stats, so the threshold and both grace periods can be moved without opening a text editor.
PipeWire 0.3.45 moved plugin config into a conf.d file
On PipeWire 0.3.45 and newer the plugin is a drop-in file. Create ~/.config/pipewire/pipewire.conf.d/, add a file named 99-input-denoising.conf, and paste a filter chain built on libpipewire-module-filter-chain with a ladspa node named rnnoise. The part that needs editing is the plugin path:
context.modules = [
{   name = libpipewire-module-filter-chain
    args = {
        node.description =  "Noise Canceling source"
        media.name =  "Noise Canceling source"
        filter.graph = {
            nodes = [
                {
                    type = ladspa
                    name = rnnoise
                    plugin = /path/to/librnnoise_ladspa.so
                    label = noise_suppressor_mono
Point that path at the real librnnoise_ladspa.so, keep label as noise_suppressor_mono, restart the service and pick Noise Canceling source as the input device:
systemctl restart --user pipewire.serviceBefore 0.3.45 there is no split-file configuration: copy /usr/share/pipewire/pipewire.conf into ~/.config/pipewire/pipewire.conf and append the same block to the context.modules list already in that file. One detail deserves attention. Switching label to noise_suppressor_stereo doubles the resource use, which the maintainer says you probably do not need even when the microphone reports itself as stereo.
PulseAudio wants a null sink, a LADSPA sink, then a loopback
PulseAudio is the awkward path, and the project's own summary of it is a one line instruction to use PipeWire instead. The chain needs three modules in a fixed order: a null sink that applications will read from later, a LADSPA sink that writes into that null sink while exposing its own input, and a loopback from the microphone into the plugin's input. Start by naming the source:
pactl list sources shortThen load the three modules, with your microphone name substituted in:
pacmd load-module module-null-sink sink_name=mic_denoised_out rate=48000
pacmd load-module module-ladspa-sink sink_name=mic_raw_in sink_master=mic_denoised_out label=noise_suppressor_mono plugin=/path/to/librnnoise_ladspa.so control=50,20,0,0,0
pacmd load-module module-loopback source=<your_mic_name> sink=mic_raw_in channels=1 source_dont_move=true sink_dont_move=true
Those three commands have to be repeated at every PulseAudio start, so the documented fix is a file at ~/.config/pulse/default.pa:
.include /etc/pulse/default.pa

load-module module-null-sink sink_name=mic_denoised_out rate=48000
load-module module-ladspa-sink sink_name=mic_raw_in sink_master=mic_denoised_out label=noise_suppressor_mono plugin=/path/to/librnnoise_ladspa.so control=50,200,0,0,0
load-module module-loopback source=your_mic_name sink=mic_raw_in channels=1 source_dont_move=true sink_dont_move=true

set-default-source mic_denoised_out.monitor
The two examples do not match. The second positional value in the control list is 20 in the command line version and 200 in the file version.
A bad microphone can make the recording worse
A poor microphone is the case this plugin cannot repair, and the project says so plainly. It cannot improve voice quality when the microphone itself is weak, and it can make a recording worse, because the classifier may decide that voice is noise and remove it, taking already thin audio along. That failure mode follows directly from the VAD design. A threshold aggressive enough to erase a loud office will also erase a quiet speaker, and the damage is invisible in the output, which simply goes quiet. Fix the capture chain first, then decide how much of what is left to hand to the filter. Licence is the other boundary: the repository is GPL-3.0, so a binary you build from it and pass to other people carries that licence's obligations with them, which is a compliance question for whoever ships the build.
EasyEffects and NoiseTorch hide the layer this one exposes
Two alternatives appear in the project's own PipeWire notes, and both are built on RNNoise as well. EasyEffects is a general audio effects GUI for PipeWire: easy to set up and use, distributed on Flathub, and described as offering fewer settings for denoising. NoiseTorch is the other one, also easy to set up, working with both PulseAudio and PipeWire, again with fewer denoising settings. The difference is not the model. It is the control surface. This plugin exposes VAD Threshold (%), VAD Grace Period (ms), Retroactive VAD Grace Period (ms) and diagnostic stats behind a minimalistic GUI. Someone who wants a quiet input with as little configuration as possible will finish faster in EasyEffects or NoiseTorch.
Editorial conclusion
Adopt it when you want one speech-gated filter whose threshold and grace periods you can see, and you are willing to hold your audio source at 48000 Hz. Walk away when the capture chain is weak or when a fixed configuration would do. Before committing, feed it one minute of your own audio at 48 kHz, raise VAD Threshold (%) until it starts biting into quiet words, then check whether your machine can afford the doubled resource use of noise_suppressor_stereo.
Frequently asked questions
How do you install noise suppression for voice on Linux?
On PipeWire 0.3.45 or newer, create ~/.config/pipewire/pipewire.conf.d/99-input-denoising.conf holding a libpipewire-module-filter-chain block that points at librnnoise_ladspa.so, run systemctl restart --user pipewire.service, then select Noise Canceling source as the input device. On older PipeWire the same block has to be appended to ~/.config/pipewire/pipewire.conf, inside the context.modules list that is already there.
What sample rate and bit depth does the plugin accept?
48000 Hz and 16 bit, with one or more channels. The documentation tells you to force the audio source to 48000 Hz when it is not, and on Windows the rate is changed through Recording devices, then Properties of the target mic, then Advanced. The Linux troubleshooting section is still a TODO.
Does the Retroactive VAD Grace Period add latency?
Yes. It holds the gate open before a voice detection is treated as real, which keeps the starts of words and sentences intact, and the documentation flags the latency directly. The plain VAD Grace Period (ms) covers the ends of words instead and carries no such warning.
Can noise suppression for voice fix a bad microphone?
No. The project states that the plugin cannot improve voice quality from a bad microphone, and that it can even make things worse when the classifier misreads voice as noise and removes it, reducing audio that was already thin.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/werman-noise-suppression-for-voice)Star history chart for your README
[](https://hysenlabs.com/projects/werman-noise-suppression-for-voice)Was this useful?