OpenBiliClaw: classified Pre-Alpha while shipping three tags an hour
Local-first, open-source, self-evolving cross-platform AI content discovery agent: understands you, then proactively finds content across Bilibili, Xiaohongshu, Douyin, YouTube, X, Zhihu, Reddit, Weibo and the open web (supports a DeepSeek harness plugin).
At a glance
- What is it?
- OpenBiliClaw is a local-first content discovery agent that profiles you and then searches a dozen platforms for things you have never consumed. Its packaging tells an odd story: the manifest declares the project Pre-Alpha while three release tags for backend, browser extension and desktop app are published minutes apart, the quick start asks you to paste a prompt into a coding agent, and a 1.1GB embedding model is baked into a container image so it never needs the network.
- Who is it for?
- OpenBiliClaw suits someone who wants a recommendation surface that is not owned by a platform, is willing to log into their own accounts through a browser extension, and wants the resulting profile to stay on their own disk. It does not suit someone who needs a stable interface, because the project classifies itself as Pre-Alpha and its release identifiers are build counters rather than versions.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
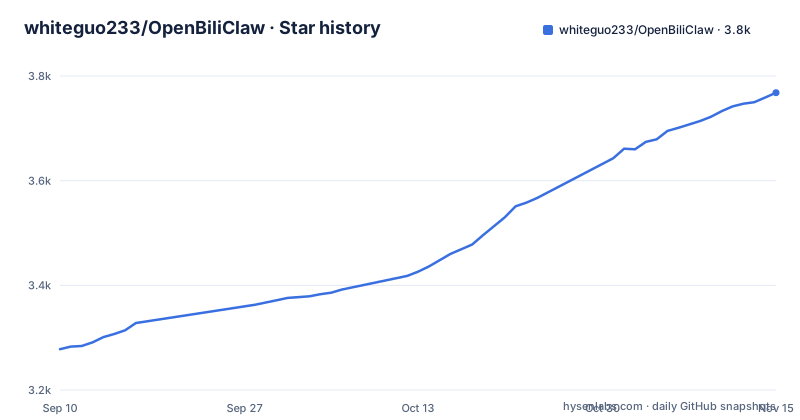
Star history
- whiteguo233/OpenBiliClaw3,768 ★ · +490
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| whiteguo233/OpenBiliClaw | 3.3k | 3.8k |
490 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The manifest says Pre-Alpha and the release tags say otherwise
The packaging metadata classifies the project as Development Status 2, Pre-Alpha. The release history shows three tags published on the same day, all carrying the same build number.
Those two facts sit next to each other and they are not describing the same thing. Pre-Alpha is a packaging classification meaning the interface is not expected to be stable. The release identifiers are a different matter entirely: the counter is in the hundreds, the patch component is climbing, and the three most recent tags were published within about thirteen minutes of one another.
The Python requirement is declared as 3.11 or newer, with classifiers for 3.11, 3.12 and 3.13. The build backend is Hatchling rather than the more common setuptools, and the version lives in the manifest as a literal string, not derived from tags the way several other projects in this space do it.
So a reader choosing whether to depend on this has two contradictory signals and no obvious tiebreaker. The honest reading is that the classification describes intent about interface stability while the tag scheme describes release cadence, and that a project can publish constantly and still be telling you not to build on its interfaces.
The licence is the one place where every signal agrees. The index records MIT, the manifest declares MIT in text form, a licence file is present at the root, and a separate third-party notices file sits beside it. That is unusually tidy for a project of this size.
Three tag namespaces share one version number
The three most recent releases are not three versions. They are three artifacts at one version, each in its own tag namespace.
One is prefixed for the application itself, one for the browser extension, and one for the desktop build. They were published at roughly 13:23, 13:25 and 13:36, so a backend, a browser extension and a desktop application were all cut from the same commit within a quarter of an hour.
That structure explains a detail in the installation instructions that otherwise looks like an inconsistency. Chrome Web Store users are told that the newest features arrive first on the latest release and that the store version may lag by several days. With three independently tagged artifacts, that gap is structural rather than accidental: the extension tag exists the moment the extension is cut, while the store copy is a separate review process with its own delay.
It also explains why the repository carries three compose files rather than one. Alongside the default compose file there is a variant for HTTPS and a variant that uses a prebuilt image. One deployment shape is not enough for a project that has to cover a desktop app, a browser extension and a mobile client against the same backend.
The mobile client is not in this repository at all. It lives in a separate one, as does a plugin that embeds the same panel into a third-party agent interface, which registers twenty-two bridge tools and adds a fourth tab to that host's navigation.
The quick start asks you to hand a remote document to a coding agent
Step two of the quick start offers two desktop installers, then says that anyone who wants to change the source should paste a specific sentence into an AI coding assistant. The sentence names a document, a developer tool, and a fetching method, and it instructs the agent explicitly how to retrieve that document:
请按照 https://raw.githubusercontent.com/whiteguo233/OpenBiliClaw/main/docs/agent-install.md 的说明帮我部署 OpenBiliClaw 后端(务必用 Bash 的 curl 下载这个文档,不要用 WebFetch — 会丢关键指令)Translated, the instruction asks the agent to follow the deployment document at that raw URL, and insists it be downloaded with curl from a shell rather than through a web-fetch tool, on the grounds that the fetching tool loses important instructions.
This is the most security-relevant line in the readme, and it deserves to be read as a design decision rather than skipped. The project is delegating its own installation to an autonomous agent that will fetch and then obey a document served from a branch that is not a tag. Anyone following this is trusting three things at once: the person running the agent, the agent's willingness to follow instructions from a URL, and the content of a file on a moving branch.
That last part is the sharp edge. The URL points at the main branch rather than at a release tag, so the document a user executes today is not necessarily the document they would get tomorrow, and it is not pinned to the version of the software being installed.
The stated reason for avoiding the web-fetch tool is that it loses key instructions, which suggests the earlier instructions were being silently truncated. That is a reasonable diagnosis of the wrong failure, and the fix trades it for a different one.
A 1.1GB embedding model is baked into the image so it never needs the network
The compose file's first service is not the application. It is an embedding daemon, described at length in the comments above it.
The image bakes the embedding model into the build, at roughly 1.1GB, and its entrypoint seeds the model store before serving. The stated reason is that the container reaches an embedding-ready state with no network pull at all, which matters for offline use and for networks where that pull would be slow or blocked.
The daemon then runs on the internal compose network, and the application's embedding configuration is seeded to point at it on first bootstrap. Removing the service, along with its dependency declaration and one environment variable, switches the project to a cloud embedding provider instead. That is a documented alternative rather than a hidden coupling.
The health check is where the care shows:
    healthcheck:
      test: ["CMD-SHELL", "ollama list 2>/dev/null | grep -q '^bge-m3'"]
      interval: 30s
      timeout: 10s
      retries: 6
      start_period: 300s
Healthy means two things at once: the daemon is up and the model is present locally. Checking for the model's presence rather than for a port is what makes the check meaningful, and a generous start period accommodates the opt-in runtime-pull path without slowing down the normal case. There is also an environment variable to permit a network pull if the baked seed is ever missing, and the default is to fail loudly through the health check rather than degrade silently.
The client installer offers the same choice at the application layer: a slim build that downloads the vector model on first launch, or a larger offline build with the model already inside.
The image bakes in its own container marker and parses pyproject to cache a layer
Two details in the backend image are worth reading closely, because both are comments explaining a decision rather than restating the code.
The first is an environment variable that marks the image as containerised. The comment explains that the usual detection method is the presence of a marker file in the root filesystem, and that file exists under one container runtime but not under others such as containerd or Kubernetes. Rather than probe for a file that may be absent, the image sets its own variable, so install-mode detection works on every runtime.
The second is the dependency layer. Only the manifest is copied before installing, and the dependency list is extracted from it by a one-line Python invocation that reads the file and writes the requirement lines to a temporary file, which is then installed and deleted. The comment above it explains the ordering: copying the source tree first would invalidate the cached layer on every source edit and force a full reinstall measured in minutes.
That is a cache-key decision stated plainly. The trade-off is that the image installs the resolved requirements rather than the project's own package metadata path, and the source is copied in a later layer.
The base image is a slim Python 3.11 build, chosen because it is published as a multi-architecture manifest. The comment lists what that buys: Intel Macs, Apple Silicon, x86_64 Linux, ARM Linux including single-board computers, and Windows through a container runtime.
Dependency pins carry upstream reasons, and two optional backends ship by default
The manifest is unusual in how much it explains. Several constraints carry a comment giving the actual failure they avoid.
The two model client libraries are held below their next major version, and the comment names the reason precisely: the newer releases vendor their HTTP library internally under a different name, and the type guard in those releases rejects a client instance passed in through a parameter the project uses for proxy support. That is a specific incompatibility with a specific workaround, not a vague caution.
The same file carries two dependencies that exist purely so an optional feature cannot fail at runtime. A Twitter command-line package is in the default install so that enabling that source never fails, and a Reddit data tool is in the default install so that selecting that backend works without extra setup. Both comments say so in as many words.
That is a deliberate choice with a cost. Two packages that only some users need are installed for everyone, so every installation carries them and their transitive dependencies whether or not those sources are ever enabled. The alternative, declaring them as optional extras, would mean an install-time failure for anyone who enables the feature without reading the documentation.
A third entry is there for the same reason: a WebSocket library is described as a core API used by both the extension and the web interface, so it does not belong in an optional group.
Taken together, the dependency block reads as a record of things that broke, which makes it more useful than a bare list of version numbers. It is also the part of a manifest most likely to age, since each of those upstream constraints is waiting for a release that resolves it.
Only the browser extension touches platform sessions
The architectural rule is stated once and it governs everything else: the browser extension handles in-platform interaction and login sessions, while the desktop web interface, the mobile web interface, the native client and the agent-host plugin all call the local API only.
That division is what makes the local-first claim workable. The four non-extension clients never hold a platform credential, because they never talk to a platform. They read from the same local API and display what the extension has already collected.
The practical consequence is that the extension is the trust boundary. Whichever platforms need an account state reuse the session the user already has in their browser, and the readme is explicit that this is how account-gated sources work. Several sources are listed as discoverable without any account at all, and for GitHub the approach is narrower still: the backend reads public repositories anonymously through the official API, and a token is optional, used only for a higher rate limit and identity checking. A public username's starred repositories can be used as an initial signal.
Two interfaces are documented on the same local backend. The desktop web view is on the loopback address, and the mobile view is reached over the local network address, with a QR code in the extension to open it and an option to add it to a phone's home screen.
That second one is the security-relevant detail in this section. Reaching the service over a local network address makes it reachable by other devices on that network, which is a different exposure from a loopback-only service and is worth understanding before scanning the code on a café network.
Remote access over a private network is off by default and its keys stay out of config
Beyond the local network, the project supports reaching the backend through a private overlay network, and the configuration is careful in three specific ways.
First, the entry point is closed by default and the documentation says the service is visible only inside the private network. The public exposure features of that overlay are explicitly not enabled. It also recommends turning on an application password at the same time, so the service is not reachable on the private network without one.
Second, the credentials involved are described with unusual precision. There is a web-login path that can be left blank, an authentication key form, and a client-secret form for a device with an authorisation tag. All three require a full application restart to take effect. The claim made about them is that they are held in local private storage only until the next start, and that they do not enter the configuration file, the API's echoed output, or logs.
That is a specific and testable claim, and it is the kind that is worth verifying rather than assuming, because a credential that reaches a configuration file or an API response has usually already been copied somewhere.
Third, the overlay client does not require installing anything on the host machine. It is compiled in as a helper binary, and building that helper from source needs a specific Go toolchain version. The mobile applications bundle the client directly.
Two limits are stated too. The capability applies to the two phone applications and not to the web or desktop clients on any platform, and the documentation is explicit about the boundary.
Editorial conclusion
OpenBiliClaw suits someone who wants a recommendation surface that is not owned by a platform, is willing to log into their own accounts through a browser extension, and wants the resulting profile to stay on their own disk. It does not suit someone who needs a stable interface, because the project classifies itself as Pre-Alpha and its release identifiers are build counters rather than versions. Four things to weigh. What a psychological profile of your own behaviour is worth to you, since the project infers personality categories and builds a layered model of you rather than modelling topics. Which LLM you point it at, since your own key is the default and reusing a local coding tool's credentials is described as experimental. Whether you are comfortable with an extension that holds your logged-in sessions. And whether you accept an install step that hands a remote document to an automated agent to execute.
Frequently asked questions
What is OpenBiliClaw?
It is a local-first, open-source content discovery agent written in Python. It builds a profile from your cross-platform behaviour and feedback, then searches Bilibili, Xiaohongshu, Douyin, YouTube, X, Zhihu, Reddit, Linux.do, Bangumi, V2EX, Weibo, GitHub and the open web for content you have not consumed.
What does OpenBiliClaw need in order to run?
Python 3.11 or newer, a browser extension for in-platform interaction and login sessions, and either the bundled embedding model or a cloud provider. Desktop installers are offered as a macOS disk image and a Windows executable, in a slim build that downloads the vector model on first launch and an offline build that already contains it.
Does OpenBiliClaw need a GitHub personal access token?
No. GitHub is read anonymously through the official REST API for public repositories, and a public username's starred repositories can be used as an initial signal. A token is optional, described only as a way to raise the rate limit and to check identity.
Where does OpenBiliClaw store my data?
Behaviour, recommendation and conversation data stay in a SQLite database on your own disk, and configuration, the profile, credentials and cache are kept in local files. The project states that it operates no cloud account of its own, so nobody else can see the profile it builds.
Can OpenBiliClaw reach my computer from outside my local network?
Yes, over a private overlay network, and the entry point is closed by default with public exposure features not enabled. Credentials for it are described as held in local private storage until the next start, and as never entering the configuration file, API output or logs. Enabling it also requires a full application restart, and the project recommends turning on an application password at the same time.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/whiteguo233-openbiliclaw)Star history chart for your README
[](https://hysenlabs.com/projects/whiteguo233-openbiliclaw)Was this useful?