adi runs Stable Diffusion, FLUX and SVD through ONNXRuntime with no Python
Accelerate your Stable Diffusion inference with the library's universal C/C++ framework design, powered by ONNXRuntime & across platforms.
At a glance
- What is it?
- Agile Diffusers Inference is a C++17 library and CLI that loads ONNX models and generates images and video without a Python process, across nine platform targets. Its own numbers are CPU-only on an Apple M4 Max, where a 4-step 1024px SD3.5-turbo frame takes about 164 seconds, and since v2.0.0 the Homebrew tap is Apple Silicon only.
- Who is it for?
- adi fits a team shipping a fixed ONNX pipeline on CPU or mobile hardware where a Python process is the thing you want gone, and it is honest about its measurements. It does not fit GPU inference, workflows that need features outside its model list, or a closed-source product that links libadi.a without reading GPL-3.0 first.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 74 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
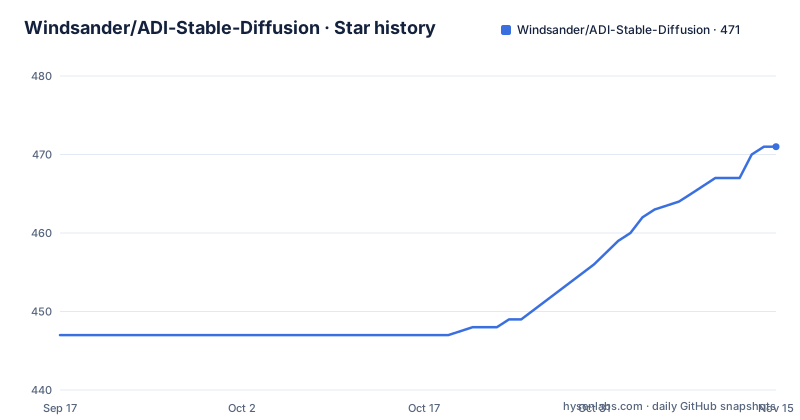
Star history
- Windsander/ADI-Stable-Diffusion471 ★ · +24
| Repository | 2026-09-17 | 2026-11-15 |
|---|---|---|
| Windsander/ADI-Stable-Diffusion | 447 | 471 |
24 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
164 seconds for four 1024px steps, on a CPU
The performance section reports two numbers, both measured on an Apple M4 Max with 128 GB of memory, ONNXRuntime 1.28.0, the default provider, and a single cold run with no GPU and no Python: sd-turbo at 512 by 512 in four steps takes about 9.7 seconds, while SD3.5-turbo at 1024 by 1024 in four steps takes about 164 seconds. That is roughly seventeen times the wall time for four times the pixels and a much heavier model, and the second figure is the one to plan around if you are considering the MMDiT generation. Both are single-machine, single-run numbers with no repetition, so treat them as an order of magnitude rather than a benchmark. Sample images come from the same path, on CPU with no Python: stills come from the prompt 'A cat in the water at sunset', and the SVD clip animates a single input photo into fourteen frames at twenty-five steps.
The Homebrew tap dropped Intel Macs in v2.0.0
Installation splits three ways, and the package manager path has a hardware footnote that arrived with the 2.0 release. The tap serves Apple Silicon only, because upstream ONNXRuntime discontinued the osx-x86_64 prebuilt, so an Intel Mac has to build from source instead. That is the kind of dependency change that quietly ends support for a machine, and it is documented rather than hidden.
## macOS (Homebrew, Apple Silicon):
brew tap windsander/adi-stable-diffusion
brew install adi
Windows goes through git-Bash and Chocolatey, with the package pinned to a version in the URL:
curl -L -o adi.2.0.0.nupkg "https://raw.githubusercontent.com/Windsander/ADI-Stable-Diffusion/deploy/adi.2.0.0.nupkg"
choco install adi.2.0.0.nupkg -y
The tap and the Chocolatey channel are refreshed by the deploy chain on every release, so what you install follows the tags rather than a version you choose.
The release archive ships a static library and a header
The second method is a plain download, and its file tree tells you what linking against adi looks like: `bin/adi`, `lib/` holding the platform library such as `libadi.a` alongside the matching ONNXRuntime shared library such as `libonnxruntime.dylib`, and `include/adi.h`, plus the changelog, readme and licence. You can put `bin` and `lib` on your system paths or run the binary from the unzipped folder. That layout is the interesting part. A static `libadi.a` plus a public header is a library meant to be linked into someone else's program, and the licence file that travels with it decides what you may do with the result.
--precision auto writes fp16 copies based on your RAM
The precision policy is a single flag with three values, `auto`, `fp32` and `fp16`, and `auto` probes available memory and derives fp16 model copies on demand for machines that cannot hold the full-precision weights. On-demand derivation implies disk: the first run of a large model may write a converted copy next to the original rather than using it in place. For a deployment target with a read-only filesystem, or a container with a small writable layer, that is the failure mode to check, and the documentation does not say where the derived copies land. The rest of the engine work in 2.0.0 is the move to ONNXRuntime 1.28.0, reported as bit-identical output against the previous engine baseline across 25 local regression cases.
Fourteen schedulers, verified against diffusers with numpy
Sampling is where a diffusion runtime either matches its reference or quietly drifts, and adi makes a specific claim: 14 discrete schedulers plus Karras sigmas and the rectified-flow family, all numpy-verified against diffusers. The 25 of 25 regression cases backing the engine upgrade are local to the project, so the reproducibility story is a self-check rather than an external audit, but the reference implementation is named, which is more than most C++ inference ports offer. For video there is a dedicated `euler_svd` scheduler with a spatio-temporal UNet and a CLIP vision encoder, so SVD img2vid is a first-class mode rather than a series of stills. Both MMDiT-era models are named with their awkward parts intact, since that is where porting usually fails: SD3.5-turbo uses three text encoders including T5-XXL through SentencePiece, and FLUX.1-schnell uses packed latents and rotary ids, both at 1024px.
Nine platform targets and one Python file in the tree
The distribution chain publishes per-platform artifacts for Android four times over, Linux twice, macOS arm64, and Windows twice, which is where the nine platform targets come from. Release history is lumpy: v1.0.1 landed on 2024-08-09, then nothing until v1.2.0 on 2026-08-01 and v2.0.0 on 2026-08-27, with the last push on 2026-09-02. Three releases in four weeks after a two-year gap is a project finding its stride, not a steady cadence. Alongside them the repository carries an `ort_sd_py_imp.py` file, plus `auto_build.sh`, `auto_clear.sh` and `auto_deploy.sh`, an `engine/` directory, `clitools/`, `apex/` and `apex-toolchain/`. An orphaned Python file sits beside the zero-Python claim, though nothing suggests it runs at inference time rather than during export or conversion. Documentation is bilingual, with `README_CN.md` beside the English `README.md`, plus `ARCHITECTURE.md`, `ROADMAP.md`, `SECURITY.md` and a `PLAN-supplement.md`. Building from source goes through one script, which defaults to a Debug build when no type is passed and picks a provider by platform:
bash ./auto_build.sh
bash ./auto_build.sh --platform macos --build-type debug
CMake options cover the trade: `ORT_COMPILED_ONLINE` for a downloaded runtime against a local build, `ORT_BUILD_COMMAND_LINE` for the tools, and `ORT_COMPILED_HEAVY`, which is debug-only, off by default and flagged as unrecommended.
GPL-3.0 decides what you can do with libadi.a
The licence is GPL-3.0, and that matters more here than the licence of a command line tool would, because the release archive hands you a static library and a header for linking into your own program. Permissive licences let you ship a binary without passing anything on; a copyleft licence asks questions about what happens when your code links the library. That is a question about your distribution model, not a detail, and the terms in `LICENSE` are where the answer lives. If you only run the `adi` binary as a separate process the analysis is different from embedding it, which is why the static library in the artifact tree is worth noticing before you pick an install method.
Where adi is the wrong tool
Two boundaries stand out. One boundary is the GPU. Every number in the documentation comes from the default provider on CPU, and ONNXRuntime's GPU providers are not what adi's own measurements describe, so anyone whose reason for choosing a diffusion runtime is a discrete GPU should benchmark elsewhere before assuming parity with a Python stack. The other is model coverage: the catalogue runs from SD v1.5 through SD3.5, FLUX and SVD, with sd-turbo, SDXL-turbo, SD v2.1 and SD3.5-turbo in the sample gallery, and anything outside that list is outside what the CLI will load. Nothing in the catalogue mentions ControlNet, LoRA weights or inpainting pipelines, so treat those as unsupported until a release note says otherwise. The honest alternative for full-featured generation remains diffusers in Python, which is also the implementation adi's schedulers are verified against.
Editorial conclusion
adi fits a team shipping a fixed ONNX pipeline on CPU or mobile hardware where a Python process is the thing you want gone, and it is honest about its measurements. It does not fit GPU inference, workflows that need features outside its model list, or a closed-source product that links libadi.a without reading GPL-3.0 first. Verify three things before adopting: that your target is in the published artifact list, that ONNX exports exist for your models, and how the static library interacts with your own licence.
Frequently asked questions
How do I install the adi command line tool on macOS?
On Apple Silicon, tap the repository and install with brew: brew tap windsander/adi-stable-diffusion followed by brew install adi. Since v2.0.0 the tap serves arm64 only, because upstream ONNXRuntime discontinued the osx-x86_64 prebuilt, so Intel Macs have to build from source with auto_build.sh.
Which models can adi generate?
The catalogue covers SD v1.5 through SD3.5, FLUX and SVD. Version 2.0.0 added SD3.5-turbo with three text encoders including T5-XXL through SentencePiece, FLUX.1-schnell with packed latents and rotary ids at 1024px, and SVD image-to-video with a dedicated euler_svd scheduler.
Does adi need Python or a GPU?
No Python at inference time, according to the documentation, and every published timing is CPU-only on an Apple M4 Max with no GPU. The repository does contain a Python file, ort_sd_py_imp.py, so Python is present in the project's tooling even though it is absent from the inference path.
Can I link adi into a closed-source product?
That depends on the GPL-3.0 terms in LICENSE and on how you link. Release assets include a static library such as libadi.a and the adi.h header, which is the copyleft case to think through first. Running the adi binary as a separate process is a different arrangement from embedding the library.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/windsander-adi-stable-diffusion)Star history chart for your README
[](https://hysenlabs.com/projects/windsander-adi-stable-diffusion)Was this useful?