better-sqlite3: the synchronous driver with eight platform entry points
The fastest and simplest library for SQLite3 in Node.js.
At a glance
- What is it?
- better-sqlite3 wraps SQLite in a synchronous Node.js API, lists eight platform targets in its package exports, ships prebuilt binaries for major platforms, and asks you to switch on WAL. Its README is unusually candid about the limits, naming three workloads where you should use a full database server instead, and about where its speed claims come from.
- Who is it for?
- Use it for short queries in command-line tools, desktop applications, embedded caches and services with suitable concurrency. SQLite can coordinate multiple processes; in WAL mode readers and a writer can generally proceed concurrently, although writes still serialize and applications must handle SQLITE_BUSY.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
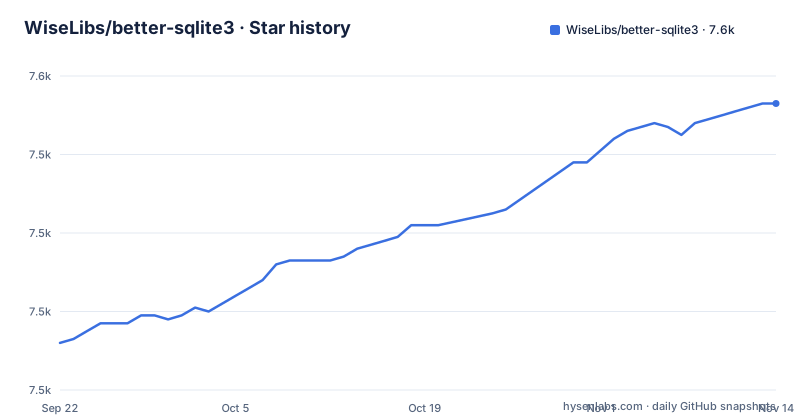
- WiseLibs/better-sqlite37,553 ★ · +61
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| WiseLibs/better-sqlite3 | 7.5k | 7.6k |
61 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The API is synchronous on purpose, and that is the whole argument
The feature list says it plainly: an easy-to-use synchronous API, followed by a parenthetical that better concurrency than an asynchronous API is the claim, and that yes, you read that correctly. The reasoning is given against node-sqlite3. Asynchronous APIs are used there for tasks that are either CPU-bound or serialized, which the README calls bad design that wastes resources and causes mutex thrashing with devastating effects on performance. Memory is the second argument: node-sqlite3 exposes low-level C language memory management functions, while better-sqlite3 does it the JavaScript way and lets the garbage collector worry about memory. The consequence is the thing to plan for. A synchronous call blocks the event loop for its duration, which is exactly right for a script or a worker and exactly wrong for a request handler sharing a thread with other work. Worker thread support exists for large or slow queries, which is the project's answer rather than a promise that the blocking goes away.
Eight platform entries in the exports map pick your binary
Installation is one command, and what happens underneath is worth knowing when it fails:
npm install better-sqlite3The package manifest requires a currently supported Node.js version and the engines field asks for node >=22. Instead of one entry point, the exports map lists eight platform targets: linux-x64, linux-arm64, linuxmusl-x64, linuxmusl-arm64, darwin-x64, darwin-arm64, win32-x64 and win32-arm64, each mapped to its own file under lib/. The files array ships binding.gyp, the C and C++ sources under src/, lib, deps and prebuilds, which is where the compiled artifacts live. The musl entries are the ones that catch people: a container on Alpine and a container on glibc are different targets and load different files, while a platform outside those eight has to compile from source with node-gyp. The README points at a troubleshooting guide for exactly those cases.
build-release forces a rebuild, which means it needs a toolchain
The scripts explain how the native side is produced. `build-release` is `node-gyp clean && node-gyp rebuild --release --force_build=1` and `build-debug` does the same with the debug flag, with the force flag in both. The `download` script runs `bash ./deps/download.sh` to fetch the SQLite sources that live in deps/, and `clean` removes node_modules, build and prebuilds entirely. The gypfile field is false, so the build is driven by these scripts rather than by an automatic npm rebuild. The practical consequence is the usual one for native Node modules: an install that cannot use a prebuild compiles, and compiling needs a working toolchain inside your image.
The comparison table is a claim you are invited to reproduce
The README publishes a table comparing itself with the sqlite and sqlite3 packages, with better-sqlite3 as the 1x baseline across five operations: selecting one row with get(), selecting 100 rows with all(), selecting 100 rows one at a time with iterate(), inserting one row with run(), and inserting 100 rows inside a transaction. Against that baseline, sqlite and sqlite3 are given as 11.7x slower, 2.9x slower, 24.4x slower, 2.8x slower and 15.6x slower respectively. Two things make this more than marketing. The page says you can verify the results by running the benchmark yourself, and the repository carries the means: a benchmark directory, an npm script `benchmark` set to `node benchmark`, and devDependencies on both sqlite and sqlite3 so the comparison packages are actually installed. Read the shape of the numbers before choosing on them. The gap is widest when iterating rows one by one and narrowest on a single insert, so the driver choice matters most when your code streams rows.
WAL is the switch the project keeps pointing you at
Usage is three lines, and the third one is the advice:
const db = require('better-sqlite3')('foobar.db', options);

const row = db.prepare('SELECT * FROM users WHERE id = ?').get(userId);
console.log(row.firstName, row.lastName, row.email);db.pragma('journal_mode = WAL');Setting the WAL pragma is described as generally important for performance reasons, though not required, and in ES module notation the same thing appears as `import Database from 'better-sqlite3'` followed by `new Database('foobar.db', options)` and the pragma call. The reason this is emphasised is the section on when the library is not appropriate, which states that the most likely causes of a performance problem are inefficient queries, improper indexing, or a lack of WAL mode, and not better-sqlite3 itself. WAL can improve concurrency, but it is not a universal performance fix: measure the workload and review its same-host and checkpointing constraints before enabling it.
Three named workloads are where you should stop using it
The README has a section asking when this library is not appropriate, and the answer is workload shaped rather than feature shaped. A high volume of concurrent reads each returning many megabytes of data, with videos as the example. A high volume of concurrent writes, with a social media site as the example. And a database size near the terabyte range. For those the recommendation is a full-fledged RDBMS such as PostgreSQL. The reasoning underneath is about serialization: if your queries take one second to complete and you expect many concurrent users running them, no amount of asynchronicity saves you from SQLite's serialized nature. The counterweight is a figure for what is achievable when the database is used as intended, upward of 2000 queries per second with 5-way joins in a 60 GB database where each query handled 5 to 50 kilobytes of real data, with proper indexing. Read both numbers before deciding.
An upgrade can change your database files, not just your code
Upgrading is the part that bites people who treat the package like any other dependency. Moving your better-sqlite3 version can introduce breaking changes either in the API, if you cross a major version on semver, or between your existing databases and the underlying version of SQLite. That second cause is the one that is easy to miss, because nothing in your code changed. The instruction is to review the better-sqlite3 release notes and the SQLite release history before you upgrade, which is two reading tasks rather than one. The documentation set backs this up with separate files for the API reference, performance, benchmark results, 64-bit integer support, worker threads, unsafe mode for advanced use and SQLite compilation for advanced use, plus contribution rules and a code of conduct. The feature list also hides two capabilities worth knowing exist: 64-bit integers that stay invisible until you need them, and user-defined functions, aggregates, virtual tables and extensions. Released as v13.0.3 on 2026-08-05, MIT licensed, with the last push on master dated 2026-08-10.
Editorial conclusion
Use it for short queries in command-line tools, desktop applications, embedded caches and services with suitable concurrency. SQLite can coordinate multiple processes; in WAL mode readers and a writer can generally proceed concurrently, although writes still serialize and applications must handle SQLITE_BUSY. For high volumes of concurrent writes, high volumes of multi-megabyte reads, or databases near a terabyte, the README suggests considering a server database such as PostgreSQL. Before upgrading a major version, read both the release notes and the SQLite release history, because an upgrade can introduce breaking changes between your existing databases and the underlying version of SQLite, not just in the API.
Frequently asked questions
Which is better, sqlite3 or better-sqlite3?
The project's comparison puts better-sqlite3 as the baseline and lists sqlite and sqlite3 as 11.7x slower for a single row get(), 2.9x slower for 100 rows with all(), 24.4x slower when iterating rows one by one, 2.8x slower for a single insert and 15.6x slower for 100 inserts in a transaction. It also asks you to verify these yourself by running the benchmark.
how to install better-sqlite3
Run npm install better-sqlite3. It requires a currently supported Node.js version, and the engines field asks for node >=22. Prebuilt binaries are provided for major platforms and architectures, with separate entries for glibc and musl Linux builds; if the install falls back to compiling, check the troubleshooting guide in docs.
is better sqlite3 async
No, it is synchronous by design, and that is the stated argument for using it over node-sqlite3, whose asynchronous APIs are applied to CPU-bound or serialized work and cause mutex thrashing. For large or slow queries the project points at worker thread support instead of an asynchronous API.
What is the best alternative to SQLite?
The project names the cases rather than a single replacement: a high volume of concurrent reads returning many megabytes, a high volume of concurrent writes, or a database size near the terabyte range. For those situations it recommends a full-fledged RDBMS such as PostgreSQL, because SQLite serializes writes and no amount of asynchronicity changes that.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- From Vibe Coding to Spec-Driven Development with Kiro IDE from AWSdev.to · Nov 11, 2026 · 6 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wiselibs-better-sqlite3)Star history chart for your README
[](https://hysenlabs.com/projects/wiselibs-better-sqlite3)Was this useful?