ghq reads its configuration out of git, and its newest release landed two minutes after its last commit
Remote repository management made easy
At a glance
- What is it?
- An MIT-licensed Go tool that organises remote repository clones into a mirrored host and path layout, documented as a manual page in AsciiDoc, with eight subcommands, a dozen configuration variables and twelve supported version control backends. Three patch releases shipped on one afternoon, the same short flag means two different things depending on the subcommand, owner completion defaults to an environment variable that is often wrong, and the build pins one tool by version while installing another at latest.
- Who is it for?
- ghq is worth using if you keep many clones and want them laid out by host and path so a path in a repository matches a path on disk, because that is the whole idea and it makes a scratch checkout, a mirror and a worktree cheap to find. Two things to know.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
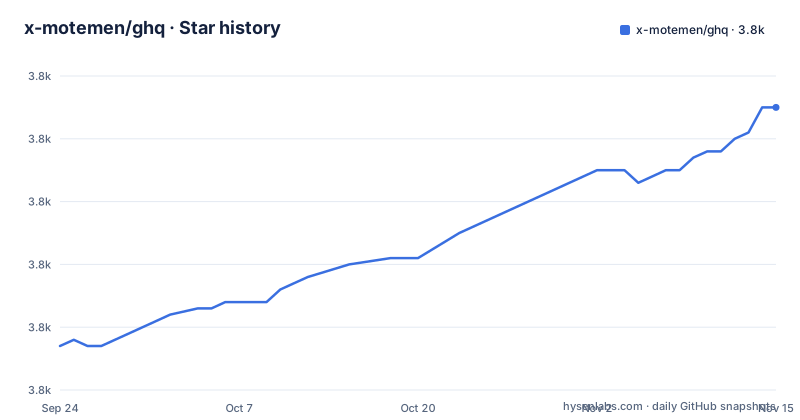
- x-motemen/ghq3,815 ★ · +38
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| x-motemen/ghq | 3.8k | 3.8k |
38 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three releases on one afternoon
The three newest tags are three patch versions of the same minor line, all published on the same afternoon, roughly fifty minutes apart and then about eighty. The newest of them was published two minutes after the repository's last push. So this is a project that releases on demand, immediately after the change that justifies it, which tells you something about its development rhythm and also means the tag list is not a useful guide to significance. That cadence is enabled by a small piece of tooling rather than by habit: the release target in the build file runs the module tidy, regenerates a credits file from the module graph, and then stages the changed files in the index directly. There is a separate configuration file whose only job is to drive the tagging.
The documentation is written as a manual page
The readme is an AsciiDoc file rather than Markdown, and it is structured the way a manual page is: a name section, a description, a synopsis written in a verse block, then one entry per command with its flags, then configuration, then cross-references. The command list is written in the same syntax the terminal accepts, with option letters and metavariables inline, which means you can compare your terminal against the documentation line by line. Two consequences. It renders as a man page if you have an AsciiDoc toolchain, and it renders as plain text with markup artefacts everywhere otherwise. And there is no illustrated section at all, no before-and-after of a directory tree beyond the one listing further down. For a tool whose entire user interface is a directory layout, that is the section you would want.
The same short flag means two different things
The synopsis puts the options for every subcommand on adjacent lines, and reading them together shows one collision. On the clone command, the short option selects the SSH protocol instead of HTTPS. On the list command, the same short option means print full repository paths instead of relative ones. Both are the letter for their command and both are the first letter of a long form, and neither is wrong in isolation. But a tool with a global mental model where letters are consistent will get this wrong, and the documentation gives no warning because in a manual page the options are scoped to their command by construction. It is the one place in this documentation where the format actively hides a hazard.
Owner completion reads an environment variable
When you ask for a repository by name alone, with no slashes, the tool has to guess who owns it, and the documented default for that guess is an environment variable: the user name on Unix, with a separate one consulted on Windows. Setting the corresponding configuration variable overrides it explicitly, and a second variable changes the strategy entirely so that a bare name completes to the owner of the same name, which is why fetching a well-known project by its own name works the way people expect it to. The default, though, is wrong in exactly the environments where automation runs. A container with no user set, a scheduled job running as a numeric identity, a build agent that exports a variable from an earlier stage: all of them produce a clone under an owner nobody intended, with no error. If you script this tool, set the owner.
Configuration is resolved by git's own URL matching
There is no configuration file. Every setting is a git configuration variable, including two that take a URL as part of their name and are matched against the repository being fetched using git's URL matching facility. That is a good design: you already have a config file, it already supports per-host sections, and a developer who understands one understands the other. The per-URL variables let you pin the version control backend and the root directory for one host without affecting anything else, and the accepted backend list is long, with aliases for the three systems whose short names people actually type. The cost is a minimum git version, stated in the documentation for the feature to take effect at all, which is the sort of requirement that bites on a machine where git was installed from an old package.
Twelve backends, two bare layouts and a warning about shallow clones
The clone command's flag list is where the depth shows. There is a recursive fetch by default that the `--no-recursive` flag turns off, which matters for Git repositories containing submodules. Shallow and partial clones are both available for one backend, in blobless and treeless modes, and both are called out as having consequences. Two layouts for a bare clone: one that suffixes the directory, and one that keeps the name clean by placing the bare repository inside a dot-directory so that worktrees can sit beside it as siblings, with a small directory listing in the documentation showing the shape. Passing both layout flags is not an error, one is ignored with a warning, which is a forgiving design choice for a tool people script. The clean layout it produces is the only tree diagram in the whole document:
repo/
├── .git/       # bare repository
├── main/       # worktree
├── feature/    # worktree
└── bugfix/     # worktree
The build pins one tool by version and installs another at latest
The build file is small and mostly good. The version stamped into the binary comes from the current commit, injected at link time, which is the standard approach. The test target runs the whole module. The lint target installs a static analyser and then runs it, rather than assuming it is present, which is convenient. The credits target installs a generator at a fixed version and regenerates a file that is derived from the module graph, so the dependency list in the repository is machine-written rather than maintained by hand. The inconsistency is in the two install lines in the same file: one tool is pinned to a release and the other is installed at its latest version, so a lint run can change behaviour without anything in the repository changing.
The source is flat at the repository root
Every command lives in its own file at the top level of the repository, and each one has its test file directly beside it with the same base name. Beside them sit the files that are not commands: the dispatcher, the fetch logic, the import logic, the local and remote repository types, the URL parser, the backend detection and the worktree handling. Only three things get their own directory: shared command utilities, the logger, and a miscellaneous directory. Platform differences are handled in one pair of files with a build constraint and the test for the non-Unix side. It is a layout that makes a six-year-old codebase navigable in one screen, and it is also why the tree at the root is the clearest documentation the project has. Two small files there are worth noticing: a spell-checker configuration, and the tagging tool's configuration.
Editorial conclusion
ghq is worth using if you keep many clones and want them laid out by host and path so a path in a repository matches a path on disk, because that is the whole idea and it makes a scratch checkout, a mirror and a worktree cheap to find. Two things to know. Configuration lives in your git config rather than in a file of its own, which is elegant for per-host overrides and means selected per-URL settings use Git's URL matching, with a minimum git version attached. And owner completion defaults to an environment variable, so in a container or a scheduled job where that variable is unset or belongs to another account, a bare repository name silently resolves to the wrong place. Pass the owner explicitly there.
Frequently asked questions
What does ghq do?
It organises remote repository clones into a directory tree that mirrors the host and path of the remote, so a clone of a repository on one host lands at a predictable location under a root directory you choose. There are commands to fetch, list, remove with a dry-run option, create a remote, print the configured roots, and migrate an existing clone into the managed layout.
How do I configure ghq?
Through git configuration variables rather than a file of its own. The root directory, the default owner, the owner-completion strategy, the default host, and per-URL overrides for the version control backend and the root, where the URL is matched with git's own URL matching and a minimum git version is needed for that to apply.
Which version control systems does ghq support?
The documentation lists twelve names with aliases: git with github as an alias, subversion with svn, git-svn, mercurial with hg, darcs, fossil, and bazaar with bzr. The backend is detected for hosts other than the default one, and can be pinned per URL through configuration.
Why does ghq clone into an unexpected owner directory?
When you give a repository name with no slashes, the owner is completed from a configuration value whose default is a user environment variable, with a different one consulted on Windows. In a container or a scheduled job where that variable is unset or wrong, the clone lands under an owner you did not intend.
Does ghq have any effect on my git configuration?
Yes, indirectly. The readme notes that because fetching runs git's own clone for git repositories, your git configuration applies too, and gives the remote-name setting as an example of a git default that changes what the created remote is called.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/x-motemen-ghq)Star history chart for your README
[](https://hysenlabs.com/projects/x-motemen-ghq)Was this useful?