printfilm's compose file ships a default database password, publishes the database port, and asks contributors for Simplified Chinese copy
PRINTFILM: an AI platform for creating science-education videos and comic dramas.
At a glance
- What is it?
- yi1108/printfilm is a MIT-licensed, Chinese-language project that turns a script into a finished short video through storyboard, image, video and compositing stages, at v0.3.0 with the last push on 2026-10-29. It self-hosts from a public container image with no build step, which is what makes the deployment section the most instructive part of the file.
- Who is it for?
- printfilm is a good fit if you want the whole video pipeline in one self-hosted stack and you already pay for image and video generation through a compatible gateway, since text, image and video generation go to that gateway and the model names are configuration. Two things to check before you start it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
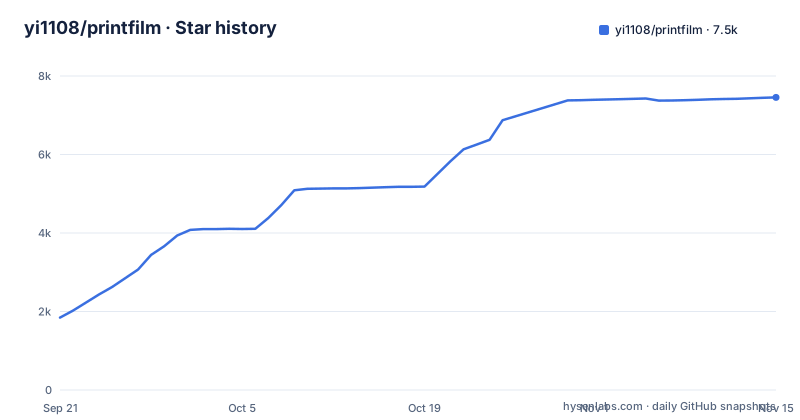
- yi1108/printfilm7,455 ★ · +5,610
| Repository | 2026-09-21 | 2026-11-15 |
|---|---|---|
| yi1108/printfilm | 1.8k | 7.5k |
5,610 Stars in the last 55 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One pipeline with two product lines sitting on top of it
The file states the workflow as a diagram:
选择画风、输入想法或已有文案
    → 编辑与保存文案 → 确认后生成分镜
    → 检查分镜卡片 → 使用画风参考图生成图片
    → AI 视频:图片生成镜头视频与声音 → 检查并合成
      静图成片:生成外部 TTS 配音 → 合成运镜、字幕与旁白
    → 预览与下载成片
Choose a style, enter an idea or paste an existing script, confirm it to generate shots, generate images from the style reference, then either turn each image into a shot video with sound or generate external TTS narration for stills, and finally preview and download the finished film. Each stage stops for review and the next step is started by the user, and projects are managed from the history page.
The two branches are the interesting part. In AI video mode each shot image becomes a shot video with sound, so there is no separate dubbing step; the static-image mode instead generates external TTS narration and FFmpeg adds camera motion and subtitles.
Two products sit on that one flow, and the file says they share the same upstream generation capability. The comic-drama line goes from a single sentence to episode-length output with characters and scenes reusable across episodes, backed by an asset library of characters, scenes and props. The short-video line starts from one of four curated non-photorealistic styles (3D animation, 2D anime, picture-book illustration and Chinese ink) and is described as suited to acquisition clips, with two modes: AI video and static images.
A third surface, the tool centre, skips the pipeline and offers standalone generation entries for images, video and audio.
Tasks survive leaving the page, and the task platform runs inside the API process
Two technical decisions are stated as characteristics rather than explained, and both matter for how you deploy it.
The first is that the task platform is in-process: a scheduler, an executor and a poller, with no separate Celery worker required.
That is a real simplification. The usual shape for a Python job queue is a broker plus one or more worker processes, which means a second thing to deploy, scale and monitor. Collapsing it into the application means one fewer container, and the cost is that generation work competes with request handling inside the same process, so a long video job can affect the latency of the API that queued it.
The second is that you can leave the page and return to the project to resume progress. The short-video feature list says this explicitly, alongside single-shot preview and regeneration.
Both facts follow from the same design choice. Generation is slow, so work cannot live in a request handler. Moving it into a background loop inside the process means a page refresh or a closed tab is irrelevant, which is why the history page is the progress view rather than the job page.
The health endpoint is the third piece of that contract: the README says to wait about half a minute after startup, and that the web and admin services come up only after the API health check passes.
Model choice is a database setting, and one doc file is named after a model version
The third stated characteristic is that the model is swappable, configured with a key and a model in the admin backend without changing code.
The environment file shows what that looks like by default, with three model variables covering the three capabilities:
OPENAI_BASE_URL=https://www.tokenfree.com/v1
MODEL_LLM=kimi-k2.6
MODEL_IMAGE=seedream-5-0-pro
MODEL_VIDEO=seedance-2-5
So the text, image and video models are three independent settings, each a name rather than an endpoint, resolved against a single compatible gateway. The admin backend has a model routing page and a channel page, and the file says changes there take effect immediately without editing the environment file.
What that design costs is documentation churn. The repository carries a document named after a specific video model version, holding that model's parameters. So at least one part of the docs tree is organised by model version rather than by feature, and every model upgrade is also a documentation task.
The troubleshooting table names the failure mode that produces: a model name returning 404 means the identifier is not one the gateway actually offers, and the fix is to pick from the list in the admin model list rather than to guess.
Two of the four key routes put the secret in the database, and the other two in a file
There are four documented ways to give the platform its generation key, and they differ in what you end up backing up.
The first is the vendor's own console: register, open the tokens section, create a key, set a quota and an expiry, and copy it, because it is shown once. The file adds the right warning: a key is equivalent to a password, do not commit it or post it in a group, and if it leaks, invalidate and rebuild it in the console.
The second is the environment file, which is what the quick start does. The key goes in two variables, and the file is explicit that you fill the same key into both.
The third is the admin backend, and this is the one with a consequence. It says a key saved there is encrypted into the database, and that when you move machines you must either back up the database as well or re-enter the key. So a routine database dump now contains a credential, and the backup becomes a secret-bearing artefact.
The fourth is not a route but a table of symptoms and fixes, which includes the check for whether the environment file still contains the placeholder value the example ships with.
There is also a mock mode. With no key at all, setting one flag lets you see the interface without real generation, and the health endpoint reports whether mock mode is on.
The compose file carries a default password and publishes both datastore ports
The self-host compose file is the one the quick start uses, and it is worth reading before running it.
The database service defaults the user, database and password to values in the file itself, with the password default written out in full as a placeholder. The environment file overrides it if you set one, which is why the quick start insists you change it.
The failure mode is worth naming. Compose substitutes the default when the variable is unset, so a deployment that skips the password edit does not fail; it starts, and it starts with a password that is written in a public repository.
The second thing is the ports. The database publishes a host port, and the cache publishes another. Compose publishes those on all host interfaces unless you bind them to loopback, so a machine on an untrusted network ends up with its database reachable.
The rest of the file is careful. The database has a health check with a retry count, and the API service declares that it waits for that check to pass. The cache runs with persistence on, a memory ceiling of half a gigabyte, and a policy that evicts any key once full. Generated media is written to a named volume rather than into the container.
The API image is pulled from a public registry in one specific cloud region, tagged with a moving tag.
The cache has a hard ceiling and an evict-everything policy
The cache service in the compose file is configured with three flags, and one of them is a design decision rather than a default.
Persistence is on. The memory ceiling is set to five hundred and twelve megabytes rather than left unbounded. And the eviction policy is the one that evicts any key when the ceiling is reached, rather than one that only evicts keys that have expired.
That combination is a deliberate statement: this cache is a working set, not a store of record. Nothing in it should be the only copy of anything, because any entry can disappear at any moment under load. Combined with the fact that it persists to a volume, you get a cache that survives a restart but not a spike.
The health check is a single ping with a three second timeout and twenty retries, which is the one place the file is generous.
Administration bootstraps by email and never creates an account
There are two roles, and the way you get the second one is the detail worth knowing.
A normal user registers with an email address at the authentication path of the user-facing service.
An administrator is bootstrapped in three steps: register normally with the address you want, add that address to an environment variable that lists bootstrap admin emails, then recreate the API container so the variable takes effect. The file annotates this with a short parenthetical, and it is the point: it promotes privileges and does not create an account.
So there is no seeded account, no default password and no first-run credential to rotate. The file states it directly, that the repository ships no built-in demo account, and reminds you to change the keys immediately in production.
The other variable in that list is a general secret used for sessions and for key encryption, which connects back to the previous section: the same secret protects the sessions and decrypts the generation key you saved in the admin. It is the highest-value line in the environment file and the file gives no guidance on its length or generation beyond any long random string.
Support is a WeChat account and contributions are expected in Simplified Chinese
The community section is two lines and both of them are worth noting for what they say about who this is for.
The first is the repository. The second is a messaging app account, with an instruction to add it and leave a specific note so you get added to the group, described as the place for deployment questions, short-drama discussion and template sharing.
There is no forum, no issue-first policy and no stated language for that channel. For a self-hosted product whose hardest part is the first deployment, a direct chat channel is a reasonable choice, and it also means the answers that matter most may not be searchable later.
The contribution section is more prescriptive, and it names three rules to check against the project's engineering standards document before opening a pull request: user-facing copy in Simplified Chinese, function comments, and server-side pagination. It also asks contributors not to commit environment files, keys, or generated media.
The Simplified Chinese rule is the one an outside contributor will meet first. It is not a technical barrier so much as a scope statement: this is a project built by Chinese-speaking developers for Chinese-speaking users, and the interface language is part of the definition of done rather than an incidental choice.
The local checks are three commands, two lint runs for the two front ends and a test run for the backend.
Editorial conclusion
printfilm is a good fit if you want the whole video pipeline in one self-hosted stack and you already pay for image and video generation through a compatible gateway, since text, image and video generation go to that gateway and the model names are configuration. Two things to check before you start it. Read the compose file rather than only the README, because the database and cache ports are published to the host and the password has a default. And decide how you will store the API key, because the project offers two places to put it and the database route encrypts it into a backup you now have to protect.
Frequently asked questions
What is the PRINTFILM platform?
A creation platform for AI comic drama and AI short video, MIT licensed and self-hostable from a public container image. It runs a script through storyboard, image generation, video generation and FFmpeg compositing, with sound produced by the video model in AI video mode or by external TTS in static-image mode.
How do I run PRINTFILM without a GPU?
You do not run generation locally at all. Text, image and video all go to an OpenAI-compatible gateway, with the model names set as configuration in the admin backend. With no key at all you can still explore the interface by enabling the mock flag.
What are PRINTFILM's system requirements?
Docker Desktop or Docker Engine with Compose. The stack is Python 3.12 with FastAPI, SQLAlchemy, PostgreSQL and Redis on the back, React 19 with TypeScript and Vite 8 on the front, and a Tailwind plus component-library admin console. There is also a source build as three local processes plus middleware containers.
Does PRINTFILM need a separate job queue worker?
No. The task platform runs in-process as a scheduler, an executor and a poller, and the file states that no separate worker is required. The trade is that generation work shares the API process, so a long job can affect request latency.
How do I become an administrator on PRINTFILM?
Register normally with the email you want, add that address to the admin bootstrap email variable in the environment file, and recreate the API container. The file stresses that this promotes privileges only and does not create an account, and that the repository ships no demo account at all.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yi1108-printfilm)Star history chart for your README
[](https://hysenlabs.com/projects/yi1108-printfilm)Was this useful?