Goldmark v2 made the AST remember the syntax you typed
:trophy: The Golden Swiss Army Knife for markdown processing. 100% CommonMark compliant, AST w/ CST, Extensible, Fast, CJK-friendly.
At a glance
- What is it?
- goldmark is a Go library for parsing Markdown into a CommonMark compliant tree, and its v2 branch rebuilt that tree around semantics and source positions instead of raw HTML conversion. The trade is a major version break that third-party extensions have not all absorbed yet, plus a migration path that runs through agent skills rather than a written guide.
- Who is it for?
- goldmark fits Go programs that need to read, transform, or write Markdown rather than merely convert it: a CommonMark 0.31.2 tree, syntax-preserving nodes, start positions on every node, and no dependencies outside the standard library. It fits badly if your pipeline runs on extensions that have not been ported, because v2 is still early and the extension ecosystem is the lagging half.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
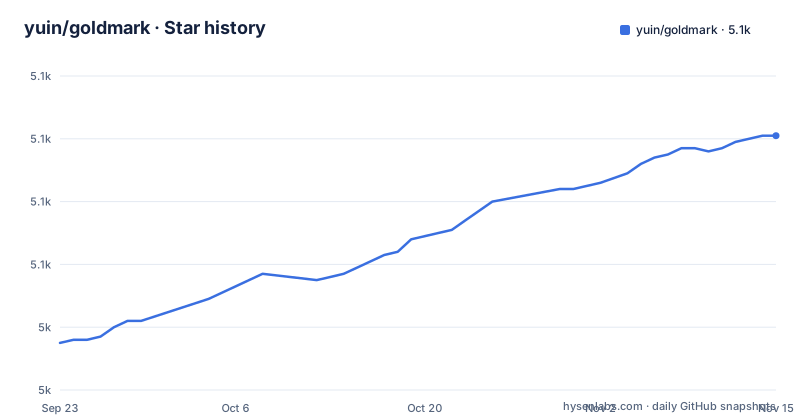
- yuin/goldmark5,101 ★ · +66
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| yuin/goldmark | 5k | 5.1k |
66 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
v2 lives on its own branch and its own module path
Two facts decide your first line of code: the import path and the branch. The module is github.com/yuin/goldmark/v2, go.mod declares `go 1.25`, and the default branch is `v2`, so a v2 checkout is the ordinary one:
$ go get github.com/yuin/goldmark/v2The author is direct about where that leaves you: v2 is still in the early stages of release, and if you depend on an extension that does not support v2 the instruction is to stay on v1. That is the price of the major version. v1 avoided breaking changes for years precisely so third-party extensions kept working, and v2 reverses that decision after seven years of accumulated debt and a Go language that gained generics along the way. The releases show the current pace, with v2.1.13 on 2026-10-31, v2.1.14 on 2026-11-02, and v2.1.15 on 2026-11-02, and the last push landed on 2026-11-02.
Every node keeps the syntax that produced it
This is the feature that changes what a parsed document can still tell you afterwards. goldmark keeps the original source information for each node, so the tree remembers whether a heading was written as ATX or as Setext, whether a link was wrapped in angle brackets as `<http://example.com>`, and whether an ampersand arrived as `you & me` or as the entity `you & me`. Other markdown libraries keep only the decoded value and cannot distinguish those cases at all. In v2 every node also holds its start position, and extensions are expected to do the same, which is what makes position-aware consumers such as LSP servers possible on top of the library. The practical payoff is round-tripping: a document can be written back to Markdown without discarding the syntax choices you made. The corresponding cost is that your tests have to assert on nodes and their attributes rather than on one normalized string.
Parser and renderer are two objects you wire yourself
Parsing and rendering are separate, and the example wires them by hand:
import (
    "bytes"
    "github.com/yuin/goldmark/v2/parser"
    "github.com/yuin/goldmark/v2/renderer/html"
)

source := []byte("こんにちは、 **世界** 。")

var buf bytes.Buffer
p := parser.New()
r := html.New()

doc := p.Parse(source)
if err := r.Render(&buf, source, doc); err != nil {
    panic(err)
}
if "<p>こんにちは、 <strong>世界</strong> 。</p>\n" != buf.String() {
    panic("unexpected output:" + buf.String())
}
The render call takes the source bytes as well as the tree, which is how the renderer recovers the original text for the nodes that need it. v2 goes one step further and lets you build a document in code: `ast.N` with `ast.NewDocument`, `ast.NewParagraph`, and `ast.NewEmphasis`, attributes attached through `SetAttribute` with `text.NewMultiLineValue`, and a render call of `r.Render(&buf, nil, doc)` where a nil source is legal because nothing was parsed. Reading a tree by query is a separate project, goldmark-astquery.
The built-in extension set stops at tables and task lists
What ships in the box includes common extensions like tables, strikethrough, task lists, and definition lists, under the `extension/` directory. The worked example in the documentation is an `@username` mention syntax, and the extension surface it needs is the whole one: your own AST nodes, a parser for block-level elements, a parser for inline-level elements, a transformer for paragraphs, a transformer for the whole AST structure, and a renderer. Six touch points, and an extension that needs one of them still has to fit the design decisions of all six. Because parsing and rendering are separate, a transformer can rewrite the tree before the renderer ever sees it, and that is the intended home for both the paragraph-level and the document-level transformer. Node start positions are part of the v2 contract, so an extension written against v1 assumptions about where a node begins will not port unchanged.
Migration to v2 runs through two agent skills
The documented migration path is not a checklist of API renames. It is a plugin and a pair of skills, aimed at Claude Code and Copilot CLI:
/plugin marketplace add yuin/goldmark@v2
/plugin install migrate-goldmark-v1-to-v2@yuin-goldmark-v2
Then choose by what you own. Extension projects run `/migrate-goldmark-v1-to-v2:migrate-goldmark-extension-v1-to-v2`, and applications that only use goldmark run `/migrate-goldmark-v1-to-v2:migrate-goldmark-app-v1-to-v2`. Each writes a migration plan and then executes that plan, and the implementations live in the `.agent-plugins` directory with `.claude-plugin` beside it, which is why those two directories are in the repository tree at all. What the tooling cannot decide for you is whether your rendered output changes. The core parsing algorithm is the same as in v1, so the grammar does not move, and the bulk of the breakage sits in the API surface, in the parser and renderer split, and in extensions that have not been ported.
The Makefile is where the compliance claim gets checked
Conformance and fuzzing are verifiable in the repository rather than taken on faith. The test target first runs the parser package with `-tags=goldmark_v1_attribute`, which keeps v1 attribute behaviour under test, then runs the module with a coverage profile and a coverpkg list naming nine packages, among them ast, extension, extension/ast, renderer/html, text, and util. Fuzzing has its own target, `cd ./fuzz && go test -fuzz=FuzzDefault`, with the fuzz corpus in the `fuzz/` directory. Linting runs `golangci-lint run -c .golangci.yml ./...`, then a `gopls check -severity hint` pass over every Go file that lacks a `Code generated ... DO NOT EDIT` header, and it fails when that pass reports anything. Benchmarks live separately: `cd _benchmark/cmark && go run goldmark_benchmark.go 500 _data.md cpu.pprof` compares against cmark. The fixtures sit in `testdata/`, with `commonmark_test.go` and `cjk_test.go` at the top level.
CJK text is a test case, not a footnote
The claim worth testing yourself is CJK handling, because the specification being implemented was not written with those languages in mind. The project states that CommonMark is primarily designed around Western languages and that many implementations assume English text, and it names its own reason for caring: the author is Japanese. The usage example is also the demonstration, since the source is `こんにちは、 **世界** 。` and the expected output is `<p>こんにちは、 <strong>世界</strong> 。</p>` followed by a newline, with the spaces around the emphasis preserved rather than trimmed. Full-width punctuation sits right next to those spaces, so a parser that normalizes whitespace there corrupts Japanese sentences in a way that reads downstream as a stray character or a broken emphasis span. `cjk_test.go` at the repository root is the guard for it, and the compliance target is CommonMark 0.31.2. There is also a browser playground for v2, built with WASM and sized at 5 to 10 MB.
Where goldmark stops and what it leaves to you
Four limits are worth stating before you commit. First, the semantic AST is the reversal of an explicit v1 choice: the original motivation lists performance first and says the goal was to prioritize performance over a semantically perfect AST, with the focus on converting to HTML. Second, goldmark is documented as a library: its usage examples are Go API calls. Third, the library depends only on the standard library, which keeps vendoring trivial and transitive upgrades irrelevant, and also means there is no helper layer to reach for. Fourth, the maintenance policy keeps bug fixes, including security fixes, for up to one major version prior to the latest major version. A Rust implementation, rushdown, exists for non-Go builds.
Editorial conclusion
goldmark fits Go programs that need to read, transform, or write Markdown rather than merely convert it: a CommonMark 0.31.2 tree, syntax-preserving nodes, start positions on every node, and no dependencies outside the standard library. It fits badly if your pipeline runs on extensions that have not been ported, because v2 is still early and the extension ecosystem is the lagging half. Before switching, check whether the extensions you depend on support v2, read the maintenance policy (fixes are maintained up to one major version prior to the latest), and run the fuzz target on your own documents, since the grammar is unchanged and the API is not.
Frequently asked questions
What is goldmark?
It is a Go library for Markdown processing that is compliant with CommonMark 0.31.2. It builds an AST, keeps the original source information per node as a concrete syntax tree, ships extensions for tables, strikethrough, task lists, and definition lists, and depends only on the standard library.
Is goldmark v2 ready to depend on?
The README says v2 is still in the early stages of release, and tells you to use v1 if you rely on an extension that does not support v2. The module path is github.com/yuin/goldmark/v2, go.mod requires Go 1.25, and the default branch is v2.
How do I migrate goldmark code from v1 to v2?
Add the marketplace with /plugin marketplace add yuin/goldmark@v2, install the plugin with /plugin install migrate-goldmark-v1-to-v2@yuin-goldmark-v2, then run the extension skill or the app skill. Those skills write a migration plan and execute it, and their implementation sits in the .agent-plugins directory.
Does goldmark keep the difference between `you & me` and `you & me`?
Yes. Because goldmark keeps the original source information for each node, it distinguishes the raw ampersand from the entity, along with whether a heading used ATX or Setext and whether a link was enclosed in angle brackets. Other markdown libraries keep only the decoded value and cannot.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yuin-goldmark)Star history chart for your README
[](https://hysenlabs.com/projects/yuin-goldmark)Was this useful?