LocalAI: A Containerized Multi-Model Engine That Needs No GPU
LocalAI is the open-source AI engine. Run any model - LLMs, vision, voice, image, video - on any hardware. No GPU required.
At a glance
- What is it?
- LocalAI wraps llama.cpp, whisper.cpp, and other engines behind an OpenAI-compatible API, pulling backends on demand. It targets teams that want local inference without a GPU, but its breadth comes with operational trade-offs.
- Who is it for?
- Adopt LocalAI if you need a single local API for multiple model types, especially on CPU-only or mixed-vendor hardware, and you value per-backend images that keep disk usage low. Skip it if you want a minimal single-model server or a tightly integrated ecosystem like Ollama or vLLM.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
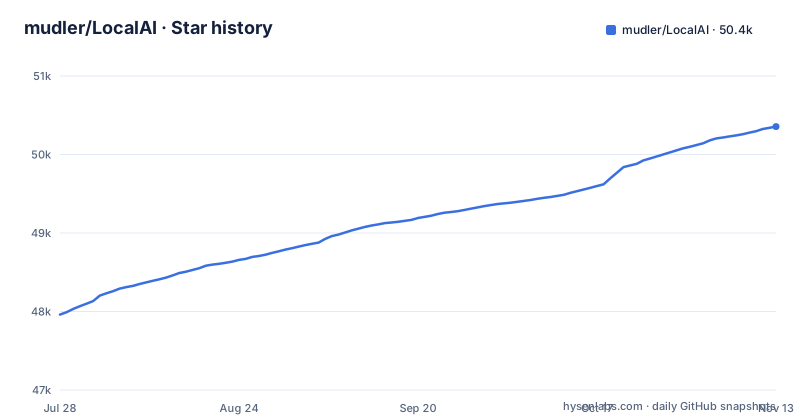
- mudler/LocalAI50,356 ★ · +2,396
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| mudler/LocalAI | 48k | 50.4k |
2,396 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What LocalAI Actually Solves
The README emphasizes privacy-first operation, with data never leaving your infrastructure. That is a strong draw for teams handling sensitive data, but it is not unique to LocalAI. The real differentiator is the breadth of backends and the on-demand image loading, which keeps the initial install small. Who it is for: developers who want local AI without a GPU, who need more than just text generation, and who are comfortable with Docker and command-line workflows.
How the Backend-on-Demand Architecture Works
The composability also extends to custom backends. The README states you can build your own backend in any language against an open interface. That is an important extensibility point for teams with specialized models that do not fit existing engines.
Getting Running: Docker Images and the local-ai CLI
The README gives a two-terminal example: one runs local-ai run llama-3.2-1b-instruct:q4_k_m, the other runs local-ai chat --model llama-3.2-1b-instruct:q4_k_m. That is a simple way to test a chat model without writing any code. For macOS, there is a DMG, but it is not signed by Apple, and the README includes a command to remove the quarantine attribute. That is a real friction point for macOS users, though it is a common issue with open-source apps.
Model Loading Sources and the Gallery
LocalAI does not force you to use its own model registry. The README lists several loading methods. The model gallery is the primary source, with a web interface at models.localai.io and a CLI command local-ai models list to see available models. The example llama-3.2-1b-instruct:q4_k_m shows a naming convention that includes the model and quantization. You can also load directly from Hugging Face with a huggingface:// URI, from the Ollama registry with ollama://, from a remote YAML config, or from any OCI registry. This is a pragmatic approach. It avoids vendor lock-in and lets you reuse models you already have. However, it also means the quality and consistency of model definitions depend on the source. A YAML config from a gist might not be maintained. For a team that needs a specific model, the first step should be checking the gallery, not assuming it exists.
Multi-User Auth, Agents, and Voice: Features Beyond Inference
The README lists several features that go beyond simple inference. API key auth, user quotas, and role-based access are built in. That makes LocalAI suitable for multi-user deployments, which is not common among lightweight local inference servers. There is also a built-in terminal agent that can answer questions, read files, and run commands on your machine, with a confirmation step for state-changing actions. That agent is invoked via local-ai chat. The agent supports commands like /models to list installed models and /model to switch models. The README also lists chats with saved agents that use tools, MCP, skills and files, plus triggers and a Telegram connector. Its guided tour has videos on user and auth, per-user usage metrics, fine-tuning and quantization, and WebRTC, and the 4.11.0 news item mentions audio scenes with transcription, speaker labels and sound detection.
Where LocalAI Falls Short: A Genuine Limitation
The most obvious limitation is that LocalAI is not a single binary. It is a collection of backend images that are pulled on demand. That means the first request for a new model type can be slow, and it requires network access at runtime. In an air-gapped environment, you would need to pre-pull all the backend images you might use. Another limitation is the macOS DMG signing issue, which is a real hurdle for less technical users. The README points to the full documentation at localai.io for deeper details such as configuration, so a team that needs quotas or role-based access should expect to read it.
Alternatives and How They Differ
The most direct alternative is Ollama. Ollama also runs local LLMs and supports GGUF models, and it has a similar one-command model pull. The key difference is that Ollama focuses almost exclusively on LLMs, not vision, voice, image, or video. Ollama has a simpler CLI and a built-in REST API, but it does not offer the same backend-on-demand architecture. Ollama's server is a single binary, not a collection of images. That makes Ollama easier to install and manage, but it also means you cannot isolate backends as cleanly. Another alternative is vLLM, which is a high-performance inference server for LLMs and is optimized for throughput on GPUs. The README lists vLLM among the engines LocalAI can wrap as a backend. If you need production-grade LLM serving on GPUs, vLLM is a better fit. For CPU-only, llama.cpp itself is the underlying engine, and you can run it directly, but you would lose the API compatibility layer and the multi-model management. LocalAI's value is the unification, not the raw performance.
Maintenance and Upgrade Costs
LocalAI is actively developed. The repository shows a last push on 2026-11-02, with releases v4.12.1 (2026-10-23), v4.12.0 (2026-10-22) and v4.11.0 (2026-10-02). That suggests a fast release cadence, which is good for features but also means you need to track releases for security updates and bug fixes. The README mentions the project is maintained by the LocalAI team, and the license is MIT, which is permissive and allows commercial use without copyleft obligations. The README links Discord for community support. For Docker users, pulling the latest image is straightforward, but for custom backends or config, you need to check for breaking changes. The README notes that the DMG is not signed, which is a maintenance issue for macOS distribution. Overall, the maintenance cost is moderate: you need to stay current with releases, manage backend image pulls, and handle the occasional breaking change that comes with a fast-moving project.
Editorial conclusion
Adopt LocalAI if you need a single local API for multiple model types, especially on CPU-only or mixed-vendor hardware, and you value per-backend images that keep disk usage low. Skip it if you want a minimal single-model server or a tightly integrated ecosystem like Ollama or vLLM. Before committing, verify that the specific models you need are available in the gallery, confirm your hardware's backend support (especially for AMD or Intel GPUs), and test the OpenAI compatibility layer against your existing client code, since not every endpoint may match exactly.
Frequently asked questions
How do I install LocalAI?
The quickstart offers a macOS disk image from the releases page and container images for CPU only, NVIDIA with CUDA 12 and 13, NVIDIA Jetson ARM64, AMD ROCm, Intel oneAPI, and Vulkan. The CPU command is `docker run -ti --name local-ai -p 8080:8080 localai/localai:latest`, and an existing container is restarted with `docker start -i local-ai`.
how to use localai
Run a model with `local-ai run`, naming one from the model gallery, or using a huggingface URI, an ollama URI, a YAML configuration URL, or an oci reference. A built-in terminal agent can be started from a second shell with `local-ai chat --model <name>`, where a slash command lists installed models and another switches between them.
how to install localai on windows
The quickstart does not give a Windows instruction. It covers a macOS disk image and container images, naming Docker, podman, and similar runtimes, and it notes that the macOS image is not signed by Apple and needs its quarantine attribute removed after install.
Is local AI as good as ChatGPT?
The repository makes no such comparison. It states that the API is drop-in compatible with the OpenAI, Anthropic, and ElevenLabs APIs across every backend, and that language, vision, voice, image, and video models can run on any hardware with no GPU required.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mudler-localai)Star history chart for your README
[](https://hysenlabs.com/projects/mudler-localai)Was this useful?