Windrecorder claims fully local operation and requires the OpenAI client to install
Windrecorder is a memory search app by records everything on your screen in small size, to let you rewind what you have seen, query through OCR text or image description, and get activity statistics, like Microsoft's Windows Recall or Rewind.
At a glance
- What is it?
- A Windows screen memory app that records the screen, indexes OCR text and serves a local search interface, where the headline claim is that everything runs locally with no upload, and the required dependency list opens with an OpenAI client.
- Who is it for?
- Windrecorder suits a single Windows user on 64-bit hardware who wants their own screen history searchable offline and is prepared to own the setup, including an ffmpeg install into a shared system directory and a clone that updates itself through git. Check five things first.
- Can I use it commercially?
- Yes, with conditions. GPL-2.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 51 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
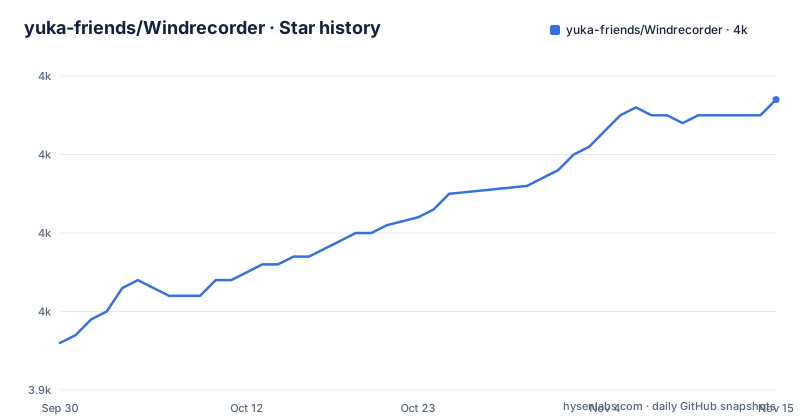
- yuka-friends/Windrecorder3,977 ★ · +31
| Repository | 2026-09-30 | 2026-11-15 |
|---|---|---|
| yuka-friends/Windrecorder | 3.9k | 4k |
31 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The local-only claim sits next to a required OpenAI client
The pitch is unambiguous. All capabilities run completely locally, without the need for an Internet connection or uploading any data, and the line ends by saying you should own all your data. Against that, the required dependency list in pyproject.toml opens with openai, pinned to a range from 1.40.8 up to but not including 2. It is not an optional group and not an extension. The optional-dependencies table below it has three entries, rapidocr, wechat and embedding, and none of them is the OpenAI client. The AI features the README does describe are opt in: tags summarisation using AI, and an agent you can use to search your records, with a how-to linked for that. So the honest reading is narrow. Your recordings, your OCR text and your database stay on the machine, which is what the claim is about, while the HTTP client for somebody else's model service is installed on every machine that installs this, whether the owner ever turns the feature on or not. The file does not draw that distinction, and a reader auditing dependencies rather than prose will find the two statements sitting next to each other.
Four OCR engines are named and only two have declared extras
The feature list names four recognition paths. The first is not a third party engine at all but the operating system's own, and the wording is careful, saying that in addition to Windows' built-in recognition capabilities the app supports others. The three that are named are Rapid OCR, described as the onnxruntime build of Paddle OCR, WeChat OCR, described as having extremely high Chinese and English accuracy, and Tesseract, described as supporting more than 100 languages and able to recognise several at once. The manifest declares extras for two of them. The rapidocr extra pins rapidocr-onnxruntime to exactly 1.4.4 with an equality operator, and the wechat extra pins wechat-ocr to exactly 0.0.3. Tesseract has no entry, which is consistent with it being an external program rather than a Python package, but the file offers no installation route for it while offering a documented route for the other two, and a link to contribute a custom engine sits in the extension directory beside the OCR list. One more detail is easy to miss: onnxruntime is a base dependency at a narrow range even though the engines that need it are optional, so the ONNX runtime is installed on every machine regardless of which engine is chosen.
Image embedding is documented as a directory and as an optional dependency
The same feature has two installation mechanisms, and the file does not reconcile them. The How it works section ends with a note that image embedding is provided as an extension and can be installed under the directory extension/install_img_embedding_module. The manifest has an optional-dependencies group called embedding, which pins uform with the onnx extra to exactly 3.1.3 and adds onnxruntime and huggingface-hub, and it carries a comment above it that reads: keep the existing uform3 model and ONNX backend, no embedding or index migration. That comment is doing real work, since it is a standing instruction not to swap the model or the vector backend, which means the search index format is tied to the model that produced it. The idle maintenance description also lists image recognition embedding as one of the tasks performed when the machine goes quiet, which is a third mention in a different register. A new user therefore has three statements about one optional capability and no single place that says which one to follow, and the practical question, whether the vector index survives an update, is answered only by that comment.
Both recording modes quantise at fifteen minutes, for different reasons
There are two modes and the difference between them is a lag. Automatic Flexible Screenshots takes a screenshot every three seconds by default, indexes a frame when its content or text changes, and every fifteen minutes converts the accumulated screenshots into video. That mode is described as consuming low system resources. Direct Video Recording via FFmpeg records in fifteen-minute segments and indexes the clips only after each segment finishes recording, and the file states the consequence plainly: there may be a fifteen-minute delay in data querying. That mode consumes moderate resources and is described as giving smooth and complete recording. So the two modes share a fifteen-minute quantum for opposite purposes. In the screenshot mode it is the assembly cadence, and search stays current. In the direct mode it is the recording chunk, and search trails the last fifteen minutes. Recording pauses by itself in three situations: when the screen stays static, when the window title, process name, included text or screen still time match a custom skip condition, and when the machine reaches the lock screen, with idle maintenance running until the user comes back.
The size table promises two columns and the two rows disagree
The sizing table at the end of the file has a header row and two data rows, and it is the weakest part of the documentation. The header names two columns, video recording size and SQlite database size, and the capitalisation of the second is wrong. The database column is empty in both rows, so the comparison the table exists to make is never made. The first cell contains a stray escape sequence in the middle of the phrase about screen change and number of monitors, so those two words run together in the rendered text. The numbers themselves are the real problem. The per hour figure is given as 2 to 100 Mb, depending on screen change and monitor count, a fifty-fold range. The per month figure is given as 10 to 20 Gb, which over a thirty day month works out to roughly 14 to 28 Mb an hour, a slice of the middle of the hourly range rather than its extremes. A reader sizing a partition from the monthly row and a reader sizing one from the hourly row will disagree by a factor of three. The same cell adds that different compression presets can bring the data to between 0.1 and 0.7 times the size, another tenfold range with no preset named.
ffmpeg is installed by unpacking a rolling build into the system directory
The first installation step is the one with the widest blast radius. It asks you to download ffmpeg, names the exact file as ffmpeg-master-latest-win64-gpl-shared.zip, and then says to extract all files in the bin directory, excluding the bin directory itself, into C:\Windows\System32, or into another directory already on PATH. Three things follow from that instruction. The system directory is shared by every program on the machine and every user account, so whatever is placed there becomes what everyone resolves. The archive is the shared build, so the extraction brings dynamic libraries into that directory alongside the two executables, which is more surface than copying a single binary. And the file name is a rolling tag, master-latest, not a version, so the ffmpeg that gets installed is whatever that build published on the day the user clicked. The alternative offered in the same sentence, another directory already on PATH, avoids the shared location and the privilege requirement, but it is offered as an equal alternative rather than as the safer default, and the file does not say which one the project tests against.
One version number in two blocks, and a shim that declares its own expiry
The manifest carries the project name and the version 0.1.0 twice, once under the project table and once under a Poetry table further down, and the second one sits under a comment that reads: discovery bridge for old Poetry launchers during their first upgrade only, with a second line saying all dependencies and installation are managed by the project table and uv.lock. So the file contains a shim that states it is temporary, and the shim is still there, holding a duplicate copy of three fields that have to be kept in step by hand. Alongside it, three separate statements describe the Python version. The project table requires a version at or above 3.11 and below 3.13, the README says uv manages Python 3.12 automatically, and a .python-version file sits at the root. A machine on 3.11 satisfies the constraint and contradicts the prose. The tooling is pinned too: uv itself is required at 0.12.18 or newer, the project is marked as not being a distributable package, and the environment list for resolving the lock file is a single entry requiring win32 and the AMD64 machine type.
Install, update and environment repair are the same batch file
install_update.bat is the whole lifecycle. It installs and configures the app on first run, it is what you reopen after a failed automatic update, and it is what you run again to rebuild the virtual environment after moving the install, where the instruction is to delete .venv in the directory and move it. The update itself is a git operation, and the recovery note names the exact command, run from a cmd prompt in the project root:
git pull --ff-onlyA further document is linked for when Git reports a conflict. Conflicts are a natural consequence of the design rather than an accident, because the git working tree is also where the data lives: video, database and statistics are all kept in a userdata directory under the install, and the virtual environment sits beside them. Moving the app is therefore a copy of a directory that contains both versioned source and unversioned state. Alongside this, the file's own language mix is worth noting for an English reader. The English README links to itself as the English version and to a Chinese document stored under the assets directory, and the one link explaining how to search records with an AI agent is marked as being in Simplified Chinese.
Editorial conclusion
Windrecorder suits a single Windows user on 64-bit hardware who wants their own screen history searchable offline and is prepared to own the setup, including an ffmpeg install into a shared system directory and a clone that updates itself through git. Check five things first. The supported environment is declared as 64-bit Windows only, so anything else is out. The version is 0.1.0 with no tagged release, so there is no artifact to install and updates come from a pull. The four OCR engines are not equally supported, since only two have declared extras. The image embedding feature is documented as a directory to install and also as an optional dependency group, so pick one route. And the local-only claim is about where your data goes, not about what gets installed, since an OpenAI client is a required dependency whether or not you use the AI features.
Frequently asked questions
What is Windrecorder?
A Windows screen recording and memory search application written in Python and released under the GPL-2.0 license. It records screens or the active window, indexes OCR text, page titles and browser URLs, and serves a local web interface for search, activity statistics, word clouds and timelines.
What are the two Windrecorder recording modes?
Automatic Flexible Screenshots, which captures a frame every three seconds by default, indexes on change and converts past screenshots into video every fifteen minutes; and Direct Video Recording via FFmpeg, which records in fifteen-minute segments and indexes them afterwards, so a query can lag the last fifteen minutes.
How do you install Windrecorder on Windows?
Install ffmpeg, Git and uv, then clone the repository with git clone https://github.com/yuka-friends/Windrecorder and run install_update.bat in the resulting directory. uv manages Python 3.12 automatically, so a separate Python installation is not required.
Which OCR engines does Windrecorder support?
Windows' own built-in recognition, plus Rapid OCR, WeChat OCR and Tesseract. The manifest declares optional dependency groups for rapidocr and wechat with exact pins, while onnxruntime is a base dependency rather than an extra, and Tesseract has no declared group.
Which platforms does Windrecorder support?
64-bit Windows. The manifest restricts lock file resolution to sys_platform equal to win32 together with platform_machine equal to AMD64. It also declares a Python range of 3.11 up to but not including 3.13, while the README says uv manages Python 3.12.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yuka-friends-windrecorder)Star history chart for your README
[](https://hysenlabs.com/projects/yuka-friends-windrecorder)Was this useful?