The 21 rules in yzhao062/agent-style, and where its own documentation breaks them
21 writing rules for AI coding and writing agents. Drop-in for Claude Code, Codex, Copilot, Cursor, and Aider, so their output reads like a tech pro.
At a glance
- What is it?
- Twenty-one English writing rules formatted for coding agents to read before they draft, shipped on PyPI and npm, with a bench whose before-and-after figure and results section report different counts for the same project.
- Who is it for?
- agent-style is worth reading as a written artifact rather than as a measurement. The rules are specific enough to act on, each canonical rule carrying a checkable citation, and the field group names failure modes no style guide covers.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
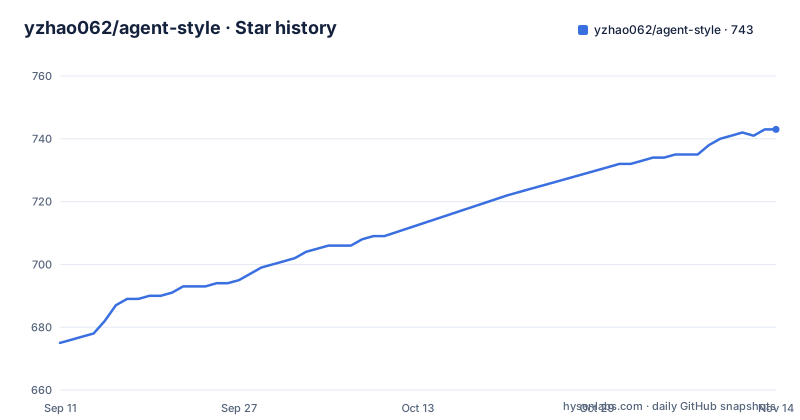
- yzhao062/agent-style743 ★ · +68
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| yzhao062/agent-style | 675 | 743 |
68 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A Python-tagged repository whose payload is English prose
The repository is tagged Python, and no Python source file sits at its top level. What it ships is English writing guidance: 21 rules an agent reads before it drafts anything. The scope table draws the boundary hard. In scope are API docs, design docs, research papers, grant proposals, READMEs, runbooks, commit messages, error messages, technical blog posts, postmortems and issue reports. Out of scope are fiction, poetry, marketing copy, long-form narrative non-fiction, and non-English prose, plus any context where rhythm or affect matter more than precision.
That last exclusion deserves a second read, because it means this is not a general writing system. A repository whose primary language is Python and whose product is a paragraph about prose is a deliberate mismatch, and the rules honour it. Every canonical rule cites an English prose authority by chapter, section or essay rule, and every field rule was logged from English model output between 2022 and 2026.
The naming follows the same logic. The head is The Elements of Agent Style, named in homage to Strunk and White's The Elements of Style (1918/1959), one of the four canonical sources behind RULE-01 through RULE-12. Both distribution channels carry the short name agent-style, one on PyPI and one on npm, so the homage lives in the documentation while the package name drops it.
The purpose is stated in a single line: a curated set of English writing rules formatted for AI coding and writing agents to follow at generation time, not as a post-hoc linter. The project also ships its own escape hatch, quoted from Orwell 1946 Rule 6: break any of these rules sooner than say anything outright barbarous. Rules are guides to clarity, not ends in themselves.
Two rule groups called peers, printed with different evidence
The README says the agent reads both groups as equal peers, with no group annotated as higher priority than the other. The two tables then disagree with that sentence.
RULE-01 through RULE-12 come from four authorities, and every row carries a citation you can check against the original work. RULE-01 traces to Pinker 2014 Ch. 3, RULE-02 to Orwell 1946 Rule 3 with S&W section II.14, RULE-06 to Orwell 1946 Rule 5 with Pinker 2014 Ch. 2, RULE-12 to S&W section II.18 with Pinker 2014 Ch. 4. That table has three columns, and the third one is the source.
RULE-A through RULE-I have two columns and no source column, because the project says so plainly. These are not literature-backed. They are patterns logged from model output across dozens of writing projects and code releases, 2022 to 2026. What they claim to add is coverage the canonical set misses, namely the failure modes that belong to how models write rather than to English itself. RULE-A forbids converting prose into bullet points unless the content is a genuine list. RULE-H requires that factual claims carry a citation or concrete evidence instead of handwaving. RULE-F forbids redefining abbreviations halfway through a document.
The formatting still ranks them. The only row in either table marked critical is RULE-H. The before-and-after panel borders two rules in red: RULE-01, the curse of knowledge, and RULE-H again. Priority therefore lives in the markup and in the figure rather than in the stated policy, and the group the project calls a peer input is the group whose one rule is declared critical.
The file that would settle the question is RULES.md, which holds the full per-rule blocks with BAD and GOOD examples, an enforcement tier and a rationale. That enforcement tier is the field where priority could be encoded instead of implied by typography.
The before-and-after figure disagrees with the scores underneath it
The before-and-after panel is a three-row build taken from real v0.3.0 bench draft pairs: the same prompt, with independent generations produced with and without the ruleset. The top row states the identity, 21 rules as 12 canonical plus 9 field-observed. The rows below it are the mechanism, and each carries a violation count.
The product description on Gemini 3 Flash moves from 8 to 0 violations. The design-doc section on Claude Opus 4.7 moves from 14 to 7. The paper related-work section on Gemini 3 Flash moves from 6 to 4. Each row shows the draft on the left with rule-violating phrases highlighted, the specific rules that fire in the middle, and the revision on the right at the same length budget, same register, same document type.
Two caveats sit inside that same paragraph, and both are the kind a project normally buries. The first is arithmetic: the figure says these are the original v0.3.0 scoring, so they do not match the corrected scores reported in the results section. A reader who screenshots the panel and then reads the percentages ends up holding two different sets of numbers for one project. The second concerns the related-work row, where the source drafts are anchored to three prompt-named benchmarks (AgentBench, BFCL, tau-bench) so the style delta stays separated from fabricated-citation noise, and where the displayed baseline snippet stops before the third name in order to keep the panel to three sentences. In other words, the panel that proves the mechanism also edits the evidence it displays.
The length budget is the one methodological control stated anywhere in the project, and it appears only here, in the figure. The ten-task bench says nothing about draft length. So the panel is the controlled comparison, and the headline percentages come from the run where no control is stated.
Ten tasks, twenty drafts, and one condition that refuses to move
The bench is small and fixed: 10 prose tasks, 2 generations per condition, flagship models drafting each one with the ruleset loaded at generation time and again without it. The task set breaks down as 2 PR descriptions, 1 design-doc section, 1 commit message, 4 paper sections, 1 product description and 1 NSF-style specific aim.
Three of the four conditions moved. Claude Opus 4.7 dropped 47 percent, from 88 violations to 47. OpenAI GPT-5.4 through Codex CLI dropped 46 percent, from 48 to 26. Gemini 3 Flash dropped 86 percent, from 65 to 9. The fourth did not move at all: GitHub Copilot CLI reported 52 to 52, and the project itself calls that number a noise control rather than a fourth treatment result. An earlier April 2026 setup reached the same wall, where copilot -p showed no measurable effect from the installed instruction file, an archived result the project scopes to the version and setup of the day.
Two null results in one project are information rather than noise to discard, and both point at the same mechanism: whether the host program reads the installed instruction file at all. The sentence that would explain it stops one clause in. Current Copilot CLI documentation describes repository instruction discovery, so it says not, and the sentence ends there with no verb to close it.
The counting method deserves the same attention as the deltas. These are raw violation totals across twenty drafts per condition, which puts the untreated Opus baseline at 4.4 violations per draft, and the text gives no per-word normalization for the bench. Violations accumulate with length, so a model that writes longer scores worse on an identical rule set. Reading the 86 percent and the 47 percent as a ranking of models claims more than the method supports. The defensible reading is narrower: two hosts honoured the rules and one did not.
Generation time, except where a review command counts the damage
The stated design point is placement. Rules applied before generation instead of after it. The argument runs that a post-hoc linter can tell you a sentence is bad, while a ruleset loaded at generation time stops the bad sentence from being written at all.
The project then measures its own effect with the kind of command the positioning disclaims. The related-work figure says the style delta is measured by agent-style review, which is a scorer that reads a finished draft and counts violations in it. That is a linter by function, whatever the packaging intent. Both halves ship in one repository. The top level carries an enforcement directory, a packages directory, a scripts directory, plus skills and agents directories that the README never introduces.
RULES.md is where the boundary should be drawn, because each rule block there records an enforcement tier. A tier is exactly the mechanism that separates guidance from enforcement, and it is also the field in which the peer-equality claim could be resolved honestly rather than by table formatting.
Two practical consequences follow. If you want the rules in an agent's context, you are pasting prose into whatever file the host already reads, and whether that read happens is a property of the host rather than of this package. The four hosts are not equivalent on the evidence, since one condition moved and one did not, and a no-change result cannot be separated from the rules never having been loaded. If you want CI enforcement instead, you are depending on a review command whose tier behaviour is defined in a file the README does not reproduce. The adapter matrix at the repository root is the file that maps hosts to mechanisms, and the tree lists it without explaining it.
The longest sentence in the README breaks RULE-12 and RULE-B
RULE-12 tells agents to split sentences over 30 words. The paragraph that explains the panel is a single sentence of roughly 190 words, running from the identity row through three rows of counts and two nested caveats without one full stop. It also leans on em dash characters as casual sentence punctuation, which is the exact behaviour RULE-B prohibits, and it stacks several qualifying connectors where RULE-D asks for restraint on transition words.
The irony is load-bearing rather than decorative, because the README text is what an adapter ships. A ruleset whose own panel paragraph models the habits RULE-12 and RULE-B exist to remove hands the model a counterexample that sits in its context window right beside the rules.
Elsewhere the document does what it asks. The scope table is a genuine list in two columns across four rows, which is the case RULE-A describes, with no over-bulleting where a sentence would have carried it. The rule tables are real tables rather than prose pretending to be one. RULE-H states its trigger in a single clause: support the claim or do not make it. RULE-I, preferring full forms over contractions in formal technical prose, shows through in the document's own habit of writing it is rather than it's. The Orwell escape hatch covers the cases where obeying a rule would otherwise produce something worse than the violation.
One collision is worth naming for anyone writing tooling against these rules. RULE-F demands consistent terms, while the two groups use two different numbering schemes, RULE-01 through RULE-12 and RULE-A through RULE-I, that a consumer has to hold in mind at once.
Three releases in three days, then six weeks of commits
The release history is compressed. v0.4.0 was published on 2026-08-12, v0.4.1 on 2026-08-13 and v0.4.2 on 2026-08-14, three tags on three consecutive days. The default branch was last pushed on 2026-09-27, about six weeks after the newest tag. The repository is not marked archived, and it carries 702 stars, 37 forks and 3 open issues.
That gap is the operational fact for anyone pinning a version. The tags cluster inside a single week and the branch keeps moving afterwards, so a pin at v0.4.2 sits roughly six weeks behind the working tree, and the difference between the two is not accounted for anywhere in the README. The root holds the files that would account for it: CHANGELOG.md and RELEASING.md for the release mechanics, TODO.md sitting next to a separate todo/ directory, and SOURCES.md, NOTICE.md, RULES.md and adapter-matrix.md beside them. A .markdownlint-cli2.jsonc config sits at the root as well, which is a second opinion worth noting. This repository checks its own Markdown with markdownlint, a different rulebook from the 21 rules it sells.
The last thing to know is where the README stops. Its table of contents links four anchors, and the fourth, Use, has no section in the file on the default branch. The prose ends inside the results discussion, one clause into a sentence about what current Copilot CLI documentation says about repository instruction discovery. The install and adapter instructions that the contents promise are therefore not in the document, which means anyone evaluating this project has to go to the root files to learn how the package is meant to be consumed.
Editorial conclusion
agent-style is worth reading as a written artifact rather than as a measurement. The rules are specific enough to act on, each canonical rule carrying a checkable citation, and the field group names failure modes no style guide covers. Two cautions sit under any decision. First, effect depends on whether the host program reads your instruction file at all, and one of the four measured conditions produced no change, so confirm the load happened before trusting a null. Second, the before-and-after figure and the results section carry different counts, and the length control exists only in the figure, so read the percentages as a direction rather than a ranking. Check the terms yourself: the README file opens with a CC-BY-4.0 SPDX header and the tree carries a LICENSES directory, while the package metadata carries no license value at all.
Frequently asked questions
How many rules does agent-style contain and where do they come from?
Twenty-one, split into two groups. RULE-01 through RULE-12 are distilled from Strunk and White, Orwell, Pinker, and Gopen and Swan, each citing a chapter, section, or essay rule. RULE-A through RULE-I were logged from model output across writing projects and code releases between 2022 and 2026, and the project states plainly that they are not literature-backed.
Does agent-style work with Claude Code, Codex, Copilot, Cursor, and Aider?
Those five are named as drop-in targets, but the bench covered three hosts plus a control. Claude Opus 4.7 went from 88 to 47 violations, GPT-5.4 through Codex CLI from 48 to 26, Gemini 3 Flash from 65 to 9, and GitHub Copilot CLI from 52 to 52, which the project treats as a noise control rather than a treatment result.
Is agent-style a linter or a generation-time ruleset?
It is positioned as generation-time guidance rather than a post-hoc linter, yet the before-and-after figure says the style delta is measured by agent-style review, which counts violations in a finished draft. Both halves ship in the same repository, with an enforcement directory at the root and an enforcement tier recorded per rule in RULES.md.
What license does agent-style use?
The README file opens with an SPDX header reading CC-BY-4.0, and the tree carries a LICENSES directory plus NOTICE.md and SOURCES.md. The package metadata for the PyPI and npm releases named agent-style carries no license value, so both sides need checking before anything is reused.
How current is agent-style?
The default branch was last pushed on 2026-09-27 and the repository is not marked archived. The three newest tags are v0.4.0, v0.4.1 and v0.4.2, published on 2026-08-12, 2026-08-13 and 2026-08-14, which leaves the newest tag about six weeks behind the branch head.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yzhao062-agent-style)Star history chart for your README
[](https://hysenlabs.com/projects/yzhao062-agent-style)Was this useful?