DeepKE's setup.py has install_requires commented out, so pip installs no dependencies
[EMNLP 2022] An Open Toolkit for Knowledge Graph Extraction and Construction
At a glance
- What is it?
- DeepKE is an MIT licensed Python toolkit for knowledge graph extraction covering named entity recognition, relation extraction, attribute extraction and event extraction, with example directories per task and a large body of published models. Two details in its packaging contradict the rest of the repository: the dependency declaration is disabled in setup.py, and the torch pin stops at 1.11.
- Who is it for?
- DeepKE fits a research group reproducing or extending a published extraction model, who will build an environment from the requirements file themselves and read the code for the task they need. It does not fit a production pipeline assembled with pip alone, because nothing installs its dependencies and the pinned versions are old.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 125 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
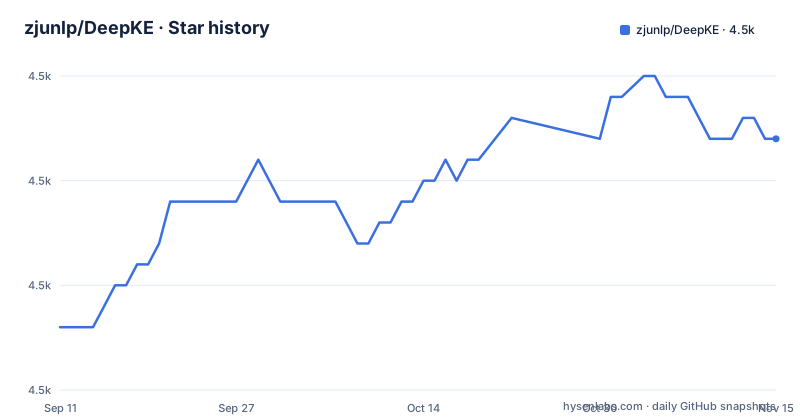
- zjunlp/DeepKE4,487 ★ · +9
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| zjunlp/DeepKE | 4.5k | 4.5k |
9 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four extraction tasks, and a directory for each
The table of contents names four functions, and the repository has a matching set of example directories:
1. Named Entity Recognition 2. Relation Extraction 3. Attribute Extraction 4. Event Extraction
The examples are laid out as `example/ae/`, `example/ee/`, `example/llm/`, `example/ner/`, `example/re/` and `example/triple/`, so the naming follows the task rather than a single framework.
Relational triple extraction has its own directory separate from relation extraction, which is a distinction worth keeping straight, since a triple extractor is given text and asked to emit subject, relation and object together, whereas relation extraction is typically given pairs that are already known to be related.
The scenarios the toolkit claims to support are listed in the description: cnSchema, low-resource, document-level and multimodal, for entity, relation and attribute extraction.
There is also a `pretrained/` directory at the root, and the README says off-the-shelf models are released under a cnSchema example path, so there are pre-trained weights to fetch rather than train from scratch.
The rest of the root is conventional: src/, docs/, docker/, mcp-tools/, MANIFEST.in, CITATION.cff, and several README variants including Chinese-language ones and separate files for tag and cnSchema usage.
The dependency declaration is commented out in setup.py
The packaging file contains two commented-out blocks, and they are the lines that decide whether `pip install deepke` works.
The first is a commented read of requirements.txt near the top of the file, and the second is `install_requires` inside the setup call, also commented.
So the installed distribution carries no dependency metadata. Pip will resolve no third-party packages, and an environment created that way will fail on its first import of torch or transformers until you install them yourself.
The rest of the setup call is unremarkable and informative about intent. The package name is `deepke`, the version is `2.2.7`, the license is MIT, the URL points at the repository, the author is ZJUNLP, and `package_dir` is set to src with packages discovered by find_packages. `platforms` is any and the classifiers are Python 3 and OS Independent.
So the package uses a src layout, and the dependency list is kept in requirements.txt rather than in setup.py.
The practical consequence is that the file that tells you what to install is requirements.txt, and nobody has connected it to the installer.
torch is pinned to 1.11 while the changelog claims newer package support
The requirements file is entirely pinned, with exact versions for almost everything, and the first line is the one that will stop you first:
torch>=1.5,<=1.11
hydra-core==1.0.6
transformers==4.26.0
numpy==1.21.0
The torch line has a lower and an upper bound, and the upper bound is 1.11.
The repository's own changelog says something different. The April 2023 entry states that new models were added and that compatibility with higher versions of Python packages, naming Transformers as an example, was offered.
Those two statements are about different things. Compatibility with newer Transformers does not widen the torch ceiling, but a reader skimming the changelog could reasonably assume the environment constraints moved with it.
The rest of the file follows the same pattern of exact pins: tensorboard 2.4.1, matplotlib 3.4.1, jieba 0.42.1, scikit-learn 0.24.1, seqeval 1.2.2, wandb 0.12.7, huggingface_hub 0.11.0, nltk 3.8, protobuf 3.20.1, datasets 2.13.2, and pyhocon 0.3.60.
There is also a long tail of tooling: ipdb for debugging, tqdm, Jinja2, ujson, opt-einsum, pytorch-crf and tensorboardX. Every one of these is a version you either accept or override by hand.
openai is pinned to the pre-1.0 client, which matters for the LLM paths
One pin deserves its own section, because DeepKE has three separate large language model directions and one of them calls a hosted API.
The requirements file pins `openai==0.28.0`.
That is the version of the client library from before the 1.0 rewrite, and it matters for anyone taking the LLM route today. The API surface changed at 1.0, so code and examples written against that pinned version will not match current documentation or current examples for the same service, and upgrading the pin is a code change rather than a version bump.
The three LLM directions are named in the news entries. DeepKE-LLM is the original, and the June 2023 entry says it was updated to support knowledge extraction with KnowLM, ChatGLM, the LLaMA series and the GPT series, with GPT-3 support and in-context learning based on EasyInstruct added in February 2023.
OneKE came later, described as an open source knowledge extraction framework supporting multi-agent knowledge extraction across various scenarios, released in December 2024, with an earlier bilingual schema-based model in April 2024 based on Chinese-Alpaca-2-13B.
And in June 2025 the project integrated MCP service tools, enabling knowledge extraction through large language models acting as tool callers for lightweight models.
So there is a hosted API path, a local model path and a tool calling path, and they have different age and different constraints.
Releases stopped in 2023 while commits continued to July 2026
There is a gap between the two histories, and it changes what version you should install.
The three most recent releases are 2.2.7 on 2023-09-21, 2.2.6 on 2023-08-05 and 2.2.4 on 2023-06-28.
The last push to the repository is dated 2026-07-13, and the setup file still declares the version as 2.2.7.
So the released artefacts are from September 2023 and the source tree is nearly three years newer, and the version number in the source has not moved either. Anything you install from a package index is therefore behind the code in the repository, and there is no way to tell from the version which side of that gap you have.
The news entries explain what the newer commits contain. July 2026 records that DeepKE was selected for a CCF open source incentive program. February 2024 released a large-scale bilingual instruction dataset for information extraction, described as 0.32B tokens, along with two models trained on it, one for baichuan2-13b and one for llama2-13b, both in a LoRA variant. September 2023 released an earlier bilingual instruction dataset for instruction based knowledge graph construction.
The datasets and models among them are linked on HuggingFace rather than shipped in a release. Take the code from the repository if you need it.
Two platform notes sit in the introduction, not in a FAQ
Practical advice is scattered through the introduction rather than collected, and two items there are worth internalising before you start.
The first is a path separator instruction: Linux is recommended, and if you use Windows you should use a double backslash in file paths. For a toolkit configured through Hydra and reading configuration from files, path separators are exactly the kind of thing that works on one platform and silently misbehaves on another.
The second is a network fallback. If HuggingFace is inaccessible, the README suggests considering `wisemodel` or `modescape`.
That note matters more than it looks, because the project's model weights and datasets are hosted on the model hub rather than in the repository. A user behind a network that cannot reach it has a documented alternative, and the pretrained models under the cnSchema path are the reason you need one.
The same introduction also points beginners at a documentation site, an online demo, a paper, slides and a poster, which is the intended reading order for someone new to the toolkit.
For problems during installation the README gives one instruction: check the Tips section, and if that does not help submit an issue promptly. The Tips heading appears in the table of contents, so there is a troubleshooting page even though the introduction does not summarise it.
The model catalogue is a list of papers with implementations attached
The supervised model path is the part of the repository that is most concrete, and its organisation is by paper.
For named entity recognition the README names LightNER, cited to COLING 2022, and W2NER, cited to AAAI 2022. For relation extraction it names KnowPrompt, cited to WWW 2022, under a few-shot example path. For relational triple extraction it names ASP from EMNLP 2022, PRGC from ACL 2021 and PURE from NAACL 2021, and it also points at a cross NER model called CP-NER from IJCAI 2023 added later.
So the reading order for a new user is stated directly: if you want to train supervised models, start with the Quick Start, where the NER, relation extraction and relational triple extraction models are grouped by task with paths for each.
Event extraction has its own standard example path and was described as covering Chinese and English.
Two entry points for the data side are also named. A README_TAG file carries annotation instructions for entity recognition and relation extraction, and there are automatic labelling paths for weakly supervised data under entity extraction and relation extraction prepare-data directories. A multi-GPU training path exists under relation extraction standard.
What none of this tells you is which of these models are current. The citations span 2021 to 2023, so a model that is a strong baseline in the paper it came from may have been overtaken since, and the toolkit's job is to make the baseline reproducible rather than to track the state of the art.
Editorial conclusion
DeepKE fits a research group reproducing or extending a published extraction model, who will build an environment from the requirements file themselves and read the code for the task they need. It does not fit a production pipeline assembled with pip alone, because nothing installs its dependencies and the pinned versions are old. Before you start, read requirements.txt and install it manually, check whether the torch ceiling of 1.11 works with your hardware and your other packages, and treat the newest tagged release, 2.2.7 from September 2023, as older than the code you get from the default branch.
Frequently asked questions
What does DeepKE do?
It is a deep learning based knowledge extraction toolkit for knowledge graph construction, supporting cnSchema, low-resource, document-level and multimodal scenarios for entity, relation and attribute extraction. It covers four functions in the documentation: named entity recognition, relation extraction, attribute extraction and event extraction, with an example directory for each.
How do I install DeepKE and its dependencies?
The requirements have to be installed by hand. In setup.py both the requirements.txt read and the install_requires entry are commented out, so a pip install of the package installs no third-party libraries. The requirements file itself pins versions tightly, starting with torch>=1.5,<=1.11 and transformers==4.26.0, so build the environment from that file before importing anything.
Which models does DeepKE ship?
Supervised models grouped by task, named after the papers they implement: LightNER and W2NER for named entity recognition, KnowPrompt for relation extraction, and ASP, PRGC and PURE for relational triple extraction, plus CP-NER for cross-domain NER. Off-the-shelf cnSchema models are also released, and there is a pretrained directory at the repository root.
Does DeepKE support large language models?
It has three separate directions. DeepKE-LLM supports extraction with KnowLM, ChatGLM, the LLaMA series and the GPT series. OneKE is an open source framework for multi-agent knowledge extraction, with an earlier bilingual model based on Chinese-Alpaca-2-13B. Since June 2025 the project has also integrated MCP service tools, letting large language models act as tool callers for lightweight models.
Which DeepKE version should I install?
Check which one you are getting, because the released artefacts and the repository have diverged. The most recent releases are 2.2.7 from 2023-09-21, 2.2.6 from 2023-08-05 and 2.2.4 from 2023-06-28, while the last commit is dated 2026-07-13 and the version in setup.py still reads 2.2.7. Anything added after September 2023 is not in a tagged release.
What are the known platform caveats for DeepKE?
Linux is recommended, and on Windows you should use a double backslash in file paths. If the model hub is inaccessible, the README suggests considering wisemodel or modescape. For installation problems it says to check the Tips section first and then submit an issue.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zjunlp-deepke)Star history chart for your README
[](https://hysenlabs.com/projects/zjunlp-deepke)Was this useful?