LightMem's manifest says Apache-2.0, its repository says MIT, and its Python ceiling is 3.11
[ICLR 2026] LightMem: Lightweight and Efficient Memory-Augmented Generation
At a glance
- What is it?
- A memory-augmented generation framework published at ICLR 2026 that now hosts four separate memory papers, forty-seven exactly pinned dependencies including a vector database client and a graph library, and two baseline evaluation frameworks announced four months apart. The readme promises a few lines of code; the shipped examples are four run scripts.
- Who is it for?
- Read this as a research group's released work rather than as a library you will install and depend on. That reading is forced by three facts in the packaging: the licence is stated two different ways, the interpreter range stops before the current one, and every dependency is frozen at an exact version including most of its own transitive closure.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 9 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
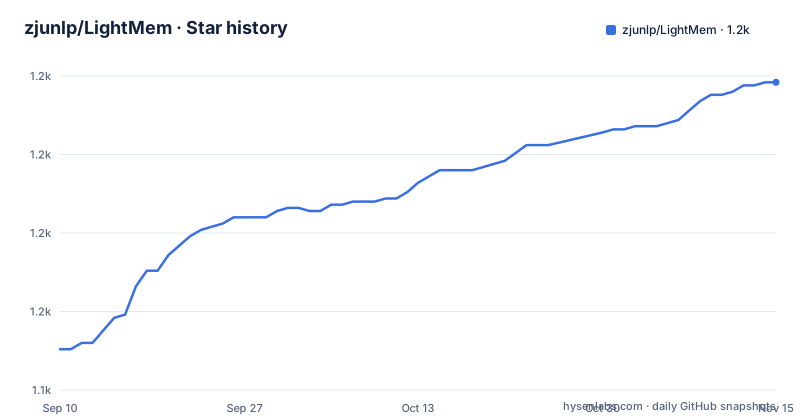
- zjunlp/LightMem1,223 ★ · +85
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| zjunlp/LightMem | 1.1k | 1.2k |
85 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two files state two different licences
The project is recorded under an MIT licence, and the readme's licence badge links to a licence file at the root.
The package manifest says something different. It declares the licence inline as Apache-2.0, as text rather than as a file reference.
So the two authoritative-looking sources disagree, and neither points at the other. One is a metadata field GitHub reads and displays; the other is a field the build backend reads when it generates distribution metadata.
The practical consequence is that which licence you get depends on where you look. A reader who checks the repository page sees MIT. A distributor who reads the built package metadata sees Apache-2.0. An organisation with a licence allowlist will get a different answer depending on which artifact they scan.
This is not worth guessing at from the outside, and this write-up does not pick one. The fix is one line in either file, pointing at the other, and it is worth raising as an issue before anyone builds on the package.
The same manifest is otherwise careful: the description field, the keywords, the intended-audience and development-status classifiers are all filled in, and the status is declared as alpha, which is a more honest label than the publication record might suggest.
The interpreter range stops two versions ago
The manifest requires a Python version above three ten and below three twelve.
The classifiers agree with the floor and list only three ten and three eleven. So the ceiling is deliberate rather than an oversight, and the project has decided its two supported interpreters.
The problem is which two. An upper bound of below three twelve means the package will refuse to install on anything newer, and the refusal will come from the resolver rather than from a clear message about interpreter support. On a machine with a current interpreter, the first thing a user hits is a failed install with a constraint error naming this requirement.
An upper bound is sometimes the right call, particularly when a pinned dependency set makes a newer interpreter genuinely untested. And this project has pinned every dependency, so the odds are good that something in the list does not have a working build for the current interpreter.
Which makes it a documented limitation rather than a bug. The readme does not mention it anywhere, though, and for a project whose selling point is broad compatibility across hosted and local models, the interpreter floor is worth stating in the first paragraph rather than in a manifest field.
Forty-seven exact pins, including the whole transitive closure
The dependency list has a comment above it saying the versions are complete and exact, for reproducibility.
Both halves of that are visible in the list itself. Complete: the entries go well past what a project would import directly, down to the low-level pieces of the HTTP stack, the charset detector, the internationalised domain library, the templating engine's escape helper, the type-inspection helpers, and the arithmetic library that a symbolic maths package needs.
Exact: every entry carries an equality sign and a full version number, down to a patch release of the templating engine's escape helper and a build number for the regular expression library.
Freezing a transitive closure does buy one thing, and it buys it well: two people installing on the same day get the same code, which is exactly what a paper reproduction needs.
It also means the list ages in a specific way. When one of those packages publishes a security fix, or a companion release that requires it, the install fails to resolve rather than quietly picking up the fix. Three of the pinned entries are dated by release day rather than by sequence, so they age visibly in a way the others do not.
The conventional split would keep exact pins for the handful of packages the results depend on and leave floors on everything else. As written, there is no second tier.
A vector store, a graph library and a compression library, all required
The feature list describes a framework built around a minimalist design with minimal resource consumption and fast response times, a simple API integrated in a few lines of code, a modular architecture supporting custom storage engines and retrieval strategies, and broad compatibility across hosted and local models.
The required dependencies tell a longer story. There is a vector database client, a graph library, a context compression library, a templating engine, an image library, a message queue library, a symbolic maths library, a data validation library and its companion core library.
None of those is decorative, and each is a plausible dependency of a memory system that stores embeddings, models relationships, compresses context and renders something. But the combination is a large install for something billed as minimalist, and three of them bring their own dependency trees.
The shipped examples reinforce the point. There are four: one running a lexical retrieval baseline, one against a local model server, one against a local transformer backend, and one running a compression library against a hosted model. So what the repository demonstrates is four backends and two baselines, not the few lines of code the feature list promises.
The presence of a lexical baseline among the examples is the useful signal there. It means the framework ships a comparison against a method that needs no model at all, which is the right thing to have in the repository and a fairly demanding bar.
Four papers in one repository, and one status stated twice
The repository hosts four separate memory methods rather than one, each with its own documentation file at the root and its own row in the navigation table.
The first is the base framework, published at a 2026 conference. The second models memory as a heterogeneous graph with evolving connectivity, and its paper is listed as under review. The third is event-centric and multimodal, aimed at long-video question answering. The fourth is structured and hierarchical, preserving event-level bindings and cross-event connections, published at a different 2026 conference.
The third one has the discrepancy. Its row in the navigation table lists the paper as coming soon, while the news section at the top of the same file carries an earlier entry announcing that the same work has been accepted at a conference, with a preprint link. Two sections of one document disagree about whether the paper exists.
A second pattern runs through the table. Three of the four methods have publication venues listed. The one that does not is the graph method, marked as under review instead. That is normal and worth stating plainly rather than reading as a gap.
The broader point is about the repository rather than the papers. The name on the package, the directory and the installation instructions is the base method only. A reader arriving for the other three has to find out that they are here at all, and the readme's framing, minimal resource consumption and simple API, describes one method rather than four.
The baseline framework was announced twice, in two repositories
The news section records a baseline evaluation framework being provided twice, four months apart, and the two entries are not the same artefact.
The first, in January, links inside this repository, at a documentation page under the memory toolkits directory. It lists three competing memory systems being benchmarked on two datasets.
The second, in March, links to a different repository entirely, under the same organisation. It is described as more comprehensive, and it lists four competing systems, with the fourth being the addition.
So the in-repository framework was superseded by an external one, and both are still linked. Worse, the reproduction table further down the readme still routes the combined baseline results to the in-repository page rather than to the newer external one.
That is a small drift with a real cost. Anyone following the combined baseline link from the readme gets the January framework with three baselines, not the March framework with four, and nothing on either page says the other exists.
The underlying decision is sound. Splitting the evaluation harness out of the method repository is right, because it is code that outlives any single paper. The readme just has not caught up with it, and it is the third place in this file where a dated announcement has not been reconciled with what the project now points at.
A package marker at the root and four directories a library rarely commits
A few things in the tree are worth noting for anyone deciding how mature this is.
There is a Python package marker file at the repository root, sitting beside a source directory. That is the wrong shape for a source layout, where the package lives under the source directory precisely so the root is not importable by accident. Two import paths for the same code is the usual result.
Then there are four directories that a library would normally keep out of its main branch. A web directory, a dataset directory, a figures directory holding logo images for light and dark themes, and a directory of tutorial notebooks.
Notebooks and figures are reasonable. A committed dataset directory and a web directory are heavier choices, and they mean the repository carries things that could be fetched on demand instead.
The positive notes are worth as much. There is a tests directory, and there is a separate module directory for the model protocol server, with the news section recording that the framework can call multiple tools that server provides. So the project exposes its own capabilities back out through a protocol other agents can drive, which is a coherent thing to do for a memory framework and is not something most research repositories attempt.
The four example scripts, a root package marker, a committed dataset and a protocol server in one tree is the shape of a group publishing quickly rather than the shape of a library that has settled.
Editorial conclusion
Read this as a research group's released work rather than as a library you will install and depend on. That reading is forced by three facts in the packaging: the licence is stated two different ways, the interpreter range stops before the current one, and every dependency is frozen at an exact version including most of its own transitive closure. None of that is wrong for a paper artefact, and all of it is friction for an application. If you want to use the method, the reproduction scripts and the separate method documents are the parts that will hold up. If you want to vendor the framework, expect to unpick the pins, raise the interpreter ceiling and settle the licence question with the authors first, because those three decisions are all in files you would otherwise inherit silently.
Frequently asked questions
What is LightMem?
A lightweight memory management framework for large language model applications and agents, providing storage, retrieval and update for long-term memories, with support for hosted model APIs and for local model backends. Its paper was accepted at ICLR 2026 and is available as a preprint.
Which memory methods does the LightMem repository contain?
Four. The base framework from the ICLR 2026 paper, a connectivity-evolving method that models memory as a heterogeneous graph and is under review, an event-centric multimodal method aimed at long-video question answering, and a structured hierarchical method published at ACL 2026. Each has its own documentation file at the repository root.
How do I reproduce the LightMem results?
Ready-to-run scripts are provided for a long conversational memory dataset, a long-context evaluation dataset, and a combined baseline set, each with its own results document in the experiments directory. A separate baseline evaluation framework is also published under the same organisation, benchmarking competing memory systems including two others by name.
Which Python versions does LightMem support?
Only three ten and three eleven. The manifest requires a version at or above three ten and below three twelve, and the classifiers list those two interpreters, so the package will not install on a newer interpreter.
What licence is LightMem released under?
The two sources disagree. The repository is recorded under MIT and the readme links to a licence file, while the package manifest declares Apache-2.0 inline as text. Anyone relying on the licence should ask the authors rather than infer it from either file.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zjunlp-lightmem)Star history chart for your README
[](https://hysenlabs.com/projects/zjunlp-lightmem)Was this useful?