SkillNet ships routing only through a Claude or Codex extra
Create, Evaluate, and Connect AI Skills
At a glance
- What is it?
- SkillNet is a Python toolkit for the agent skill lifecycle: discovery, installation, creation, evaluation, analysis and routing. Its releases live on PyPI rather than in GitHub releases, its browser interface ships prebuilt, and the routing capability is gated behind a specific model provider extra.
- Who is it for?
- SkillNet fits teams who already keep skills as GitHub folders and want one place to search, download, generate and grade them, since the SDK covers all four in a few calls and the local interface lets you read the evidence behind each relationship. It is a poor fit if you need routing without committing to one of two named model providers, or if you want a single install that includes analysis, because the extras split that work across three flags.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 13 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
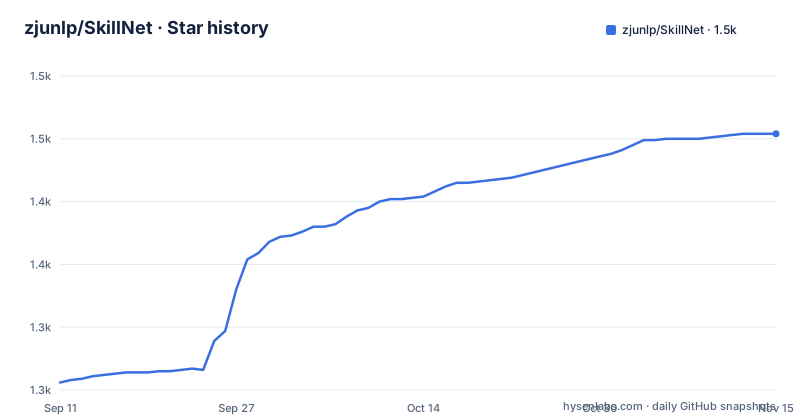
- zjunlp/SkillNet1,454 ★ · +198
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| zjunlp/SkillNet | 1.3k | 1.5k |
198 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Routing is not in the base package, and not in [graph] either
The lifecycle this project covers runs discovery, installation, creation, evaluation, analysis and routing. The install section then splits the optional work across three extras:
pip install "skillnet-ai[graph]"         # scenario analysis
pip install "skillnet-ai[graph,claude]"  # analysis and routing via Claude
pip install "skillnet-ai[graph,codex]"   # analysis and routing via Codex
Read the comments rather than the flags. The first extra buys scenario analysis and nothing more. Routing appears only when a model provider is named alongside it, and only two providers are named, Claude or Codex. So the sixth stage of the lifecycle the project advertises is unreachable through the base package and unreachable through `[graph]` on its own.
The SDK initialization says as much indirectly. The client is constructed with no arguments, `SkillNetClient()`, and then reads environment variables and saved settings, with a configuration section covering model endpoints or GitHub authentication. Analysis and routing both need a model endpoint; discovery and download are the parts that work without one, which is why the local browser interface section can promise browsing with no keys at all.
Nothing on this page states what a routing decision costs, or how many times one task will call the model.
The local interface ships prebuilt, listens on 8765, and starts empty
The browser interface arrived with skillnet-ai 0.1.2 on 2026-09-24, and it lives inside the Python package rather than beside it, with its own README under `skillnet-ai/src/skillnet_ai/web/ui/`:
pip install "skillnet-ai[ui]>=0.1.2"
skillnet ui --skills-dir "/absolute/path/to/skills"
Then open `http://127.0.0.1:8765`. Three design decisions are worth naming. The path is given as an absolute path to a skills directory, so the tool reads a directory you point at rather than a library it manages. The port is fixed. And the packaged releases include the website, so browsing needs neither Node.js nor model keys.
That last point has a consequence the section states plainly: analysis is generated separately with the SDK or CLI, and the interface only displays what already exists. It starts with an empty personal library, which means the first run shows you nothing until you have run analysis yourself and either pointed the tool at the results or imported a `graph.json` produced by `skillnet analyze`.
Two relationship predicates, and evidence back to source lines
The Analysis results view is where the project's model of a skill library becomes concrete, and it is small. The saved relationships are `compose_with` and `similar_to`, two predicates and no others, and the interface lets you follow relationship evidence to the original source lines rather than showing an unexplained edge between two skill names.
That evidence trail is the substantive claim here. A composition relation that points at a line in a file is auditable; the same relation without a source is a guess. The same applies to `similar_to`, where the interesting question is always which two descriptions were compared and by what, since that determines whether near duplicates are being merged or two genuinely different skills are being called similar.
The web platform presents the same shape at a larger scale, offering curated collections where you can inspect the relationships between their skills, and the July update added local scenario graphs plus orchestration. The vocabulary on the public site and in your local library is the two-predicate one, which keeps the local files and the hosted catalogue comparable.
Keyword search sorts by stars, and vector search borrows the service's embeddings
Search has two modes and one signature:
results = client.search(
    q="analyze financial PDF reports",
    mode="vector",
    threshold=0.85,
    limit=10,
)

for skill in results:
    print(skill.skill_name, skill.stars, skill.skill_url)
The default ordering is stated in prose rather than in the call: keyword search sorts by stars, while vector search uses the search service's own embeddings. That is the whole ranking policy this page describes. A star count decides the default order, and the semantic mode delegates to whatever the hosted service uses, which also means the threshold of 0.85 in the example is a threshold on someone else's embedding space rather than on your own corpus.
Two things follow for anyone using this to pick a skill. The search is against the hosted catalogue, not against your local directory, so it will happily return things you cannot inspect before installing. And the result fields are a name, a star count and a URL, which is the same three-field summary the table-driven hub problems come back to: enough to recognise a skill, not enough to choose between two.
Download returns one path, create returns a list, and only one source per call
Download takes a GitHub tree URL and a target directory, checks the structure it found, and hands back where it landed:
local_path = client.download(
    url="https://github.com/anthropics/skills/tree/main/skills/pdf",
    target_dir="./my_skills",
)
print(local_path)
`overwrite=True` replaces an existing folder, so overwriting is opt-in rather than silent.
Creation is the asymmetric one. The same call accepts a prompt, a GitHub repository, an office file or an execution trace, and the page is explicit that you choose one source per call and that the result is a list of generated directory paths. The three examples make the shapes concrete: a prompt asking for a csv-quality-checker skill that checks CSV files for missing values and duplicate rows without modifying the input, a repository URL pointing at DeepKE, and an office file called guide.pdf.
So one skill from GitHub gives you a single path back, and generation gives you an unbounded list, which is the practical difference between importing something a person already wrote and letting the tool decide how many artifacts to emit.
Evaluation is five dimensions, three levels, and a sentence per dimension
Evaluation works on a local skill or on a GitHub skill URL, and it grades across the five dimensions named in the overview: safety, completeness, executability, maintainability and cost awareness. Each dimension comes back with a `level` of `Good`, `Average` or `Poor` and a `reason`. The shape is a rubric with an explanation attached, not a single score, which is the right choice for something a person is supposed to overrule.
The hosted site shows the same thing under review skills, where you can inspect descriptions, evaluation ratings and GitHub sources with download links. The rubric is therefore not a local extra; it is part of how the public library presents entries, which makes its weakness more consequential. Five dimensions multiplied by three levels gives a coarse grid, and cost awareness in particular has no unit stated anywhere on this page: no token count, no price, no per-run figure.
The section itself stops mid-sentence, at the point where it would explain what evaluation reviews in the skill's instruction. So the criteria that assign Good or Poor to a skill are named but not defined here.
No GitHub releases, so the version that matters is the wheel version
The repository has no GitHub releases. Versions move on PyPI instead, and the news list is the changelog: skillnet-ai 0.1.2 on 2026-09-24 for the browser interface, a report update on 2026-08-20 introducing SkillNet-Gym with executable benchmarks for skill construction, retrieval and composition plus SkillNet-Fabric for Wiki-based routing, a library update on 2026-07-11 claiming 500K+ indexed GitHub skills with improved deduplication and broader coverage of scientific research and data analysis, an MCP server maintained by CycleChain on 2026-03-12, the arXiv paper on 2026-03-04, and integrations with JiuwenClaw and OpenClaw in March and February.
The repository layout backs that up: `skillnet-ai/` for the package, `skills/` for skill material, `examples/` with separate scripts for analyze, create, evaluate, route and search plus two notebooks, `experiments/`, and `images/`. Two of the named integrations are third parties, one of them mirrored in the tree as `examples/JiuwenClaw/`, and both carry the same Claw suffix.
One small thing to note if you link to it: the site, the homepage and the in-page links are written with plain `http://` at skillnet.openkg.cn, while the badge links elsewhere in the header use https.
Editorial conclusion
SkillNet fits teams who already keep skills as GitHub folders and want one place to search, download, generate and grade them, since the SDK covers all four in a few calls and the local interface lets you read the evidence behind each relationship. It is a poor fit if you need routing without committing to one of two named model providers, or if you want a single install that includes analysis, because the extras split that work across three flags. Before you build on it, check two things. Confirm the provider you already use is one of the two the routing extras name, since `[graph]` alone stops at analysis. And note that versions are published to PyPI with no GitHub releases, so pin the wheel version rather than the repository state, and remember that the evaluation rubric's own description stops mid-sentence on this page, which is the first place to look when a grade looks wrong.
Frequently asked questions
What does SkillNet do?
It provides infrastructure for the agent skill lifecycle: searching a public skill library by keyword or semantic intent, downloading skill folders from GitHub into local workspaces, generating skills from a prompt, repository, document or execution trace, evaluating skills on safety, completeness, executability, maintainability and cost awareness, extracting capabilities and usage scenarios, and routing a task to a skill from your local library.
How do I install the SkillNet Python SDK and what do the extras enable?
Python 3.10 or newer is required, and the base install is `pip install skillnet-ai`. The `graph` extra adds scenario analysis, and routing appears only in `skillnet-ai[graph,claude]` or `skillnet-ai[graph,codex]`, which route via Claude or via Codex respectively.
Do I need a model API key to browse skills with SkillNet locally?
Not to browse. Packaged releases include the website, so no Node.js and no model keys are needed to read skill files and saved results. Analysis has to be generated separately with the SDK or CLI first, and the interface starts with an empty personal library.
What relationships does SkillNet's analysis record between skills?
Two, named `compose_with` and `similar_to`, and they can be explored under Analysis results in the local interface or imported from a `graph.json` produced by `skillnet analyze`. The interface lets you follow the evidence for a relationship back to the original source lines.
Is there an MCP server for SkillNet?
Yes. A SkillNet MCP server maintained by CycleChain makes the SkillNet tools available to MCP-compatible agents, and it was announced on 2026-03-12 in the project's news list.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zjunlp-skillnet)Star history chart for your README
[](https://hysenlabs.com/projects/zjunlp-skillnet)Was this useful?