Daily-LLM numbers 19 architecture families by theme, and its phase numbers disagree with requirements.txt
Machine learning, deep learning, Python, large language models, multimodal AI, LLM, algorithm interview prep and NLP tutorials.
At a glance
- What is it?
- A learning path that sorts deep learning and large model work into nineteen numbered folders, each with a one-line description and a key year, plus cross-cutting foundations and a local web timeline. The page at the repository root is in Chinese, the tutorials are Python, and the only compiled code in the project is the timeline site.
- Who is it for?
- Daily-LLM fits someone building a structured self-study path through modern model architectures who wants the ordering and the key years settled before writing any code, since the nineteen folders are a usable syllabus and the cross-cutting foundations directory covers what the families assume.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 50 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
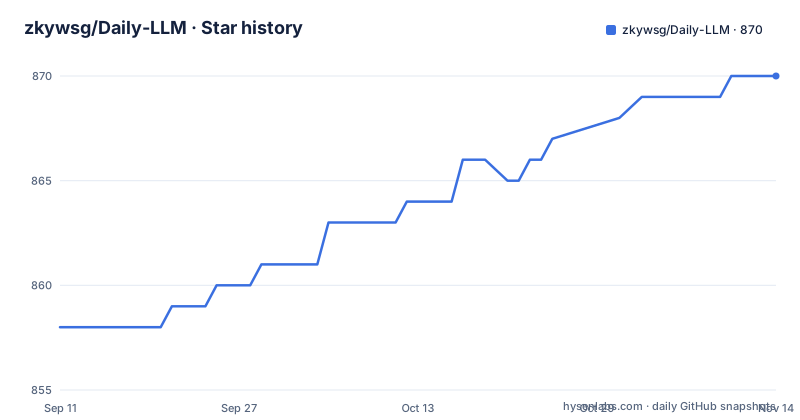
- zkywsg/Daily-LLM870 ★ · +12
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| zkywsg/Daily-LLM | 858 | 870 |
12 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Nineteen folders, numbered by theme rather than by year
The organising idea is a set of nineteen numbered directories, one per architecture family, each carrying a key year and a single-sentence description of what the family changed. The list runs from 01-cnn through 19-recommendation. CNN carries 2012 onward, Transformer is a single year at 2017, BERT 2018 onward, GPT and scaling 2018 to 2020, ViT 2020 onward, multimodal alignment 2021 onward, diffusion 2020 onward, PEFT and LoRA 2021 onward, alignment and RLHF 2022 onward, MoE and efficient inference 2023 onward, RAG and agents 2023 onward, reasoning models 2024 onward, graph neural networks 2017 onward, speech and audio 2020 onward, and recommendation systems 2016 onward. Two directories are not model families at all: foundations/ for the cross-cutting material such as activation, backpropagation, optimisers, normalisation and attention, and projects/ for practical work that spans families.
The heading says 1986 and the table's first year is 1997
The section heading announces a range of 1986 to 2025, and the introductory sentence attributes 1986 to RNN and 2025 to reasoning models. The table underneath does not back the first number. Its earliest key year is 1997, on the RNN, LSTM and GRU row, which is listed as 1997 and 2014 onward. Everything else starts in 2012 or later, from CNN onward. So the 1986 endpoint in the heading has no matching row, and the range it implies, 1986 to 2025, describes the narrative rather than the data. The last end year, 2025, also sits in the heading only; the newest family, reasoning models, is given as 2024 onward. There is a generated year index at TIMELINE.md for looking things up by date instead.
The folder order is thematic, so it never reads as a chronology
Reading the key years down the table in order makes the numbering choice obvious. Nine is multimodal alignment at 2021 onward, and ten is diffusion at 2020 onward, so the earlier family is filed after the later one. Fifteen is reasoning models at 2024 onward, sixteen is world models and video generation at 2018 onward, seventeen is graph neural networks at 2017 onward, and eighteen is speech and audio at 2020 onward. That sequence runs backwards three times. The grouping that emerges is thematic: attention-based models together, generative models together, then efficiency and systems topics, then the more peripheral families at the end. Anyone using the numbering as a study order should know they are getting a curriculum, not a timeline, and that several families are old enough to predate the ones filed before them.
The phase numbers on the page are not the phase numbers in the file
The quick start offers a full install and a staged one, and the staging labels disagree with the dependency file. The page groups the work into Phase 00-01 for prerequisites and the vision line, Phase 02-03 for the language line and scale multimodal, Phase 04 for alignment and fine-tuning, and Phase 05 for systems and production:
# Phase 05(系统与生产)
pip install sentence-transformers faiss-cpu chromadb langchain vllm fastapi mlflow wandb
requirements.txt uses a different scheme, with comments headed Core ML/DL for Phase 1-2, Transformers and NLP for Phase 3-4, RAG and vector databases for Phase 5, and Serving and monitoring for Phase 6-7. The page has no Phase 06 or 07, and the file has no Phase 00. Nineteen packages are listed in the file with lower bounds only, from torch at 2.0.0 and numpy at 1.24.0 through vllm at 0.2.0 and wandb at 0.16.0, plus tqdm, pandas and jupyter under a utilities comment.
sentence-transformers is asked for twice in the staged guide
The staged install has a repetition worth knowing about. sentence-transformers appears in the language line group and then again in the first position of the systems and production group, so a reader following the stages in order installs the same package twice. The earlier line covers the language line and scale multimodal work with transformers, datasets and sentence-transformers, while the later line pairs that same package with faiss-cpu, chromadb, langchain, vllm, fastapi, mlflow and wandb. Nothing is broken by this, since pip resolves an already satisfied requirement, but it does mean the staging list is a rough guide rather than a tested sequence, and it is a reminder to read requirements.txt as the authoritative dependency list and treat the four phase blocks as a suggestion about which subset you actually need.
The project is filed as TypeScript because of one directory
The repository's primary language is TypeScript, which is misleading if you take it as a description of the tutorials. Almost everything here is Python: the quick start clones the repository and runs pip install against a requirements.txt, and each of the nineteen family directories is a set of Python notes. The TypeScript comes from web/, the visualisation page, which is a separate small site with its own npm workflow:
cd web
npm install
npm run dev
That page offers two ways to browse, by time and by family, and its node pages combine Markdown body text with interactive golden specimens. The rest of the repository is prose: AGENTS.md, CLAUDE.md, CONTRIBUTING.md, STYLE.md and the generated TIMELINE.md sit at the root next to the nineteen folders, alongside docs/ and scripts/.
The web timeline is local only, and _archive/ is kept as rewrite material
Two details explain the shape of the repository. The first is the web page: it is described as currently maintained as a local page, with a formal access address to be added once a public deployment exists. That is why the repository has no homepage recorded. The second is the _archive/ directory, which holds the previous timeline/ and tracks/ content and is described as a source of material while family content is being rewritten, which tells you the nineteen folders are a migration in progress rather than a settled structure. The page at the repository root is the Chinese version, and an English README is listed alongside it. The licence is MIT, and no GitHub releases have been published.
Editorial conclusion
Daily-LLM fits someone building a structured self-study path through modern model architectures who wants the ordering and the key years settled before writing any code, since the nineteen folders are a usable syllabus and the cross-cutting foundations directory covers what the families assume. It is a poor fit as a reference for one specific architecture, because each folder is a starting point rather than an API, and a poor fit for a contributor who wants a uniform phase to run, since the phase numbering differs between the page and the dependency file. Before starting, pick your phases from the folder numbers rather than from the phase labels, and note that the web timeline is local only until a deployment URL is added.
Frequently asked questions
How many architecture families does Daily-LLM cover?
Nineteen, in numbered directories from 01-cnn through 19-recommendation, each with a key year range and a one-line description. Two more directories are cross-cutting: foundations/ for shared material and projects/ for practical work spanning families.
How do I install the Daily-LLM dependencies?
Clone the repository and run pip install -r requirements.txt, which lists nineteen packages with lower bounds only. A staged alternative is given in four phase blocks, from the vision line through to systems and production.
What language is the Daily-LLM repository written in?
The primary language is recorded as TypeScript, which comes from the web/ visualisation page and its npm workflow. The tutorials themselves are Python and are installed with pip from requirements.txt.
Is the Daily-LLM web timeline available online?
Not yet. The visualisation page in web/ is currently maintained as a local page, and a public access address is to be added after deployment, which is why the repository records no homepage.
What is in the Daily-LLM archive directory?
The _archive/ directory holds the older timeline/ and tracks/ content and is described as source material for when family content is rewritten, which indicates the nineteen family directories are still being migrated.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zkywsg-daily-llm)Star history chart for your README
[](https://hysenlabs.com/projects/zkywsg-daily-llm)Was this useful?