geo-seo-claude: five parallel subagents, one 0 to 100 score, and what it never checks
GEO-first SEO skill for Claude Code. Comprehensive AI search optimization for any website — citability scoring, AI crawler analysis, brand authority, schema markup, platform-specific optimization, and PDF reports. If you want learn how to sell this to real businesses, check out the skool community
At a glance
- What is it?
- A Claude Code skill that fetches a site, fans the analysis out to five subagents, and folds the results into a composite GEO score for agencies and in-house marketers. The pipeline is well mapped. The blind spot is that none of the six score categories measures whether an AI model actually cites you.
- Who is it for?
- Use it when you want a repeatable, weighted audit of a site you control plus a deliverable PDF you can hand a client. Skip it when you need proof that AI assistants cite you, because it scores signals on your own pages and nothing in the pipeline reads a model answer.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
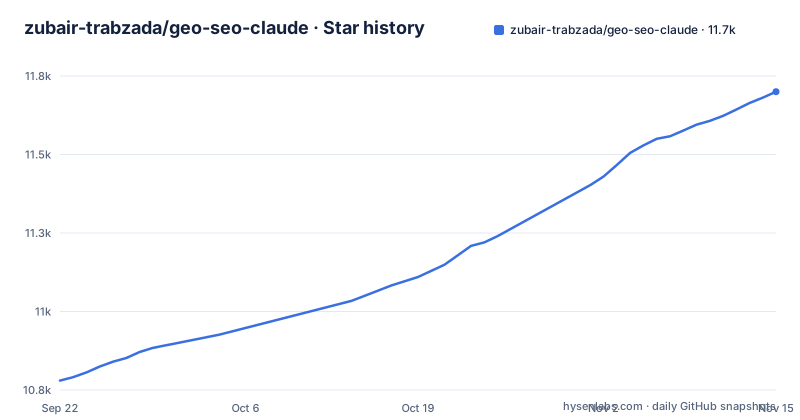
- zubair-trabzada/geo-seo-claude11,700 ★ · +920
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| zubair-trabzada/geo-seo-claude | 10.8k | 11.7k |
920 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One audit fans out into five subagents before anything gets scored
Running /geo audit <url> starts with discovery: it fetches the homepage, detects the business type, and crawls the sitemap. From there the work splits across five subagents launched simultaneously. One covers AI visibility (citability, crawler access, llms.txt, brand mentions), one covers platform analysis for ChatGPT, Perplexity and Google AI Overviews, one runs a technical SEO pass over Core Web Vitals, server-side rendering, security and mobile, one grades content quality and E-E-A-T, and one handles schema markup detection, validation and generation. Nothing is scored until all five return. The synthesis step collapses them into a single composite GEO Score from 0 to 100, and the report step emits a prioritized action plan with quick wins. The weights are the part worth memorizing: AI citability and visibility 25 percent, brand authority signals 20 percent, content quality and E-E-A-T 20 percent, technical foundations 15 percent, structured data 10 percent, platform optimization 10 percent. Citability alone decides a quarter of the number, so a thin brand profile can sit behind a high composite, and a fifth of the score rides on two categories (structured data and platform work) that most teams do once and forget. The repository root carries a tests/ directory, a scripts/ directory and two pull request drafts named for agent HTTP checks and content signals, which is the shape you would expect from a project that treats the subagent split as the product.
Everything installs into ~/.claude/skills/geo/.venv/ and never touches system Python
The dependency set is unusual for a skill: it is a real Python application with a parse-and-render stack, and the installer gives it a private interpreter at ~/.claude/skills/geo/.venv/. Skill and agent files reference that venv directly, so the tool keeps working no matter what python3 resolves to on your PATH, and uninstalling the skill removes the venv with everything else. The pinned ranges are worth reading before you upgrade anything on your machine:
beautifulsoup4>=4.12.0,<5.0.0
requests>=2.34.2,<3.0.0
lxml>=6.1.1,<7.0.0
playwright>=1.56.0,<2.0.0
Pillow>=12.3.0,<13.0.0
urllib3>=2.7.0,<3.0.0
validators>=0.22.0,<1.0.0
flask>=3.1.3,<4.0.0
rich>=13.0.0,<14.0.0
Two of those are optional at install time. Playwright is listed as optional and marked for screenshots. uv is optional too, and when the installer finds it present it uses uv for a faster dependency install, which is the difference between a fast and a slow first run. flask, Pillow and rich have no obvious role in a crawler audit, which tells you the report and image paths are part of the product rather than an afterthought. One cost sits outside requirements.txt: Claude Code itself, which is a separate CLI you must already have, plus Git, plus Python 3.10 and up, plus python3-venv on Debian and Ubuntu.
install-win.sh exists because PowerShell is explicitly not a supported shell
Windows gets its own installer and an explicit warning. The supported path is Git Bash from Git for Windows, and the repository ships install-win.sh beside install.sh. Both routes are offered:
# Option 1: One-command install (run from Git Bash, not PowerShell/CMD)
curl -fsSL https://raw.githubusercontent.com/zubair-trabzada/geo-seo-claude/main/install-win.sh | bash

# Option 2: Manual install
git clone https://github.com/zubair-trabzada/geo-seo-claude.git
cd geo-seo-claude
./install-win.sh
The instruction is to right-click the folder and choose Open Git Bash here, or open Git Bash and navigate to the directory, and the guidance is blunt about not using PowerShell or Command Prompt. On macOS and Linux the equivalent one-liner runs install.sh:
curl -fsSL https://raw.githubusercontent.com/zubair-trabzada/geo-seo-claude/main/install.sh | bashand the manual route is git clone, cd, ./install.sh. Note the shape of the repository root: it holds uninstall.sh, and there is no Windows-specific uninstall script named alongside install-win.sh. The project also documents an isolated install rather than a global one, and the Skool community linked from the repository homepage is where the sales material lives, not where the code is.
A 134 to 167 word window is the entire citability rubric
The citability scorer is the narrowest and most opinionated part of the system, and the /geo citability <url> command exposes it on its own. Its premise, as the README states it, is that optimal AI-cited passages are 134 to 167 words, self-contained, fact-rich, and written to answer a question directly. Four constraints and one number. This is the mechanism behind the 25 percent slice of the composite score, which is why it matters more than its simplicity suggests. A page can be flawless on Core Web Vitals and structured data, and still lose 25 points because its paragraphs are 300-word introductions that build to a point instead of stating one. Here is the honest tradeoff: that shape is optimized for extraction by a retrieval step, and a human reading the same page will notice the seams. Sections rewritten to sit inside 134 to 167 words, stripped of throat-clearing and pushed to state the answer in the first sentence, read as denser and more confident, and they read as chopped when every single block obeys the same window. The README says the scorer analyzes content blocks, so the practical use is as a threshold: flag the passages that fall outside the window, then rewrite them by hand against the four rules. Treat the number as a prompt for an editor, not as a grade.
robots.txt is the only file the crawler check ever opens
The /geo crawlers <url> command has a sharply defined job: parse robots.txt, look for 14 or more named AI crawlers (GPTBot, ClaudeBot, PerplexityBot among them), and hand back allow or block recommendations. That is a complete description of what the check does, and it is worth being precise about what it therefore cannot do. It does not confirm that any crawler ever requested the site, because a file the site serves is a declaration, not a log entry. It does not read server access logs, does not pull referral data, and does not compare the recommendation against what a model returned. Nothing in the command table offers a slot for that evidence. The consequence is concrete for anyone evaluating the tool: unblocking ClaudeBot in robots.txt changes a permission and nothing else, so a green crawler report is the start of a test rather than the result of one. The same limit applies to /geo quick <url>, a 60-second visibility snapshot, which is a fast read of the same surface. If your question is whether AI crawlers are actually arriving and whether those arrivals convert, you need server logs and referral analytics from outside this project, and you should not let a clean audit stand in for them.
The uninstaller leaves ~/.geo-prospects/ full of client names on purpose
There is a second command family hiding behind the audit tools. The CRM and reporting skills /geo prospect, /geo proposal and /geo compare write runtime data outside the Claude Code directory, into ~/.geo-prospects/, and that layout is fixed:
~/.geo-prospects/
├── prospects.json              # Client/prospect pipeline data
├── proposals/                  # Generated proposal documents
│   └── <domain>-proposal-<date>.md
└── reports/                    # Monthly delta reports
    └── <domain>-monthly-<YYYY-MM>.md
Three things follow. First, the pipeline state is plain JSON in your home directory, which means it is readable, greppable, and trivially backed up by whatever syncs your dotfiles. Second, the naming is deterministic (domain, date, month), so monthly delta reports accumulate as a history you can diff between runs, and the examples/ directory in the repository shows the same pattern in committed form with an electron-srl.com audit JSON, a quick audit, a proposal and a dated PDF report. Third, and most important, the README states plainly that this directory is not removed by the uninstaller, so you have to delete it by hand when you no longer want the prospect data. For an agency that is a retention decision, not a convenience one: client domains, proposal documents and monthly commentary outlive the tool that wrote them, and they land in backups and sync folders alongside your shell config. A white-label/ directory at the repository root suggests the reports are meant to carry your own branding, which makes the copy inside those markdown files doubly worth reviewing before it is handed over. The upside is the obvious one: reports that are files, not chat transcripts, are the only way to hand a client something they will still read next month.
No releases means the installer always pulls whatever main holds today
The repository has no GitHub releases, and the last push was on 2026-11-02. The license is MIT and the project is not archived, so nothing here suggests abandonment; the freshness of that commit date is the fact to anchor on. What the missing releases cost you is reproducibility, and the install paths make that concrete. Both one-command installers fetch a script from the main branch over raw.githubusercontent.com, and the skill files, the sub-skills, the templates/ directory and the scoring weights all arrive from that same moving ref. There is no release tag to pin and no changelog in the repository root, so a team using the moving installer can get different scoring weights, subagent routing in geo/SKILL.md, or commands on a later reinstall. For reproducibility, review and pin a specific commit and use an installation method that preserves that revision. The dependency ranges are bounded on both ends, which caps how far the environment can drift, but a bounded range is not a lockfile, so a clean install later resolves whatever satisfies those bounds at that moment. The repository does carry tests/, CONTRIBUTING.md and CLAUDE.md, which tells you the project has the scaffolding for care even without tagged versions. The practical rule for client work: record the commit you installed, and treat any change in the composite GEO Score between two audits as potentially a scoring change rather than a site change until you have confirmed the weights still match what you recorded. That single habit prevents the most expensive misreading this tool invites, which is a number that moved for reasons you did not write down.
The composite score describes your pages, not whether a model quoted them
Six weighted categories produce the 0 to 100 number, and every one of them is a property of assets you control or can observe from the outside: your own content blocks, your own robots.txt, your own schema, your own technical baseline, and a scan for your brand on third-party sites (YouTube, Reddit, Wikipedia, LinkedIn and seven or more others). The platform optimization category, weighted 10 percent, is built on a stated overlap figure: only 11 percent of domains are cited by both ChatGPT and Google AI Overviews for the same query, which is a good reason to optimize per platform and a poor substitute for knowing which platform cites you today. That is the core limit of the whole design. A higher score across two audits means the analyzable surface of your site changed. It does not mean your share of AI answers rose, because no category in the weight table measures model output and no command in the table reads a generated response. The same applies to brand scanning: it is a point-in-time sweep, so a mention published on Reddit after the run is invisible until the next one, and a mention that disappears leaves no trace in the comparison. Market framing in the README (a GEO services market above 850M dollars, AI-referred traffic up 527 percent year over year, 4.4x conversion against organic, a Gartner projection of a 50 percent search traffic drop by 2028, and only 23 percent of marketers investing) is the author arguing the case for the category, not data your audit collected. Read the score as a prioritized to-do list generated by a rule set, keep your own referral analytics beside it, and never let the two numbers substitute for each other.
Editorial conclusion
Use it when you want a repeatable, weighted audit of a site you control plus a deliverable PDF you can hand a client. Skip it when you need proof that AI assistants cite you, because it scores signals on your own pages and nothing in the pipeline reads a model answer. Before treating a score jump as a win, re-run the audit and check referral analytics, and know that prospect data written to ~/.geo-prospects/ survives the uninstaller.
Frequently asked questions
What does the GEO skill for Claude do?
It adds a /geo command family to Claude Code that audits a URL for AI search visibility, folding citability, brand authority, content quality, technical foundations, schema and platform readiness into a composite 0 to 100 GEO score, then emits a prioritized action plan in markdown or PDF.
What is GEO SEO and how does it work?
GEO is generative engine optimization: making a site readable and quotable by AI answer engines such as ChatGPT, Claude, Perplexity, Gemini and Google AI Overviews. The skill checks robots.txt for 14 or more named AI crawlers, scores content blocks against the 134 to 167 word passage shape AI systems tend to quote, analyzes or generates an llms.txt file, and scans for brand mentions on third-party platforms.
Is Claude AI good for SEO?
The project uses it as an analyst rather than a ranker. A full audit launches five subagents at once, one per analysis area, and a synthesis step aggregates them into a 0 to 100 GEO score, after which a report step writes a prioritized action plan. The output is an audit document, not a ranking.
Is SEO dead now with AI?
The tool does not drop traditional SEO. Technical foundations are 15 percent of the score and structured data 10 percent, alongside 25 percent AI citability and visibility, 20 percent brand authority and 20 percent content quality and E-E-A-T, and its market table cites a Gartner projection of a 50 percent search traffic drop by 2028.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zubair-trabzada-geo-seo-claude)Star history chart for your README
[](https://hysenlabs.com/projects/zubair-trabzada-geo-seo-claude)Was this useful?