1rgs/claude-code-proxy: Run Claude Code Against OpenAI or Gemini Models
Run Claude Code on OpenAI models
At a glance
- What is it?
- A FastAPI server that speaks the Anthropic Messages API and forwards to LiteLLM, so Claude Code can run on gpt-4.1 or gemini-2.5-pro instead of Claude. The README covers setup well and says nothing about auth, limits or rollback.
- Who is it for?
- Adopt it if you already pay for OpenAI or Gemini, want Claude Code's client experience without Anthropic billing, and are comfortable running an unauthenticated local server on port 8082. Do not adopt it if you need per-user authentication, a documented support policy, or a licence you can point a legal team at, because none of those appear in the repository.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 146 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
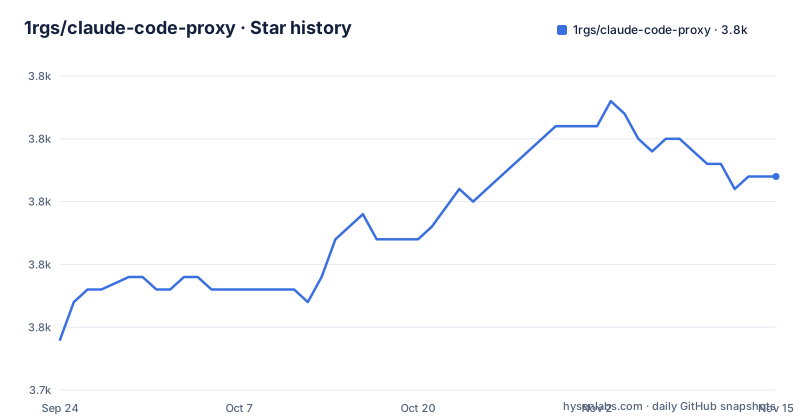
- 1rgs/claude-code-proxy3,762 ★ · +13
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| 1rgs/claude-code-proxy | 3.7k | 3.8k |
13 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What claude-code-proxy actually does
Claude Code is an Anthropic client. It sends requests to an Anthropic-shaped endpoint and expects Anthropic-shaped responses. If you want the same terminal workflow but your budget or your model preference sits with OpenAI or Google, you need something in the middle that accepts the Anthropic wire format and re-emits it as an OpenAI or Gemini call. That is the entire job of this repository, and the README states it plainly: it is "a proxy server that lets you use Anthropic clients with Gemini, OpenAI, or Anthropic models themselves (a transparent proxy of sorts), all via LiteLLM."
The audience is narrow and specific. You need to be a Claude Code user, you need an OpenAI or Google AI Studio key, and you need to be willing to run a Python service locally. The project is not a gateway for a team, not a hosted service, and not a general Anthropic-compatible API for arbitrary applications, even though it would technically accept any Anthropic-format client. The README frames the whole thing around Claude Code and gives one client-side example.
One design decision is worth flagging early. Setting PREFERRED_PROVIDER="anthropic" turns the server into what the README calls "just an Anthropic proxy" mode, where haiku and sonnet requests pass through with an anthropic/ prefix and are not remapped. That is a useful escape hatch, but it also means the project is two tools in one: a model translator and a plain pass-through. The pass-through mode adds a network hop and a running process for no functional gain over pointing Claude Code at Anthropic directly.
How the request path and model mapping work
The repository is small: server.py, tests.py, pyproject.toml, a Dockerfile and a uv.lock. The dependency list in pyproject.toml tells you the architecture without reading the code. FastAPI and uvicorn serve the HTTP surface. LiteLLM does the provider translation. httpx and pydantic handle transport and payload shapes. python-dotenv loads the .env file. google-auth and google-cloud-aiplatform exist purely to support the Vertex AI authentication path.
The interesting part is the mapping layer. Claude Code sends requests naming Claude tiers, and the proxy rewrites them. According to the README, haiku and sonnet are the two tiers that get remapped, and the target depends on PREFERRED_PROVIDER. With the default openai setting, haiku becomes SMALL_MODEL and sonnet becomes BIG_MODEL, each prefixed with openai/. With google, the same two tiers map to the Gemini equivalents, prefixed with gemini/, but only if the chosen model appears in the server's known GEMINI_MODELS list. If it does not, the README says the proxy falls back to the OpenAI mapping. That fallback is the most consequential detail in the whole document, and it is described in a single clause. A typo in BIG_MODEL under PREFERRED_PROVIDER=google does not produce a clear error. It silently routes your traffic to OpenAI instead, which means you may be billed by a provider you were not trying to use.
The README's mapping table gives defaults of openai/gpt-4o-mini for haiku and openai/gpt-4o for sonnet, while the environment variable section says BIG_MODEL defaults to gpt-4.1 and SMALL_MODEL to gpt-4.1-mini. Those two statements disagree. The .env.example comments side with the gpt-4.1 pair. Treat the table as stale and set both variables explicitly rather than relying on defaults.
The supported model lists are short and worth reading before you commit. On the OpenAI side the README lists o3-mini, o1, o1-mini, o1-pro, gpt-4.5-preview, gpt-4o, gpt-4o-audio-preview, chatgpt-4o-latest, gpt-4o-mini, gpt-4o-mini-audio-preview, gpt-4.1 and gpt-4.1-mini. On the Gemini side it lists gemini-2.5-pro and gemini-2.5-flash. Newer models released after the last push are not in those lists, and the prefix logic keys off them.
Installing claude-code-proxy and making a first request
The README documents two install routes, from source and from Docker, and both end at the same place: a server on port 8082. The source route assumes uv is available. Clone the repository and move into it first.
git clone https://github.com/1rgs/claude-code-proxy.git
cd claude-code-proxy
If uv is not installed, the README gives the install script. Running it pipes a remote script into a shell, so read it first if that matters to you.
curl -LsSf https://astral.sh/uv/install.sh | shNext, create the environment file from the example and fill in keys. At minimum you need OPENAI_API_KEY. GEMINI_API_KEY is only needed when PREFERRED_PROVIDER=google and you are not using Vertex authentication.
cp .env.example .envA minimal .env for the default OpenAI path looks like this. Set both model variables explicitly, because the README's default values are inconsistent between sections.
OPENAI_API_KEY="sk-..."
PREFERRED_PROVIDER="openai"
BIG_MODEL="gpt-4.1"
SMALL_MODEL="gpt-4.1-mini"
Start the server. The --reload flag is optional and the README marks it as a development convenience.
uv run uvicorn server:app --host 0.0.0.0 --port 8082 --reloadThe Docker path is shorter. The README's curl line for fetching the example env file is written as curl -O .env https://..., which puts the URL in the output-name position and will not do what the surrounding prose describes. Use the raw file directly instead.
curl -o .env https://raw.githubusercontent.com/1rgs/claude-code-proxy/refs/heads/main/.env.exampleThe README's compose file mounts the env file and publishes the port. Note that it uses the ghcr.io image rather than a local build.
services:
  proxy:
    image: ghcr.io/1rgs/claude-code-proxy:latest
    restart: unless-stopped
    env_file: .env
    ports:
      - 8082:8082
Finally, point Claude Code at the proxy. Install the client if you have not, then set ANTHROPIC_BASE_URL for the session. The README shows the variable inline rather than exported, and that is enough for a single invocation.
npm install -g @anthropic-ai/claude-code
ANTHROPIC_BASE_URL=http://localhost:8082 claude
If the wiring is correct, Claude Code starts normally and its requests are answered by the configured backend. There is no health endpoint documented in the README, so the first real signal is whether a prompt returns an answer.
The exposed port and the missing authentication story
The README does not mention authentication on the proxy itself. Every example binds to 0.0.0.0 and publishes port 8082, and the Dockerfile's CMD does the same. There is no API key check, no token, no allowlist described anywhere in the repository documentation. The only credentials in play are the upstream provider keys sitting in .env.
That is a real limitation, not a theoretical one. A server on 0.0.0.0:8082 that forwards to a paid OpenAI account is an open relay for anyone who can reach the port. On a laptop behind a home router that is a modest risk. On a cloud VM, a shared lab machine, or a container network with other tenants, it is not. The README offers no guidance here, and the Dockerfile exposes the port without qualification.
The practical mitigation is to bind to 127.0.0.1 instead of 0.0.0.0 when running from source, since Claude Code runs on the same machine in the documented workflow. The Docker compose snippet publishes 8082:8082, which maps to all interfaces; narrowing that to 127.0.0.1:8082:8082 is a one-character-class change in the compose file. Neither change is documented, and neither is a substitute for authentication if you actually need multi-user access.
A second gap: the README says nothing about rate limits, request timeouts, retries, or what happens when the upstream provider returns an error. LiteLLM handles some of that internally, but the proxy's own behaviour on failure is not described. If you are running this in front of a long Claude Code session, you are trusting LiteLLM's defaults.
LiteLLM versus a hand-written translation layer
The obvious alternative is to write the translation yourself: a small FastAPI app that accepts /v1/messages, reshapes the Anthropic payload into an OpenAI chat completion request, and reshapes the response back. That is more work than it sounds. Streaming responses, tool calls, system prompts, and the content-block structure of Anthropic messages all need handling, and getting streaming right is where most hand-rolled attempts stall.
LiteLLM is the reason this project is a few hundred lines rather than a few thousand. It already speaks both formats and covers the provider matrix, which is why the whole repository is server.py plus configuration. The trade-off is that you inherit LiteLLM's behaviour and its release cadence. When a provider changes its API shape, you wait for LiteLLM to catch up and then bump the dependency. The pyproject.toml pins litellm>=1.81.0, a floor rather than a ceiling, so a fresh uv sync can pull a newer LiteLLM than the author tested against.
A different kind of alternative is a general-purpose gateway such as LiteLLM's own proxy mode, which exposes an OpenAI-compatible endpoint and handles keys, budgets and logging. That solves a different problem. It does not speak the Anthropic Messages API, so Claude Code cannot talk to it without a translation shim, which is exactly what this project is. If your goal is a shared, authenticated gateway for a team, a general gateway plus a translation layer is the shape you want, and claude-code-proxy is the translation layer, not the gateway.
A third option is simply not proxying. If the reason you are here is cost, check whether Anthropic's own tiers cover your usage before adding a process to your stack. The proxy only pays for itself if the OpenAI or Gemini models you map to are genuinely cheaper or better for your workload.
Maintenance, licence and upgrade cost
The repository is not archived, and the last push was on 2026-06-23. That is roughly three months before the date of this article, which puts it inside the six-month window but well short of the daily churn you would see in a project with an active maintainer. The repository has no published GitHub releases, so versioning is whatever the main branch happens to contain. There is no changelog in the top-level file listing.
The dependency surface is where upgrade cost accumulates. LiteLLM moves quickly and its provider integrations change with upstream APIs. google-cloud-aiplatform and google-auth are large packages that exist only for the Vertex path; if you never set USE_VERTEX_AUTH=true, you are still installing them because they are unconditional entries in pyproject.toml. The Dockerfile builds FROM python:latest, which means an image rebuild can silently change the Python version under you. That is a reproducibility problem the project does not address.
The licence field is unknown. There is no LICENSE file in the top-level repository entries, and the README does not state terms. For local, personal use that is unlikely to matter. For anything shipped inside a company, it is a blocker you have to resolve with the author before you build on it. This is not legal advice; it is an observation that the terms are not stated in the repository.
On the positive side, the code footprint is tiny. server.py and tests.py are the whole application. If the project goes quiet, a competent Python developer can read it in an afternoon and fork it. That is a meaningful hedge against abandonment, and it is the strongest argument for adopting a small proxy over a large gateway for this particular job.
Editorial conclusion
Adopt it if you already pay for OpenAI or Gemini, want Claude Code's client experience without Anthropic billing, and are comfortable running an unauthenticated local server on port 8082. Do not adopt it if you need per-user authentication, a documented support policy, or a licence you can point a legal team at, because none of those appear in the repository. Before wiring it into a team workflow, verify which models your account can actually reach, confirm that BIG_MODEL and SMALL_MODEL are valid names for the chosen provider, and check whether the proxy is exposed beyond localhost.
Frequently asked questions
Can Claude Code use a proxy?
Yes. Claude Code reads the ANTHROPIC_BASE_URL environment variable, and the README's usage example sets it to http://localhost:8082 before launching the client.
How do I install claude-code-proxy?
Clone the repository, run the uv install script if uv is not present, copy .env.example to .env and fill in your keys, then start the server with uv run uvicorn server:app --host 0.0.0.0 --port 8082 --reload. A Docker image at ghcr.io/1rgs/claude-code-proxy:latest is also documented.
How do I use claude-code-proxy with Claude Code?
Install the Claude Code client, then launch it with ANTHROPIC_BASE_URL=http://localhost:8082 claude. The README states that the client will then use the configured backend models.
What is claude-code-proxy?
It is a proxy server, built on FastAPI and LiteLLM, that lets Anthropic clients such as Claude Code talk to Gemini, OpenAI, or Anthropic backends by translating between the Anthropic API and the other providers.
Is there a free proxy for Claude Code?
The project itself is free to run, but it does not provide free model access. You still need your own OpenAI API key, Google AI Studio key, or Vertex AI credentials, and usage is billed by whichever provider you configure.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/1rgs-claude-code-proxy)Star history chart for your README
[](https://hysenlabs.com/projects/1rgs-claude-code-proxy)Was this useful?