ChatTTS: A dialogue-focused TTS model with fine-grained prosody control
GitHub describes it as A generative speech model for daily dialogue.. The repository metadata lists Python as its primary language. The metadata lists the AGPL-3.0 license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- ChatTTS is a generative speech model built for conversational text-to-speech, supporting English and Chinese with controllable laughter, pauses, and interjections. This review covers its architecture, setup, licensing, and the trade-offs you should know before adopting it.
- Who is it for?
- Adopt ChatTTS if you need a research-grade, dialogue-oriented TTS with fine-grained prosody control and are comfortable with the AGPL-3.0 code license and the CC BY-NC 4.0 model license, which blocks commercial use. Do not adopt it if you need multi-emotion control (still on the roadmap), commercial deployment, or a fully optimized inference stack, since the README warns against installing FlashAttention-2 and TransformerEngine.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
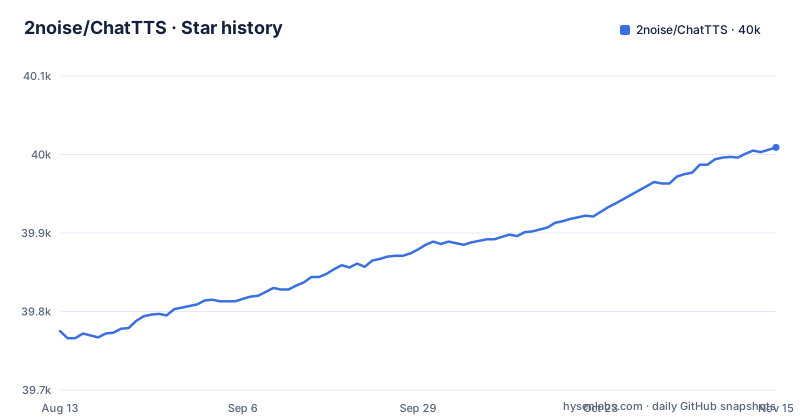
- 2noise/ChatTTS40,009 ★ · +234
| Repository | 2026-08-13 | 2026-11-15 |
|---|---|---|
| 2noise/ChatTTS | 39.8k | 40k |
234 Stars in the last 94 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What ChatTTS is for and who should look at it
ChatTTS is a text-to-speech model designed for dialogue scenarios, such as an LLM assistant. It is not a general-purpose audiobook or narration TTS. The README states it is optimized for dialogue-based tasks, enabling natural and expressive speech synthesis, and it supports multiple speakers for interactive conversations. The target user is a researcher or developer building a conversational agent who needs TTS that can produce varied, interactive-sounding speech rather than flat, single-speaker output. The model is trained on 100,000+ hours of Chinese and English audio, but the open-source release is a 40,000-hour pre-trained model without SFT, which means it is a base model, not a fine-tuned product. If you are looking for a production-ready voice for a commercial app, this is not it, partly because of the license, which we will get to later, and partly because the model is explicitly released for academic purposes.
The mechanism: fine-grained control over prosody
The core differentiator is fine-grained control. The documentation says the model can predict and control prosodic features including laughter, pauses, and interjections. The advanced usage example shows a parameter object, InferCodeParams, which takes a speaker embedding, temperature, top_P, and top_K. That suggests the model uses a sampling-based decoding process, likely over discrete codes, rather than a deterministic synthesis. The roadmap lists the DVAE encoder and a spk_stats file as open-sourced, and the advanced usage example samples a speaker from a Gaussian with sample_random_speaker(). This is a concrete mechanism: you can sample a speaker embedding, save it, and reuse it later for timbre recovery. That is a practical feature for dialogue systems where you want consistent voices across turns.
Getting it running: commands and configuration
There are several paths: install from PyPI with pip install ChatTTS, install from GitHub or a local directory, or clone the repo and install from requirements.txt. The README also shows a conda setup with Python 3.11. The quick start offers a WebUI, launched with python examples/web/webui.py, and a command-line inference that saves MP3 files: python examples/cmd/run.py "Your text 1." "Your text 2.". The basic Python usage is short: create a Chat() instance, call load(compile=False), then infer(texts). The compile flag is set to False for the example, with a note that True gives better performance, which implies a torch.compile path. The advanced usage shows how to sample a random speaker and pass it as spk_emb in InferCodeParams, along with temperature, top_P, and top_K. The setup is straightforward, but the README includes two warnings about optional packages: do not install FlashAttention-2 because it slows generation, and do not install TransformerEngine because it cannot run properly yet. Those are clear constraints for anyone with NVIDIA GPUs.
The wrong tool: cases where ChatTTS fails or is a poor fit
The most obvious limitation is the license. The code is AGPL-3.0, which has strong copyleft implications for any service that exposes the code over a network. The model is CC BY-NC 4.0, which explicitly forbids commercial use. The README states the model is for educational and research use only. That alone disqualifies ChatTTS for most commercial products. Another limitation is the roadmap: multi-emotion controlling is not done. So if you need a model that can express anger, sadness, or excitement beyond laughter and interjections, this is the wrong tool. The README also mentions that the authors added high-frequency noise during training and compressed audio quality with MP3 to prevent misuse. That means the output quality is deliberately degraded. If you need high-fidelity audio for production, this is a deal-breaker. Finally, the documentation is thin on the exact data flow and model architecture. The README says the repo contains the algorithm infrastructure and simple examples, and only links to an external diagram visualization of the codebase. For a reviewer, that means you cannot fully verify how the model works without reading the code yourself.
Alternatives: how other TTS models differ in approach
ChatTTS gives explicit parameters for speaker sampling and prosody, with a Gaussian-based speaker embedding. The README's roadmap marks open-sourcing the DVAE encoder and zero shot inferring code as done. Another alternative is the extended ecosystem listed in Awesome-ChatTTS, which includes community-built end-user products, but that is not a model comparison. For a direct comparison, you would need to look at each model's conditioning mechanism and whether it supports fine-grained prosody control.
Maintenance, upgrade cost, and the vLLM option
The latest release and the last push are both from April 2026, and the three most recent releases are dated February 2025, May 2025 and April 2026, so the cadence is slow. The roadmap lists ChatTTS.cpp as a desired new repository, which suggests the Python implementation may not be the final performance target. The upgrade cost is moderate: the basic usage example includes a try/except block for torchaudio.save, indicating that the API may change across torchaudio versions. You will need to test your environment. The optional vLLM installation is Linux only and pins vllm==0.2.7, so check it against the CUDA and PyTorch versions you use. The README explicitly warns against installing TransformerEngine and FlashAttention-2, so you should not expect to speed up inference with those. The maintenance burden is on you to pin dependencies and handle the torchaudio quirk. The license implications are clear: AGPL-3.0 for code means if you modify and deploy it as a network service, you must share your source. The CC BY-NC 4.0 model license is more restrictive, and the README adds a disclaimer that the authors do not guarantee accuracy or reliability.
What to verify before you commit
Before adopting ChatTTS, there are three things to check. First, the exact torchaudio version in your environment, because the save function's behavior changes between versions, and the README's workaround is not elegant. Second, the Hugging Face model card for the 40k-hour base model, because the README only gives a summary, and you need to know the exact input format and any known artifacts. Third, the status of the detection model that the authors say they trained internally. The README says they plan to open-source it, but it is not available yet. If you are building a system that needs to detect synthetic speech, you cannot rely on ChatTTS's own detector. Also, the README says the model is trained with MP3 compression and high-frequency noise, so test the audio quality on your target use case before you assume it is acceptable. The vLLM option is Linux-only and pinned to vllm==0.2.7, so if you are on Windows or want a newer vLLM, you are out of luck.
Editorial conclusion
Adopt ChatTTS if you need a research-grade, dialogue-oriented TTS with fine-grained prosody control and are comfortable with the AGPL-3.0 code license and the CC BY-NC 4.0 model license, which blocks commercial use. Do not adopt it if you need multi-emotion control (still on the roadmap), commercial deployment, or a fully optimized inference stack, since the README warns against installing FlashAttention-2 and TransformerEngine. Before adopting, verify the exact versions of PyTorch and torchaudio you plan to use, because the basic usage example includes a fallback path for torchaudio.save that implies version-dependent behavior. Also check the Hugging Face model card for the specific 40k-hour base model's limitations and the planned detection model, which is not yet released.
Frequently asked questions
how to install chattts
Three routes are given. pip install ChatTTS gets the stable version from PyPI, pip install git+https://github.com/2noise/ChatTTS gets the latest from GitHub, and pip install -e . installs a local checkout in development mode. From a clone you can instead run pip install --upgrade -r requirements.txt, or create a conda environment with python=3.11 first, which pulls in gradio and the Linux-only text processing packages that the package metadata omits.
what is chat tts
A generative speech model for daily dialogue, and a text-to-speech model designed specifically for dialogue scenarios such as an LLM assistant. It supports English and Chinese, handles multiple speakers for interactive conversations, and can predict and control fine-grained prosodic features including laughter, pauses and interjections. The repository itself is described as containing the algorithm infrastructure and some simple examples.
Is TTS free?
For ChatTTS specifically, the code is published under AGPLv3+ and the model under CC BY-NC 4.0, which the project states is intended for educational and research use and should not be used for commercial purposes. Formal enquiries about the model and roadmap go to [email protected]. The published checkpoint is a 40,000 hour pre-trained model without supervised fine-tuning, released for academic purposes only.
chattts vs kokoro
The README's introduction does not mention Kokoro or name any other text-to-speech system. What it does claim for ChatTTS is that it surpasses most open-source TTS models in terms of prosody, and what it discloses is that the released 40,000 hour model was deliberately trained with added high-frequency noise and MP3 compression to limit its misuse.
How do I use TTS with ChatTTS?
Instantiate ChatTTS.Chat, call load, then pass a list of strings to infer, which returns waveforms you save with torchaudio. Two ready-made entry points are documented as well: python examples/web/webui.py launches a web interface, and python examples/cmd/run.py takes text arguments and writes mp3 files to ./output_audio_n.mp3. Both commands must be run from the project root.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/2noise-chattts)Star history chart for your README
[](https://hysenlabs.com/projects/2noise-chattts)Was this useful?