Happy-LLM: A Free Chinese Tutorial That Builds a 215M LLaMA2 From Scratch
GitHub describes it as Happy-LLM: building large language models from scratch. The repository metadata lists Jupyter Notebook as its primary language. The metadata lists the NOASSERTION license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- Happy-LLM is a free, open-source Chinese tutorial from Datawhale that walks readers from NLP basics to a working 215M-parameter LLaMA2, covering pretraining, SFT, LoRA, RAG, and Agentic RL. The repository is a structured course with notebooks, PDFs, and PPTs, but its non-commercial license and Chinese-first material set clear boundaries for adoption.
- Who is it for?
- Adopt Happy-LLM if you are a Chinese-speaking student, researcher, or hobbyist who wants a structured, free path from NLP basics to training a small LLaMA2, and who can accept a non-commercial license. Do not adopt it if you need English material, commercial use rights, or a production-grade training framework.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 97 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
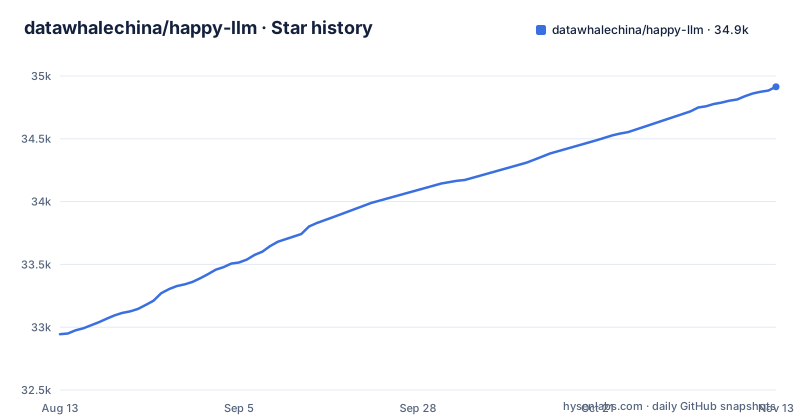
- datawhalechina/happy-llm34,914 ★ · +1,970
| Repository | 2026-08-13 | 2026-11-13 |
|---|---|---|
| datawhalechina/happy-llm | 32.9k | 34.9k |
1,970 Stars in the last 92 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Happy-LLM Actually Is
Happy-LLM is a systematic tutorial, not a software library. It is a collection of Jupyter notebooks and markdown documents that teach large language model theory and practice, organized into eight chapters plus an extra blog section. The target reader is someone who has basic Python skills and some familiarity with deep learning, but who has never built a language model from scratch. The project explicitly positions itself as a follow-up to Datawhale's self-llm guide, which covers how to use existing models. Happy-LLM goes one level deeper: it explains how a model is constructed and trained. The repository includes a downloadable 215M-parameter LLaMA2 base model and a supervised fine-tuned version, both hosted on ModelScope, so you can inspect or run a real model without training it yourself. This is a learning resource with a concrete artifact, which is rare among tutorials.
How the Content Is Structured
The course is split into two halves. Chapters 1 through 4 cover theory: NLP basics, the Transformer architecture, pretrained language model families, and the definition and training strategy of large language models. Chapter 2 includes a hand-built Transformer implementation, and Chapter 5 moves to building a LLaMA2 in PyTorch, including training a tokenizer and pretraining a small model. Chapter 6 introduces the Transformers framework for more efficient training, covering pretraining, supervised fine-tuning, and LoRA/QLoRA. Chapter 7 covers evaluation, RAG, and agents. Chapter 8 focuses on Agentic RL methods: GRPO, OPD, Search-R1, and ReTool. The structure is linear but the README says you can read selectively. The extra chapter is a collection of contributed blog posts on topics like fine-tuning small models, multimodal concatenation, and generation methods. That mix of formal chapters and informal blogs gives readers both a curriculum and a window into current practice.
Getting It Running: Environment and Dependencies
To reproduce the code, you start with the learning and environment preparation document, which the README says contains chapter-specific dependency lists and hardware advice. The key instruction is to use a separate Python environment for each chapter to avoid version conflicts. This is a practical choice because the code moves from plain PyTorch in Chapter 5 to the Transformers framework in Chapter 6, and those libraries may have different dependency requirements. The README does not give a single install command; you have to read the per-chapter documents. The repository provides PDF and PPT versions of the tutorial, which can be downloaded from the releases page. The PDF includes a Datawhale watermark to deter resale, which tells you the authors expect the document to circulate. The 215M models are available on ModelScope, and there is a ModelScope Space for interactive testing of the SFT model. That means you can try the model without local GPU resources, but training it yourself will likely require a GPU with sufficient memory, though the exact requirement is not stated in the README.
The 215M LLaMA2: A Concrete Learning Artifact
Chapter 5 is the centerpiece: you implement a LLaMA2 model from scratch in PyTorch, train a tokenizer, and pretrain a small language model. The repository provides two pretrained checkpoints on ModelScope: a base model and an SFT model, both 215M parameters. The SFT model is also available in a ModelScope Space, so you can chat with it in a browser. This artifact is what separates Happy-LLM from purely theoretical textbooks. You are not just reading about attention; you can see the model that came out of the tutorial's code. The download links are explicit, and the release notes for v1.0.2 mention a PPT release, indicating the project is actively maintained.
Limitations: Language, License, and Scope
The most obvious limitation is that the entire tutorial is in Chinese. There is an English README (README_en.md). That excludes a large portion of the global developer audience. The license is CC BY-NC-SA 4.0, which is a non-commercial license. That means you cannot use the material in a paid course or a commercial product without permission. The README explicitly says the PDF is watermarked to prevent resale, which confirms the authors' intent. Another limitation is that the scope is educational, not production. The 215M model is for learning, not for deployment. Chapter 8 covers Agentic RL, but the README points to a separate repository, agentic-rl-lab, for more algorithms and training code. So if you want to go beyond the tutorial's coverage, you have to switch projects. The project is also notebook-based, which is fine for learning but not a substitute for a training framework like Axolotl or Lit-GPT.
Alternatives: How Happy-LLM Differs
The closest alternative is the Hugging Face course, which covers Transformer usage and fine-tuning with the Transformers library, but it does not build a model from scratch. Happy-LLM's Chapter 5 does exactly that: it implements LLaMA2 in PyTorch, which is a different pedagogical approach. Another alternative is Andrej Karpathy's nanoGPT, which is a minimal GPT implementation in PyTorch. nanoGPT is more code-focused, with less theoretical explanation, and it targets GPT, not LLaMA2. Happy-LLM provides a broader curriculum, including RAG and Agentic RL, which nanoGPT does not. For Chinese readers, there is also Li Mu's 'Hands-On Deep Learning' (Dive into Deep Learning), which covers Transformer but not LLM training workflows like LoRA. Happy-LLM's unique angle is the combination of a full course and a trainable small model, all in Chinese, with a community-driven extra chapter. The choice depends on whether you want theory with a guided project or a minimal codebase to experiment with.
Maintenance, Community, and Upgrade Cost
The repository is active. The last push was August 8, 2026, while the latest release v1.0.2 is from January 29, 2026. The project has two named maintainers, both Datawhale members, and a list of extra chapter contributors. The README invites contributions, with a PR guideline for the extra blog section. The maintenance model is community-driven, which means content quality varies across the extra chapter. The upgrade cost for a learner is low: you read the docs and run the notebooks. The main cost is environment setup, because each chapter may require a different Python environment. The project does not have a packaging system or a CLI, so there is no version upgrade path in the software sense. You simply pull the latest repository state or download the latest PDF release. The release notes indicate a PPT release.
Editorial conclusion
Adopt Happy-LLM if you are a Chinese-speaking student, researcher, or hobbyist who wants a structured, free path from NLP basics to training a small LLaMA2, and who can accept a non-commercial license. Do not adopt it if you need English material, commercial use rights, or a production-grade training framework. Before committing, verify that your hardware meets the requirements in the environment preparation chapter, and check the release PDF for the latest content. The repository is maintained, with a release as recent as January 2026, but the license is CC BY-NC-SA 4.0, which prohibits commercial redistribution, so confirm that fits your use case.
Frequently asked questions
What is Happy-LLM from Datawhale?
It is a free and open-source tutorial for understanding how large language models work and training them yourself, running from basic NLP concepts through the Transformer and pretrained language model architectures to hands-on work. The README describes it as a systematic LLM learning tutorial that starts from basic NLP research methods and works layer by layer into architecture and training.
Do I need to install anything to use Happy-LLM?
Not to read it, since the material is a book with notebooks, available through an online reading address, a free PDF and a separate set of teaching slides. To run the code, the README tells you to read the environment preparation page first, because the repository splits dependencies by chapter and each chapter is advised to use its own Python environment to reduce version conflicts.
What licence is Happy-LLM under?
The README states Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International, so the material is free to read and share with attribution, but the non-commercial term restricts commercial reuse and adaptations carry the same licence.
Which models does Happy-LLM provide?
Two, both from chapter 5 and both hosted on ModelScope: Happy-LLM-Chapter5-Base-215M and Happy-LLM-Chapter5-SFT-215M, the base and the supervised fine-tuned versions of a 215 million parameter model. A ModelScope studio link is also given for trying the SFT model.
How current is the Happy-LLM material?
The last push to the repository was 2026-08-08 and the newest release tag is v1.0.2 from 2026-01-29, which published the teaching slides, after v1.0.1 from 2025-07-27. For agentic reinforcement learning the README sends you to a separate repository, agentic-rl-lab, which it says is updated more frequently.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/datawhalechina-happy-llm)Star history chart for your README
[](https://hysenlabs.com/projects/datawhalechina-happy-llm)Was this useful?