Subs AI puts eight speech backends behind one subtitle pipeline
🎞️ Subtitles generation tool (Web-UI + CLI + Python package) powered by OpenAI's Whisper and its variants 🎞️
At a glance
- What is it?
- Subs AI is a subtitle generation tool that ships a Streamlit web UI, an argparse CLI and a Python package, and its real product is the backend matrix: openai-whisper, faster-whisper, whisper.cpp, whisperX, stable-ts, whisper-timestamped, Hugging Face transformers and the OpenAI API are all selectable with the same flag. Around transcription it adds translation, ffsubsync re-timing and subtitle merging, at the cost of a pinned dependency set and a Python 3.11 ceiling.
- Who is it for?
- Adopt Subs AI if you transcribe more than one file at a time, if you need translation or re-timing after transcription, or if you want to compare backends on the same file before choosing one for production, because switching is a flag and the output format is the same. Do not adopt it if you have a single video and a machine with a modern Python, where calling the whisper CLI directly is less work and fewer dependencies.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
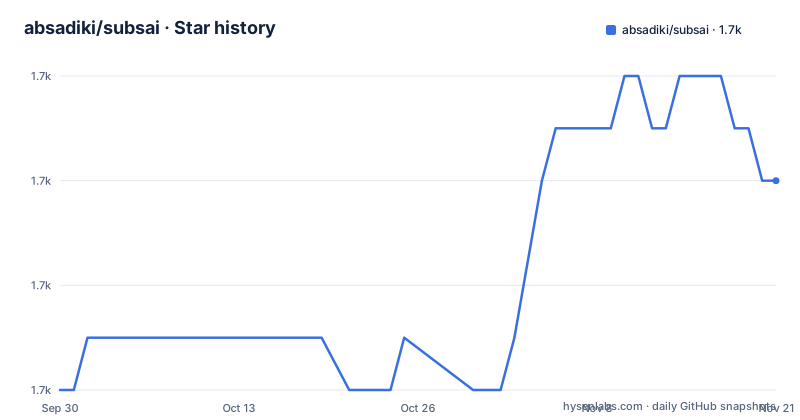
- absadiki/subsai1,682 ★ · +4
| Repository | 2026-09-30 | 2026-11-21 |
|---|---|---|
| absadiki/subsai | 1.7k | 1.7k |
4 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Eight backends, one flag
The feature list opens with supported models, and it is the most useful part of the documentation. openai/whisper is the reference implementation. linto-ai/whisper-timestamped adds word-level timestamps with confidence. ggerganov/whisper.cpp is reached through the author's own pywhispercpp wrapper, a plain C and C++ implementation that runs on the CPU. guillaumeknl/faster-whisper is the CTranslate2 reimplementation, which the README describes as up to four times faster for the same accuracy with less memory, further improved by 8-bit quantization on CPU and GPU. m-bain/whisperX adds batched inference at 70x realtime with large-v2, word-level timestamps through wav2vec2 alignment, speaker diarization through pyannote-audio, and voice activity detection to reduce hallucination. jianfch/stable-ts modifies Whisper to produce more reliable timestamps. Hugging Face transformers is there for any pretrained model on the hub, and the OpenAI API backend covers hosted inference or any OpenAI-compatible endpoint. One interface, -m, across all of them.
Picking a backend is the decision you are actually making
The choice follows from your hardware and your tolerance for bad timestamps. If you have no GPU and no appetite for it, whisper.cpp through pywhispercpp is the CPU path, with no dependency beyond the C library. If you have a GPU and care about throughput, faster-whisper is the default choice, and its 8-bit path is what makes a modest card viable. If you need to know who spoke when, whisperX is the only option in the list, at a stated cost of under 8GB of GPU memory for large-v2 with beam_size=5, and it depends on pyannote-audio for the diarization labels. If your problem is subtitles drifting out of sync, the answer is not a better model but stable-ts or whisper-timestamped, both of which exist to fix timestamp quality. And if you would rather not host a model at all, the API backend removes the GPU question entirely and replaces it with a network dependency. The CLI takes the model with -m and its settings with -mc, so experimenting is a flag change rather than a rewrite.
requirements.txt is a time capsule, and it sets the Python ceiling
The dependency file is the honest description of the project's constraints, and the pins are load-bearing rather than tidy. numpy is held below 2, and torch and torchaudio are fixed to the same release:
numpy<2
torch==2.2.0
torchaudio==2.2.0
Around them sit openai-whisper at a dated nightly build, transformers 4.48.1, stable-ts 2.18.2, pywhispercpp 1.3.1, the openai client 1.60.1, pandas 1.5.3, and whisperX installed straight from GitHub at a fixed commit hash. Two of the comment lines say the reason out loud, that these are there to avoid problems with dependency versions. The consequence reaches the README's install note, which recommends Python 3.10 or 3.11 and warns that 3.12 or later may have compatibility issues, even though pyproject declares a floor of 3.8. That combination is worth internalising: this is a project whose Python support is set by the oldest pinned scientific stack it carries, and on a machine with a current interpreter the install is where you will find out.
The torch CPU wheel trap, issue 162
One failure mode is documented well enough to save you an afternoon. If torch fails to detect your GPU while you are running Subs AI, and you do have a supported device, the likely cause is that pip installed the CPU version of torch, and the README points you at PyTorch's own guide for getting a CUDA build. The reference is issue 162. This is not a Subs AI bug so much as a packaging reality: the default wheel resolution on a machine without the right index configuration will happily give you a working torch that cannot see the GPU, and the error surfaces later as a slow transcription rather than at import time. The same family of problem appears during installation, where the quoted upstream guidance notes that rust may be needed if the tokenizers package has no pre-built wheel for your platform, along with the setuptools_rust fallback. The practical order is therefore: install ffmpeg, pin an interpreter at 3.11, install torch for your hardware first, then install the tool.
Install is ffmpeg, then pip from git
There is no wheel to download from a package index, the documented install is from the repository, and it requires the ffmpeg command line tool first. The README quotes the upstream Whisper installation guidance for each platform, and the Linux line is the one most people need:
# on Ubuntu or Debian
sudo apt update && sudo apt install ffmpeg
with the equivalents given for Arch, macOS through Homebrew, Windows through Chocolatey and Windows through Scoop. Then the package itself:
pip install git+https://github.com/absadiki/subsaiInstalling from git rather than from a release index means you get whatever is on the default branch at that moment, and since the repository publishes no GitHub releases, the pyproject version of 1.6.2 is the only version marker there is. Two entry points are installed, subsai for the command line and subsai-webui for the browser interface. The project is usable as a library too, and the examples folder contains two notebooks, subsai_translation.ipynb and subsai_vad.ipynb, which is the fastest way to see how the translation and voice activity paths are meant to be called from Python.
The web UI is Streamlit, and offline depends on your backend
Starting the interface is one command, and a page opens in your default browser:
subsai-webuiThe feature list calls it fully offline with no third party services, and that is true of the application itself: the Web UI ships as a local page, works on Linux, Mac and Windows, supports editing the subtitles after transcription, and integrates translation, auto-sync and merging. The dependency list shows the implementation, with streamlit, streamlit_player and streamlit-aggrid pinned alongside pandas. The offline claim has one asterisk, which is the backend you choose: selecting the OpenAI API model sends your audio to someone else's endpoint, and the README notes that any OpenAI-like API works, naming speaches.ai as an example of a self-hosted one. The translation path is local by default, going through dl_translate with four Meta models available, from nllb-200-distilled-600M up to m2m100_1.2B. Auto-sync uses ffsubsync, which is the piece that fixes subtitles whose timing drifted during translation.
Docker ships two services and one base image pin
The compose file defines two services built from the same Dockerfile, subsai-webui with an nvidia GPU device reservation and subsai-webui-cpu without one, so the CPU path is a supported deployment rather than an accident. The Dockerfile is where the operational detail sits. It is based on a pinned PyTorch runtime image, pytorch/pytorch:2.0.1-cuda11.7-cudnn8-runtime, installs gcc and mono-mcs, installs the pinned requirements file, then installs the package itself, exposes port 8501, and starts Streamlit with the file watcher disabled and usage statistics gathering turned off. Two things are worth checking before you trust the GPU service. The base image carries torch 2.0.1 with CUDA 11.7 while requirements.txt asks pip for torch 2.2.0, and those are independently chosen pins, so the CUDA runtime available to the installed wheel is the thing to verify on your hardware. And a container with a fixed CUDA base will need a rebuild, not a pull, when either of those pins moves.
Six subtitle formats, a library, and the alternative of no wrapper
Output formats come from pysubs2, and the list covers SubRip, WebVTT, substation alpha, MicroDVD, MPL2 and TMP, which is enough to feed a player, a player with styling, or an editor without conversion. The CLI exposes the rest of the surface as flags: -f for the format, -df for a destination folder, -tm and -tc for the translation model and its configuration, -tsl and -ttl for the source and target language. The alternative is to skip the wrapper. openai-whisper and whisper.cpp both have command line tools that take a file and write a subtitle file, with none of the translation, re-timing or merge steps and none of the pinned stack, and for a single file that is the faster path. What the wrapper buys is the comparison: running the same audio through two backends with the same output format is the only reliable way to find out which one your corpus suits, and that is a job no single-backend tool can do. The licence is GPL-3.0, the package version is 1.6.2, the documentation is built with mkdocs from a docs directory, and the last push to the repository was 2026-04-20.
Editorial conclusion
Adopt Subs AI if you transcribe more than one file at a time, if you need translation or re-timing after transcription, or if you want to compare backends on the same file before choosing one for production, because switching is a flag and the output format is the same. Do not adopt it if you have a single video and a machine with a modern Python, where calling the whisper CLI directly is less work and fewer dependencies. Verify four things before your first run: that Python is 3.10 or 3.11 rather than 3.12 or newer, that pip installed a CUDA build of torch rather than the CPU wheel, which the README links to issue 162 for, that ffmpeg is on your PATH, and that the pinned versions in requirements.txt still resolve together, since torch, torchaudio, transformers and numpy are held at specific versions to avoid conflicts. The project is GPL-3.0, the package version is 1.6.2, and the last push was 2026-04-20.
Frequently asked questions
Which Python version does Subs AI support?
The install note recommends Python 3.10 or 3.11 and warns that 3.12 or later may have compatibility issues, because requirements.txt holds numpy below 2 and pins torch and torchaudio to 2.2.0. pyproject declares a floor of 3.8.
How do I install Subs AI?
Install ffmpeg first, for example sudo apt update && sudo apt install ffmpeg on Debian or Ubuntu, then run pip install git+https://github.com/absadiki/subsai. The repository publishes no GitHub releases, so the install always comes from the default branch.
Which speech recognition backends does Subs AI support?
Eight, selectable with the -m flag: openai-whisper, linto-ai/whisper-timestamped for word-level timestamps and confidence, whisper.cpp through pywhispercpp for CPU inference, faster-whisper, whisperX for diarization and alignment, stable-ts, Hugging Face transformers, and the OpenAI API or any OpenAI-compatible endpoint.
Why is my GPU not detected by Subs AI?
The README says the likely cause is that pip installed the CPU version of torch, and points to PyTorch's local install guide for a CUDA build, with issue 162 referenced for the details. It also notes that Python 3.12 or later may have compatibility issues.
Does Subs AI translate subtitles and fix their timing?
Yes. Translation goes through dl-translate with four Meta models available, and auto-sync uses ffsubsync. The Web UI also supports editing the subtitles and merging them into the video, and the CLI exposes translation model, configuration and language flags.
Can I run Subs AI without a GPU?
Yes. The compose file defines a subsai-webui-cpu service alongside the GPU one, and the whisper.cpp backend through pywhispercpp is a plain C and C++ implementation that runs on the CPU.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/absadiki-subsai)Star history chart for your README
[](https://hysenlabs.com/projects/absadiki-subsai)Was this useful?