PyTorch: the tape is the API, and setup.py is on its way out
PyTorch is a Python package for GPU-accelerated tensor computation and deep neural networks built on a tape-based autograd system, extensible via NumPy and SciPy.
At a glance
- What is it?
- Two headline features, a NumPy-style tensor with GPU acceleration and reverse-mode autograd that records while your Python runs. What the repository shows in detail is the build: scikit-build-core has replaced setup.py, one MAX_JOBS variable feeds every parallel sub-build, and the Docker image defaults to the nightly wheel channel.
- Who is it for?
- PyTorch fits a team that writes its own layers and wants a stack trace pointing at the line it wrote.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
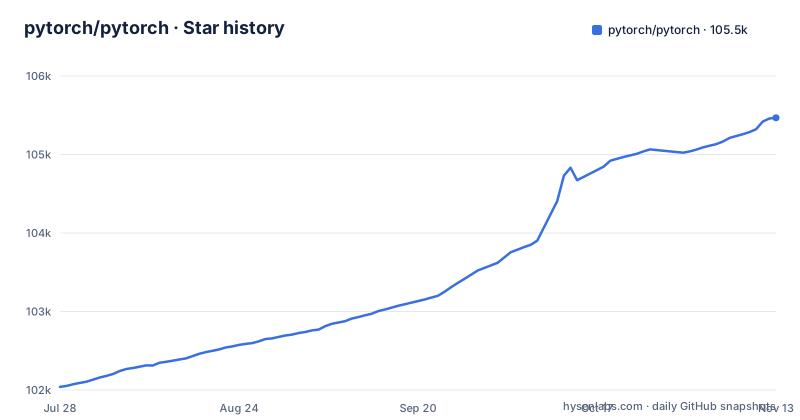
- pytorch/pytorch105,467 ★ · +3,428
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| pytorch/pytorch | 102k | 105.5k |
3,428 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The tape records as your Python runs, and autograd replays it in reverse
Networks are built here the way a tape recorder works. Operations execute and record themselves onto a tape, and reverse-mode auto-differentiation replays that tape backwards to produce gradients. The project contrasts this with a static view of the world in which a network is built once and reused, naming TensorFlow, Theano, Caffe and CNTK as frameworks that work that way, where changing how the network behaves means starting from scratch. The claim made for PyTorch is that behaviour can be changed arbitrarily with zero lag or overhead, and that the technique is not unique to this project even though the implementation is described as one of the fastest.
Consequence for the shape of your code: control flow stays in Python. A branch, a loop or an early return decides what lands on the tape, which is the opposite of declaring a graph up front.
Six subpackages, and the split tells you which one owns your problem
A component table divides the library into five parts with separate jobs. torch is the tensor library itself, with strong GPU support. torch.autograd is the tape-based automatic differentiation library, covering every differentiable Tensor operation in torch. torch.nn is the neural network library, described as deeply integrated with autograd and designed for maximum flexibility. torch.utils carries DataLoader and other utility functions, and torch.multiprocessing is Python multiprocessing with shared memory of torch Tensors across processes, which the table points at for data loading and Hogwild training.
Consequence: a question about where a tensor lives belongs to torch, a question about a gradient that never arrives belongs to autograd, and a question about sharing data between worker processes belongs to torch.multiprocessing.
Stack traces point at the line you wrote, because nothing runs ahead of you
The execution model is deliberately plain. When you execute a line of code it gets executed, with no asynchronous view of the world, and the argument offered for that choice is the debugger: the stack trace points to exactly where your code was defined, and the stated hope is that you never spend hours on bad stack traces or opaque execution engines. Underneath, acceleration libraries are integrated, with Intel MKL on the CPU side and cuDNN and NCCL from NVIDIA, over CPU and GPU backends described as mature and tested for years.
Consequence: stepping through a model in a debugger is an ordinary experience rather than a fight, which is why the project treats this as a design decision and not a convenience. The cost sits on the other side of the same choice. Nothing is captured unless the code path actually runs, so a forward pass skipped by a branch, or a tensor produced outside the recorded path, leaves you with a graph that is correct for the run you did and silent about the one you meant.
Layers are written in Python, and Cython and Numba are the way further
PyTorch is positioned as not a Python binding into a monolithic C++ framework but a library built to be deeply integrated into Python, used the way you would use NumPy, SciPy or scikit-learn, and written so you can put new neural network layers in Python itself. Cython and Numba are named as the route past that when Python is not enough, the stated goal being not to reinvent the wheel where that is appropriate, and existing Python packages such as NumPy and SciPy are meant to be reused rather than replaced.
Consequence: there is no separate plugin interface to learn, and the price of trying an idea is an edit and a re-run rather than a rebuild of a C++ extension. The trade appears in the tree instead. c10, aten, caffe2, functorch, cmake, android, binaries and benchmarks all sit at the top level, so native code goes through the same scikit-build-core build as the framework, and a change that touches it is a build change.
setup.py forwards to pip today and carries a published removal date
The build moved to the PEP 517 interface declared in pyproject.toml, where the backend is scikit_build_core.build. setup.py is still in the tree, but only as a stub for direct python setup.py calls: install and develop are forwarded to pip, and every other command fails with instructions. The file states its own schedule. PyTorch 2.14 to 2.15 forward install and develop to pip, 2.16 to 2.17 fail all commands with instructions, and 2.18 removes the file. The replacements it prints are:
install:           spin install  (or: pip install --no-build-isolation -v .)
editable install:  spin develop  (or: pip install --no-build-isolation -v -e .)
wheel:             python -m build --wheel --no-isolation
sdist:             python -m build --sdist
Consequence: a CI job or build script that calls python setup.py install keeps working through 2.15 and then fails on a version bump rather than on anything you changed. Build customization through environment variables such as DEBUG=1, USE_CUDA=0 and MAX_JOBS is stated to work unchanged with the replacements.
MAX_JOBS feeds CMake, the linters, the JIT and the nccl sub-builds at once
One variable does the parallelism work, and pyproject.toml wires it to the setting CMake honours for cmake --build:
CMAKE_BUILD_PARALLEL_LEVEL = { env = "MAX_JOBS" }The comment beside it names every reader: the linters, the cpp_extension JIT, and the nccl and MKLDNN sub-builds, plus the umbrella knob itself. It also gives the precedence rule, that setdefault semantics mean a CMAKE_BUILD_PARALLEL_LEVEL you export yourself always wins. The parent [tool.scikit-build] table pins minimum-version to build-system.requires, so the schema and defaults track the scikit-build-core version the project builds against, and sets build-dir to build.
Consequence: you cannot hand the JIT a different job count from the linters or from the nccl and MKLDNN builds, so a machine short on memory for native builds has to be tuned through one variable that reaches everything at once. The other direction works the other way round: a CMAKE_BUILD_PARALLEL_LEVEL you export yourself always wins, so it sets the CMake build's job count while MAX_JOBS still reaches the linters, the JIT and the sub-builds.
The image defaults to ubuntu:24.04, cu121 and the nightly wheel channel
The Dockerfile names ubuntu:24.04 as its base image and notes that building needs docker version 23.0 or newer. Stages chain: dev-base installs build-essential, cmake, git, python3-dev and ccache, then removes the PEP 668 EXTERNALLY-MANAGED marker, described as safe in containers; python-deps installs the development requirements; submodule-update runs git submodule update --init --recursive; pytorch-installs picks a wheel index from build arguments, defaulting to CUDA_PATH=cu121 and INSTALL_CHANNEL=whl/nightly. One exception is spelled out, since torchaudio does not publish wheels against the CUDA 13.2 index yet and is skipped when CUDA_PATH is cu132.
Consequence: an image built with no arguments tracks the nightly channel, so two builds a week apart are not the same build and a regression may have arrived in a wheel rather than in the commit. Pin INSTALL_CHANNEL for a repeatable image. A second platform wrinkle sits in requirements.txt, where lintrunner is skipped when platform_machine is s390x, which leaves a development environment on that architecture with no lint step rather than a different one. The trunk itself is not archived, the last push landed on 2026-11-02, and v2.15.0 shipped on 2026-10-28 after v2.14.1 on 2026-09-30 and v2.14.0 on 2026-09-02.
Editorial conclusion
PyTorch fits a team that writes its own layers and wants a stack trace pointing at the line it wrote. Two things to check before adopting it as a build dependency: setup.py stops forwarding pip in 2.16 and disappears in 2.18, so any script that shells out to python setup.py install has to move to spin or python -m build, and MAX_JOBS is the one knob read by the linters, the cpp_extension JIT and the nccl and MKLDNN sub-builds at once, which means you cannot tune them separately. If you only need tensors on a GPU, a prebuilt wheel is the cheaper path, and hud.pytorch.org is where to look before blaming your own code for a broken build.
Frequently asked questions
Is PyTorch a Python library?
It is a Python package offering two high-level features: tensor computation like NumPy with strong GPU acceleration, and deep neural networks built on a tape-based autograd system. Existing Python packages such as NumPy, SciPy and Cython are meant to be reused to extend it.
What is the difference between PyTorch and TensorFlow?
PyTorch records operations onto a tape as your Python runs and replays it in reverse for gradients, so you can change how a network behaves without rebuilding it. The README names TensorFlow, Theano, Caffe and CNTK as frameworks with a static view, where a network is built once and reused.
How do I use the PyTorch DataLoader?
torch.utils holds DataLoader and other utility functions. Data loading that needs to share tensors between processes goes through torch.multiprocessing, Python multiprocessing with shared memory of torch Tensors across processes, which the component table also points at for Hogwild training.
How do I install PyTorch with CUDA?
The README's from-source section lists NVIDIA CUDA support alongside AMD ROCm support and Intel GPU support as separate prerequisites. The repository Dockerfile picks its wheel index from build arguments, defaulting to CUDA_PATH=cu121 and INSTALL_CHANNEL=whl/nightly, and skips torchaudio when CUDA_PATH is cu132.
How do I start using PyTorch?
The README links a basics tutorial at pytorch.org and describes the library either as a replacement for NumPy that uses the power of GPUs, or as a deep learning research platform offering flexibility and speed. It also points at hud.pytorch.org for the trunk's continuous integration signals.
Official sources
Where this project is recommended
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 2 in the last 30 days; newest first.
- Jensen is out. CUDA isn't. A Developer's Guide to Everything Nvidia Builtdev.to · Nov 13, 2026 · 7 points · 2 comments
- Fine-Tuning Gemma 4 on an 8 GB RTX 3050: Slow, Low End and Still Viabledev.to · Oct 21, 2026 · 4 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pytorch-pytorch)Star history chart for your README
[](https://hysenlabs.com/projects/pytorch-pytorch)Was this useful?