manga-image-translator: a detect, OCR, translate and inpaint pipeline you have to run from main
Translate manga/images: one-click translation of text in various kinds of images. https://cotrans.touhou.ai/ (no longer working)
At a glance
- What is it?
- zyddnys/manga-image-translator translates text inside manga and other images and redraws it in place, with Japanese as the main source language. Its last tagged release dates from 2022, its hosted demos are unreliable, and a local install pulls in a C++ build step, so self-hosting from the main branch is the realistic path.
- Who is it for?
- manga-image-translator fits readers and scanlation hobbyists who can run Python 3.12 with a GPU stack and want image boards or group chat comics translated in place, mostly from Japanese. It does not fit anyone who wants a stable versioned release or a hosted service they can count on, since the last tag is beta-0.3 from 2022 and the original homepage no longer works.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
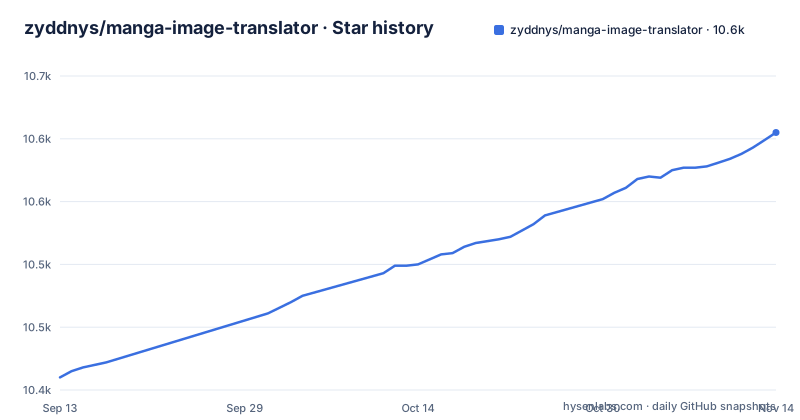
- zyddnys/manga-image-translator10,605 ★ · +195
| Repository | 2026-09-13 | 2026-11-14 |
|---|---|---|
| zyddnys/manga-image-translator | 10.4k | 10.6k |
195 Stars in the last 62 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Text is detected, read, translated, erased and typeset in one pass
The project targets images that nobody will translate professionally: comics and pictures passed around group chats and image boards. It mainly handles Japanese, and also supports Simplified and Traditional Chinese, English and 20 other minor languages. A run chains several stages, and the configuration file has a section for each: detector, OCR, translator, inpainter (the text removal step), render for typesetting, upscale and colorizer. Each stage can be swapped by option. The showcase uses `--detector ctd` for one sample and `--translator none` for another, and each sample is paired with the mask image the pipeline produced. Fonts ship in the fonts/ directory, and the Docker image installs GIMP because one rendering path goes through it. The project calls itself v2 of an earlier OCR effort, Qiú wén zhuǎn yì zhì, and states that it is still early in development with many shortcomings.
The newest tag is beta-0.3 from April 2022
Version tags stopped long ago. The recent releases are beta-0.3 on April 23, 2022, beta-0.2.1 in July 2021 and alpha-v3.0.0 in May 2021, while the main branch received its last push on October 11, 2026. pyproject.toml still reports version 0.1.0. The practical consequence is that there is no versioned build that matches current behavior: you install from main and get whatever is there that day. The online demo runs the latest main as well, so it offers no stable reference point either. Even the showcase images carry a warning that they may not represent the current main branch. If you need reproducible output for a long project, record the commit hash you installed and do not upgrade casually, because nothing in the release history will tell you what changed between two points on main.
The hosted versions cannot be relied on
The repository homepage, cotrans.touhou.ai, is marked in the project description as no longer working. A separate official demo is maintained by zyddnys at touhou.ai/imgtrans, and a browser script maintained by QiroNT is published on Greasy Fork as script 437569. The demo comes with its own caveat: if it is unreachable, the cause may be Google GCP restarting the server, and the advice is to wait for the service to come back. For a casual reader that is acceptable. For anyone translating a batch of chapters, it means the hosted options can disappear mid task with no status page or timeline, and the only dependable setup is a local or Docker install on your own hardware. The project also publishes run_as_colab.ipynb and run-as-kaggle.ipynb at the repository root for running on hosted notebooks instead of a local GPU.
A local install needs Python 3.12 and a C++ compiler
The recommended local route is pip inside a venv, with separate notes for Windows users. pyproject.toml sets requires-python to 3.12 or newer, so older interpreters are out. The heavier surprise is in requirements.txt: pydensecrf is installed from a git branch, zyddnys/pydensecrf at fix/python313-cython3, and is built from source for Python 3.13 and Cython 3 fixes, which requires a C++ compiler. Without one, pip install -r requirements.txt fails partway through. The same file pins torch==2.14.1 and torchvision==0.29.1, and adds an extra index at frederik-uni.github.io for rusty-manga-image-translator==0.12.1, so installs behind a strict package mirror need that host allowed. AMD and Intel GPU users have their own files, requirements-rocm.txt and requirements-xpu.txt. Launch helpers run.sh and run.bat sit at the repository root.
The Docker build downloads models and keeps going when a step fails
The Dockerfile starts from pytorch/pytorch:2.14.1-cuda12.6-cudnn9-runtime, installs g++, git, ffmpeg, GIMP and a few libraries, installs requirements.txt, then removes g++ and git again. Models are prepared during the build by docker_prepare.py with the --continue-on-error flag, using a BuildKit cache mounted at /.cache/models, and the copy commands around it end in || true. That design saves bandwidth on rebuilds, but it also means a finished image is not proof that every model arrived in /app/models; a failed download does not stop the build. Check the build log before trusting a fresh image. The image sets PYTHONPATH to /app and its entrypoint runs the manga_translator module, so arguments passed to docker run go straight to the translator CLI. The README covers a web server mode with an Nvidia GPU variant, CLI use, and building the image locally.
docker-compose.yml starts only the front end
Running docker compose up in the repository root does not give you a working translator. docker-compose.yml defines a single service, front, built from the front/ directory with NODE_ENV set to production and port 3000 published. The translation backend from the Dockerfile is not part of that compose file, and the server/ directory sits beside it as separate code. The consequence is a web page on port 3000 with nothing behind it until you start the translator in one of its server modes yourself. The CLI exposes several: local batch mode, web mode with an old and a new UI, API mode with its own documentation, WebSocket mode options, and a config-help mode. A docker-compose.debug.yml file also exists at the root. Plan on wiring the frontend to a backend you run separately rather than treating compose as a one-command install.
Translator backends pull in several cloud SDKs
requirements.txt pins client libraries for several translation services at once: deepl==1.32.0, openai==3.28.0, groq==1.7.0 and google-genai==2.29.0, along with ctranslate2==4.8.2. websockets is held at 16.1.1 because later releases conflict with google-genai. Every install carries all of them whether you use one backend or none. Quality controls go beyond picking a translator: there is a glossary feature, a replacement dictionary, a GPT configuration reference, a summary of environment variables, and a sakura_dict.txt file plus a dict/ directory at the root. OCR for Japanese can draw on manga-ocr==0.1.16, which is pinned in the same file. The cost of carrying every SDK is a larger environment and more pinned versions that can collide with other packages you install next to it, as the websockets pin already shows.
The Rust port is easier to install but not feature complete
Manga Image Translator Rust, maintained at frederik-uni/manga-image-translator-rust, ships as a compiled binary and is pointed to as the version that may be easier to set up. It is not a full replacement: stable diffusion has not been rewritten in it yet. The Python project already depends on part of that work through the rusty-manga-image-translator wheel, so the two codebases are linked rather than competing. The license is GPL-3.0-only for the Python repository, which matters if you plan to bundle it into a distributed tool. The README was last updated on 2025/05/10, while the code kept moving through October 2026, so options listed in the README may lag behind what main accepts; the config-help mode is the place to confirm current settings.
Editorial conclusion
manga-image-translator fits readers and scanlation hobbyists who can run Python 3.12 with a GPU stack and want image boards or group chat comics translated in place, mostly from Japanese. It does not fit anyone who wants a stable versioned release or a hosted service they can count on, since the last tag is beta-0.3 from 2022 and the original homepage no longer works. Before installing, check that you have a C++ compiler for pydensecrf, the right requirements file for your GPU vendor, and enough disk for the models the Docker build downloads.
Frequently asked questions
How do I install manga image translator?
Use pip inside a venv with Python 3.12 or newer, or build the Docker image from the repository Dockerfile. The pip route compiles pydensecrf from source, so a C++ compiler must be present.
How do I use manga image translator once it is installed?
Run it in local batch mode on a folder of images, or start web mode, API mode or WebSocket mode to serve requests. Detector, OCR, translator, inpainter and render settings are chosen by command line options or a configuration file.
Can manga-image-translator translate Japanese characters from an image?
Yes. Japanese is its main source language: it detects the text, reads it, translates it, removes the original lettering and typesets the translation into the image.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zyddnys-manga-image-translator)Star history chart for your README
[](https://hysenlabs.com/projects/zyddnys-manga-image-translator)Was this useful?