Trafilatura: A Python and CLI Tool for Turning Raw HTML into Clean Text and Metadata
Python & Command-line tool to gather text and metadata on the Web: Crawling, scraping, extraction, output as CSV, JSON, HTML, MD, TXT, XML
At a glance
- What is it?
- Trafilatura is a Python package and command-line tool for crawling, scraping, and extracting main text and metadata from web pages. It targets researchers and developers building corpora, RAG pipelines, or news aggregators who need reliable extraction without a database.
- Who is it for?
- Adopt Trafilatura if you need a self-contained, rule-based extractor that prioritizes precision and recall for main text and metadata, especially for corpus building, NLP, or RAG workflows. It is a poor fit if you require heavy JavaScript rendering or a full scraping framework with built-in scheduling and storage.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
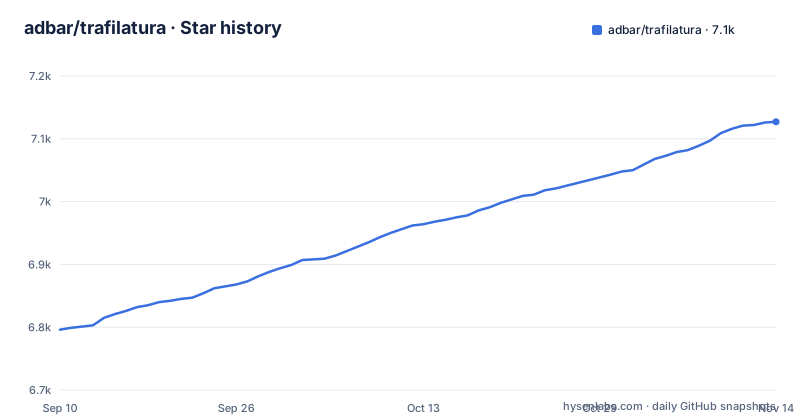
- adbar/trafilatura7,126 ★ · +330
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| adbar/trafilatura | 6.8k | 7.1k |
330 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Trafilatura Solves and Who Needs It
Trafilatura addresses a specific pain: raw HTML is full of navigation, ads, and boilerplate that obscure the actual article or page content. The tool extracts the main text and metadata such as title, author, date, site name, and categories, filtering out recurring elements like headers and footers. This is for anyone building text corpora, news aggregators, or retrieval-augmented generation (RAG) pipelines where clean, structured text is the foundation. The README frames it as a comprehensive package and command-line tool that handles crawling, downloads, scraping, and extraction, all without requiring a database. That modular, no-database design is a deliberate contrast to heavier scraping frameworks that impose storage or queue infrastructure.
The Extraction Mechanism: Rule-Based with Fallbacks
The core extraction logic is a rule-based extractor, not a machine-learned model. The README says it uses its own rule-based extractor with jusText and readability-lxml as fallbacks. That means the tool applies heuristics to identify content blocks, likely based on HTML structure, text density, and tag patterns. It aims to balance precision (excluding noise) and recall (including all valid parts). The design is configurable: you can toggle optional elements like comments, links, images, and tables, and enable add-ons for language detection and speed optimizations. This rule-based approach is both a strength and a limitation. It can be fast and predictable on typical article pages, but it may struggle with unusual layouts where a machine-learning model might generalize better. The fallbacks provide a safety net, but they are still algorithmic.
Crawling and Input Handling: Sitemaps, Feeds, and Parallel Queues
Trafilatura is not just an extractor; it includes discovery and crawling components. According to the README, it supports sitemaps in TXT and XML formats and feeds in ATOM, JSON, and RSS. It also performs smart crawling with URL filtering and deduplication. For downloading, it offers parallel processing of live URLs with an efficient and polite download queue, meaning it can handle rate limiting and concurrent requests. It can also process offline input: previously downloaded HTML files and parsed HTML trees. This dual mode is practical for corpus builders who may have archived pages locally. The Python API example shows a simple flow: fetch_url downloads the page, extract returns the text. That simplicity is appealing.
Getting Started: Installation and Basic Usage
The README points to the quickstart guide and installation page for detailed steps, but the core usage is visible in the Python example. You install the package via pip (the PyPI badge indicates it is available as trafilatura). Then you import the fetch_url and extract functions. The example shows a two-step process: download the HTML with fetch_url, then call extract on the downloaded string. With no arguments, extract returns plain text. To get structured output, you pass output_format='json' and with_metadata=True, which yields a JSON object with fields like title, author, and text. The README links to a separate documentation page for command-line usage. The tool supports multiple output formats: TXT, Markdown, CSV, JSON, HTML, XML, and XML-TEI. This makes it easy to integrate into existing pipelines, whether you need Markdown for a blog or TEI for scholarly text encoding.
Performance and Benchmark Claims
The README makes strong claims about evaluation. It states that Trafilatura consistently outperforms other open-source libraries in text extraction benchmarks. It cites a ScrapingHub article extraction benchmark where it was the most efficient open-source library, a French-language study that called it the best overall tool, and a 2023 paper by Bevendorff et al. that gave it the best single tool score by ROUGE-LSum Mean F1 Page Scores. These are external evaluations, not self-reported numbers, which lends credibility. However, the README does not provide raw benchmark numbers or methodology details. The actual benchmark data and code are in the repository under tests, and the documentation has an evaluation section. If you are evaluating this tool for your own use, you should run your own tests on representative pages, because benchmark results on news articles may not transfer to forums, product pages, or JavaScript-heavy sites.
Limitations and When It Is the Wrong Tool
The most obvious limitation is that Trafilatura is not designed for sites that require JavaScript execution to render content. The README describes processing of raw HTML, so if a page loads its article via client-side scripts, the extractor will see an empty shell. Another limitation is the rule-based nature: it may be less adaptable than machine-learning approaches for highly varied layouts, though the fallbacks help. The tool also does not include a database, which is a feature for simplicity but a constraint for large-scale crawling where you might need persistent state. For such cases, you would have to build your own storage layer.
Alternatives and How They Differ
The README explicitly names two fallback extractors: jusText and readability-lxml. These are direct alternatives in the same niche. jusText is a simpler, rule-based boilerplate removal tool that focuses on paragraph-level classification. The key difference is that Trafilatura integrates crawling, metadata extraction, and multiple output formats into one package, while jusText and readability-lxml are focused on the extraction step alone. If you only need to clean a single HTML page, readability-lxml might be lighter. But if you need sitemap crawling, feed parsing, and structured output, Trafilatura provides that out of the box. Another broader alternative is Scrapy, which is a full web scraping framework; Scrapy gives you more control over requests, pipelines, and middlewares, but you would pair it with an extractor like Trafilatura to get clean text.
Licensing, Maintenance, and Upgrade Cost
Trafilatura is distributed under the Apache 2.0 license, which is permissive for commercial use. However, the README notes that versions prior to v1.8.0 are under GPLv3+. That is a crucial distinction for anyone maintaining old code or using a version pinned before that release. If you are upgrading from an older version, you may need to review license implications, though this is not legal advice. The project is actively maintained, with recent releases in 2026 (v2.3.1, v2.3.0 and v2.2.0). The last push was October 2026, indicating ongoing development. The README mentions that the project started as a PhD project and that its future depends on community support. This means maintenance depends on community contributions and sponsorship, which is a risk for long-term adoption. The upgrade cost is likely low for a Python library, but you should check the changelog for breaking changes between major versions, especially since v2.0.0 was a major release.
Editorial conclusion
Adopt Trafilatura if you need a self-contained, rule-based extractor that prioritizes precision and recall for main text and metadata, especially for corpus building, NLP, or RAG workflows. It is a poor fit if you require heavy JavaScript rendering or a full scraping framework with built-in scheduling and storage. Before adopting, verify that its extraction quality meets your content types by testing on your target sites, check the output formats you need (TXT, Markdown, JSON, XML-TEI are available), and confirm that the Apache-2.0 license is compatible with your project, especially since versions before v1.8.0 are GPLv3+.
Frequently asked questions
What is the Trafilatura library?
A Python package and command-line tool that gathers text from the web and turns raw HTML into structured data. It does crawling, downloading, scraping and extraction of main text, metadata and comments, and needs no database.
How to install trafilatura?
It is published on PyPI under the name trafilatura, so pip install trafilatura adds it to an environment. The metadata requires Python 3.10 or newer, and the documentation keeps a dedicated installation page.
how to use trafilatura
Call fetch_url to download a page and pass the result to extract, which returns the main text as a string. Adding output_format="json" together with with_metadata=True returns title, author and text as structured data instead.
is trafilatura open source
Yes. It is distributed under the Apache 2.0 license, while versions prior to v1.8.0 were under GPLv3+. The repository also carries a CONTRIBUTING page and an issue tracker.
trafilatura vs readability
They sit at different layers: readability-lxml is one of the fallback extractors trafilatura calls when its own rule-based extractor does not fit a page. Use trafilatura for crawling, formats and metadata, and reach for readability when you want that single algorithm on its own.
What are the advantages of Trafilatura compared to BeautifulSoup?
Trafilatura decides what the content of a page is, strips headers, footers and boilerplate, and pulls out metadata, formatting and optional elements such as comments, links, images and tables. It also crawls sitemaps and feeds and deduplicates URLs, which is more than a parser does.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/adbar-trafilatura)Star history chart for your README
[](https://hysenlabs.com/projects/adbar-trafilatura)Was this useful?