Soup: YAML-driven LLM fine-tuning with layer streaming for 4 GB GPUs, and a v0.77 that refuses what it used to warn about
Fine-tune LLMs from one YAML. Layer streaming trains an 8B model on a 4 GB laptop GPU.
At a glance
- What is it?
- Soup (soup-cli on PyPI) is an Apache-2.0 command line tool that fine-tunes and post-trains LLMs from a single YAML config. Its headline feature, opt-in layer streaming, fits Llama-3.1-8B training into a 4 GB laptop GPU, and its recent releases tighten config validation enough that upgrades need a check first.
- Who is it for?
- Soup fits people who want to run LoRA, QLoRA or GRPO fine-tuning from a YAML file on their own hardware, including owners of small laptop GPUs willing to use beta layer streaming, and Apple Silicon users who want GRPO through MLX. It fits poorly if you are on Python 3.14 or 3.10, or need a tool whose configs stay valid across minor versions without review, since the project labels itself Alpha.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
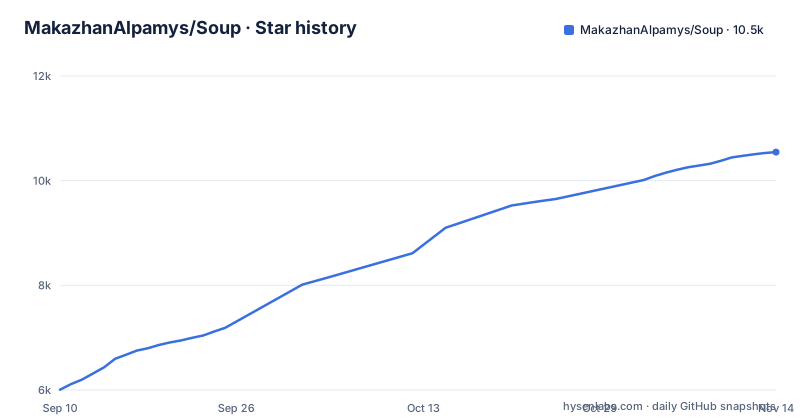
- MakazhanAlpamys/Soup10,545 ★ · +4,540
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| MakazhanAlpamys/Soup | 6k | 10.5k |
4,540 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Layer streaming keeps the frozen base model out of VRAM
Soup's most distinctive mechanism is layer streaming. During fine-tuning, the frozen base model stays out of GPU memory, and Soup feeds it to the GPU one decoder layer at a time. That is what lets it train Llama-3.1-8B-Instruct with NF4 quantization on an RTX 3050 Laptop with 4 GB of VRAM. On v0.72.2 that run, using LoRA at batch 1 and sequence length 512, peaked at 3.32 GB and reached 119.6 tok/s at a 952 MHz clock, and the output was bit-exact against a normal resident run. An independent run on an H100 reached 113.00 tok/s in the same 3.32 GB.
Streaming is opt-in and marked beta. You turn it on with `stream_layers: true` in the config. A Colab notebook, `notebooks/proof-4gb.ipynb`, runs on a free T4, caps the process to 4 GB, and asserts that a streamed model is bit-identical to a normal one, so you can check the claim yourself.
The faster post-repair number is a clock difference, not a speedup
The project is unusually careful about what its benchmark does not show, and readers should be too. The 119.6 and 113.00 tok/s figures predate the v0.73.0 correctness repair, which cost 4.8 percent at 32B. A post-repair run on another RTX 3050 Laptop 4 GB reads 208.6 tok/s in a 2.40 GB peak, but at 1935 to 1957 MHz rather than 952 MHz.
That run reaches 59 percent of its same-session GEMM ceiling, against 68 percent before, which works out to about 14 percent slower per unit of clock. The raw 1.74x gain comes from the clock. Large-layer streaming also changed the memory pattern between the two runs, so even the ceiling fraction is not a like-for-like comparison. The consequence: do not plan training time from the 208.6 figure. Measure on your own card, and treat the memory peak, not throughput, as the reason to use streaming.
The default install is a light CLI with no PyTorch
Since v0.71.0, Soup splits its package. A bare `soup-cli` install gives you the CLI, the config system and the data tools, without PyTorch. The training stack, torch, transformers, peft, trl, datasets, bitsandbytes and accelerate, sits behind the `[train]` extra. The quick start installs the extra, creates a config from a template and trains:
pip install "soup-cli[train]"   # add [train] to fine-tune; bare `soup-cli` is the light CLI
soup init --template chat
soup train
If you install without the extra, `soup train` has nothing to train with. The split is useful on machines that only prepare data with `soup data` commands such as `dedup`, `filter`, `convert`, `merge`, `sample`, `pii` and `toxicity`, where pulling in the full training stack would be wasted download and disk.
Python 3.14 and 3.10 are both refused
The package declares `requires-python = ">=3.11,<3.14"`, and the ceiling is deliberate. CI tests 3.11, 3.12 and 3.13 and nothing above. Without the upper bound, pip on 3.14 resolves torch wheels the project has never run, and the failure is a loader crash inside c10.dll or libc10.so before any Soup code executes, leaving the user with no Soup error message to act on. A test derives the bound from the CI matrix, so the two cannot drift apart. Python 3.10 support was dropped when 3.13 joined, after 3.10 reached end of life on October 1, 2026.
If your environment runs 3.14, or an older system Python 3.10, you need a separate interpreter for Soup. On 3.10, pip does not fail loudly: it quietly installs an older soup-cli whose bounds still admit 3.10, so you can end up on 0.76.x without noticing.
v0.77 turns earlier warnings into refusals
v0.77.0 refuses settings that v0.76 warned about or ignored. A config that loaded on 0.76.x can stop loading after the upgrade. The recommended first step when coming from 0.76.x is:
soup doctor --config soup.yamlv0.77.1 extends the same strictness. `soup plan` and `soup apply` now refuse the configs `soup train` refuses, with the same message, and write no plan. Eighteen `soup data` commands refuse an `--output` that is the same file as an input, under any spelling, before reading anything. External programs now start only from an absolute path found on `PATH`, so a tool that lived in the current directory or a relative `PATH` entry needs its directory added. The same release lets `task: grpo` with `backend: mlx` train GRPO natively on Apple Silicon, and `soup infer --backend mlx` generates without Torch. The package classifies itself as Development Status 3, Alpha, and breaking tightenings like these are the practical meaning of that label.
The pre-flight VRAM estimate is calibrated only for dense models up to about 3.5B
`soup train`'s pre-flight check, `soup profile` and `soup plan` share one peak-VRAM estimate, calibrated on 39 measured runs. Inside the range it was fitted on, dense models up to about 3.5B parameters, it now refuses some long-sequence, large-vocabulary runs it used to let through.
Outside that range, the estimate is weaker and the behaviour changes. For a larger model, a mixture-of-experts model, `medium` or `selective` checkpointing, `use_liger` or `use_cut_ce`, or `backend: unsloth`, a run that does not fit gets only a warning and starts anyway. It is refused only when the weights, CUDA context and the gradients and optimizer state of trained parameters exceed the card, such as a 7B full fine-tune on 80 GB or Llama-3.1-70B in 4-bit on 24 GB. LoRA and partial-training runs are judged on fewer terms. So for big or MoE models, a pass from the pre-flight is not a promise; `--allow-oom-attempt` launches a refused run if you want to try.
The Docker build stops unless you pin SOUP_VERSION
The Dockerfile builds on `nvidia/cuda:12.8.2-runtime-ubuntu24.04` with Ubuntu's Python 3.12 in a virtual environment, and asserts the interpreter is within 3.11 to 3.13 before downloading any wheel. Ubuntu 22.04 was rejected because its Python 3.10 would make pip silently install an older soup-cli, so an image tagged 0.77.0 would hold 0.76.x. It installs a released soup-cli from PyPI, never the local source, and there is no default version. A local build must pass one:
docker build --build-arg SOUP_VERSION=0.77.0 .With compose, the equivalent is `SOUP_VERSION=0.77.0 docker compose build`; unset, the build stops. Pulling the published `ghcr.io/makazhanalpamys/soup:latest` image needs no argument. The compose file reserves all NVIDIA GPUs, mounts the current directory at `/workspace`, and sets `ipc: host` for PyTorch multiprocessing, so it assumes an NVIDIA host.
Editorial conclusion
Soup fits people who want to run LoRA, QLoRA or GRPO fine-tuning from a YAML file on their own hardware, including owners of small laptop GPUs willing to use beta layer streaming, and Apple Silicon users who want GRPO through MLX. It fits poorly if you are on Python 3.14 or 3.10, or need a tool whose configs stay valid across minor versions without review, since the project labels itself Alpha. Before upgrading from 0.76.x, run soup doctor against your config, and before trusting the pre-flight memory check, confirm your model sits in the dense, up to about 3.5B range it was fitted on.
Frequently asked questions
What does Soup's layer streaming do?
It keeps the frozen base model out of VRAM and feeds it to the GPU one decoder layer at a time. It is opt-in with stream_layers: true and still beta.
Does pip install soup-cli include PyTorch?
No. Since v0.71.0 the bare soup-cli install is a light CLI with the config system and data tools. Fine-tuning needs the [train] extra, which brings torch, transformers, peft, trl, datasets, bitsandbytes and accelerate.
Which Python versions does Soup support?
soup-cli requires Python 3.11, 3.12 or 3.13. Python 3.14 is excluded because untested torch wheels crash at load time, and 3.10 support was dropped.
Can Soup train on Apple Silicon?
As of v0.77.1, task: grpo with backend: mlx trains GRPO natively on Apple Silicon using Soup's own MLX loop, and soup infer --backend mlx generates from MLX bases without Torch.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/makazhanalpamys-soup)Star history chart for your README
[](https://hysenlabs.com/projects/makazhanalpamys-soup)Was this useful?