amitness/learning: a personal curriculum log, not a learning platform
A log of things I'm learning
At a glance
- What is it?
- The repository is a Markdown table of courses, books and video series with progress markers, updated roughly once a month. It is useful as a template for structuring self-directed study and useless as a library, a dataset or a tool.
- Who is it for?
- Adopt this repository only as a structural template: copy the table format and the generic-versus-adjacent split, then replace every row with your own resources. Do not treat it as a curated recommendation list, because the README shows completion markers without any evaluation of the material.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 13 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
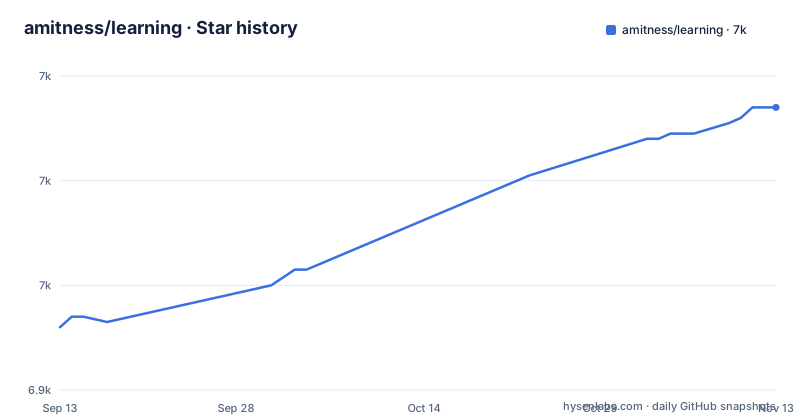
- amitness/learning6,994 ★ · +42
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| amitness/learning | 7k | 7k |
42 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What amitness/learning actually is
The README opens by describing the repository as "a running log of things I'm learning", aimed at building strong fundamentals while expanding knowledge of adjacent technologies. That sentence is the whole product. There is no package to install, no module to import, no CLI. The repository is a set of Markdown tables with columns for format, resource, length and progress, and the progress column uses checkmark and empty-square symbols to mark completion. The stated update cadence is once a month, and the stated current focus is Generative AI. If you are looking for code that trains a model or processes text, this is the wrong repository. The audience is one person: the author. The secondary audience is anyone who wants to see how another engineer organises a multi-year self-study plan and is willing to copy the structure.
The generic versus adjacent split
The organising idea visible in the README is a division between Generalized Skills, described as "domain-agnostic, stack-independent skills", and everything else. The generic block contains System Design, Maths, Data Structures and Algorithms, Data Modeling, Design Sense, and Linux and Command Line. The README cites two external articles to justify the approach: one on mastering adjacent disciplines and one on continuous improvement. The split is a real editorial decision, and it carries a cost. Grouping A/B testing, OAuth, REST API design, linear algebra and Figma illustration under one heading means the section has no single learning path. A reader cannot work through Generalized Skills in order because the rows are not sequenced by dependency. The tables are inventories, not syllabi. That is fine for a personal log where the author already knows why each row is there, and it is a problem for anyone who copies the file expecting the order to mean something. The one signal about sequencing is the progress column: some rows are checked, some are empty, and at least one row uses an hourglass symbol, which suggests an in-progress state distinct from complete and not-started.
Reading the progress column without overreading it
Progress is encoded with symbols rather than text, and the tables do not define them. A checkmark appears next to completed items. An empty square appears next to items that are not complete. An hourglass appears next to Advanced Algorithms, where the length column reads 1/7. The fraction and the hourglass together imply partial completion, but the tables carry no legend, so the exact meaning of each symbol has to be inferred. This matters if you plan to fork the repository and continue the log, because you will inherit an undocumented convention. Two other columns are similarly loose. The length column mixes units freely: pages for books, hours for DataCamp courses, and lesson fractions for Udacity and Neetcode courses. A row reading 5/5 next to a Udacity course and a row reading 4h next to a DataCamp course are not comparable quantities, yet they sit in the same column. The format column is more consistent, using Book, Udacity, Udemy, Datacamp, Neetcode, edX, MIT, Youtube, Pluralsight, Course and Article as values. That inconsistency is not a defect for a personal log. It is a defect if you try to parse the file programmatically or aggregate the lengths.
Running it: clone, read, edit
There is nothing to build. The default branch is master, and the repository is not archived. The practical workflow is to clone it, open README.md in an editor, and edit the tables. A clone command would look like git clone https://github.com/amitness/learning, followed by cd learning. Because the content is Markdown, any editor works, and the tables render on GitHub without a build step. If you want to reuse the structure, the realistic path is to copy the table headers (Format, Resource, Length, Progress) and the section headings, then replace the rows. If you want to keep the progress symbols, define them somewhere in your own README, because these tables do not. The absence of any tooling is worth stating plainly: there is no script that checks links, no workflow that validates the Markdown, and no automation behind the monthly update. The cadence is a human habit, not a scheduled job. The repository has no published GitHub releases, which is consistent with a documentation-only repository.
What the log does not tell you
The most important limitation is that completion is the only recorded signal. A checkmark next to a book means the author finished it, not that the book was good, current, or suitable for anyone else. There is no rating column, no notes column, no date column. You cannot tell from the README whether a completed course was worth the hours. Several rows point at material that ages quickly: an AWS Certified Developer Associate course labelled 2018, and a Udacity catalogue that has changed shape over the years. Because the update cadence is monthly but the rows are not dated, a reader cannot distinguish a resource added last month from one added years ago. There is also no coverage of how the author decides what to add. The README links to a continuous improvement article, but the selection criteria are not written down. For a reader, this means the repository is a snapshot of one person's choices at an unknown mix of dates. Treating it as a vetted curriculum imports assumptions the file does not support. The MIT licence permits reuse, but it does not make the resource list accurate or current.
Alternatives and the difference in approach
The obvious alternative is a curated awesome-style list, such as the many awesome-machine-learning repositories on GitHub. The difference is editorial stance. An awesome list is written for an audience: entries are selected to be broadly useful, and the maintainer usually accepts contributions and applies some inclusion criteria. This repository is written for one person, and the progress column only makes sense to that person. A second alternative is a structured course catalogue with prerequisites and ordering, such as a university syllabus or a roadmap-style repository. Those impose a sequence. This one does not, which is why Generalized Skills can hold linear algebra and Figma illustration side by side. A third alternative is a spaced-repetition or note-taking tool where each completed resource produces an artifact: summaries, flashcards, code. This repository produces no artifact beyond the checkmark. If your goal is to retain what you study, a log of completed titles is weaker than a set of notes, and the README does not claim otherwise. The honest comparison is that this repository is a well-maintained personal index, and the alternatives are either audience-facing lists or output-producing study systems.
Maintenance cost and licence
The maintenance burden for the author appears to be low: edit a Markdown file once a month. For a forker, the burden is higher than it looks. Every link is a dependency. Udacity, DataCamp, Udemy and Pluralsight all change their catalogues, retire courses and move URLs, and none of that is validated by anything in the repository. A forked copy will accumulate dead links unless someone checks them. The MIT licence is permissive and, per the repository metadata, applies to the whole project. That means you can copy the tables into your own repository, modify them and redistribute them, provided you keep the licence notice. It does not grant any rights to the linked courses, books or videos, which remain under their own terms. This is a description of the licence identifier, not legal advice; if you plan to republish the tables at scale, read the LICENSE file in the repository and the terms of each linked provider. The absence of a release history also means there are no versioned snapshots to pin against, so any fork starts from whatever master contains on the day you clone it.
Editorial conclusion
Adopt this repository only as a structural template: copy the table format and the generic-versus-adjacent split, then replace every row with your own resources. Do not treat it as a curated recommendation list, because the README shows completion markers without any evaluation of the material. Anyone expecting installable code, a dataset or an API will find none. Before reusing it, check the last push date against the resources you intend to keep, and confirm the MIT licence text in the repository before republishing any part of the tables.
Frequently asked questions
What does the amitness/learning repository actually contain?
Two files: README.md and LICENSE. The README is a Markdown log of courses, books and videos grouped under headings such as System Design, Maths, Data Structures and Algorithms, Data Modeling, Design Sense and Linux & Command Line. Nothing is executable, and the repository has no releases.
How often is the amitness/learning list updated?
The README header states Updated: Once a month and names Generative AI as the current focus. The last push to the repository was on 2026-11-01, and the licence file is MIT.
Does the amitness/learning repository have any install steps?
No. There is no package manifest, no Dockerfile and no install command, and the top level of the repository holds only LICENSE and README.md. GitHub records no primary language for it, so there is nothing to build or run.
How does amitness/learning record progress on a resource?
Each row has a Format, Resource, Length and Progress cell. The progress cell holds a tick for finished items and an empty box for untouched ones, with an hourglass marking an entry in progress, such as Advanced Algorithms, whose Length is written as the fraction 1/7.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/amitness-learning)Star history chart for your README
[](https://hysenlabs.com/projects/amitness-learning)Was this useful?