antlr/grammars-v4: a grammar library for ANTLR v4 with no embedded actions
Grammars written for ANTLR v4; expectation that the grammars are free of actions.
At a glance
- What is it?
- antlr/grammars-v4 is a collection of ANTLR v4 grammars organised one directory per language or file format. The design rule is that grammars stay free of actions, which keeps them reusable across target languages but pushes work into listeners and visitors.
- Who is it for?
- Adopt antlr/grammars-v4 when you need a starting grammar for a language or format you do not want to write from scratch, and you accept that you will supply the semantics yourself through listeners or visitors. Do not adopt it expecting a parser: the repository holds grammars, and the README states the expectation that they are free of actions, so nothing here evaluates or interprets what it parses.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly ANTLR, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
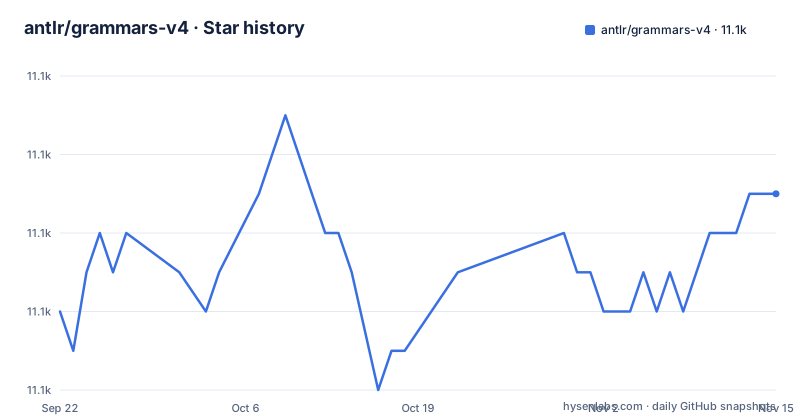
- antlr/grammars-v411,059 ★ · +3
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| antlr/grammars-v4 | 11.1k | 11.1k |
3 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What antlr/grammars-v4 actually contains
The repository is a collection of formal grammars written for ANTLR v4. The README states the naming convention directly: the root directory name is the all-lowercase name of the language or file format parsed by the grammar, with java, cpp, csharp and c cited as examples. The top-level listing follows that rule literally, from abb and abnf through ada, algol60, awk, basic, bcpl, bibtex, bison and beyond. There is no package index and no single grammar file at the root. You navigate by directory name.
The stated expectation is that the grammars are free of actions. That single sentence shapes everything about how the project is used. An action is target-language code embedded inside a grammar rule, and a grammar carrying actions is bound to one target. A grammar without them describes syntax only. The semantics live in whatever listener or visitor you write afterwards, in whichever language you generated into.
Why action-free grammars matter when you generate for several targets
ANTLR v4 generates parsers in more than one target language, for example Python, C++ or TypeScript. A grammar with embedded actions cannot serve all of them: the action text is copied into the generated parser verbatim, so a Java expression inside a rule breaks a Python build. Keeping actions out is what makes one .g4 file usable across targets.
The cost is real. Every piece of meaning you need, such as building an AST, resolving a symbol, or evaluating an expression, has to be attached after parsing through the generated listener or visitor interfaces. For a small configuration format that is a few lines. For a full programming language it is the bulk of the work, and the grammar only gets you to a parse tree.
Cloning antlr/grammars-v4 and taking one grammar
There is no package to install. The README points to the repository itself, and the top-level entries are directories, so the unit you take is a single grammar directory. Clone the repository and look at what is inside the one you need.
git clone https://github.com/antlr/grammars-v4.gitEach language directory, such as bibtex or java, is the unit to look inside first, and its contents list is the first thing to read. The README does not document a per-grammar install step, so if a directory carries extra build files, read them rather than assuming a single command is enough. The README does link a grammar performance table for comparing grammars, which is the closest thing to a per-grammar status page.
The maintenance question: a large tree with uneven per-grammar coverage
The last push to the default branch was on 2026-10-30, and the README links a CI badge for the last PR merge build plus weekly .jar and dev builds. So the repository as a whole moves. That does not mean every grammar in the tree is equally exercised. The tree is large, and a grammar for a niche format may have been contributed once and touched rarely since.
This is the practical risk of a collection organised by directory rather than by release. The repository has no published GitHub releases, so there is no version number to pin and no changelog to read when a grammar changes under you. If you depend on one grammar, keep your own copy of the .g4 file in your tree and diff it against upstream deliberately, rather than tracking master and discovering the change at build time.
Where this is the wrong tool
If you need to parse a format whose semantics are the point, such as evaluating arithmetic or executing a configuration, the grammar alone will not get you there. The action-free expectation means the repository deliberately stops at syntax. A project that wants a working interpreter out of the box is looking at the wrong repository, and the effort to build the listener layer is easy to underestimate before you start.
A second case: if your language changes frequently, a contributed grammar is a snapshot, not a specification. You will be maintaining the .g4 file yourself. And if you only need to read one small, stable format, writing a hand-rolled parser may be less total work than learning ANTLR's grammar syntax, generating, and then writing the visitor on top.
How this differs from writing your own ANTLR grammar
The alternative is not another grammar library; it is starting from an empty .g4 file and writing the rules yourself. The difference in approach is that you would be encoding the language's syntax from its specification, deciding your own rule names and structure, and owning every ambiguity you introduce. That gives you a grammar shaped exactly to your needs and no dead rules.
Taking a grammar from antlr/grammars-v4 trades that control for a head start: the syntax is already described, and the directory may include test inputs you can reuse. The trade-off is that you inherit someone else's rule structure and any gaps in their coverage, and you have to read the grammar to find out what it does and does not accept. For a well-known language the head start is large. For a format you know intimately and that is small, it may not be worth the reading time.
Licence and the cost of keeping a grammar current
The repository is MIT licensed, which permits use, modification and redistribution provided the licence notice is preserved. That is permissive enough for commercial use. Note that the licence covers the repository's contents; it says nothing about the languages and formats the grammars describe, and a grammar for a proprietary format does not grant you any right to that format. That is a question for your own legal review, not something the repository answers.
Upgrade cost is low in the sense that there is nothing to upgrade: you copy a .g4 file and regenerate. It is higher in the sense that regeneration can change your parse tree shape if the grammar's rules changed, which can break listener code that assumed a particular structure. Regenerating after pulling a newer grammar is the moment to re-run whatever tests you have against your listener, not just the parser.
Editorial conclusion
Adopt antlr/grammars-v4 when you need a starting grammar for a language or format you do not want to write from scratch, and you accept that you will supply the semantics yourself through listeners or visitors. Do not adopt it expecting a parser: the repository holds grammars, and the README states the expectation that they are free of actions, so nothing here evaluates or interprets what it parses. Before relying on any single grammar, check its directory for a test corpus and read the grammar file for the target you generate into, because coverage and target support differ per grammar.
Frequently asked questions
What are the four types of grammar?
The repository does not classify grammars into types. It is a collection of formal grammars written for ANTLR v4, one root directory per language or file format, and the README states the expectation that they are free of actions.
Is ANTLR still used?
The repository's last push to the default branch was on 2026-10-30, and the README links a CI badge for the last PR merge build along with weekly .jar and dev builds, so contributions and builds continue.
How does ANTLR work?
ANTLR v4 takes a grammar and generates a parser for a chosen target. In antlr/grammars-v4 the grammars are expected to be free of actions, so the meaning of what is parsed is added afterwards through a listener or visitor.
Can I use ANTLR with C#?
The repository contains a csharp directory alongside java, cpp and c, and ANTLR v4 supports generating for multiple targets. Whether a specific grammar works for your target depends on that grammar, so check the directory you need.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/antlr-grammars-v4)Star history chart for your README
[](https://hysenlabs.com/projects/antlr-grammars-v4)Was this useful?