Apify MCP Server: Wiring Thousands of Scrapers Into an MCP Client
The Apify MCP server enables your AI agents to extract data from social media, search engines, maps, e-commerce sites, or any other website using thousands of ready-made scrapers, crawlers, and automation tools available on the Apify Store.
At a glance
- What is it?
- The Apify MCP server exposes Apify Store Actors as tools an AI agent can call over the Model Context Protocol. It is a thin bridge, not a scraper: the value and the cost both live in the Actors behind it.
- Who is it for?
- Adopt it if your agent already needs to pull structured data from sites you do not want to maintain scrapers for, and you are willing to run each call as a paid Apify Actor. Skip it if you need a self-contained scraper, offline operation, or a fixed, auditable tool list.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
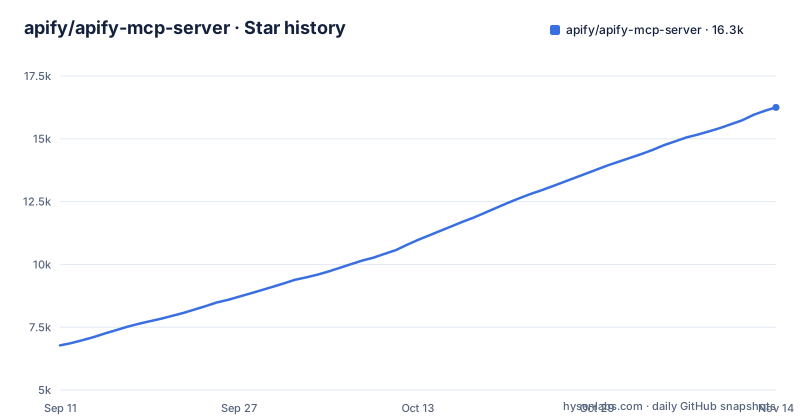
- apify/apify-mcp-server16,251 ★ · +9,475
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| apify/apify-mcp-server | 6.8k | 16.3k |
9,475 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The gap this fills: agents that need live web data
An agent with only a shell and an HTTP client can fetch a page, but it cannot reliably render JavaScript, rotate proxies, or survive an anti-bot challenge. The Apify MCP server takes that problem and hands it to Apify Store, where the README says thousands of ready-made scrapers, crawlers, and automation tools already exist. The server itself does not scrape anything. It translates between the Model Context Protocol and the Apify platform, so a client such as Claude Desktop, Cursor, or VS Code can call an Actor as if it were a local function.
The intended audience is narrow and specific. It is for teams already building on MCP clients who want web extraction without writing and maintaining per-site scrapers. The setup assumes: you have an Apify account, you accept that extraction runs on Apify infrastructure, and you want the agent to choose among tools rather than call one hardcoded endpoint.
How the Actor-as-tool mechanism actually works
The architecture is a relay. Your MCP client speaks the protocol to the server, the server maps a tool call onto an Apify Actor run, and the Actor returns a dataset or key-value output that the server passes back. The README says the agent searches Apify Store, checks an Actor's input and pricing, runs it, and reads the structured results, and that the server loads only what each task needs, which means tool discovery is dynamic rather than a fixed catalog compiled into the binary.
That dynamic discovery is the design decision worth noticing. A conventional MCP server ships a stable list of tools, and the model sees the same schema every session. Here the tool surface depends on which Actors are available and which tools you choose to load in the configurator.
Getting it running: hosted URL or npx
There are two supported paths. The hosted endpoint is https://mcp.apify.com over streamable transport. Because it supports OAuth, clients like Claude.ai or Visual Studio Code can connect with just the URL. Alternatively you send an Authorization: Bearer <APIFY_TOKEN> header.
The local path is stdio, run with the @apify/actors-mcp-server npm package and Node.js 22 or later. You set the client's server command to npx @apify/actors-mcp-server and supply the APIFY_TOKEN environment variable with your Apify API token.
Where it breaks down or is the wrong choice
The first limitation is the dependency chain. Every tool call is an Apify Actor run on Apify infrastructure, billed and rate-limited by your account. The server is MIT-licensed, but the license covers the bridge, not the Actors it invokes, and the README has the agent check an Actor's input and pricing before running it. An agent that decides to call a scraper in a loop can spend money without a human in the loop.
Second, the tool list is chosen per setup in the configurator, which makes behavior harder to reproduce across a team. If you need a fixed, auditable set of tools with deterministic schemas, a hand-written MCP server wrapping one or two endpoints is a better fit.
The alternative: a hand-rolled MCP server over your own fetch layer
The closest alternative is writing your own MCP server that wraps a small set of HTTP endpoints or a self-hosted crawler. The difference is where the work lives. With Apify MCP Server, you inherit thousands of maintained Actors but you also inherit Apify's runtime, billing, and account model, and the tool list is discovered at runtime. With a hand-rolled server, you own the extraction code, the schemas are fixed and versioned in your repository, and nothing leaves your infrastructure. You also own every anti-bot regression and every site redesign.
A second alternative is calling the Apify API directly from your agent's code instead of through MCP. You get the same Actors and the same billing, but you skip the protocol layer and its client-compatibility variance. The tradeoff is that you lose the drop-in integration with MCP clients, which is the entire reason this project exists. The choice is between a managed, broad, dynamic tool surface and a narrow, static, self-owned one.
Maintenance, versioning, and licence implications
The repository is TypeScript, MIT-licensed, and not archived. Recent releases are v0.20.1, v0.20.0, and v0.19.5, dated between 2026-10-27 and 2026-11-03. A 0.x version line means the maintainers have not declared API stability. Pin the version you run and read release notes before upgrading, because a transport change can silently break every client config in your team.
Upgrade cost is mostly configuration, not code, if you use the hosted endpoint: the server updates on Apify's side and your client keeps pointing at https://mcp.apify.com. If you run stdio via npx, you are pulling whatever version npx resolves unless you pin it, so an unpinned setup can change behavior between sessions. The MIT licence covers this server's source. It does not cover Apify Store Actors, and it says nothing about how the hosted service handles your data. The README has a privacy and license section, so read it before sending sensitive URLs through the hosted server.
Who should adopt it, and what to check first
Adopt it if your agent already lives in an MCP client, you need extraction from sites you have no intention of maintaining scrapers for, and you are comfortable with calls running as paid Apify Actors. The hosted endpoint is the version to start with, since the README's Quickstart is built around it.
Do not adopt it if you need offline operation, a fixed and auditable tool list, or extraction that never leaves your own infrastructure. Do not adopt it as a general-purpose scraper library either; it is a protocol bridge, and the scraping is somebody else's Actor.
What to verify first: confirm your client can reach https://mcp.apify.com with OAuth or an Authorization: Bearer header, decide between the hosted URL and npx @apify/actors-mcp-server with APIFY_TOKEN, and check how your Apify account is billed for the Actors your agent picks.
Editorial conclusion
Adopt it if your agent already needs to pull structured data from sites you do not want to maintain scrapers for, and you are willing to run each call as a paid Apify Actor. Skip it if you need a self-contained scraper, offline operation, or a fixed, auditable tool list. Before wiring it in, verify which transport your client supports, whether the hosted server at mcp.apify.com is acceptable for your data, and how your Apify account will be billed for the Actors your agent decides to invoke.
Frequently asked questions
What is the Apify MCP server?
A Model Context Protocol server that lets an AI assistant use any Apify Actor as a tool, so an agent can run scrapers for social media, search engines, maps or commerce sites. It is hosted at mcp.apify.com and is MIT licensed.
How do I install the apify-mcp-server?
Locally, set your MCP client server command to npx @apify/actors-mcp-server and the APIFY_TOKEN environment variable to your Apify API token. Node 22 or newer is required. Alternatively connect to the hosted endpoint at https://mcp.apify.com over streamable HTTP, or use a one-click install link from the configurator at mcp.apify.com.
Is Apify an MCP?
Apify is the platform whose Store holds the scrapers, crawlers and automation tools. The MCP server is the separate layer that exposes those Actors to an AI agent, and it is what speaks the protocol to clients like Claude Desktop, Cursor or VS Code.
What is the difference between Apify and apify-mcp-server?
Apify is the platform and its Store of Actors, while apify-mcp-server is the interface that lets an agent call those Actors as tools. The server depends on an APIFY_TOKEN, so it is the access layer for an agent rather than a replacement for the platform.
Is apify-mcp-server free?
The server code is MIT licensed. The README has the agent check each Actor's pricing before running it, and you sign in with an Apify account (a free one can be created), so a free server does not mean a free Actor run.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/apify-apify-mcp-server)Star history chart for your README
[](https://hysenlabs.com/projects/apify-apify-mcp-server)Was this useful?