ArchiveBox: A self-hosted web archiving tool that stores everything as plain files
🗃 Open source self-hosted web archiving. Takes URLs/browser history/bookmarks/Pocket/Pinboard/etc., saves HTML, JS, PDFs, media, and more...
At a glance
- What is it?
- ArchiveBox saves URLs as HTML, PDF, WARC, and more, keeping data in formats that do not require the tool to read them. This review covers how it works, how to run it, and where it may not fit.
- Who is it for?
- Adopt ArchiveBox if you need a self-hosted, multi-format web archiving system that stores data in standard files and folders, and if you can manage its dependency on external tools like Chrome, wget, and yt-dlp. Do not adopt it if you want a single-binary appliance with no external runtime dependencies, or if your archive must be fully reproducible without those tools.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
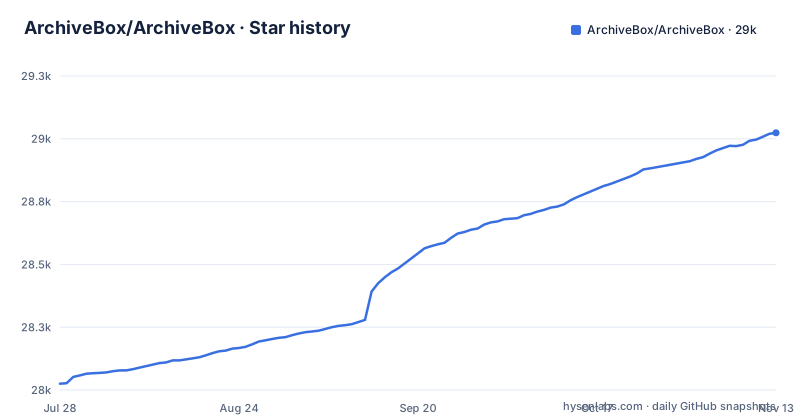
- ArchiveBox/ArchiveBox29,024 ★ · +999
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| ArchiveBox/ArchiveBox | 28k | 29k |
999 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What ArchiveBox actually preserves
The tool is aimed at individuals and organizations that want to preserve public or private web content while keeping control over the data. The README lists use cases: saving bookmarks, preserving evidence for legal cases, backing up photos from social media, saving research papers, and archiving media from YouTube or SoundCloud. It is not a general-purpose crawler like a search engine. It takes the URLs you feed it, one at a time or through scheduled imports, and docker-compose.yml shows add --depth=1 for following links one level deep. If you need to archive an entire website with millions of pages, ArchiveBox may not be the right fit. It is more suited to a curated collection of links that you want to keep accessible.
How the archiving pipeline works
The README describes ArchiveBox as using standard tools: Chrome, wget, and yt-dlp. Each URL is processed by a pipeline that invokes these external programs to produce different output formats. The dependency list makes the mechanism clear: ArchiveBox is a wrapper that orchestrates multiple specialized tools. The data flow is straightforward. You add a URL, ArchiveBox runs the tools, and the results land in a folder structure. The README mentions that the archive layout uses ordinary files and folders, and that you can access the collection via the CLI, web UI, Python API, or SQLite3. This design means that even if ArchiveBox stops being maintained, the archived files remain readable with standard software. That is a strong point for preservation, but it also means the archiving quality depends on the external tools being installed and kept up to date.
Installation and first run: Docker versus uv
The README gives four install options. The recommended one is Docker Compose. You create a data directory, download a docker-compose.yml from docker-compose.archivebox.io, then run docker compose pull and docker compose up -d --wait. The setup initializes a new collection automatically. After that, you open http://admin.archivebox.localhost:5797 to finish setup. To add a URL, you run docker compose run --rm archivebox add 'https://example.com'. The plain Docker route starts a container with the current directory mounted to /data and port 5797 published. The third option is installing via uv. The command is uv tool install --python 3.13 --prerelease explicit --upgrade 'archivebox>=0.9.0rc0,<0.10'. Then you run archivebox init, archivebox install, and archivebox add 'https://example.com'. There is also a curl shortcut script at get.archivebox.io. The key point is that the CLI and Docker methods access the same collection. The README says all ways of using it are equivalent. That means you can start with Docker for the web UI and later use the CLI on the same data folder.
The web interface and configuration keys
ArchiveBox runs a web server that exposes two UIs. The README mentions http://web.archivebox.localhost:5797 for the public interface and http://admin.archivebox.localhost:5797 for the admin interface. The BASE_URL environment variable controls the public base domain. The default 'auto' mode uses web. and admin. subdomains on *.localhost, but for ordinary DNS names it uses one host. The BIND_ADDR variable only controls the local listen address. That means the default setup is designed for local or internal use, not for direct public exposure. You would need to reverse-proxy and set BASE_URL properly if you want to publish the archive. docker-compose.yml also lists SERVER_SECURITY_MODE, PUBLIC_ADD_VIEW and optional ADMIN_USERNAME and ADMIN_PASSWORD, so the web layer is configurable through environment variables.
Input formats and scheduling
ArchiveBox accepts URLs from multiple sources. The README lists browser history, bookmarks, Pocket, Pinboard, social media feeds, RSS, and the browser extension. It can take URLs one at a time or schedule regular imports. The browser extension is a separate project, archivebox-browser-extension. The input flexibility is a major advantage if you already use a link-saving service or want to archive your entire browsing history. The README points to its Input Formats section for the full list of supported formats.
Output formats and the plain-file promise
The output formats are the core of ArchiveBox's value proposition. The README lists HTML, PNG, PDF, TXT, JSON, WARC, and SQLite as long-lived formats intended to remain readable by other tools. Long-term access still depends on intact backups, compatible software, and the preservation of needed content. The data is stored in a folder per snapshot, with each format as a separate file. The README emphasizes that the data is readable without running ArchiveBox. That is a strong contrast to tools that store everything in a proprietary database. If you ever stop using ArchiveBox, you still have the files. However, this approach has a cost: the archive takes more disk space because the same content is stored in multiple formats. For a large collection, this could be significant. Also, the WARC format is not human-readable without special tools, but it is a standard for web archiving.
Limitations and failure modes
ArchiveBox depends on external tools that must be installed and maintained. If Chrome is not installed, the screenshot and PDF extraction will fail. If yt-dlp is outdated, YouTube downloads may break. Another limitation is that the archiving quality varies by site. Dynamic pages that require heavy JavaScript may not render fully in headless Chrome, and sites with anti-bot protection may block the archiver. The README does not claim to handle every site. Also, the project is under active development, with pyproject.toml at version 0.9.78rc56 and a Beta development status classifier. That means the API and configuration may change between versions. The README recommends pinning to a version range (>=0.9.0rc0,<0.10) for the uv install, which suggests that breaking changes are expected. If you need a stable, long-term tool, the release candidate status is a risk.
Alternatives and how they differ
A common alternative is the Internet Archive's Save Page Now, which archives a URL on their servers. The difference is that ArchiveBox is self-hosted and gives you control over the data, while Save Page Now stores the archive on the Internet Archive's infrastructure. For private or sensitive content, self-hosting is preferable. Another alternative is a simple wget mirror script, which downloads a website recursively. ArchiveBox differs by producing multiple formats and an indexed collection with metadata, tags, and a web UI. wget alone gives you raw HTML files without screenshots or PDFs. A more direct comparison is with a tool like SingleFile, which saves a page as a single HTML file. ArchiveBox includes SingleFile as one of its output formats, but it also saves the original HTML and WARC. The trade-off is that ArchiveBox is more complex to set up and run, while SingleFile is a browser extension that works on demand. If you only need a quick, one-off save of a page, SingleFile is simpler. If you need a systematic archive with multiple formats and scheduling, ArchiveBox is the better fit.
Maintenance and upgrade considerations
ArchiveBox is actively developed, with multiple releases on a single day (v0.9.76 and v0.9.77 on 27 October 2026). That implies a fast release cycle, which can be a maintenance burden. You will need to track updates and test them before applying to a production archive. The Docker Compose method makes upgrades straightforward: you pull the new image and restart. The uv method requires running uv tool install with the --upgrade flag. Since data is stored in plain files, an upgrade should not alter the archived content, but the index database (SQLite) may change schema. The license is MIT, which permits commercial use and modification without restrictions, aside from preserving the license notice. The community wiki and GitHub issues are the main support channels. Before adopting, check whether the project has a stable release (not just release candidates) and whether the external dependencies are available in your environment.
Editorial conclusion
Adopt ArchiveBox if you need a self-hosted, multi-format web archiving system that stores data in standard files and folders, and if you can manage its dependency on external tools like Chrome, wget, and yt-dlp. Do not adopt it if you want a single-binary appliance with no external runtime dependencies, or if your archive must be fully reproducible without those tools. Before committing, verify the exact versions of Chrome and yt-dlp that your distribution provides, test the Docker Compose or uv install path on your target OS, and confirm that the output formats (especially WARC and SingleFile) meet your long-term access needs. The project is under active development with frequent release candidates, so pin a specific version and test upgrades before applying them to a production archive.
Frequently asked questions
How do I install ArchiveBox?
Four routes are documented: Docker Compose from a curl-fetched compose file, a plain docker run container, uv tool install with an explicit prerelease flag, and a curl piped to bash shortcut. pyproject.toml sets requires-python to >=3.13 and the package version reads 0.9.78rc56, so a resolver that skips release candidates will not pick this line.
how to use archivebox
The same collection is reachable from the Browser Extension, the CLI, the self-hosted web interface, the Python API and the filesystem directly, and the documentation states that these ways are equivalent and offer matching features such as tags, scheduled crawls and log viewing. URLs arrive one at a time or through scheduled imports from bookmarks, history, RSS and services like Pocket and Pinboard.
archivebox vs singlefile
Inside ArchiveBox, singlefile is one output format for a snapshot rather than a separate system to pick between, sitting alongside original HTML, PNG, PDF and WARC output. What ArchiveBox wraps around those files is the server, the CLI, the Python API, scheduled imports and a SQLite3 store.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/archivebox-archivebox)Star history chart for your README
[](https://hysenlabs.com/projects/archivebox-archivebox)Was this useful?