SQLFluff: a lint report that names the rule code, the position, and the layout tag
A modular SQL linter and auto-formatter with support for multiple dialects and templated code.
At a glance
- What is it?
- SQLFluff is a Python SQL linter and auto-formatter whose real design decisions are visible in its output format, its dialect list, and its optional Rust parser. It runs on CPython 3.10 through 3.14, ships a Docker image whose entrypoint is the CLI itself, and treats the Python API as the unstable corner of an otherwise SemVer-disciplined project.
- Who is it for?
- SQLFluff fits a team that lints SQL across more than one warehouse dialect, renders its SQL through Jinja or dbt, and wants violations reported as stable rule codes such as LT01 rather than as prose. It does not fit a project with a single fixed dialect and no templating, because the dialect and templater configuration is the bulk of the work.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
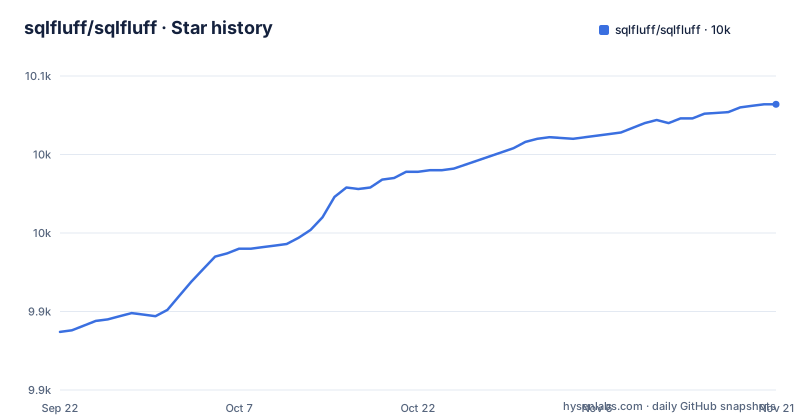
- sqlfluff/sqlfluff10,032 ★ · +145
| Repository | 2026-09-22 | 2026-11-21 |
|---|---|---|
| sqlfluff/sqlfluff | 9.9k | 10k |
145 Stars in the last 60 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The lint output carries a rule code, a position, and a dotted tag
The quickest way to understand SQLFluff is to read what it prints for a two-space-indented query. The full sequence of install, fixture, and lint is three lines:
$ pip install sqlfluff
$ echo "  SELECT a  +  b FROM tbl;  " > test.sql
$ sqlfluff lint test.sql --dialect ansi
== [test.sql] FAIL
L:   1 | P:   1 | LT01 | Expected only single space before 'SELECT' keyword.
                       | Found '  '. [layout.spacing]
L:   1 | P:   1 | LT02 | First line should not be indented.
                       | [layout.indent]
L:   1 | P:   1 | LT13 | Files must not begin with newlines or whitespace.
                       | [layout.start_of_file]
L:   1 | P:  11 | LT01 | Expected only single space before binary operator '+'.
                       |
Four things are encoded per violation: line, position, rule code, and a dotted tag in brackets such as [layout.spacing] or [layout.start_of_file]. The consequence is that a lint failure is a data structure, not a sentence, so the codes can be selected, exempted, or ignored by exact identifier instead of by matching English text. Note also that the file failed on three distinct layout rules (LT01, LT02 and LT13) before anything semantic was considered.
Dialect coverage is wide, and the README admits it is not complete
The supported list runs from ANSI SQL through Athena, BigQuery, ClickHouse, Databricks, Db2, Doris, DuckDB, Exasol, FlinkSQL, Greenplum, Hive, Impala, MariaDB, Materialize, MySQL, Oracle, PostgreSQL, Redshift, Snowflake, SOQL, SparkSQL, SQLite, StarRocks, Teradata, Transact-SQL, Trino, and Vertica. Two caveats are stated rather than buried. ANSI SQL is the base version and on occasion may not strictly follow the ANSI/ISO SQL definition. And the whole list is introduced as dialects supported though perhaps not in full. Databricks is a special case, extending the sparksql dialect with Unity Catalog syntax rather than being independent of it. The consequence for a reader choosing a dialect is that picking the right name does not promise full grammar coverage of that engine, and pyproject.toml lists sqlmesh among its keywords without any corresponding dialect in the list. The stated route to coverage is an issue, or an upvote on one, and pull requests from people who know the missing syntax.
Templating is a second axis, and dbt is not free
SQL does not lend itself well to modularity, so SQLFluff treats templating as its own dimension rather than folding it into the dialect. Four templaters are supported: Jinja, also called Jinja2, SQL placeholders such as SQLAlchemy parameters, Python format strings, and dbt. The last one carries a parenthetical that matters: dbt requires a plugin. The consequence is that the text SQLFluff reads is not necessarily the text your database receives. A Jinja conditional, a parameter placeholder, and a dbt ref all change the shape of the file before any rule runs, and when the templater fails to render you get a parse or lint failure that looks like a SQL problem and is not one. Teams using dbt therefore install a plugin before they can lint anything, and teams on plain SQL can leave the whole axis alone.
The rs extra is optional, and it can silently turn pip into a Rust build
The default install is pure Python. The Rust-backed parser and lexer are an opt-in extra:
$ pip install sqlfluff[rs]On supported CPython 3.10+ platforms this installs a prebuilt ABI3 wheel. If no wheel is published for your platform, pip falls back to building sqlfluffrs from source, which requires a Rust toolchain and a working C/C++ build setup, and the project points at rustup as the easiest way to install Rust. The consequence for continuous integration is concrete and easy to miss. On an obscure platform, or on a Python build outside the published wheel matrix, adding the extra silently converts a fast wheel install into a compile step that needs a toolchain you may not have in the image. The base package keeps working in that situation, so a project that never asks for rs is insulated from it entirely.
The Docker image mounts at /sql and starts the CLI, not a shell
The published image is built from a python:3.14-slim-trixie base in two stages, with a virtual environment created and pip-compile extracting requirements straight from pyproject.toml with pip-compile -o requirements.txt pyproject.toml -v --strip-extras. What matters for using it is the runtime shape: the working directory is switched to /sql so a bind mount needs no full path, the entrypoint is the sqlfluff executable itself, and the default command is --help. That is why the documented invocation passes no command name, only arguments:
docker run --rm -it -v $PWD:/sql sqlfluff/sqlfluff:latest lint test.sqlThe consequence is an argument parsing constraint rather than a usability nicety. Because the CLI is the entrypoint, anything that expects to start a shell or a Python interpreter in that image has to override the entrypoint, and forgetting that produces a confusing failure on what looks like a volume path problem.
The development container mounts your dbt profiles and publishes Postgres to your host
docker-compose.yml defines two services. The development service builds from ./docker/development/Dockerfile, depends on a postgres service running the postgres:14-bullseye image, and enters through /bin/bash. Its volumes are the ones to read carefully: the repository is mounted at /app, ./test/fixtures/dbt/profiles_yml is mounted over /root/.dbt, ~/.gitconfig becomes /etc/gitconfig, ~/.ssh becomes /root/.ssh, and the host SSH agent socket is passed through. The postgres service sets POSTGRES_PASSWORD=password and maps the port as "5432:5432", with a comment explaining that this makes the server reachable from both the host and the container and can be narrowed to "5432" if you do not want it on the host. The consequence is that this compose file is a contributor environment that deliberately shadows your real dbt profiles and deliberately exposes a database on a fixed port.
The Makefile is a Docker wrapper, and release takes its version as an argument
Nothing in the Makefile builds or tests Python. Its targets are help, build, clean, fresh, release, shell, start, and stop, and help is the default goal, generated by grepping the target comments so the list stays in sync with the file. build runs docker-compose build development, fresh adds --no-cache, shell runs docker-compose exec development bash, start runs docker-compose up -d, and clean goes further than its name suggests by running docker system prune -f and then docker rmi on every image on the machine. release is the one target that leaves Docker entirely, and it forwards a VERSION that is parsed out of the make goals:
python util.py release $(VERSION)The consequence is twofold. Running make release with no version argument hands util.py an empty VERSION, and make clean is not confined to this project's containers. Testing and linting of the project itself are wired elsewhere, through tox.ini, requirements_dev.txt, .pre-commit-config.yaml, .pre-commit-hooks.yaml, and .yamllint at the root.
The Python API is the one part SemVer does not promise to hold
SQLFluff adheres to Semantic Versioning, so breaking changes are meant to be restricted to major releases, with details in the release notes and the changelog. The exception is called out immediately: some elements, such as the Python API, are in a less stable state and may see more significant changes more often. The repository's own examples directory reflects how much surface there is, with 01_basic_api_usage.py, 02_timing_api_steps.py, 03_getting_rules_and_dialects.py, 04_config_overrides.py, 05_simple_api_config.py, and 06_full_parse_api.py. pyproject.toml declares requires-python >=3.10 and classifies the project for CPython 3.10, 3.11, 3.12, 3.13, and 3.14, plus the CPython implementation classifier. The consequence is a clean split for anyone choosing an integration point. Pin the CLI and you are inside the SemVer promise; embed the library and you are inside the part the project tells you to expect to move, so pin exactly and read the release notes on every minor bump.
Editorial conclusion
SQLFluff fits a team that lints SQL across more than one warehouse dialect, renders its SQL through Jinja or dbt, and wants violations reported as stable rule codes such as LT01 rather than as prose. It does not fit a project with a single fixed dialect and no templating, because the dialect and templater configuration is the bulk of the work. Before adopting it, check three things: whether your dbt setup needs the plugin and whether your profiles resolve, whether a prebuilt ABI3 wheel exists for your platform or your CI will compile sqlfluffrs with a Rust toolchain, and whether you are depending on the Python API, which the project itself flags as less stable.
Frequently asked questions
what is sqlfluff
SQLFluff is a dialect-flexible and configurable SQL linter and auto-formatter written in Python, designed with ELT applications in mind and also working with Jinja templating and dbt. It will auto-fix most linting errors and is MIT licensed.
How do I install SQLFluff?
The base install is pip install sqlfluff, and requires-python is set to >=3.10 with classifiers for CPython 3.10 through 3.14. If you want the Rust-backed parser and lexer, install the extra with pip install sqlfluff[rs], which uses a prebuilt ABI3 wheel where one is published and otherwise builds sqlfluffrs from source with a Rust toolchain. An official Docker image and an online playground are also offered.
what is sqlfluff lint
It is the lint command from the CLI, used against a file and a dialect such as sqlfluff lint test.sql --dialect ansi. It reports line, position, rule code, and a dotted tag such as [layout.spacing], and the companion sqlfluff fix command is the one that rewrites what it can.
How do I use SQLFluff in dbt?
dbt is one of the supported templates, and it requires a plugin before it works. The motivation is that SQL itself does not lend itself well to modularity, so templating is handled as its own axis alongside the dialect.
how to run sqlfluff in vscode
There is a VS Code extension maintained in its own repository at github.com/sqlfluff/vscode-sqlfluff and published to the VS Code marketplace as dorzey.vscode-sqlfluff. The linter itself remains a command line tool installed from the package.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sqlfluff-sqlfluff)Star history chart for your README
[](https://hysenlabs.com/projects/sqlfluff-sqlfluff)Was this useful?