ProxyPool: Redis sorts what the Tester is allowed to keep
An Efficient ProxyPool with Getter, Tester and Server
At a glance
- What is it?
- ProxyPool is three cooperating processes, Getter, Tester and Server, backed by Redis, that harvest free public proxy sources, throw away the ones that fail and hand the survivors out over a small HTTP API. The author is direct about the hit rate: this is a teaching project, not a supply of working proxies, and the configuration surface says so in env vars rather than in a config file.
- Who is it for?
- ProxyPool is worth running when the goal is to understand how a proxy pool is put together, since the three processes are separated on purpose and every knob is a named environment variable. It is not worth running when you need reliable egress for a scraping job, because the source list is public free proxies and the yield is a handful per thousand.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 141 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
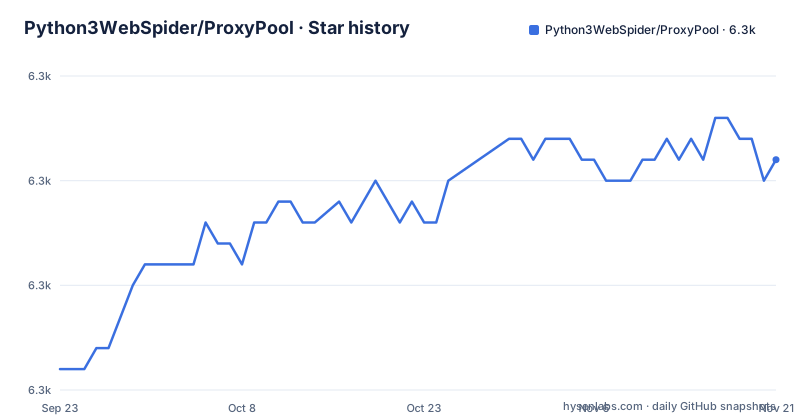
- Python3WebSpider/ProxyPool6,261 ★ · +10
| Repository | 2026-09-23 | 2026-11-21 |
|---|---|---|
| Python3WebSpider/ProxyPool | 6.3k | 6.3k |
10 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The project tells you to buy proxies instead of scraping free ones
The warning is the first thing the documentation gives you and it is unusually blunt. This proxy pool is built on assorted public proxy sources, so availability is low: out of hundreds or thousands of proxies you may find only one or two that work, and it is not suitable for crawler tasks directly. If your goal is to finish a scraping job quickly, the advice is to buy paid proxies or reuse resources you already have. If your goal is to learn how a proxy pool is assembled, the advice is to keep going here.
The paid options are named as three products from one vendor: ADSL dial-up proxies inside China, overseas and global proxies, and cellular 4G and 5G proxies described as high quality and resistant to risk control. There is also a companion write-up on how to build an efficient proxy pool, which the documentation asks you to read before using the code.
One thing this project cannot do is hand you a working proxy on demand. No amount of configuration fixes a source list made of free listings.
Two ways to run it, and the compose file puts Redis next to the app
The non-Docker route needs Python 3.6 or newer plus Redis, and the project asks for a virtual environment built with Conda or virtualenv before installing anything. The Docker route needs Docker and Docker-Compose, and the official image is published as germey/proxypool.
The compose file defines two services, redis4proxypool on the redis:alpine image and proxypool built from the local directory, with only port 5555 published and a restart policy of always. Redis gets no volume and no password, and the proxy service is wired to it by hostname:
services:
  redis4proxypool:
    image: redis:alpine
    container_name: redis4proxypool
  proxypool:
    build: .
    image: "germey/proxypool:master"
    container_name: proxypool
    ports:
      - "5555:5555"
    restart: always
    environment:
      PROXYPOOL_REDIS_HOST: redis4proxypool
A commented volume line points at proxypool/crawlers/private, which is the place for your own crawlers. The Dockerfile builds in a separate stage with gcc, g++, libxml2-dev and libxslt1-dev, then copies the user site-packages into a clean python:3.11-slim image, sets APP_ENV=prod, exposes 5555, mounts that same crawlers/private path as a volume, and hands the container to supervisord with supervisord.conf as the entrypoint.
Redis holds the pool as a dict, and the PROXYPOOL_ prefix wins
Redis does more than storage here. Proxies are stored in it and ranked by availability, and the dictionary name used for that is configurable through PROXYPOOL_REDIS_KEY. Connection settings come from environment variables, and every one of them has a short form and a prefixed form:
export PROXYPOOL_REDIS_HOST='localhost'
export PROXYPOOL_REDIS_PORT=6379
export PROXYPOOL_REDIS_PASSWORD=''
export PROXYPOOL_REDIS_DB=0export PROXYPOOL_REDIS_CONNECTION_STRING='redis://localhost'Use either form, not both. The connection string has to follow redis://[:password@]host[:port][/database], where the bracketed parts are optional, port defaults to 6379, database defaults to 0 and the password is empty when unset. For host, port, password, database index and connection string alike, the PROXYPOOL_ prefixed variable overrides the bare REDIS_ one, which is a convenient way to keep a base config and adjust it per deployment.
An empty password string is how a local Redis without authentication is expressed.
run.py runs all three processors or exactly one of them
Once Redis and the dependencies are in place, one command starts everything:
```shell script python3 run.py
That starts Tester, Getter and Server together, after which a request to http://localhost:5555/random returns one random proxy that passed testing. If you have worked out how the pieces fit, you can start them one at a time instead:
shell script python3 run.py --processor getter python3 run.py --processor tester python3 run.py --processor server ```
The processor flag takes getter, tester or server. Each stage can also be turned off entirely, which matters more than it sounds: ENABLE_TESTER, ENABLE_GETTER and ENABLE_SERVER all default to true, so an unattended deployment quietly runs all three unless you say otherwise.
Under Docker the same arrangement is handled by supervisord, and the startup log shows the sequence: Redis ready to accept connections, supervisord started with pid 1, then spawned getter.
The API speaks count, area and key, and area needs an offline GeoLite2 file
Three endpoints are served on port 5555 by default, /random, /all and /count. Asking for more than one proxy at a time is a query parameter, with one proxy per line in the response:
GET http://localhost:5555/random?count=5Leave count out or set it to 1 and the old single-proxy behaviour is unchanged; set it higher than the number of available proxies and you get everything available. It also combines with the key parameter.
Filtering by country works on both /random and /all, using an ISO country code that is not case sensitive:
GET http://localhost:5555/random?area=CN
GET http://localhost:5555/all?area=CN
Country information comes from a built-in GeoLite2 offline database, pinned in the dependency list as maxminddb_geolite2==2018.703, and a proxy whose location cannot be resolved is dropped from the result. area combines with count and key.
The Server binds every interface with no key, and the docs say so in a warning
API_HOST defaults to 0.0.0.0 and API_PORT to 5555, and API_KEY defaults to empty, which means no authentication at all. Anyone who can reach that port can call /random, /all and /count. The documentation attaches a security note directly to the setting: if you expose the proxy pool to the public internet, set API_KEY and restrict the source with a firewall or a security group. When a key is set, those three endpoints expect it in an API-KEY request header.
The key query parameter is filtered separately: only letters, digits, and the characters _: - are allowed, up to 64 characters. That validation stops a key from being abused as something else in a URL, but it does not change the default, which is open access on all interfaces.
API_THREADED defaults to true, so the server handles requests in multiple threads. Combine that with the open default and the picture is a public endpoint that hands out the pool's proxies to whoever asks.
Tester defaults to anonymous proxies only, tested against a URL you can redirect
The Tester is the filter, and its defaults are opinionated. CYCLE_TESTER runs every 20 seconds, CYCLE_GETTER fetches every 100 seconds, TEST_URL points at Baidu by default, TEST_TIMEOUT is 10 seconds, and TEST_BATCH is 20 proxies per pass. TEST_ANONYMOUS defaults to true, so only anonymous proxies are kept, and TEST_VALID_STATUS sets which status codes count as working.
Anonymity is checked against TEST_ANONYMOUS_URL, defaulting to https://httpbin.org/ip and expecting httpbin style JSON such as {"origin": "1.2.3.4"}. The docs suggest pointing it at a self-hosted httpbin instance to avoid rate limiting on the public service, which tells you how much traffic a small pool sends. With the default, a shared public endpoint is doing the judging for every proxy in your pool.
The other environment settings follow the same pattern, with APP_ENV defaulting to dev, APP_DEBUG to true, and APP_PROD_METHOD defaulting to gevent, with tornado and meinheld as the alternatives if you install those modules.
Editorial conclusion
ProxyPool is worth running when the goal is to understand how a proxy pool is put together, since the three processes are separated on purpose and every knob is a named environment variable. It is not worth running when you need reliable egress for a scraping job, because the source list is public free proxies and the yield is a handful per thousand. Before exposing it anywhere, set API_KEY and restrict port 5555, since the Server binds 0.0.0.0 and ships without authentication.
Frequently asked questions
what is proxy pool
A proxy pool is a store of proxy addresses, kept in Redis here, ranked by availability, and handed out on request. ProxyPool builds one from public free proxy sources, with a Getter that harvests them, a Tester that discards the ones that fail, and a Server that exposes the survivors at /random, /all and /count.
How do I run ProxyPool for the first time?
Clone the repository, then choose Docker or the normal route. With Docker and Docker-Compose installed, docker-compose up brings up Redis and the app, and http://localhost:5555/random then returns a random proxy. Without Docker you need Python 3.6 or newer and Redis, then pip3 install -r requirements.txt and python3 run.py.
Why does ProxyPool return so few working proxies?
Because it is built on assorted public proxy sources, and the project's own documentation says availability is low, with only one or two usable proxies out of hundreds or thousands. It recommends paid proxies or existing resources for real crawling work, and points learners at the project instead.
How do I secure the ProxyPool API?
Set API_KEY, which defaults to empty and therefore means no authentication, and then send the API-KEY header when calling /random, /all or /count. The Server defaults to API_HOST 0.0.0.0 and API_PORT 5555, so restricting the source with a firewall or security group is called for when the pool is reachable from outside.
Can ProxyPool filter proxies by country?
Yes. Pass an ISO country code, case insensitive, as the area parameter to /random or /all, for example GET http://localhost:5555/random?area=CN. Country data comes from a built-in GeoLite2 offline database, and proxies whose location cannot be resolved are excluded.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/python3webspider-proxypool)Star history chart for your README
[](https://hysenlabs.com/projects/python3webspider-proxypool)Was this useful?