Caffeine: The Java Cache Library That Puts TinyLFU Into Production
A high performance caching library for Java. Cache Caffeine provides an in-memory cache using a Google Guava inspired API.
At a glance
- What is it?
- Caffeine is an in-memory caching library for Java with a Guava-style API and a TinyLFU-based eviction policy. This review covers its mechanism, setup, and the trade-offs you should check before adopting it.
- Who is it for?
- Adopt Caffeine if you need a high-throughput in-memory cache in a Java 11+ application and you value an eviction policy that adapts to shifting workloads. It is a poor fit if you require a distributed cache, need to cache values larger than your heap, or cannot afford the complexity of its asynchronous refresh semantics.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 21 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
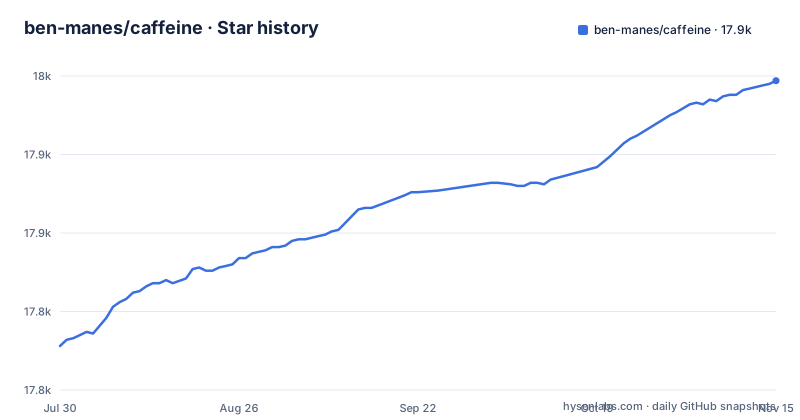
- ben-manes/caffeine17,947 ★ · +169
| Repository | 2026-07-30 | 2026-11-15 |
|---|---|---|
| ben-manes/caffeine | 17.8k | 17.9k |
169 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Caffeine Solves and Who Needs It
Caffeine addresses a specific problem: providing an in-memory cache for Java applications that must serve hot data with minimal latency while keeping memory bounded. It is aimed at engineers who previously reached for Guava's cache or built their own ConcurrentHashMap-based cache and hit limits on concurrency, eviction quality, or maintenance. The library is not a distributed cache, nor a persistent store. It lives entirely inside one JVM process. The README positions it as "a high performance caching library," and its origin is telling: the author also designed Guava's cache and ConcurrentLinkedHashMap. So this is a second-generation attempt at the same problem. You would use it when your application needs to memoize expensive computations, database queries, or remote calls, and you want a cache that handles concurrent access without turning into a bottleneck.
The Eviction Mechanism: TinyLFU and the Adaptive Window
Caffeine's core differentiator is its eviction policy. The README links to research papers on TinyLFU and its adaptive variant. TinyLFU stands for Tiny Least Frequently Used, and it is an admission policy: before an entry is admitted to the cache, the library estimates its future frequency using a compact frequency sketch. This sketch uses a probabilistic data structure to count accesses with a small memory footprint. The policy keeps frequently used entries and rejects one-hit wonders. The adaptive part, described in the README's link to "The Adaptive Window, From the Ground Up," adjusts the balance between a small recency-protected window and the main frequency-based segment. This matters because pure LFU can fail when a workload shifts to a new set of hot keys; the adaptive window gives recent entries a chance to prove themselves before being admitted. The README does not detail the exact parameters, but the mechanism is documented in the linked papers. In practice, this means Caffeine can outperform a simple LRU cache on skewed workloads, but the cost is a more complex algorithm that is harder to reason about.
Getting It Running: Dependencies and a Minimal Cache
You add Caffeine to a Gradle project with one line: implementation("com.github.ben-manes.caffeine:caffeine:3.3.1"). There are optional artifacts for Guava adapters and JCache, but the core dependency is the caffeine artifact. The README shows a minimal construction: a LoadingCache that loads entries via a function. The builder accepts maximumSize, plus expireAfterWrite and refreshAfterWrite with Duration objects. For example, the README's snippet sets a maximum of 10,000 entries, expiration after five minutes, and refresh after one minute. The build method takes a key-to-value function. This is the same pattern as Guava's CacheBuilder, so anyone familiar with Guava will feel at home. The library requires Java 11 or above for version 3.x; if you are on Java 8, you must use the 2.x line. That is a hard constraint to check before upgrading.
Beyond Basics: Async Loading, References, and Statistics
The README lists features that go beyond simple get-and-put. You can load entries asynchronously, which is useful when the load function performs I/O. You can set expiration based on last access or last write, and you can refresh entries asynchronously when the first stale request arrives. Keys can be wrapped in weak references, and values in weak or soft references, which lets the garbage collector reclaim memory under pressure. There is a removal listener for eviction notifications, a way to propagate writes to an external resource, and a statistics collector for hit rates and miss counts. These are not gimmicks; they address real operational needs. The statistics feature is particularly useful for tuning the cache size, because you can observe the hit ratio and adjust maximumSize accordingly.
Where Caffeine Is the Wrong Tool
Caffeine is an in-memory cache, so it is the wrong tool for any scenario that requires sharing cache state across multiple JVMs or processes. If your application runs on several nodes, each node will have its own cache, and you will get inconsistent data unless you add an external cache like Redis or Memcached. Even within a single JVM, a maximumSize bound such as the README's 10,000 counts entries, so large values can take a lot of heap. Another trade-off is the complexity of the eviction algorithm, which is harder to reason about than plain LRU. The README links the project's own benchmark page; treat those performance figures as the project's own.
Alternatives: Guava Cache and Caffeine's Own Adapters
The most direct alternative is Guava's cache, which Caffeine's API mimics. The difference is in the eviction policy: Caffeine's is based on frequency and recency, drawing on the TinyLFU research the README links. The README even provides a Guava adapter artifact, so you can keep your existing Guava cache API and switch the backend to Caffeine. Another alternative is to use Caffeine's JCache implementation if you need a standard JSR-107 interface. If you need a distributed cache, you would look at Infinispan or Redisson, both listed as projects that use Caffeine internally, but they are not replacements for Caffeine itself. The key difference is scope: Caffeine is a single-node cache, while those are multi-node systems. For a single-node cache, the choice is often between Caffeine and a hand-rolled ConcurrentHashMap, and Caffeine's advantage is the eviction policy and the built-in statistics.
Maintenance and Licensing: What the Repository Tells You
The repository is active, with the latest release v3.3.1 published on 2026-10-13 and the last push on 2026-10-25. The project is not archived. The license is Apache-2.0, which is permissive and allows commercial use without copyleft obligations. The README lists a long set of integrations, including Spring, Micronaut, and Quarkus, which suggests a healthy ecosystem. The release notes are linked, so check those for breaking changes. You must verify that your Java version matches the 3.x requirement. The project also maintains a simulator tool, listed as an extension with its own module and wiki page; read it before committing to Caffeine in production.
Editorial conclusion
Adopt Caffeine if you need a high-throughput in-memory cache in a Java 11+ application and you value an eviction policy that adapts to shifting workloads. It is a poor fit if you require a distributed cache, need to cache values larger than your heap, or cannot afford the complexity of its asynchronous refresh semantics. Also confirm that your project can tolerate the Apache-2.0 license and that you are on a supported Java version, since 3.x requires Java 11 or above.
Frequently asked questions
How do you add Caffeine to a Gradle project?
Declare the artifact from Maven Central and pick the line that matches your JDK. The project states that Java 11 or above uses 3.x and anything older uses 2.x, and snapshots of the development version sit in Sonatype's snapshots repository.
What is the difference between expireAfterWrite and refreshAfterWrite in Caffeine?
Expiration removes entries, while refresh happens asynchronously when the first stale request for an entry arrives, which is why a refreshing cache needs a loader passed to build(). The documentation does not describe what a caller sees while the refresh is in flight.
Why does a Caffeine cache miss a key it still holds?
The optional reference features wrap keys in weak references and values in weak or soft references, so an entry can be collected while the cache is below its maximum size and no expiration has fired. Size, time and reference policies are all added to the builder explicitly.
Does Caffeine require Google Guava on the classpath?
The API is a Google Guava inspired one, and the project ships a separate guava artifact as an optional extension next to the jcache artifact. The core dependency is com.github.ben-manes.caffeine:caffeine.
What does the Caffeine simulator do?
It is one of three extensions named in the README, alongside JSR-107 JCache support and the Guava adapters. It has its own module in the repository, and the documentation points at a wiki page rather than describing it.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- One Load per Key: Collapsing Duplicate Lookups with Spring Boot's Cache and Caffeinedev.to · Oct 23, 2026 · 5 points · 1 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ben-manes-caffeine)Star history chart for your README
[](https://hysenlabs.com/projects/ben-manes-caffeine)Was this useful?