Apache Kafka: A Distributed Event Streaming Platform with a Java 17/25 Build Baseline
Apache Kafka - A distributed event streaming platform. We build and test Apache Kafka with Java versions 17 and 25.
At a glance
- What is it?
- Apache Kafka is a distributed event streaming platform for high-performance data pipelines and analytics. This review covers its build system, Java version requirements, testing workflows, and operational commands, with a focus on what engineers need to know before adopting it.
- Who is it for?
- Adopt Apache Kafka if you need a proven, open-source event streaming platform for high-throughput data pipelines and you can commit to Java 17 or 25 for development. Do not adopt it if you require a lightweight, single-node solution or if your team lacks Java and Gradle expertise.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
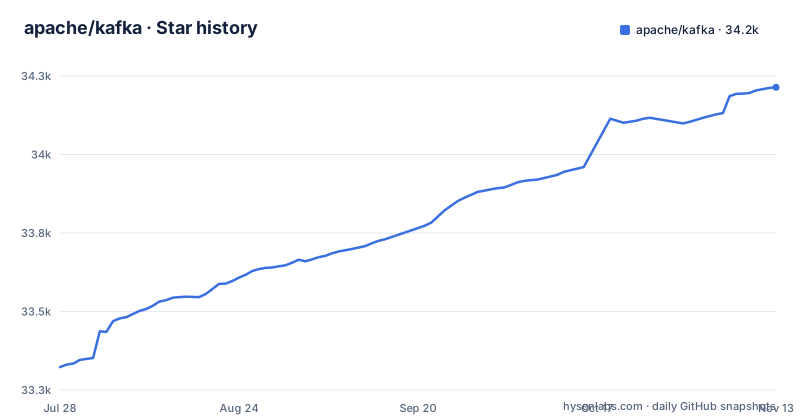
- apache/kafka34,214 ★ · +891
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| apache/kafka | 33.3k | 34.2k |
891 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Apache Kafka Solves and Who It Targets
Apache Kafka is a distributed event streaming platform. It solves the problem of moving large volumes of events between producers and consumers in real time, while providing durability and fault tolerance. The README describes it as used by thousands of companies for high-performance data pipelines, streaming analytics, data integration, and mission-critical applications. That makes it a fit for data engineers, backend developers, and platform teams who need a central backbone for event-driven architectures. It is not a tool for simple message queuing or for teams that want a zero-dependency, embedded solution. Kafka is a server-side system with its own storage and networking layer, so it expects a cluster of brokers and a client library in your application. The target audience is organizations that already operate infrastructure and need a scalable, battle-tested event log.
Java and Scala Version Constraints
The README states that Apache Kafka is built and tested with Java versions 17 and 25. That is a specific, narrow window. The `release` parameter in javac is set to 11 for the clients and streams modules, and 17 for the rest. That means the compiled bytecode for those modules targets Java 11, so they can run on older JVMs, but the build itself requires at least Java 17. Scala 2.13 is the only supported Scala version. This is a deliberate trade-off: it reduces the matrix of compatibility, but it also means other Scala versions are not supported. For developers, this is a clear constraint. If your organization standardizes on Java 11 or 21, you can still run the clients and streams, but you must build with a JDK 17 or 25. The README also notes that JDK 17 should be used when developing Kafka, which is a strong signal that the build tooling expects a specific JDK version.
Building from Source: The Gradle Workflow
The build system is Gradle. The README gives a set of commands that form the core workflow. To produce a runnable JAR, you run `./gradlew jar`. For a source JAR, `./gradlew srcJar`. There are separate tasks for javadoc and scaladoc: `./gradlew javadoc`, `./gradlew javadocJar`, `./gradlew scaladoc`, `./gradlew scaladocJar`, and `./gradlew docsJar` for both. The aggregated javadoc task is `./gradlew aggregatedJavadoc --no-parallel`. The README also shows how to build a binary release tarball with `./gradlew clean releaseTarGz`, which places the artifact in `./core/build/distributions/`. That is the standard way to get a deployable Kafka distribution. The build is modular, with `core`, `clients`, `streams`, and `examples` as separate Gradle projects. You can target a specific module, like `./gradlew clients:jar` or `./gradlew core:test`. The presence of a `clean` task and a `tasks` task to list all tasks indicates a conventional Gradle setup.
Running Tests: Unit, Integration, and Flaky Tests
Testing is a big part of the README, and the commands are specific. `./gradlew test` runs both unit and integration tests. You can split them with `unitTest` and `integrationTest`. There is also a flag to run flaky tests: `./gradlew test -Pkafka.test.run.flaky=true`. That is an honest admission that some tests are known to be flaky, and the project provides a way to run them anyway. For a specific test class or method, the README shows patterns like `./gradlew clients:test --tests RequestResponseTest` or `./gradlew streams:integration-tests:test --tests RestoreIntegrationTest`. You can even run a specific method with `--tests org.apache.kafka.clients.MetadataTest.testTimeToNextUpdate`. The README includes a loop command to run a test N times until failure, using `--rerun --fail-fast`. That is useful for reproducing intermittent failures. Test retries are disabled by default, but you can enable them with `-PmaxTestRetries=1 -PmaxTestRetryFailures=3`. That gives you control over flaky tests without masking real failures. The log4j output can be adjusted by editing `log4j2.yaml` in the module's test resources, and the README points to a specific line for the clients module.
Operational Commands: Running a Broker
The README provides two ways to run a Kafka broker. The first uses compiled files. You generate a cluster ID with `./bin/kafka-storage.sh random-uuid`, then format the storage with `./bin/kafka-storage.sh format --standalone -t $KAFKA_CLUSTER_ID -c config/server.properties`, and finally start the server with `./bin/kafka-server-start.sh config/server.properties`. That is a three-step process that reflects Kafka's storage layer, which requires a format step before the broker can start. The second way is a Docker image: `docker run -p 9092:9092 apache/kafka:latest`. That is simpler for a quick start, but it hides the storage formatting details. The README points to `docker/README.md` for more information, so the Docker path is documented but not fully explained in the main README. For a production deployment, you would likely use the tarball and the shell scripts, because they give you control over the configuration file. The `format` command is a clear operational step that you cannot skip, and it is a potential failure point if the config file is wrong.
Limitations and Failure Modes
One limitation is the Java version requirement. The README says you need Java installed, and the build is tested only with Java 17 and 25. If your CI environment uses Java 21, you may still build, but it is not officially tested. The `release` parameter set to 11 for clients and streams means those modules run on Java 11, but the build itself needs a newer JDK. That mismatch can confuse developers. Another limitation is the single Scala version. The README also mentions flaky tests, which indicates that the test suite is large and sometimes unreliable. The retry mechanism is disabled by default, so a flaky test can fail a build unless you explicitly enable retries.
Alternative Approaches: Kafka vs. Other Event Streaming Tools
A real alternative is Apache Pulsar, which also provides distributed event streaming but uses a different architecture. Pulsar separates storage and serving, using Apache BookKeeper for storage, while Kafka uses a log-based storage model on each broker. That difference affects scaling and latency characteristics. Another alternative is RabbitMQ, which is a message broker rather than a stream platform. RabbitMQ is simpler to operate and supports many protocols, but it does not provide the same replayability and long-term retention that Kafka offers. For a team that needs a simple queue, RabbitMQ is a lower-cost choice. For a team that needs event sourcing or stream processing, Kafka's log model is a better fit.
Maintenance and Upgrade Cost
The build itself requires a JDK 17 or 25, so you must keep your build environment up to date. The README mentions that auto-generated messages may need to be rebuilt when switching branches, with the command `./gradlew processMessages processTestMessages`. That is a maintenance step that can fail due to code changes. The project uses a `trunk` branch, which indicates active development. The license is Apache-2.0, which allows commercial use, modification, and distribution, but you must retain the license notice. That is a permissive license, so the main cost is not legal but operational: you need to manage the cluster, handle upgrades, and deal with the storage format. For a team that adopts Kafka, the maintenance cost is ongoing.
Editorial conclusion
Adopt Apache Kafka if you need a proven, open-source event streaming platform for high-throughput data pipelines and you can commit to Java 17 or 25 for development. Do not adopt it if you require a lightweight, single-node solution or if your team lacks Java and Gradle expertise. Before adopting, verify your Java version matches the build requirements (17 for most modules, 11 for clients and streams) and confirm that Scala 2.13 is acceptable for your Streams usage. Check the latest release notes for any changes to the build or runtime requirements, and review the Apache-2.0 license to ensure compliance with your distribution model.
Frequently asked questions
How do I install Kafka?
You need Java installed, and the README builds it from source with the Gradle wrapper, producing a jar with `./gradlew jar` and a binary release tarball with `./gradlew clean releaseTarGz`, which lands under ./core/build/distributions/. A published container image is also available as apache/kafka:latest.
How do I use Kafka locally?
Start a broker from compiled files in three steps: generate a cluster ID with `./bin/kafka-storage.sh random-uuid`, format the storage with `./bin/kafka-storage.sh format --standalone` against config/server.properties, then run `./bin/kafka-server-start.sh config/server.properties`. The container route is one command, `docker run -p 9092:9092 apache/kafka:latest`.
how to use kafka
For running it, the README covers the broker startup and then points to the quickstart at kafka.apache.org/quickstart for the client side. For working on it, everything is Gradle: build a jar, run unit or integration tests, run one test by class or method, and generate coverage with a flag, plus javadoc and scaladoc targets for each module.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/apache-kafka)Star history chart for your README
[](https://hysenlabs.com/projects/apache-kafka)Was this useful?