bRAG-langchain: A Notebook Tour from Basic RAG to RAG-Fusion and Self-RAG
Everything you need to know to build your own RAG application
At a glance
- What is it?
- A Jupyter notebook collection that walks from a minimal RAG pipeline through multi-query, routing, advanced indexing, and reranking. It is a learning path rather than a production framework, with code snippets that you must adapt to your own API keys and data.
- Who is it for?
- Adopt bRAG-langchain if you are a developer or data scientist who learns best by reading and modifying notebook code, and who wants a structured path from a basic RAG chatbot to advanced techniques like RAPTOR, ColBERT, RAG-Fusion, and Self-RAG. Do not use it as a production library: it has no packaged install, no pinned dependencies, and no formal release, so you will need to extract the relevant cells into your own project.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 27 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
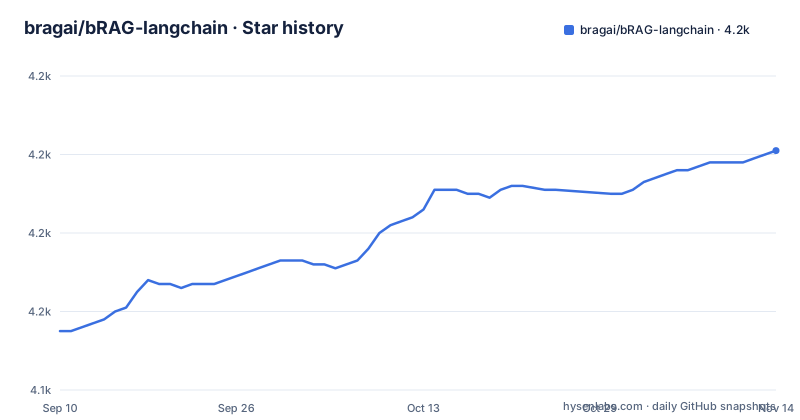
Star history
- bragai/bRAG-langchain4,201 ★ · +46
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| bragai/bRAG-langchain | 4.2k | 4.2k |
46 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What This Repository Actually Offers
The repository is a collection of Jupyter notebooks that teach Retrieval-Augmented Generation by example. The README positions it as a comprehensive exploration, and the file names confirm a deliberate progression: notebook 1 covers environment setup, document loading, embeddings, and a basic pipeline; notebook 2 adds multi-query retrieval; notebook 3 introduces routing and query construction; notebook 4 covers multi-representation indexing, RAPTOR, and ColBERT; notebook 5 handles reranking with RRF and Cohere, plus CRAG and Self-RAG. The intended audience is someone who wants to understand RAG mechanics hands-on, not a team looking for a drop-in library. The primary language is Jupyter Notebook, which tells you the deliverable is educational code, not a pip-installable package. If you are an engineer evaluating production components, this repository is a map of techniques, not a toolkit.
The Learning Path: From Boilerplate to Advanced Retrieval
The README points to full_basic_rag.ipynb as the boilerplate starter code for a customizable RAG chatbot. That file sits outside the notebooks directory, which suggests it is the entry point. The numbered notebooks then build on that foundation. Notebook 1 gives a baseline pipeline with OpenAI embeddings and a choice of ChromaDB or Pinecone as the vector store. Notebook 2 introduces multi-querying, where multiple queries are generated from a single input to diversify retrieval, and it compares results against a single-query baseline. Notebook 3 covers two routing styles: function-based routing that classifies queries by programming language, and semantic routing that uses cosine similarity to direct questions to a math or physics prompt. It also shows how to structure search queries for metadata filters, such as filtering YouTube tutorials by view count or publication date. Notebook 4 moves to indexing, covering multi-vector structures, in-memory summary storage, and the RAPTOR and ColBERT models. Notebook 5 demonstrates RAG-Fusion, Reciprocal Rank Fusion, Cohere reranking, and CRAG and Self-RAG. Each notebook appears to contain runnable code, but the README does not state that every notebook executes end-to-end without modification.
Getting It Running: Commands and Version Pitfalls
The README gives concrete setup steps. You clone the repository, create a virtual environment with Python 3.11.11, and activate it. The version is specific: Python 3.11.11 is preferred, and the setup instructions include a warning that the virtual environment might default to a different version, such as Python 3.13. The README then shows steps to make sure the python command uses Python 3.11. The installation instructions cover macOS, Linux, and Windows, with platform-specific steps for each. The repository ships a requirements.txt listing the dependencies, including langchain, chromadb, pinecone-client and cohere, but only pydantic>=2.7.0 and youtube-transcript-api<1.0.0 carry version bounds, which means you could face dependency conflicts, particularly with LangChain versions.
The Architecture: What the Notebooks Reveal
From the notebook descriptions, a clear pattern emerges. The basic pipeline loads documents, splits them, generates embeddings, stores them in a vector store, and then retrieves relevant chunks for the LLM. Multi-querying adds a step where the LLM generates several query variations before retrieval. Routing adds a decision layer before retrieval, either through function calls or semantic similarity. Indexing techniques change how documents are stored: multi-representation indexing keeps summaries and parent documents, while RAPTOR and ColBERT alter the granularity of representation. Reranking adds a post-retrieval step that reorders results, either by fusing multiple lists or by using a dedicated model like Cohere. The notebooks seem to rely heavily on LangChain, given the repository name and the mention of MultiVectorRetriever and InMemoryByteStore. The actual code lives in the notebooks rather than the README. This is a strength for learning, because you see how components connect, but it is a weakness for reuse, because you must extract the logic yourself.
Where It Falls Short: No Releases, No License, No Maintenance Guarantees
The repository has no GitHub releases, and the license field is NOASSERTION. That means you cannot assume any open-source license terms. The repository does include a LICENSE file at the top level, so read it before using the code in a commercial product. The last push was on 2026-10-18. The project is not archived, and the homepage points to bragai.dev, which is described as launching soon. For an engineer, this means the code may not be updated to match LangChain API changes. LangChain evolves quickly, and notebooks written against one version can break within months. The README itself warns about Python version mismatches, which is a sign that the setup is fragile. If you need a stable, versioned RAG library, this repository is not it.
Comparing to a Structured Framework: LangChain Itself
The obvious alternative is LangChain, which this repository uses as its underlying library. LangChain is a proper Python package with releases, documentation, and a large ecosystem. Instead of reading notebooks, you can use LangChain's official RAG tutorials, which are maintained and versioned. The difference in approach is that LangChain gives you modular components and a consistent API, while bRAG-langchain gives you narrative code that shows how to combine those components. If you already know LangChain, the notebooks add little. If you are new, the notebooks may help you see the workflow, but you will still need to consult LangChain's documentation for current API signatures. Another alternative is LlamaIndex, which takes a different design philosophy: it provides high-level abstractions for data ingestion and query engines, whereas this repository focuses on LangChain-style chains and retrievers. LlamaIndex has its own learning resources and a more opinionated structure for connecting data sources. The choice depends on whether you prefer to learn by reading code or by using a framework's official guides.
Maintenance and Upgrade Costs
The maintenance cost is high if you adopt this as a codebase. There is no dependency lock file and no release process. Each notebook likely imports libraries that have their own release cycles. When LangChain or ChromaDB releases a breaking change, you must manually update the notebook cells. The cost of upgrading is essentially the cost of rewriting the code to match new APIs. For a one-time learning exercise, that cost is acceptable. For a long-lived project, it is prohibitive. The license situation adds legal uncertainty. NOASSERTION means the repository does not declare a standard license, so you cannot rely on standard permissions. You should contact the owner before copying any code into a proprietary system. The README also mentions external resources for chunking and long-context impact, which means the notebooks do not cover everything themselves. You will need to follow those links to fill gaps, adding to your research time.
Editorial conclusion
Adopt bRAG-langchain if you are a developer or data scientist who learns best by reading and modifying notebook code, and who wants a structured path from a basic RAG chatbot to advanced techniques like RAPTOR, ColBERT, RAG-Fusion, and Self-RAG. Do not use it as a production library: it has no packaged install, no pinned dependencies, and no formal release, so you will need to extract the relevant cells into your own project. Before investing time, verify that your target Python version is 3.11.11, that you have API keys for the services you plan to use (OpenAI, Pinecone, Cohere, and others mentioned in the notebooks), and that you are comfortable with the cost of running multiple embedding and reranking models. The repository is a teaching resource, not a maintained framework, so treat every notebook as a starting point and expect to rewrite the code for your own data and deployment constraints.
Frequently asked questions
What is LangChain, in the context of bRAG-langchain?
It is the framework the notebooks are built on. The requirements file installs langchain plus langchain-community, langchain-core, langchain-openai, langchain-pinecone, langchain-cohere and langchainhub, one package per service the examples call.
What does RAG stand for and what is its purpose?
Retrieval-Augmented Generation. In this repository it is built in layers: a baseline pipeline over a vector store, then multi-query retrieval, routing and query structuring, multi-representation indexing with ColBERT, and finally reranking with reciprocal rank fusion and a Cohere model.
Which Python version does bRAG-langchain need?
Python 3.11.11 is the stated prerequisite, with install steps for macOS, Linux and Windows. If the virtual environment comes up on a different version, the README shows how to make the python command use Python 3.11.
Which API keys do the bRAG-langchain notebooks need?
An OpenAI key for the model and embeddings, Pinecone credentials with an index name and host for the vector store, and a Cohere key for the reranking chapter. The example environment file also enables LangSmith tracing by default.
Which notebook should I start with in bRAG-langchain?
full_basic_rag.ipynb at the repository root, which the README describes as boilerplate starter code for a customisable RAG chatbot. The five numbered notebooks under notebooks/ take the same system apart in stages.
Does bRAG-langchain pin its library versions?
Almost not. Of the entries in requirements.txt only pydantic has a lower bound of 2.7.0 and youtube-transcript-api has an upper bound below 1.0.0. Every LangChain package is unpinned, so a fresh install resolves to current releases.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/bragai-brag-langchain)Star history chart for your README
[](https://hysenlabs.com/projects/bragai-brag-langchain)Was this useful?