OWL: A Multi-Agent Framework That Runs Tasks Through Real Browsers and Terminals
🦉 OWL: Optimized Workforce Learning for General Multi-Agent Assistance in Real-World Task Automation
At a glance
- What is it?
- OWL is a Python framework from the CAMEL-AI project that orchestrates multiple agents over toolkits including browser automation and a desktop commander. It is aimed at teams that need general task automation rather than a single-purpose script, and it carries the operational weight that comes with that scope.
- Who is it for?
- Adopt OWL if you already run Python services and need agents that touch a browser, a shell, or a document pipeline rather than a single API. Do not adopt it if you need a stable released version or an agent that runs without a capable model behind it.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
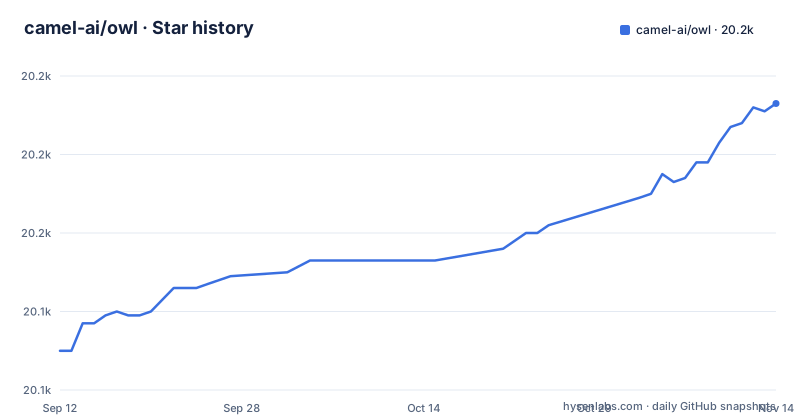
- camel-ai/owl20,191 ★ · +61
| Repository | 2026-09-12 | 2026-11-13 |
|---|---|---|
| camel-ai/owl | 20.1k | 20.2k |
61 Stars in the last 62 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Gap OWL Targets: General Tasks, Not Single-Tool Scripts
Most agent projects pick a lane. They browse, or they write code, or they answer questions over a document set. OWL is built for the case where the task is not known in advance and may require several of those capabilities in sequence. The README frames this as general multi-agent assistance in real-world task automation, and the toolkit list backs that framing: browser interaction, terminal access, and multimodal inputs all sit under the same agent loop. The intended user is an engineer who has a task that spans tools and does not want to hand-write an orchestration layer for each new task shape. The project is written in Python and builds on the CAMEL-AI Framework, so the agent primitives and message passing come from CAMEL rather than from OWL itself. That dependency is the first thing to understand: OWL is an application and toolkit layer on top of another framework, not a standalone agent runtime.
Workers, a Coordinator, and Toolkits: The Architecture the README Shows
The README describes the design as dynamic agent interactions, with the term workforce used for the framework component and optimized workforce learning used for the training methodology. The paper title and the 2025.05.27 news entry both use that vocabulary. In practice this means a set of agents with assigned roles that hand work to each other, plus a registry of toolkits the agents can call. The toolkit split is explicit in the table of contents: multimodal toolkits that require a multimodal model, and text-based toolkits that do not. That split is a real constraint rather than a labeling choice. If your model cannot accept images, the multimodal toolkits are unavailable to you regardless of what the task needs. External capability arrives through the Model Context Protocol, with a Playwright MCP service listed as the browser automation path. Node.js installation instructions for Windows, Linux and Mac appear before the Playwright MCP setup, which tells you the browser tooling is not pure Python and will pull in a separate runtime.
Getting It Running: Four Install Paths and the Environment Variables
The installation section offers four options. Option 1 uses uv and is marked recommended. Option 2 uses venv and pip. Option 3 uses conda. Option 4 uses Docker, and within that option the README distinguishes a pre-built image (also marked recommended) from building the image locally, plus a set of convenience scripts. Python installation is listed as a prerequisite before any of these. After installation you set environment variables, either directly in your shell or through a .env file, which the README presents as an alternative rather than the default. Model configuration is separate from installation: the README has a Supported Models subsection under Model Requirements, and a Running with Different Models section under Quick Start. The repository also documents an MCP Desktop Commander setup step, which is what gives agents terminal-level access. There is a web interface with its own starting instructions and a features list, so you can drive the agent from a browser instead of a script. The owl/ directory holds the examples referenced from the top navigation.
The Model Requirement Is the Real Cost Center
OWL does not ship a model. It expects you to supply one, and the toolkit you can use depends on what that model supports. The multimodal toolkits are gated behind multimodal model capabilities, stated plainly in the toolkit heading. This has a practical consequence that the README does not spell out: the cost of running a task is not fixed by the framework, it is set by how many agent turns the task takes and which model answers them. Multi-agent designs multiply calls, because a coordinator and its workers each consume context. A task that looks cheap as a single prompt can become many billed requests. The repository also has no published GitHub releases, so there is no versioned artifact to pin against. The repository has a main branch and a dated last push, and the news entries reference a gaia69 branch used to replicate the GAIA experiment. If you need a tagged version with a changelog, the repository does not offer one.
Licence and the CAMEL Dependency
The licence is listed as unknown in the repository metadata, and the README links a Package License badge and a License section in the table of contents. pyproject.toml declares license = "Apache-2.0", and the repository has a licenses/ directory rather than a root LICENSE file. Read the licence texts there before you build anything on top of OWL, particularly if you plan to redistribute it or ship it inside a product. The second dependency question is CAMEL. The README has a section titled Exploring CAMEL Dependency with a subsection on accessing CAMEL source code, which suggests the project expects users to read CAMEL internals at some point. That is a signal about where bugs will land. When an agent misbehaves at the message-passing level, the fix may belong in CAMEL, not in OWL, and you would be tracking two repositories instead of one. None of this is legal advice; it is a pointer to what you need to read yourself.
Where OWL Is the Wrong Choice
If your task is a fixed sequence of API calls with known inputs, OWL is heavier than the problem. A script with a retry wrapper will be easier to debug, because there is no agent deciding what to do next. If you need deterministic output for a compliance or audit path, a system where agents choose their own tool sequence is a poor fit; you cannot reproduce a run exactly when the model's choices drive the path. If you cannot supply a capable model, the framework has nothing to run on. And if your environment forbids installing Node.js or a browser automation service, the Playwright MCP path is closed, which removes much of what makes OWL interesting for web tasks. The README also notes that training code for the optimized workforce learning method was still coming soon as of the 2025.07.21 entry, while the dataset and model checkpoints were already open-sourced on Hugging Face. So the training half of the project is partially available, and anyone hoping to fine-tune with the published method should check the current state of that code before planning around it.
How This Differs From a Single-Agent Tool Loop
The obvious alternative is one agent with a tool list, the pattern most agent libraries default to. The difference is structural. A single agent holds the whole task in one context and picks tools one at a time. OWL splits the task across roles, which means a coordinator can delegate a subtask and a worker can report back without the coordinator carrying every intermediate observation. That helps when a task has genuinely separable parts, such as research followed by a browser action followed by a file write. It hurts when the task is short, because you pay coordination overhead for work that one agent could have done in three turns. The other difference is the toolkit breadth. A single-agent library typically gives you function calling and leaves browser and desktop control to you. OWL ships those as named toolkits, including the MCP Desktop Commander setup and the Playwright MCP service, so the integration work is already done at the cost of a heavier install. Choose based on whether your bottleneck is orchestration or tooling.
Maintenance Burden and What to Verify First
Running OWL means maintaining a Python environment, a Node.js runtime for the browser tooling, a browser automation service, and a model endpoint. Each of those can break independently. The .env file approach centralizes configuration, which helps, but the failure modes are spread across layers. The project is active: the last push date in the repository metadata is 2026-11-02, and the news entries run through September 2025 with a NeurIPS 2025 acceptance for the paper. Activity is not the same as stability, and with no published GitHub releases there is no upgrade path with defined breaking changes. Plan to track main and read commits. The benchmark figure the README displays, 69.09 average on GAIA, is a claim from the project's own technical report on arXiv, not an independent measurement, and it describes one benchmark rather than general task performance. Verify it against the paper if the number matters to your decision. The first concrete step is to read the licence files in licenses/, then run one example from owl/ with your chosen model and watch how many turns it takes.
Editorial conclusion
Adopt OWL if you already run Python services and need agents that touch a browser, a shell, or a document pipeline rather than a single API. Do not adopt it if you need a stable released version or an agent that runs without a capable model behind it. Before committing, read the licence files in the licenses/ directory, confirm which model you will point the agent at, and run one of the example tasks under owl/ end to end on your own machine.
Frequently asked questions
What is OWL, the camel-ai project?
OWL stands for Optimized Workforce Learning for General Multi-Agent Assistance in Real-World Task Automation. It is a framework for multi-agent collaboration built on top of the CAMEL-AI framework, and its README reports a 69.09 average score on the GAIA benchmark, ranking first among open source frameworks.
How do the agents in OWL communicate?
The README points to the technical report for the workforce framework and the optimized workforce learning methodology, and the documentation splits capabilities into multimodal toolkits, which need a model with multimodal support, and text based toolkits.
What language is OWL written in?
Python, with `requires-python` set to `>=3.10,<3.13`, hatchling as the build backend, and mypy configured for python_version 3.11. The Model Context Protocol and Playwright path additionally asks for Node.js on Windows, Linux, or Mac.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/camel-ai-owl)Star history chart for your README
[](https://hysenlabs.com/projects/camel-ai-owl)Was this useful?