dqlite turns SQLite into a Raft cluster, and only on Linux
Embeddable, replicated and fault-tolerant SQL engine.
At a glance
- What is it?
- dqlite is a C library that wraps SQLite in a Raft replicated, wire-protocol cluster with automatic failover, embedded in an application rather than run as a separate server. The trade is platform freedom for asynchronous native I/O and a language binding you still have to choose.
- Who is it for?
- Adopt dqlite if your application is a Linux service that wants clustered SQLite with no separate database process and can live with the Linux-only kernel requirement and a hand-picked client binding.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
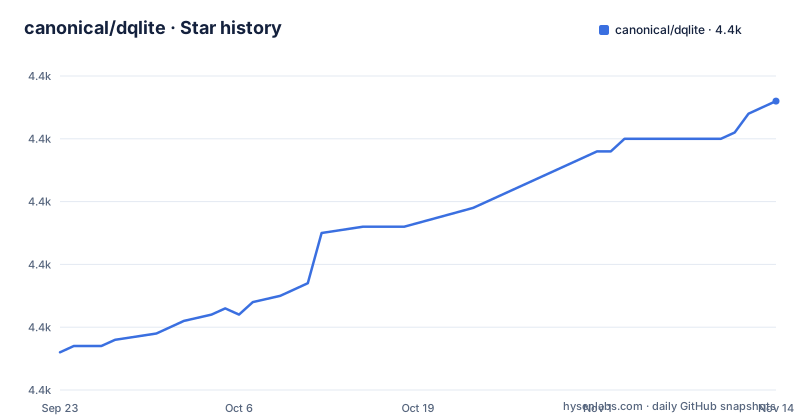
Star history
- canonical/dqlite4,426 ★ · +40
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| canonical/dqlite | 4.4k | 4.4k |
40 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The cluster lives inside your application, not beside it
dqlite is a C library, and that single word decides most of its trade-offs. It implements an embeddable and replicated SQL database engine with high availability and automatic failover, and the name expands to distributed SQLite: it extends SQLite with a network protocol that links several instances of your own application so they behave as one highly available cluster, with no dependency on external databases.
The audience is therefore narrow and specific. If you run a service on Linux, ship the same binary across several machines, and would rather not operate a database server, dqlite fits. It is not a replacement for a client library, because there is no client library here either: the wire protocol documentation lives at dqlite.io/docs/protocol and is aimed at people writing a client from scratch.
The repository says so plainly by pointing elsewhere for the first thing a new user wants. The README routes you to the demo program shipped with the Go dqlite bindings and to that project's documentation, rather than offering a demo of its own. That single line is the honest description of the project's shape: libdqlite is the engine, and every usable client today comes from a binding maintained separately.
libuv and native async I/O narrow the field to Linux
The implementation is asynchronous and single-threaded, with libuv as the event loop, and dqlite ships a custom wire protocol tuned for SQLite primitives and data types. Replication follows the Raft algorithm. Put together, that means one event loop drives both the network and the database work.
The cost is stated in the Compatibility section without hedging: dqlite runs on Linux and requires a kernel with support for native async I/O, and the README is careful to say this is not to be confused with POSIX AIO. A kernel that offers only the POSIX interface will not carry dqlite, and the README does not document a fallback path for it.
That single line removes macOS, Windows and any BSD target from the conversation before anything else is discussed. Everything else in the design follows from that choice: single-threaded because the engine is inside an event loop, custom protocol because the wire format is shaped around what SQLite can express, Raft because replication has to agree across those event loops.
Building libdqlite from source is the only install path with a version floor
Debian-based systems can take a recent build from the dqlite dev PPA, which is the shortest route and also the least controlled one:
sudo add-apt-repository ppa:dqlite/dev
sudo apt update
sudo apt install libdqlite-dev
Building from source needs pkg-config and GNU Autoconf, Automake, libtool and make, plus headers for libuv at v1.8.0 or later, SQLite at v3.22.0 or later, and optionally LZ4 at v1.7.1 or later for compression. On a Debian-based distribution the dependencies install like this:
sudo apt install pkg-config autoconf automake libtool make libuv1-dev libsqlite3-dev liblz4-devWith those in place the build is the ordinary autotools sequence, and you should end up with a shared library and headers under /usr/local:
$ autoreconf -i
$ ./configure
$ make
$ sudo make install
Because the default prefix is /usr/local, the dynamic linker may not find libdqlite.so afterwards, which is what the ldconfig step is for. A different prefix is a configure flag:
$ sudo ldconfig$ ./configure --prefix=/usrStatic linking needs a flag and a larger stack
Two build details get their own section in the README.
The first is --with-static-deps. Passing it to configure disables code that relies on dependencies being dynamically linked. The README then adds a parenthetical that deserves attention: currently this only affects the test suite, and you should use the flag anyway even when building libdqlite.a only, for future compatibility. So the flag is a precaution, not a current requirement, and the project says so rather than overselling it.
The second is a stack size problem when linking against musl libc. The default musl stack is too low for dqlite's needs, and the fix is passed through LDFLAGS:
LDFLAGS="-Wl,-z,stack-size=1048576"One megabyte. If you ship dqlite inside a statically linked binary on Alpine or any other musl base, this is the setting the README recommends. The contrib/build-static.sh script exists to demonstrate building and testing dqlite with every dependency, libc included, statically linked.
One inconsistency is worth flagging for anyone reading the container recipe. The Dockerfile still references go1.15.2 and clones canonical/raft and canonical/go-dqlite alongside the library, so the image described in the repository is anchored to an old Go toolchain.
dqlite-utils is a snap, and inspecting a node is a separate install
There is no server to start and no CLI shipped with the library, which catches out anyone expecting a database server binary.
The library takes its tracing level from the `LIBDQLITE_TRACE` environment variable, which must be set before startup.
The range is 0 to 5, where 0 emits nothing and 5 is the minimum level, FATAL records only. The README's numbering runs the opposite way to intuition: 1 is the maximum verbosity, emitting DEBUG, INFO, WARN, ERROR and FATAL, and 5 is the quietest setting that still emits something. A reader who assumes a larger number means more output will run with essentially no logs and conclude the engine is silent.
Where dqlite differs from rqlite and Litestream
The README itself points to a 2022 blog post comparing dqlite with rqlite and Litestream, other replication software for SQLite, which is an admission that the comparison matters.
The difference is in what gets embedded. dqlite is a C library linked into your application, with the Raft layer and the wire protocol inside the process. rqlite takes the opposite shape: it exposes SQLite over its own service boundary, so a program talks to it as a client rather than linking it. Litestream sits on a third axis entirely, replicating the SQLite file itself to object storage for continuous backup rather than running a consensus group that clients write through.
So the choice is about where the database lives relative to your process. Embedding removes a network hop and a deployment unit, and it means a cluster is as available as the application instances you already run. In exchange you accept that the database is only as durable as your own binary's upgrade path, that every node must run Linux with native async I/O, and that client code has to be written against dqlite's protocol or taken from a binding.
If your architecture already has a distinct database tier that operations staff know how to monitor and back up, that separation is a real asset and dqlite gives it up.
What to check before you commit a build pipeline to it
The constraint list is short enough to hold in your head. Linux only, with native async I/O required from the kernel. libuv v1.8.0 or later, SQLite v3.22.0 or later, and LZ4 v1.7.1 or later if you want compression. The engine is single-threaded and asynchronous on a libuv event loop, so it belongs inside an event-driven service and would fight an application built on blocking threads.
Two things the documentation leaves open deserve attention before adoption. The README does not document a migration path for moving data between dqlite nodes yourself, and it does not document rollback of an applied schema change. For a system where you intend to run migrations across a cluster, both are questions to ask before the first production rollout rather than during one.
The repository is not archived, and the last push was on 2026-10-30. The library carries a slightly modified LGPLv3 with a copyright exception permitting static linking.
Editorial conclusion
Adopt dqlite if your application is a Linux service that wants clustered SQLite with no separate database process and can live with the Linux-only kernel requirement and a hand-picked client binding. Do not adopt it for a desktop app, a mixed-OS deployment, or a team that wants an operational tool it can run without linking C. Verify first that your target kernels provide io_setup and that the binding you intend to use, such as the Go bindings, actually covers the calls you need, since the C library exposes no command line of its own.
Frequently asked questions
Is dqlite just SQLite with a network protocol?
It extends SQLite with a network protocol and Raft based replication, and it runs its own custom wire protocol optimized for SQLite primitives and data types rather than speaking the standard SQLite file format over the wire.
What operating systems can dqlite run on?
dqlite runs on Linux only, and requires a kernel with support for native async I/O, which the README notes is not the same as POSIX AIO.
How do I try dqlite without writing a client?
The README points to the demo program that comes with the Go dqlite bindings, and to that project's own documentation for the demo. The C library ships no command line of its own.
How do I inspect a running dqlite node?
The README does not describe an inspection tool; it points to the demo program in the Go dqlite bindings and documents LIBDQLITE_TRACE for detailed tracing.
How is a static dqlite build different?
Pass --with-static-deps to configure, which disables code that relies on dependencies being dynamically linked. When linking against musl libc, also raise the stack size, since the default is too low for dqlite.
How do I turn on logging in dqlite?
Set LIBDQLITE_TRACE before startup, with a value from 0 to 5. The scale runs the opposite way to intuition: 0 emits no traces, 1 is the most verbose and emits DEBUG, INFO, WARN, ERROR and FATAL, and 5 emits FATAL records only.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/canonical-dqlite)Star history chart for your README
[](https://hysenlabs.com/projects/canonical-dqlite)Was this useful?