AI 驯龙笔记 (ai_wiki): A Chinese-Language AI Engineering Notebook, Not a Library
AI Full Stack — a site collecting the best resources from across the web, documenting solutions and key points for engineering problems, sharing practical case studies and tracking cutting-edge developments. Covers the full AI stack: large language models, programming, machine learning, deep learning, reinforcement learning, graph neural networks, speech recognition, NLP and image recognition.
At a glance
- What is it?
- ai_wiki is a directory of Markdown and Jupyter notes covering everything from MySQL to RAG, with no package to install and no releases to pin. The judgement: it is a reading resource for Chinese-speaking engineers, and the README's own badge and licence mismatch is the first thing to check.
- Who is it for?
- Adopt ai_wiki as a reading list and a source of worked examples if you read Chinese and want a single index across LLM, RAG, Agent, vector database and classical deep learning topics. Do not adopt it if you need an installable dependency, a versioned API, or English documentation.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 36 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
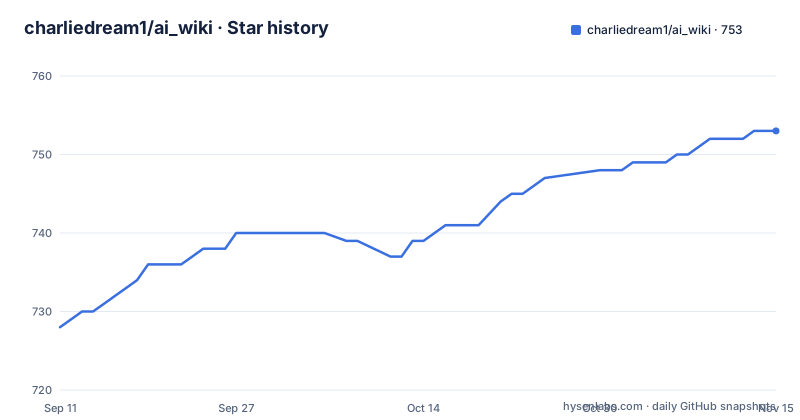
- charliedream1/ai_wiki753 ★ · +25
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| charliedream1/ai_wiki | 728 | 753 |
25 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What ai_wiki is, and the problem it actually solves
The repository describes itself as a collection site for outstanding resources across the web, a place that records strategies and key points for solving engineering problems. That framing is accurate: this is a knowledge base, not a library. There is no package name to install, no import statement, no CLI. The primary language is listed as Jupyter Notebook, which tells you the unit of content is a notebook or a Markdown file that a reader opens and reads, not a module that a program calls. The problem it addresses is fragmentation. An engineer working on a retrieval augmented generation pipeline in Chinese has to find material on document parsing, vector indexing, reranking and evaluation across four or five separate sources. The README's knowledge tree puts those under one roof: 35_RAG covers parsing, retrieval optimisation, knowledge graph RAG, memory RAG, agentic RAG, internet RAG and evaluation. Whether every one of those subdirectories is populated is not something the README states, and you should check before assuming coverage. The intended audience is Chinese-speaking developers moving from classical deep learning into large model work, or practitioners who already ship models and want a reference shelf. The README's stated goal is to help developers master AI technology efficiently and improve application ability, which is a reasonable description of a curated index rather than a product.
How the knowledge tree is organised, and why the numbering matters
The structure is a set of numbered top-level directories, grouped into seven clusters. The first cluster covers programming foundations and engineering practice: 01_系统平台网站, 02_程序代码, 03_算法原理, 04_对象存储容器. The second covers storage: 05_数据库 for MySQL and Redis, 06_向量数据库 for Milvus, Chroma, Faiss, Vespa and ElasticSearch, and 07_图数据库 for Neo4j and NebulaGraph. The third cluster is theory: 10_数学基础 through 15_数据工程, including 13_强化学习 and 14_图网络. The fourth covers applied classical deep learning: 20_图像识别, 21_NLP文本处理, 22_音频, 23_时间序列, 24_视频分析. The fifth is the large model cluster: 31_LLM, 32_多模态, 33_图像视频, 34_Prompt工程, 35_RAG, 36_Agent, 37_其它应用. The sixth covers deployment and tooling: 09_模型部署, 38_开发工具及注意事项, 39_具身智能_数字人, 40_深度学习_工具, 41_显卡硬件, 42_数据接口. The seventh is a mixed personal and career group: 50 through 78, including 面试, 招聘信息, 专利及著作权, 执业证书, 团队管理 and 软技能. That last group is the tell. A repository that files interview preparation, patent records and team management alongside vector database notes is a personal working archive that was made public, not a curated product with an editorial boundary. The numbering has gaps (08, 16 through 19, 25 through 30) which suggests the tree grew organically. The README presents each module as providing detailed cases and code, but it does not give per-directory file counts, so the depth of, say, 06_向量数据库 relative to 36_Agent is not determinable from the README alone.
Getting it running: there is nothing to install
The README's quick start is three numbered prose steps, not commands. It says: choose a topic using the directory above, read the content since each module provides detailed cases and code for direct reference, then apply the knowledge to real engineering problems. That is the entire onboarding. There is no pip install line, no conda environment file referenced, no Dockerfile mentioned, no configuration keys documented. The only version constraint anywhere in the README is the Python badge, which reads Python 3.8+. If you want the content locally, the practical route is a clone of the default branch, master, and the README also points at a Gitee mirror at gitee.com/charlie1/ai_wiki.git for readers who prefer that host. Because the primary language is Jupyter Notebook, expect individual notes to carry their own dependencies inside cells, and expect those dependencies to vary by directory. A note under 06_向量数据库 will assume a Milvus or Chroma client; a note under 31_LLM will assume something else. Nothing in the README promises a shared environment, a lockfile or a tested dependency set. The citation block gives a BibTeX entry with author Yi Li and year 2022, which is the only authorship information provided. Treat every notebook as a standalone document with its own assumptions, and read the imports at the top of each one before running it.
The licence discrepancy is the first thing to resolve
The README carries a shields.io badge reading License Apache 2.0, linked to opensource.org/licenses/Apache-2.0. The repository metadata supplied for this review lists the licence as unknown. Those two statements do not agree, and the badge is a self-declared marker rather than a licence file. Apache 2.0, if it is in fact the governing licence, is permissive and includes an explicit patent grant, which is the reason many companies allow it. But a badge in a README is not the same as a LICENSE file at the repository root, and the repository does not confirm that such a file exists. This is not a legal opinion and I am not giving one. The practical point is narrower: before you copy code from any notebook in this repository into a product, confirm what the repository actually ships as its licence, because the two sources you have available disagree. If your organisation has a policy requiring a recognised licence file, that policy cannot be satisfied by a badge image. This is the single highest-value check to perform before spending time on the content.
Where it is the wrong tool
If you need a maintained dependency, ai_wiki is the wrong choice and no amount of reading fixes that. The repository has no published GitHub releases, so there is nothing to pin, no changelog to read, and no semantic version to reason about when an upstream API changes. A notebook that calls a vector database client will silently rot when that client changes its interface, and nothing in the repository structure described here suggests a mechanism for detecting that. The second failure mode is language. The README is written in Chinese, the directory names are in Chinese, and the description is in Chinese. An English-only team gets an index it cannot read and notes it cannot skim. The third is scope drift. Because the tree includes 73_招聘信息 (recruitment information), 71_专利及著作权 (patents and copyright) and 78_团队管理 (team management), the repository is not a technical reference with a defensible boundary. If you want a reference you can hand to a new engineer and say read all of this, you cannot, because parts of it are one person's career notes. The fourth is verification. The README claims each topic is grounded in an engineering problem and provides complete solution strategies and key code, but claims of completeness in a personal knowledge base are exactly the kind of thing that varies per directory. Nothing in the repository lets you audit that claim in aggregate.
A real alternative, and the difference in approach
Hugging Face's course materials and the Hugging Face Transformers documentation occupy overlapping territory for the LLM and NLP portions of this tree, and the difference is structural rather than topical. Hugging Face maintains documentation and courses as versioned artefacts tied to library releases: when the Transformers API changes, the docs change with it, and the version you read corresponds to the version you install. ai_wiki has no such coupling. Its notes are dated by commit, not by library version, and the repository has no published GitHub releases. The trade is real in both directions. Hugging Face gives you correctness guarantees for one ecosystem and almost nothing about vector database selection, graph databases, GPU hardware tuning, or the deployment and evaluation concerns spread across directories 06, 07, 09 and 41 here. ai_wiki gives you breadth across those topics and no guarantee that any single note still matches the library it describes. If your question is how do I call this specific model, the versioned documentation wins. If your question is what does the space of options look like across vector stores and graph stores and RAG evaluation, the notebook collection covers ground that a single-vendor documentation set does not attempt.
Maintenance cost and what the update cadence tells you
The last push recorded in the metadata is 2026-08-28, and the repository is not archived, so it is being touched. There are no releases, which means there is no upgrade path in the software sense: you do not upgrade ai_wiki, you re-read it. The maintenance cost therefore falls on you rather than on the maintainer. Every time you lift a code fragment from a notebook, you own the job of checking it against the current version of whatever library it imports. The README does not describe a contribution process beyond pointing at GitHub Discussions for discussion and GitHub Issues for problems, and it directs readers to a paid community for additional support. That is a legitimate model for a personal knowledge base, but it means the correction loop is informal. If a note is wrong, there is no test suite that will catch it. The Gitee mirror at gitee.com/charlie1/ai_wiki.git is worth noting for readers in regions where GitHub access is unreliable, though a mirror adds its own question of how promptly it syncs with master. Neither the README nor the metadata states a sync policy.
Editorial conclusion
Adopt ai_wiki as a reading list and a source of worked examples if you read Chinese and want a single index across LLM, RAG, Agent, vector database and classical deep learning topics. Do not adopt it if you need an installable dependency, a versioned API, or English documentation. Before relying on any single note, verify the licence question first: the README badge points at Apache 2.0 while the repository metadata reports no licence, and that discrepancy matters the moment you copy code into a product. Then check the specific subdirectory you care about, because the repository is organised as numbered folders and the depth of each one is not described in the README.
Frequently asked questions
What is inside the charliedream1/ai_wiki repository?
It is a Chinese, notebook-first collection of 54 top-level directories covering programming practice, databases, vector and graph stores, machine learning theory, traditional deep learning applications, large model work, tooling and deployment, plus personal career notes. The README index names 44 modules.
How do I install charliedream1/ai_wiki?
There is nothing to install. The quick start is three lines telling you to pick a topic, read it and apply it, and the top level holds directories plus README.md and README_EN.md with no dependency file or build script. The primary language is recorded as Jupyter Notebook.
What licence does charliedream1/ai_wiki use?
The README carries an Apache-2.0 badge, and the repository's licence metadata field carries no value. No licence file appears among the top-level entries, so the badge is the only statement available.
Does charliedream1/ai_wiki publish releases?
No. The repository has no GitHub releases, so there is no tag to install or pin. The BibTeX entry the README offers for citation still gives the year as 2022.
Do all the links in the ai_wiki README resolve?
Two of the index rows do not: 09_模型部署/ and 76_博客及知识星球/ have no matching top-level directory, and 76_自媒体/ sits in the second slot instead. The frequently-asked-questions entry lower down links to an empty target.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/charliedream1-ai-wiki)Star history chart for your README
[](https://hysenlabs.com/projects/charliedream1-ai-wiki)Was this useful?