RAG_Techniques: 42 Tutorial Notebooks for Moving Retrieval-Augmented Generation Past the Basics
This repository showcases various advanced techniques for Retrieval-Augmented Generation (RAG) systems. Each technique has a detailed notebook tutorial.
At a glance
- What is it?
- NirDiamant/RAG_Techniques is a community-driven collection of over 42 Jupyter notebooks that teach advanced retrieval-augmented generation methods, from query rewriting to agentic RAG. It is a learning resource, not a library, so its value depends on how you use notebooks.
- Who is it for?
- Adopt RAG_Techniques if you are a developer or ML engineer who learns by reading and running code, and you want a broad survey of advanced RAG methods without committing to a single framework. The notebooks show concrete implementations, so you can see how each technique fits into a real pipeline.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 12 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
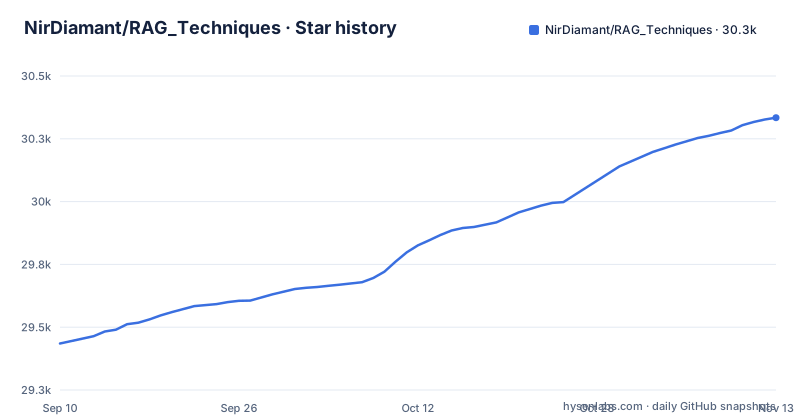
Star history
- NirDiamant/RAG_Techniques30,334 ★ · +899
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| NirDiamant/RAG_Techniques | 29.4k | 30.3k |
899 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What This Repository Actually Is
NirDiamant/RAG_Techniques is not a software package or a framework. It is a collection of Jupyter notebooks, more than 42 of them according to the README, each presenting one advanced technique for retrieval-augmented generation. The repository positions itself as a community-driven hub that teaches the intuition, the code, and the references behind each method. The intended audience is people who already understand the basic RAG loop of indexing, retrieving, and generating, and who now want to see how to improve accuracy and context handling. The README describes the coverage as going from foundational to cutting-edge, but the material itself is tutorial code, not a deployment toolkit. If you need a drop-in solution for a production RAG service, this repository will not give you that. If you need to learn what techniques exist and how they are implemented in practice, it likely will.
The Techniques Covered and How They Fit Together
The repository organizes its content by technique, and each technique gets its own notebook. The coverage includes agentic RAG, embeddings, semantic search, and vector databases, plus the usual advanced RAG methods like query rewriting, chunking strategies, and re-ranking. The README claims the notebooks go from foundational to cutting-edge, which suggests a deliberate progression. The inclusion of agentic RAG is notable because that is a newer pattern where an LLM decides how to retrieve, rather than following a fixed retrieval step. The notebooks are meant to be runnable, so you can execute them locally and see the outputs. The repository does not appear to provide a unified data flow across all notebooks; each one is a self-contained tutorial. That is a strength for learning one technique at a time, but it means you will not find a single pipeline you can copy and adapt wholesale. You have to extract the idea and integrate it into your own system.
Running the Notebooks: Commands and Setup
The notebooks live in all_rag_techniques/, with runnable script versions in all_rag_techniques_runnable_scripts/ and a shared helper_functions.py at the root. A typical workflow would be to clone the repository, create a Python virtual environment, and install the dependencies listed in each notebook. Since the notebooks are the primary content, you run them with Jupyter: jupyter notebook or jupyter lab from the repository root. The repository has a release called book-v1.0 from April 2026, which is a companion book, but that is separate from the notebooks. A second release, ai-agents-book-v1.0, followed on 2026-10-26 for the author's AI Agents Made Simple book. The last push to the repository was November 2026, so the content is actively maintained.
The Learning Format: Intuition, Code, References
Each notebook is structured to give you three things, as the README states: the intuition, the code, and the references. That means you are not just getting a code dump. You get an explanation of why a technique works, a working example, and pointers to further reading. This is a good format for understanding trade-offs. For instance, a notebook on chunking might explain how smaller chunks improve retrieval precision but lose context, then show you code that adjusts chunk size. The repository also links to paid books and a newsletter, which suggests the author treats this as a funnel for deeper learning. That commercial angle is worth noting, but it does not diminish the value of the free notebooks. The content is accessible without paying, and the repository is not archived, so it is still being updated.
A Real Limitation: Breadth Over Depth and Version Drift
The main limitation is that a repository of 42+ notebooks cannot give each technique the depth it deserves. You get a working example, but not a rigorous comparison of when to use one technique over another. The README says the notebooks cover from foundational to cutting-edge, but cutting-edge in RAG changes quickly. A notebook written in 2024 might use an API that is deprecated in 2026. The last push is recent, but that does not guarantee every notebook is updated. You will likely need to adapt the code to your own library versions, especially if you use a different LLM provider than the one in the notebook. Another limitation is that the repository is not a framework, so you cannot simply pip install it and call a function. You have to read the code and translate it into your own project. For a beginner, that is a barrier. For an experienced engineer, it is a benefit because you are forced to understand the implementation.
Alternatives: LangChain and LlamaIndex Documentation
The main alternative to this repository is the official documentation and cookbooks of the frameworks it uses, namely LangChain and LlamaIndex. Both projects have extensive tutorials and example notebooks that cover advanced RAG techniques like parent document retriever, self-query, and agentic retrieval. The difference is in approach. LangChain and LlamaIndex documentation is organized by framework, so you learn techniques within a consistent API and ecosystem. RAG_Techniques is organized by technique, independent of a single framework. If you already work heavily in one framework, the official docs will be more coherent and up to date. If you want a framework-agnostic survey to decide which techniques matter, RAG_Techniques is more useful. The repository also includes its own references, which can point you to the original papers behind each method.
Maintenance, License, and Upgrade Cost
The repository is actively maintained, with the last push in November 2026 and a recent book release in October 2026. That suggests the author is invested in keeping the content current. However, the license is listed as NOASSERTION, which means GitHub could not identify the license in the repository's LICENSE file. This is a red flag for code reuse. You can read and learn from the notebooks freely, but if you want to copy code into a commercial product, you need to read the LICENSE file. The upgrade cost is moderate. Since the notebooks are standalone tutorials, you do not have to upgrade a library or migrate a codebase. But you do have to maintain your own adaptation of the techniques, because the repository will not provide versioned releases of the notebook code. The book release is a separate artifact, so the notebooks themselves may not follow semantic versioning.
Who Should Adopt It and What to Verify First
This repository is best for practitioners who want a broad, hands-on introduction to advanced RAG techniques and who are comfortable extracting ideas from tutorial code. It is not the right tool for someone who wants a production library or a single, authoritative implementation. Before you rely on any notebook, verify the date it was last updated and the versions of the libraries it imports. Check whether the notebook uses an API that has changed, such as the OpenAI SDK or a LangChain component. Also verify the license for any code you plan to reuse, given the NOASSERTION status. If you are evaluating whether to use a specific technique like query rewriting or agentic RAG, start with the corresponding notebook, run it, and then compare its approach with the official documentation of your chosen framework. The repository is a starting point, not a destination.
Editorial conclusion
Adopt RAG_Techniques if you are a developer or ML engineer who learns by reading and running code, and you want a broad survey of advanced RAG methods without committing to a single framework. The notebooks show concrete implementations, so you can see how each technique fits into a real pipeline. Do not use it if you need a production-ready library or a maintained codebase with clear versioning; the repository is a tutorial hub, and the license is listed as NOASSERTION, which means you should verify the terms for any code you plan to reuse. Before relying on any notebook, check the publication date of the technique and the versions of the libraries it imports, because RAG methods and their implementations change quickly. Start with the notebook on query rewriting to get a feel for the style, then move to the agentic RAG tutorials if you want to see how retrieval can be controlled by an LLM-driven loop.
Frequently asked questions
What is RAG Techniques?
RAG_Techniques is a community-driven collection of 42+ runnable Jupyter notebooks on retrieval-augmented generation, moving from foundational techniques to more advanced ones, with each technique presented as its own notebook tutorial. The repository is a teaching hub written in notebooks, not a library you install.
How do I run the RAG_Techniques notebooks?
No dependency manifest sits at the top level of the repository. The runnable material sits in all_rag_techniques_runnable_scripts/, the notebooks in all_rag_techniques/, and a shared helper_functions.py sits at the root, which means the libraries each technique needs have to be read out of the cells themselves.
Is RAG_Techniques still being worked on?
The last push to the repository was on 2026-11-02 and the project is not archived. The tagged releases are book-v1.0, a visual companion book published on 2026-04-15, and ai-agents-book-v1.0 for the author's AI agents book on 2026-10-26, so there is no code version to pin to.
Can I import RAG_Techniques into my own RAG system?
No. The top level carries no package manifest, and the primary language of the repository is Jupyter Notebook, so what you get is a worked pattern rather than an API. Ingestion, indexing and evaluation have to be built on your side.
Does RAG_Techniques benchmark the techniques it teaches?
Not in any shared way. The repository includes evaluation/ and tests/ directories, but no results file or leaderboard sits at the top level, so nothing records how a technique scored. Any figure inside a notebook belongs to that notebook.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nirdiamant-rag-techniques)Star history chart for your README
[](https://hysenlabs.com/projects/nirdiamant-rag-techniques)Was this useful?