ClearML: Two Lines of Code for Experiment Tracking, and the Server You Will Have to Run
ClearML - Auto-Magical CI/CD to streamline your AI workload. Experiment Management, Data Management, Pipeline, Orchestration, Scheduling & Serving in one MLOps/LLMOps solution
At a glance
- What is it?
- The clearml Python package is the instrumentation layer of a five-part MLOps suite: experiment tracking, dataset versioning, orchestration, serving and reports. It is genuinely low-friction to add to a training script, but the package is only the client half of the system, and the server half has to be self-hosted or used through the free hosted tier.
- Who is it for?
- Adopt clearml if you want experiment tracking, dataset versioning and remote execution behind one Python client and you are willing to run the ClearML server, either self-hosted or on the free tier. Do not adopt it if you only need local run comparison, or if nobody on the team wants to own a server and an agent fleet, because the client package is not useful on its own.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 12 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
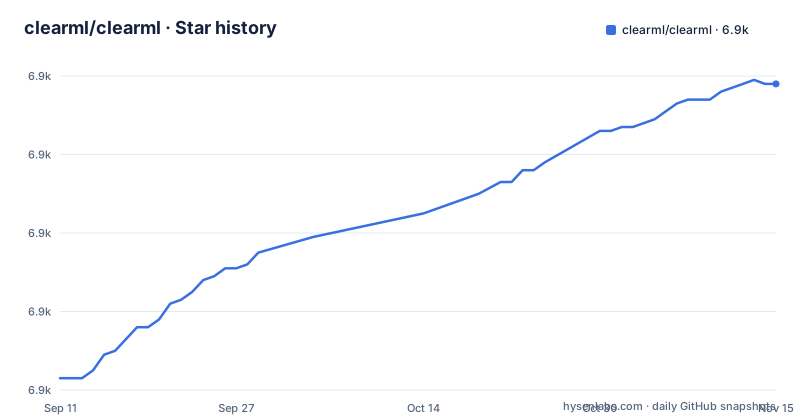
- clearml/clearml6,938 ★ · +75
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| clearml/clearml | 6.9k | 6.9k |
75 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What the clearml Package Actually Solves
The problem is the gap between a training script that produced a good result and anyone else being able to say what was in it. The README frames the package as the instrumentation layer of a larger suite, and the first module it lists is the Experiment Manager, which it describes as automagical experiment tracking, environments and results. The claim is that adding only two lines to your code gets you a complete experiment setup log: source control info including non-committed local changes, the execution environment with specific package versions, hyper-parameters pulled from argparse, Click, PythonFire, Hydra or an explicit dictionary, and the initial model weights file. Output capture is listed as stdout and stderr, resource monitoring for CPU and GPU utilization, temperature, IO and network, model snapshots, artifacts, and TensorBoard or TensorboardX scalars, metrics, histograms, images, audio and video samples. The audience is a team running enough training jobs that manual note-taking has already failed. A single researcher comparing three runs in a notebook is not the target; the target is a group where a result has to survive the departure of the person who produced it.
The Client Is Only Half the System
The most important architectural fact in the README is easy to skim past: instrumenting these components is the ClearML-server, with links to a self-hosting page and a free tier hosted at app.clear.ml. That sentence defines the boundary of what this repository gives you. The clearml package on PyPI is a client that talks to a server; the server is where experiments, datasets, queues and reports live. The README also points outward to sibling repositories for the other modules: clearml-agent for orchestration, automation and pipelines across Kubernetes, cloud or bare metal; clearml-serving for model endpoints; and clearml-fractional-gpu for container-based, driver-level GPU memory limitation. The repository you are looking at is one piece of a distributed system, and the pieces are versioned and released separately. That matters for adoption because a decision to use clearml is not a decision to install a library. It is a decision to run a service, or to depend on someone else's service, and to keep client and server versions compatible across a fleet of machines that are all reporting into the same place.
Getting a Script Reporting: Two Lines and a Config File
The README's central promise is the two-line integration, and the tutorials it links are the concrete path: three Colab notebooks under docs/tutorials cover experiment management, remote execution agent setup, and remote execution, in that order. Beyond the code change, the client needs to know which server to talk to and under which credentials, so the exact config file contents are something to read from the docs site rather than from this page. What the README does establish is the shape of the workflow: you instrument a script, it reports to a server, and then the second and third tutorials move you from watching runs to having an agent execute them remotely. The remote execution path is where the suite stops being a tracking tool. An agent picks up a job from a queue, reconstructs the environment from the captured setup, and runs it on a worker. The environment capture that looked like a nice-to-have in the first tutorial becomes load-bearing in the third.
Where the README Stops Being Useful
The documentation surface described here is a marketing-shaped README: module list, badges, animated GIFs, and a Colab path. Its opening sections do not cover how many services the self-hosted deployment runs, what backing store it needs, how upgrades are performed, or what happens to in-flight experiments during a server restart; for self-hosting it links to separate documentation. The release cadence is visible and brisk: v2.1.10, v2.1.11 and v2.1.12 all landed between July and August 2026. Frequent patch releases are normal for a client that has to track many ML frameworks, but they also mean your server and your agents should not drift far apart. The README's own framing, a suite of five main modules with two more linked at the bottom, is a fair description of scope and also a warning: the surface area you are adopting is larger than the package name suggests.
Automatic Capture Is Convenient Until It Is Not
The design choice at the centre of the Experiment Manager is that capture is automatic and broad: source control state including uncommitted local changes, installed package versions, hyper-parameters from argparse, Click, PythonFire, Tensorflow Defines and Hydra, stdout and stderr, resource telemetry, and model snapshots. That breadth is why the two-line pitch works, and it is also the failure mode. A system that records everything will happily record things you did not intend to publish, and the README's list of captured items includes exactly the categories where that goes wrong: uncommitted local changes can carry credentials or internal hostnames, stdout can carry data samples, and a model snapshot upload to shared storage is a copy of your weights in a location you may not have thought about. None of this is a defect in the library; it is the cost of the convenience. The practical consequence is that artifact storage destinations and the scope of what gets uploaded are decisions to make deliberately, not defaults to accept. The README lists shared folder, S3, GS, Azure and HTTP as artifact destinations, which means the upload path is configurable, which means it is also configurable wrongly.
The Alternative: MLflow and the Difference in Shape
The obvious comparison is MLflow, which also offers experiment tracking with a Python client and a server component, and also has a model registry and a serving story. The difference is in how the pieces are packaged. MLflow is one project with one release cadence covering tracking, projects, models and registry, so a version bump moves all of it together. ClearML splits the same functional territory across separate repositories with separate release streams: this package for tracking and datasets, clearml-agent for orchestration, clearml-serving for endpoints, clearml-fractional-gpu for GPU memory limits. That split lets you adopt tracking without adopting orchestration, which is a real advantage for a team that already has a scheduler. It also means compatibility between the parts is a thing you manage rather than a thing the project manages for you. If you want the smallest number of moving parts and you do not need remote execution or fractional GPUs, MLflow's single-package model is easier to reason about. If you specifically want the orchestration dashboard, the agent fleet and the fractional GPU support in one coherent system, that is the case ClearML is built for.
Licence, Upgrades and the Cost You Own
The client code in this repository is Apache-2.0, which permits commercial use and modification with the usual notice and patent terms attached. That is the licence on the code you are reading, and it is not legal advice about the server you deploy or any hosted tier you sign up for; read the terms of whatever you actually run. The maintenance cost that follows from the architecture is version alignment. With releases arriving roughly monthly in the v2.1.x line, a self-hosted deployment has a recurring obligation: upgrade the server, upgrade the agents, and confirm that experiments recorded by older clients still render correctly. The agent side is the heavier half, because it reconstructs training environments on workers, and environment reconstruction is where ML infrastructure usually breaks. The README's environment capture records what a run used; it does not promise that the same environment can be rebuilt on a different host. Teams that treat the captured environment as a reproducible build recipe will be disappointed. Teams that treat it as a record and keep their own container images will be fine.
Editorial conclusion
Adopt clearml if you want experiment tracking, dataset versioning and remote execution behind one Python client and you are willing to run the ClearML server, either self-hosted or on the free tier. Do not adopt it if you only need local run comparison, or if nobody on the team wants to own a server and an agent fleet, because the client package is not useful on its own. Before committing, verify three things against your own environment: that a self-hosted server deployment is something your team can maintain, that your object storage credentials work with the artifact upload path, and that the agent image you build can reproduce your training environment, since the README's environment capture is a record of what ran, not a guarantee that it will run again. The Apache-2.0 licence covers the client code in this repository; the server deployment is a separate concern, so check what you are actually installing before you assume the licence settles it.
Frequently asked questions
What is ClearML for?
It is a machine learning and deep learning development and production suite built from five main modules: an Experiment Manager, an MLOps and LLMOps layer for orchestration and pipelines, Data Management, Model Serving, and Reports. Orchestration, model serving and fractional GPUs live in separate repositories.
Is ClearML open source?
Yes. The repository is Apache-2.0, and setup.py records the licence as Apache License 2.0 with a Development Status of Production/Stable. Alongside the code there is a free tier of the hosted service at app.clear.ml, and documentation for running your own server.
How to install ClearML?
The README's documented first step is to sign up for the free hosted service, or to set up your own ClearML server through the self-hosting documentation. The client package is published on PyPI as clearml.
what does clearml do
Adding two lines to a training script captures a complete setup log: source control information including non-committed local changes, the execution environment with package versions, hyper-parameters from argparse, Click, PythonFire, Tensorflow Defines or Hydra, and the initial model weights. stdout, stderr, resource usage, snapshots, artifacts and framework output are captured too.
is clearml free
The README advertises a free ClearML Hosted Service and links a free tier hosting option next to the self-hosting documentation, so you can start without running a server. The code in this repository is Apache-2.0.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/clearml-clearml)Star history chart for your README
[](https://hysenlabs.com/projects/clearml-clearml)Was this useful?