PocketSphinx 5.1.1: the small recognizer that still ships a decoder and an aligner
A small speech recognizer
At a glance
- What is it?
- PocketSphinx is the compact, pure C speech recognizer from Carnegie Mellon University, and its command line program does more than transcribe: it can force-align audio to a known word sequence. The tradeoff is old algorithms and models, not build complexity.
- Who is it for?
- Adopt PocketSphinx when you need an offline recognizer you can link into a C program, a wake word pipeline that must run on a Raspberry Pi, or word and phone level timestamps for annotation, and the default acoustic and language model is acceptable. Do not adopt it for open vocabulary dictation or anything where modern neural accuracy matters.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 33 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
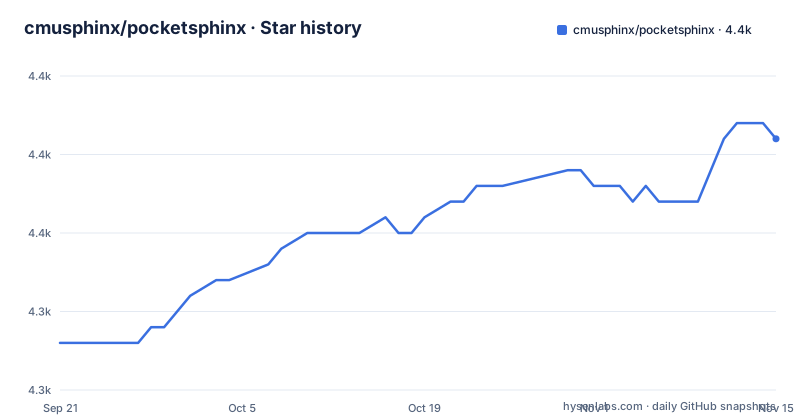
- cmusphinx/pocketsphinx4,356 ★ · +13
| Repository | 2026-09-21 | 2026-11-15 |
|---|---|---|
| cmusphinx/pocketsphinx | 4.3k | 4.4k |
13 Stars in the last 55 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A recognizer sized for embedded targets, not for dictation
PocketSphinx is one of Carnegie Mellon University's open source large vocabulary, speaker independent, continuous speech recognition engines, and the README is blunt about where its algorithms sit: some of them date back to the 1970s. What is current is the packaging. The build moved to CMake, which the README says should give reasonable results across Linux and Windows, and the Python module installs from the top level directory into a virtual environment.
That combination matters for a specific reader. If you are putting voice input on a device with no network, or you need recognition inside a C program that cannot take on a large runtime, the small footprint is the whole reason to choose this over a neural recognizer. The voice for this is a Python developer, a systems programmer, or a hobbyist with a Raspberry Pi who needs to prove that offline recognition works at all before investing in it.
The honest limit is the age of the models: the CLI uses the default acoustic and language model. The README itself hedges the very first example: the results may not be wonderful.
SphinxBase is gone, and so is the audio library
Two pieces of the old stack have been removed, and both removals change how you write build scripts. There is no longer any dependency on SphinxBase. The README puts it flatly: there is no SphinxBase anymore, this is not the SphinxBase you are looking for.
The audio library went the same way. The README says it never really built or worked correctly on any platform at all, and that it has simply been removed. So there is no legacy audio shim to link against, and any code you are porting from an older PocketSphinx will need its capture path rewritten.
Here is the contradiction worth noticing. The repository still ships examples named live_portaudio.c and live_pulseaudio.c, and the Docker image installs portaudio, alsa-utils and alsaconf. The removed library was the built in one; capturing audio is now the caller's job through those external examples or through sox and ffmpeg, which the README installs as example dependencies. The removal is real, and so is the surrounding capture code.
On Debian based systems, including Raspberry Pi OS and Ubuntu, those example dependencies install in one command: `sudo apt install ffmpeg libasound2-dev libportaudio2 libportaudiocpp0 libpulse-dev libsox-fmt-all portaudio19-dev sox`.
Two install paths, and the Python wheel hides a CMake build
The Python module install is three commands. Replace the path with whatever you want the environment to be called:
python3 -m venv ~/ve_pocketsphinx
. ~/ve_pocketsphinx/bin/activate
pip install .
The C library and its bindings are three different ones. If you cannot write to /usr/local, add -DCMAKE_INSTALL_PREFIX to the first cmake command and set your own prefix.
cmake -S . -B build
cmake --build build
cmake --build build --target install
What the Python path hides: pyproject.toml requires scikit-build-core and Cython, and pip does not skip the native build. It compiles the C library, then wraps it. pyproject.toml also pulls in sounddevice as a dependency, and registers two console scripts, pocketsphinx_lm and pocketsphinx_to_textgrid.
The cibuildwheel configuration builds CPython 3.11 and 3.13 wheels plus PyPy, with macOS archs set to x86_64, universal2 and arm64. cibuildwheel explicitly skips macosx_x86_64 and macosx_arm64 standalone builds and every 32 bit target, so if you need a nonstandard wheel you are back to pip install. from source.
soxflags is the answer to the raw PCM contract
The pocketsphinx program reads single-channel 16-bit PCM from standard input or from files. That single sentence is the whole audio contract, and it is where a first run usually fails, because most people have mp3 or m4a. The CLI provides a helper for this rather than making you guess the sample rate and endianness. The soxflags command returns the arguments that produce the right input format.
Microphone input, where -d tells sox to read from the device:
sox -d $(pocketsphinx soxflags) | pocketsphinx -Decoding a compressed file instead:
sox audio.mp3 $(pocketsphinx soxflags) | pocketsphinx -Read the order carefully. The README notes that the sox command line is slightly quirky and that these arguments must always come after the filename or after -d.
For a WAV file already in the right shape, the command is shorter:
pocketsphinx single speech.wavThe command defaults to live. single treats the whole file as one utterance and prints one JSON object; live segments the stream and prints line-delimited JSON. If you see nothing but error lines on standard error, add -loglevel INFO. Partial results are not printed, and the README says not to hold your breath for them.
align turns a word list into timestamps, and the quoting is yours to get right
The align command force-aligns one audio file to a text you supply. The first positional argument is the input and every later one is concatenated into the text, which the README explains is deliberate so you cannot be surprised by forgetting quotes.
pocketsphinx align goforward.wav "go forward ten meters"Word level alignment is the default. Set `text` to the normalized transcript, for example `text="go forward ten meters"`. Phone level needs a flag, and -state_align yes also turns on phone alignment:
pocketsphinx -phone_align yes align audio.wav "$text"pocketsphinx -state_align yes align audio.wav "$text"State level output is admittedly not readable as printed, so the README pipes it through jq. Word names and start times:
pocketsphinx align audio.wav "$text" | jq '.w[]|[.t,.b]'Phone names and durations, with the alignment flag turned on:
pocketsphinx -phone_align yes align audio.wav "$text" | jq '.w[]|.w[]|[.t,.d]'The upstream examples use an unquoted shell variable; these versions quote it to prevent shell word splitting and wildcard expansion. The README also puts normalization on you: strip punctuation and uppercase yourself before aligning.
Short JSON field names, and a config you can dump and reload
Every recognition result is a JSON object with deliberately terse keys. b is start time in seconds from the beginning of the stream, d is duration in seconds, p is the estimated probability of the result as a number between 0 and 1, t is the full text, and w is a list of segments, usually words, each carrying the same four fields.
The short names are a real ergonomic choice. A live session produces one line per recognized utterance, and the README's own aside is that this is not the prettiest format but it beats XML. If you enable phone alignment, each word gains its own nested w list of phone segments in the same shape.
Configuration follows the same pattern of being inspectable. The config command dumps the whole configuration as JSON to standard output, and that output can be fed back through the -config option, so a working setup can be captured, edited by hand and replayed.
Command specific help exists for the options the README declines to enumerate, which is the honest way to find them:
pocketsphinx help alignWhere PocketSphinx is the wrong tool, and what to use instead
The clearest failure mode is acoustic model coverage. The README's own hedge on the first example is the warning sign.
The second failure mode is accuracy against neural systems on clean, read speech. If you need open vocabulary dictation, choose a neural recognizer such as Whisper, which runs a model rather than a compact statistical pipeline and is designed for general transcription. The difference in approach is the whole argument: Whisper spends compute per utterance to generalize, PocketSphinx spends a fraction of the compute per frame and lives inside an embedded process.
For local speech recognition in Python, Vosk takes the same small offline shape with its own model files and a Python API. PocketSphinx differs in what it gives you for the same footprint: an aligner, state level timestamps, and C bindings in the same tree.
If your input is not single channel 16-bit PCM, sox and ffmpeg are not optional extras. The README removes the audio library outright, so a project that assumed PocketSphinx could open an mp3 itself will need a conversion stage in the pipeline, and the Dockerfile exists for exactly that arrangement: alpine runtime with sox and portaudio, cmake and ninja for the build stage, then the wheel copied into the final image.
Editorial conclusion
Adopt PocketSphinx when you need an offline recognizer you can link into a C program, a wake word pipeline that must run on a Raspberry Pi, or word and phone level timestamps for annotation, and the default acoustic and language model is acceptable. Do not adopt it for open vocabulary dictation or anything where modern neural accuracy matters. Verify first that your audio decodes as single channel 16 bit PCM and that the default acoustic and language model cover the words you expect, since pocketsphinx single on a file called speech.wav may not be wonderful.
Frequently asked questions
how to install pocketsphinx
The Python module installs from the top level directory with python3 -m venv, then pip install ., and pyproject.toml requires scikit-build-core and Cython so the C library is compiled during that install. The C library and bindings build with cmake -S . -B build, cmake --build build, then cmake --build build --target install.
how to use pocketsphinx
The command line program takes a command that defaults to live plus one or more inputs, or - to read from standard input. single treats a file as one utterance, live segments it, and align force-aligns audio to a text you pass after the filename. Results come back as JSON with b, d, p, t and w fields.
What is a good alternative to PocketSphinx?
Whisper takes a different approach by running a neural model for general transcription, and Vosk offers a similar small offline footprint with Python bindings. PocketSphinx distinguishes itself by also providing forced alignment at word, phone and state level plus C bindings.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/cmusphinx-pocketsphinx)Star history chart for your README
[](https://hysenlabs.com/projects/cmusphinx-pocketsphinx)Was this useful?