FluxGym: a Gradio front end for Kohya FLUX LoRA training on 12GB of VRAM
Dead simple FLUX LoRA training UI with LOW VRAM support
At a glance
- What is it?
- FluxGym wraps the Kohya sd-scripts trainer in a Gradio UI so you can train FLUX LoRAs without a terminal, and it targets 12GB, 16GB and 20GB cards instead of the 24GB that AI-Toolkit's UI assumes.
- Who is it for?
- FluxGym fits anyone with a 12GB to 20GB NVIDIA card who wants to train a FLUX LoRA from a browser form and is willing to let Kohya sd-scripts do the work underneath. Skip it if you need a training API, a non-NVIDIA accelerator, or a maintained release history, because the repository shows no releases and the last push was on 2026-07-28.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 110 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
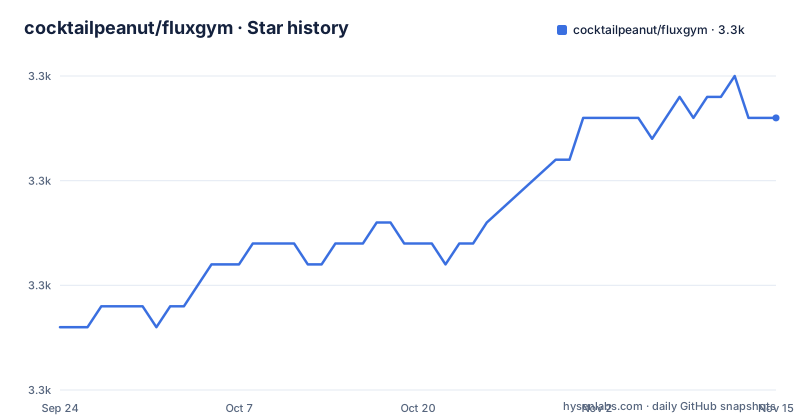
- cocktailpeanut/fluxgym3,263 ★ · +10
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| cocktailpeanut/fluxgym | 3.3k | 3.3k |
10 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The gap FluxGym fills between AI-Toolkit's UI and Kohya's terminal
Two projects solve half of the FLUX LoRA problem each. AI-Toolkit ships a Gradio interface contributed by @multimodalart that the README calls "perfect", but the project only works for 24GB VRAM. Kohya sd-scripts are "very flexible and powerful for training FLUX", yet you have to run them in a terminal. FluxGym is the combination the author wanted: the AI-Toolkit-style form on top, Kohya sd-scripts underneath, aimed at 12GB, 16GB and 20GB cards.
The audience is narrow and specific. It is someone with a consumer NVIDIA GPU who has a set of captioned images and a trigger word, and who wants a LoRA file rather than a command line. The README's usage section is three steps long: enter the lora info, upload and caption images with the trigger word, click start. Nothing in that flow assumes you know what a learning rate schedule is.
The claim worth scrutinising is "100% of Kohya sd-scripts features". That is delivered through an Advanced tab that is hidden by default, so the simple path and the complete path are the same application with a different amount of surface area exposed. It is a reasonable design, but it means the simple UI is a curated subset and the Advanced tab is effectively raw Kohya configuration wearing a Gradio widget.
How the Gradio form reaches the Kohya trainer
FluxGym is a two-layer stack. app.py is the Gradio application you interact with. The sd-scripts directory is a clone of kohya-ss/sd-scripts on the sd3 branch, and that is where training actually happens. The repository layout makes the split visible: app.py, requirements.txt, models/, outputs/ and models.yaml sit at the top level next to the sd-scripts checkout.
models.yaml is the model registry. The README says supported base models are Flux1-dev, Flux1-dev2pro and Flux1-schnell, and that you can add more by editing that file, with a pull request invited if you have an interesting base model. The models themselves are downloaded automatically when you start training with that model selected, which is the September 25 change alongside Docker support and custom base models.
The training loop is Kohya's, not FluxGym's. That matters for two reasons. First, the output artifacts land where Kohya puts them, so anything you know about Kohya LoRA output applies. Second, the memory behaviour that makes 12GB possible comes from the sd-scripts configuration, not from anything FluxGym invented. FluxGym's contribution is choosing and exposing those settings through a form.
Sample image generation is the clearest example of the layering. FluxGym does not generate samples during training by default. You enable it with two fields: Sample Image Prompts and Sample Image Every N Steps. The README's arithmetic is explicit: expected training steps of 960 with a sample interval of 100 produces images at steps 100 through 900, for each prompt. Underneath, the prompts accept Kohya's sample-image flags, so a prompt ending in --d 42 pins the seed and lets you watch the same composition change as the LoRA evolves. Other flags the README lists are --n for a negative prompt up to the next option, --w for width and --h for height.
Installing FluxGym manually, or with Pinokio or Docker
There are three install paths. Pinokio is the one-click launcher, and the README points at its item page for FluxGym. The manual path is the one worth understanding because it shows the dependency chain.
Start by cloning both repositories. FluxGym expects sd-scripts to live inside its own directory, on the sd3 branch:
git clone https://github.com/cocktailpeanut/fluxgym
cd fluxgym
git clone -b sd3 https://github.com/kohya-ss/sd-scripts
Create and activate a virtual environment from the fluxgym root. On Linux the README gives:
python -m venv env
source env/bin/activate
Install sd-scripts dependencies first, then FluxGym's, then PyTorch Nightly. The order matters because sd-scripts is installed into the same activated environment:
cd sd-scripts
pip install -r requirements.txt
cd ..
pip install -r requirements.txt
pip install --pre torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu121
For an NVIDIA RTX 50-series card such as a 5090 the README gives a different pair of commands, cu128 torch plus a bitsandbytes upgrade:
pip install --pre torch torchvision torchaudio --index-url https://download.pytorch.org/whl/nightly/cu128
pip install -U bitsandbytes
Then start the app from the fluxgym root with the venv active. The README warns twice about activation, once for Windows and once for Linux:
python app.pyThe Docker route avoids the venv entirely. Clone the same two repositories, check your user and group id with `id`, and set PUID and PGID in the environment if they are not 1000. Then build and start:
docker compose up -d --buildThe compose file maps port 7860 to 7860 and passes the GPU through with an nvidia device reservation, so the browser target is http://localhost:7860. Note the comment in docker-compose.yml: switch the dockerfile to Dockerfile.cuda12.4 if you are on CUDA 12.4 drivers, otherwise leave it. The default Dockerfile is built on nvidia/cuda:12.2.2-base-ubuntu22.04 and installs torch for cu122, so the two files are not interchangeable by accident.
Once the UI is open, the first real run is the README's three steps. Fill in the lora info, upload images and caption them with your trigger word, click start. If you want to watch progress visually, set Sample Image Prompts and Sample Image Every N Steps before starting, and remember that sample generation is off unless you set both.
Where FluxGym is the wrong tool
The VRAM claim is a floor, not a guarantee. The README advertises 12GB, 16GB and 20GB support, and the mechanism is Kohya's memory configuration, but nothing in the README states which resolutions, batch sizes or base models stay inside 12GB. If you pick Flux1-dev2pro or push resolution upward, you are changing the memory profile, and the README offers no table mapping settings to VRAM. Treat 12GB as the entry point the project was built for, not as a promise that every configuration fits.
Flux1-schnell is listed as supported with a candid caveat: the author could not get high quality results and does not really recommend it. That is honest and it is also a limitation. If schnell is your reason for choosing FluxGym, the project itself is telling you the results were not good.
The bigger structural limitation is that FluxGym is a UI, not a service. There is no documented API, no headless training mode, and no queue. Everything runs through the Gradio process started by app.py. If you want to trigger training from a script, schedule runs, or train on a machine without a browser session, the Gradio front end is overhead rather than help, and you would be better served calling sd-scripts directly.
Maintenance is the other thing to weigh. The repository is not archived, but the last push was on 2026-07-28, and it has no published releases. The README's news entries are dated September 11, 16 and 25 without a year, so they cannot be placed against that push. There is no changelog, no versioning scheme and no documented upgrade path. Anyone who needs a pinned, versioned training dependency should look elsewhere.
FluxGym versus Kohya sd-scripts and AI-Toolkit
The comparison that matters is against the two projects FluxGym is assembled from, because the README names both.
Against Kohya sd-scripts, the difference is purely the interface. The training engine is identical, since FluxGym clones sd-scripts and drives it. Kohya gives you a terminal, full flag control and the ability to script runs. FluxGym gives you a form, a hidden Advanced tab that exposes Kohya's features, and automatic model downloads. If you already have a working Kohya command line, FluxGym adds a browser layer and a models.yaml registry on top of it, and takes away nothing except the need to remember flags. If you have never used Kohya, FluxGym is the gentler entry, but you are still going to read Kohya documentation the moment you open the Advanced tab.
Against AI-Toolkit, the difference is the memory target. The README states plainly that AI-Toolkit only works for 24GB VRAM, and that its Gradio UI is the one FluxGym forked. So FluxGym is not a competitor to AI-Toolkit's interface; it is that interface rebuilt on a different trainer so that smaller cards can run it. If you have 24GB and you are already happy with AI-Toolkit, there is no stated reason to switch.
The search results also put FluxGym next to ComfyUI and OneTrainer. The README describes neither integration nor comparison, so any claim about how FluxGym relates to them would be invention. What can be said is that FluxGym's outputs are LoRA files from Kohya sd-scripts, and how you use a LoRA afterwards is outside this project's scope.
Licence, upgrade cost and what the repository does not settle
FluxGym is MIT licensed, and the LICENSE file sits at the top level. That covers FluxGym's own code. It does not cover what FluxGym pulls in. The manual install clones kohya-ss/sd-scripts, which carries its own licence, and requirements.txt pins a long list of third-party packages including diffusers==0.38.0, transformers==4.49.0, peft==0.17.1, lycoris-lora==1.8.3, pydantic==2.9.2 and starlette==0.50.0. The pinned versions are the practical constraint: if another project in the same environment needs a different transformers or pydantic, the venv is where that conflict surfaces. This is a description of the dependency list, not legal advice, and anyone redistributing a build should read the upstream licences themselves.
Upgrade cost is hard to estimate from the README. There are no releases, so there is no version to pin and no release notes to read before pulling. The repository does contain update.js and reset.js alongside install.js and start.js, which suggests the Pinokio path handles updates through those scripts, but the README does not document what update.js does or whether it touches the sd-scripts clone. Manual installers have no documented upgrade procedure at all: the README's install section ends at `python app.py`.
The models.yaml file is the extension point and also the upgrade risk. Adding a base model means editing that file, and the README invites pull requests for interesting ones. If you add a model locally and later pull the repository, you are reconciling your edit against whatever the upstream file now contains, and the README describes no merge strategy for that.
One more thing the README leaves open: the sample image flag list is truncated mid-sentence at the --d flag, so the full set of advanced sample flags lives in Kohya's documentation rather than here. That is consistent with the project's overall posture. FluxGym documents the form; Kohya documents the training.
Editorial conclusion
FluxGym fits anyone with a 12GB to 20GB NVIDIA card who wants to train a FLUX LoRA from a browser form and is willing to let Kohya sd-scripts do the work underneath. Skip it if you need a training API, a non-NVIDIA accelerator, or a maintained release history, because the repository shows no releases and the last push was on 2026-07-28. Before committing a training run, verify the sd-scripts clone is on the sd3 branch, that models.yaml lists the base model you intend to use, and that app.py starts on port 7860 under your activated venv.
Frequently asked questions
How do I install FluxGym?
Clone fluxgym and kohya-ss/sd-scripts on the sd3 branch, create and activate a venv, install sd-scripts requirements, then FluxGym's requirements, then PyTorch Nightly, and run python app.py from the fluxgym root. Pinokio provides a one-click launcher and there is also a Docker path via docker compose up -d --build.
How do I use FluxGym to train a LoRA?
The README describes three steps: enter the lora info, upload images and caption them using the trigger word, then click start. Sample image generation is off by default and only runs if you fill in both Sample Image Prompts and Sample Image Every N Steps.
Is FluxGym local?
Yes. FluxGym runs as a Gradio app on your own machine, started with python app.py, and the Docker path serves it on port 7860 at http://localhost:7860. Training uses a local clone of kohya-ss/sd-scripts, and base models are downloaded automatically when you start training with that model selected.
Is FluxGym free?
The repository is MIT licensed, so the FluxGym code itself is free to use under those terms. The install pulls in kohya-ss/sd-scripts and a long list of pinned third-party packages, each with its own licence.
What is the difference between FluxGym and Kohya sd-scripts?
There is no difference in the training engine, because FluxGym clones kohya-ss/sd-scripts and drives it. FluxGym adds a Gradio web UI and a models.yaml registry on top, with an Advanced tab that the README says exposes 100% of Kohya sd-scripts features.
What is the difference between FluxGym and AI-Toolkit?
The README says AI-Toolkit's Gradio UI is what FluxGym forked, and that AI-Toolkit only works for 24GB VRAM. FluxGym keeps that interface style but runs Kohya sd-scripts underneath so it can target 12GB, 16GB and 20GB cards.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/cocktailpeanut-fluxgym)Star history chart for your README
[](https://hysenlabs.com/projects/cocktailpeanut-fluxgym)Was this useful?