Sequoia-X screens the A-share market after close and pushes to Feishu
An automated stock-picking system for China's A-share market: scans multiple technical patterns, runs automatically after market close, and pushes results to Feishu.
At a glance
- What is it?
- A Python system that pulls back-adjusted daily K-line data for roughly 5,200 A-share listings into local SQLite, runs six technical pattern strategies over it, and posts the results to a Feishu group. The data choice is the interesting part: a free source with no registration, and an adjustment convention chosen so incremental updates stay correct.
- Who is it for?
- Sequoia-X fits someone who wants a repeatable end-of-day screen over the whole A-share market without paying for a data feed, and who is comfortable running a scheduled job on a server. It does not fit intraday work, since the pipeline is designed around daily bars and a post-close run.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 127 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
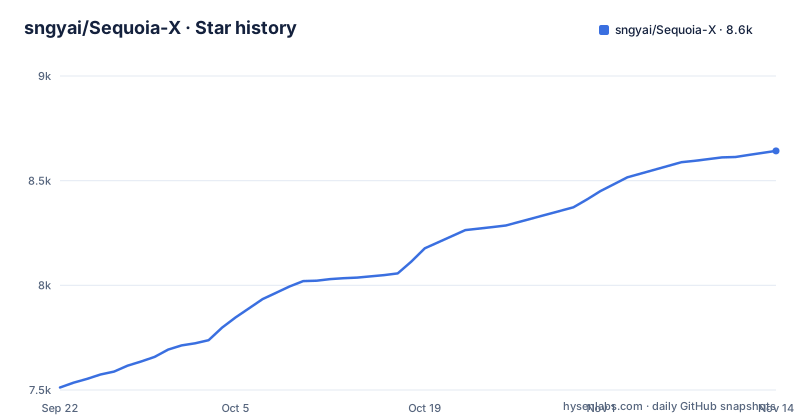
- sngyai/Sequoia-X8,642 ★ · +1,130
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| sngyai/Sequoia-X | 7.5k | 8.6k |
1,130 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two modes, and one of them takes twelve minutes
The whole runtime is one entry point with two arguments:
python main.py               # 日常模式:8进程增量补数据 + 跑策略 + 飞书推送(2~3分钟)
python main.py --backfill     # 回填模式:全市场历史K线一次性灌入(约12分钟)
The daily path does three things in order: it updates the incremental data with eight worker processes, runs the strategies, and pushes the output to Feishu. Two to three minutes is the expected duration. The backfill path is the one you run once, and it loads the entire market's history in a single pass, taking about twelve minutes.
The scale that number implies is stated separately: the backfill covers roughly 5,200 A-share listings of historical back-adjusted daily K-line data. So the twelve minutes is a one-off cost, and everything after it is incremental.
Back-adjusted prices are what make the database incremental
The adjustment convention is the quiet decision that makes the rest work, and the readme explains it directly. Data is stored 后复权, meaning back-adjusted, with the stated benefit that historical prices stay unchanged, which suits incremental storage and avoids the data corruption that ex-rights events would otherwise cause.
That is the whole reason an incremental update is safe here. With back-adjusted series, a new bar is a new bar.
Storage is a local SQLite file at data/sequoia_v2.db, and the readme notes it can be copied directly to another machine. The database is generated at runtime and is excluded from version control, so the repository stays small and the data is yours.
The data source is baostock, and akshare is still in the manifest
The data layer uses baostock, described as free, requiring no registration, and having no rate limit. The reason given is blunt: pulling from baostock into local SQLite completely sidesteps Eastmoney's anti-scraping problems.
There is one inconsistency worth knowing about. The dependency manifest lists both baostock and akshare, plus pandas, requests, pydantic-settings, python-dotenv and rich. The documented pipeline only ever mentions baostock, so akshare appears to be either a fallback path or a leftover. Either way it is installed, so it is part of your environment whether you use it or not.
The rest of the stack is small and conventional. Configuration is handled with pydantic-settings over a dotenv file, and logging uses rich for structured output, which is what a scheduled job's output will be formatted through when it fails.
Seven webhook slots for six strategies
The .env template is where the notification design becomes visible. There is one required key, a default Feishu webhook URL, explicitly marked as the fallback:
DB_PATH=data/sequoia_v2.db
START_DATE=2024-01-01
FEISHU_WEBHOOK_URL=https://open.feishu.cn/open-apis/bot/v2/hook/your-default-token
Then there are per-strategy overrides, named with a strategy identifier suffix: MA_VOLUME, TURTLE, FLAG, SHAKEOUT, LIMIT_DOWN, RPS and PRIVATE_PLACEMENT. Any strategy without its own key falls back to the default URL, so you can run one shared channel or split them.
Count the slots against the strategy table and there is a mismatch. The built-in strategies are TurtleTrade, MaVolume, HighTightFlag, LimitUpShakeout, UptrendLimitDown and RpsBreakout, six in total, while the template reserves seven webhook names. The private placement slot has no matching strategy in the list, so it is either planned or left over.
The crontab entry runs at 19:15 on weekdays
Running this on a schedule is the intended deployment, and the readme gives the line:
15 19 * * 1-5 cd /root/Sequoia-X && .venv/bin/python main.py >> log.txt 2>&1Every field carries a decision. Days 1 to 5 restrict it to weekdays. Minute 15 of hour 19 puts it after the A-share close, which for a market that shuts at 15:00 leaves a buffer for the vendor's data to settle. Output is appended to a log file rather than mailed, and both streams are redirected so a crash is visible in the file.
The virtual environment path is invoked directly rather than relying on an activated environment, because cron has no shell profile. And it is run from the project root, which matters given that the database path in the config is relative.
Six strategies, each a module behind an abstract base class
The strategy set is pattern-based rather than factor-based, and the readme summarises each in a table:
- TurtleTrade is a turtle breakout: a 20-day high, turnover above 100 million, and a bullish candle filter against false breakouts, with results sorted by gain. - MaVolume is a moving average plus volume breakout. - HighTightFlag is a breakout from a high and narrow flag consolidation. - LimitUpShakeout is a pullback confirmation after a limit-up shakeout. - UptrendLimitDown is an engulfing pattern after a limit-down inside an uptrend. - RpsBreakout is an O'Neil relative strength breakout.
The directory layout shows how they are organised. Under sequoia_x/strategy/ there is an abstract base class and one module per strategy, with turtle_trade.py and ma_volume.py named explicitly. The same discipline applies elsewhere: core/ holds config and logging, and data/engine.py holds the whole data engine, including the baostock backfill, the incremental sync and the SQLite layer.
hypothesis in the dev group, and a licence that is only half recorded
The development dependencies say something about how the project is tested. Beyond pytest and pytest-mock, the dev group includes hypothesis, which is a property-based testing library. That choice fits a codebase built on numerical invariants: strategies and data transforms are easier to test by asserting properties over generated inputs than by asserting values for one example.
Lint and format configuration is compact too. ruff runs with a line length of 100, targets Python 3.11 while the package itself allows 3.10 and newer, and selects four rule groups: pycodestyle errors, pyflakes, import sorting, and pyupgrade. pytest is pointed at the tests directory explicitly.
One administrative gap is worth flagging. The readme states the project is MIT licensed, and the repository metadata reports no recognised licence, and the tree contains no LICENSE file. If you intend to reuse the code, resolve that before you do rather than after.
Editorial conclusion
Sequoia-X fits someone who wants a repeatable end-of-day screen over the whole A-share market without paying for a data feed, and who is comfortable running a scheduled job on a server. It does not fit intraday work, since the pipeline is designed around daily bars and a post-close run. Before running it, note that the readme claims MIT while the repository licence field is unrecorded, decide whether you need akshare given that the documented data source is baostock, and keep the Feishu webhook tokens out of version control.
Frequently asked questions
How do I install and run Sequoia-X?
You need Python 3.10 or newer. Install dependencies with uv sync, or with pip install ., then copy .env.example to .env and fill in your Feishu webhook URL. Run python main.py --backfill once to load history, then python main.py for the daily cycle.
What data source does Sequoia-X use?
baostock, which is described as free, needing no registration and having no rate limit. Data is stored as back-adjusted daily K-line data in a local SQLite file at data/sequoia_v2.db, and the readme says this setup avoids Eastmoney's anti-scraping problems.
How long does the Sequoia-X backfill take and how often does it run?
The first backfill takes about twelve minutes and loads historical data for roughly 5,200 A-share listings. After that the daily run updates incrementally with eight parallel processes, runs the strategies and pushes to Feishu, taking two to three minutes, and the readme suggests a crontab entry at 19:15 on weekdays.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sngyai-sequoia-x)Star history chart for your README
[](https://hysenlabs.com/projects/sngyai-sequoia-x)Was this useful?