website-hot-hub: A Plain Archive of Chinese Tech and Video Hot Lists
36Kr bilibili GitHub 2023-10-25 Releases .
At a glance
- What is it?
- This Python project scrapes hourly hot lists from 36Kr, bilibili, GitHub, and other Chinese platforms and stores them as dated archives. It is a straightforward data collection tool, not an analysis platform.
- Who is it for?
- Use website-hot-hub if you need a raw, timestamped record of Chinese platform hot lists for research, trend spotting, or dataset building. Do not use it if you want analytics, sentiment, or any derived insight, because the project only stores raw links and titles.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
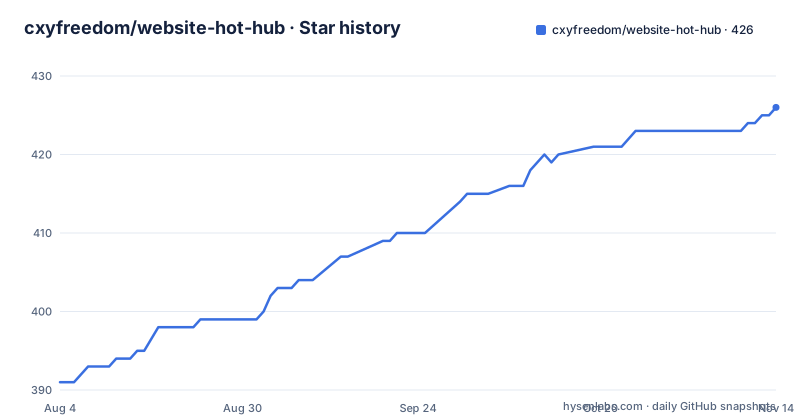
- cxyfreedom/website-hot-hub426 ★ · +35
| Repository | 2026-08-04 | 2026-11-14 |
|---|---|---|
| cxyfreedom/website-hot-hub | 391 | 426 |
35 Stars in the last 102 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What This Repository Actually Stores
The project records hot lists from 36Kr, bilibili, GitHub, 抖音, 掘金, 微信读书, and 快手, starting from 2023-10-25. The README states that data is captured hourly and archived by day under the archives directory. The visible content for 36Kr shows a numbered list of article titles with links and timestamps. There is no evidence of any processing, ranking logic, or deduplication. It is a timestamped snapshot, nothing more. The archive format is plain markdown, which is easy to read but lacks structure for automated analysis. If you need a historical record of what was popular on these platforms at a given hour, this repository provides exactly that. If you need clean tabular data, you will have to parse the markdown yourself.
The Mechanism: Hourly Snapshots, No API Required
The repository layout and README point to a simple mechanism: a script runs every hour, fetches the current hot list from each platform, and writes the results to a markdown file. The README shows a '最后更新时间' (last update time) field, which suggests the scrape is triggered by a scheduler, likely cron. The archive directory is organized by date, so each day gets its own file. The project does not appear to use official APIs; the URLs in the 36Kr list are direct article links, and the timestamps are in Beijing time. This approach has a trade-off. Scraping public pages is fragile because site structures change. The README does not document which libraries are used, but the primary language is Python, so requests or a similar HTTP client is likely. There is no mention of rate limiting or retry logic, which could be a problem if a platform blocks the scraper. For a hobby project, this works. For a production data pipeline, you would need to add error handling and monitoring.
Getting It Running: What the README Does and Does Not Tell You
The README is minimal. It explains the purpose and points to the archives, but it does not provide installation instructions, a requirements.txt, or example commands. There is no documented setup like 'pip install -r requirements.txt' or 'python run.py'. The repository has a Python primary language and an MIT license, but you have to inspect the source code to learn how to run it. The release tags, v0.0.1 and v0.0.2, suggest that the project is packaged somehow, but the README does not describe how to invoke the scraper. You will likely need to clone the repository, examine the Python files, and infer the entry point. This is a barrier for non-developers. If you are comfortable reading code, you can figure it out. If you expect a turnkey tool, this project will disappoint. The hourly scheduling is also not documented; you must set up your own cron job or task scheduler to replicate the archive behavior.
A Genuine Limitation: The Data Is Raw and Unstructured
The main limitation is that the repository only stores titles and URLs, with no metadata like author, publish time, or engagement metrics. The 36Kr list shows article titles and links, but no view counts or timestamps for each item. That means you cannot analyze trends over time beyond the presence of a title on a given day. You cannot measure how long an item stayed on the list, because the archive is a snapshot, not a time series of ranks. If you want to study hot list dynamics, you need to process the markdown files yourself and build a database. The README does not provide any tooling for that. Another limitation is the coverage. The README lists seven platforms, but the visible archive excerpt only shows 36Kr. You have to trust that the other platforms are being captured. If you need bilibili or GitHub data, verify that the corresponding archive files exist and are being updated.
A Real Alternative: Official APIs and Commercial Aggregators
Instead of scraping hot lists, you could use official platform APIs where they exist. GitHub has a public REST API that can return trending repositories, though the trending endpoint is not officially documented; you would need to scrape the HTML page or use a third-party service. bilibili has an official API for popular videos, but it requires authentication and has rate limits. The advantage of official APIs is stability and structured data. The disadvantage is that they often do not expose the exact same 'hot list' that you see on the website, and they may require a developer account. Another alternative is commercial data aggregators like Newrank or Feigua, which track Chinese social media and news platforms. They offer historical data and analytics dashboards, but they charge a subscription fee. website-hot-hub is free and open source, but you get what you pay for: raw data with no support. If you need reliable, structured historical data for serious research, an official API or a commercial service is a better choice. If you just want a personal record, this repository is sufficient.
Maintenance and License: What You Are Signing Up For
The repository was last pushed in February 2026, and the latest release v0.0.2 is dated the same day, which indicates active maintenance as of that date. The MIT license means you can use, modify, and distribute the code freely, but you must include the original copyright notice. There is no documentation on how to update the scraper when a platform changes its HTML structure. That is a real maintenance cost. If a site like 36Kr alters its page layout, the scraper will break, and you will have to fix it yourself. The release tags suggest that the author packages changes in versions, but there is no changelog. You should check the commit history to understand what changed between v0.0.1 and v0.0.2. The project is not archived, so it is presumably still being maintained, but the README offers no roadmap or contribution guide. If you plan to deploy this in a production environment, budget time for debugging and for writing your own tests.
Editorial conclusion
Use website-hot-hub if you need a raw, timestamped record of Chinese platform hot lists for research, trend spotting, or dataset building. Do not use it if you want analytics, sentiment, or any derived insight, because the project only stores raw links and titles. Before adopting, verify that the hourly cron job is still running and that the archive format matches your downstream needs. The repository's recent release tags suggest ongoing maintenance, but the README does not document the scraping code, so check the source for robustness. Adopt it as a data source, not as a finished product.
Frequently asked questions
What does website-hot-hub collect?
The hot ranking lists of 36Kr, bilibili, GitHub, Douyin, Juejin, WeRead and Kuaishou, from 2023-10-25 onward. Each list is written into README.md between BEGIN and END marker comments, with older snapshots archived by day.
How often does website-hot-hub scrape?
Once an hour. The timestamps written into each region use the +0800 offset, and the recorded 36Kr and bilibili regions differ by one second, which indicates a sequential loop rather than parallel fetching.
What does website-hot-hub need to run?
Two pinned Python packages, requests 2.32.4 and beautifulsoup4 4.12.3. Nothing in that list can schedule work, so whatever runs the hourly cycle lives outside the two dependencies, and the repository does not document the command that starts a run.
Where does website-hot-hub keep past snapshots?
In per-platform directories under archives/, linked from the end of each region in the README, for example ./archives/36kr and ./archives/bilibili. A raw/ directory also exists in the repository but is not described anywhere in the written material.
What are the website-hot-hub releases?
Two, and both are named for archive coverage rather than software. v0.0.1 is titled Archive-2023-2024-v0.0.1 from 2025-06-14, and v0.0.2 is titled Archive-2025 from 2026-02-07. No release covers 2026.
Is website-hot-hub still being updated?
The repository is not archived and the last push is dated 2026-10-01, so the hourly collection was still running at that point. The version numbers on the releases have stayed at 0.0.x throughout.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/cxyfreedom-website-hot-hub)Star history chart for your README
[](https://hysenlabs.com/projects/cxyfreedom-website-hot-hub)Was this useful?